# Lamatic.ai Documentation — Full Text
Concatenated source of every documentation page. Each page is preceded by its source URL.
---
# Agents
Source: https://lamatic.ai/docs/agents.md
# Lamatic Agents

Agents are AI-powered components in Lamatic that handle different types of tasks, such as generating text, processing structured data, and orchestrating multi-agent flow. This guide introduces the different agent types and how they function within the Lamatic ecosystem.
## Prerequisites
- Basic understanding of [Flows](/docs/flows) and [Nodes](/docs/nodes)
- A Lamatic Project in Studio
## What are Agents?
Agents are specialized AI entities that execute specific tasks based on input and predefined logic. They can work independently or as part of a larger workflow inside **Flows**. After deployment, you can interact with these agents via **API Endpoints** in a flow or execute them directly.
## Types of Agents
### 1. Supervisor Agent
A **Supervisor Agent** orchestrates multiple AI agents, ensuring structured flow by dynamically routing tasks based on input conditions.
- **Key Features:**
- Multi-agent coordination for structured execution.
- Memory retention for context-aware interactions.
- Adaptive execution paths based on agent responses.
- Check out the [Supervisor Agent](./agents/supervisor-agent.mdx) for more details.
### 2. Generate Text Agent
A **Text Generation Agent** produces AI-generated content based on prompts. This agent is ideal for generating responses, summarizing content, or creative writing.
- **Key Features:**
- Supports advanced language models for text generation.
- Configurable temperature and response length.
- Ideal for chatbots, content generation, and summarization.
- Check out the [Text Agent](./agents/text-agent.mdx) for more details.
### 3. Generate JSON Agent
A **JSON Agent** structures AI-generated responses into JSON format, making it useful for APIs and automated processing pipelines.
- **Key Features:**
- Generates structured JSON outputs.
- Useful for integrating AI with databases or APIs.
- Ensures predictable response formats.
- Check out the [JSON Agent](./agents/json-agent.mdx) for more details.
### 4. Multi-Modal Agent
A **Multi-Modal Agent** processes and generates outputs across different data types, including text, images, and structured data.
- **Key Features:**
- Supports vision-language models.
- Processes multiple data types simultaneously.
- Useful for applications like AI-powered design assistants.
- Check out the [Multi-Modal Agent](./agents/multi-modal-agent.mdx) for more details.
## Best Practices
- **Choose the Right Agent:** Select the agent type that best suits your task requirements.
- **Optimize Prompts:** Well-structured prompts lead to better AI outputs.
- **Use Memory Wisely:** Enable memory retention for agents that need contextual awareness.
- **Test & Iterate:** Experiment with different configurations for the best results.
By leveraging these agent types effectively, you can build powerful AI-driven applications inside Lamatic.ai.
## Troubleshooting
- **Agent not responding**: Check that the agent is deployed and the project is active
- **Unexpected output format**: Verify the agent type matches your use case (e.g., use JSON Agent if you need structured output)
- **Memory issues**: Review memory configuration if the agent isn't retaining context between calls
## Next steps
- Learn how to create agents: [Getting Started with Agents](/docs/agents/getting-started)
- Explore specific agent types:
- [Supervisor Agent](/docs/agents/supervisor-agent)
- [Text Agent](/docs/agents/text-agent)
- [JSON Agent](/docs/agents/json-agent)
- [Multi-Modal Agent](/docs/agents/multi-modal-agent)
- Integrate agents into your application: [Authentication with API Keys](/docs/studio-keys)
---
# Alerts
Source: https://lamatic.ai/docs/alerts.md
# Error Alerts & Notifications
Get notified the moment a deployed flow fails, by email and in-app, with a direct link to the failing log.
## What it is
Error alerts notify you as soon as a flow in a deployed project hits an error. Instead of keeping Logs open to watch for failures, Lamatic sends the alert to you directly.
## What it does
- **Email alerts**: includes the flow name, project, error message, and a "Check Log" link straight to the failing run.
- **In-app alerts**: same error details, surfaced in the notification bell and stacked as they come in.
- **Near real-time delivery**: alerts trigger per error within a 5-minute window.


## Managing your notifications
### Profile-level preferences
Your profile page has dedicated controls to turn email and in-app notifications on or off, independent of any specific project.
### Project-level settings
Each project has its own **Notifications** page under **Settings**. From here you can:
- Turn email and in-app alerts on or off for the whole project.
- Control which team members receive alerts, per recipient and per channel.
### Notification schedule (from the notification icon)
Open the **notification bell** in the navbar to set a delivery schedule for each notification preference. The schedule controls when external-channel notifications (like email) are delivered.
- Toggle specific days on or off, and set an allowed time range (**From** / **To**) for each day.
- Outside the scheduled window, external-channel notifications pause.
- **In-app and critical notifications are always delivered**, regardless of the schedule.
This lets you, for example, mute email alerts overnight or on weekends while still catching critical issues in-app.
This gives you full control over exactly who gets notified, how, and when, for every project.
## Related
- [Logs](/docs/logs) — full request and node-level traces for every flow run.
- [Reports](/docs/reports) — usage and performance analytics for your projects.
---
# Architecture
Source: https://lamatic.ai/docs/architecture.md
# Architecture
Lamatic was designed with redundancy and scalability in mind. The architecture is divided into different layers that work together to provide a seamless experience to the users.
It is designed such that even if our main system fails, it will not affect your deployed applications and APIs.

## Execution Steps
These following steps highlight the typical execution of steps involved in building and deploying project on Lamatic.ai
### User Creates a flow
Create flow by connecting required nodes to achieve the desired output.
### Connecting custom data and apps
Integrate your data sources for custom data and apps within your flow.
### Connect models
Add model credentials to your flow.
### Deploy the flow on Edge
Triggering deployment compiles the whole workflow and deploys it on the edge. This is a locked in state of your project which is isolated from lamatic studio and platform.
### Trigger the Flow with GraphQL API, widgets or webhooks
Integrate with method of your choice to trigger the flow.
### Privacy and on premise hosting
The green shaded area is where the private information of organisation is stored and processed. Lamatic can be customized
to host this data on premise or on a private cloud. This ensures that the data is not shared with any third party and is
completely secure.
## Layers

Different parts of lamatic could be easily understood through the following different layers -
### Integration
This layer integrates third-party applications with Lamatic.ai, which is accessible in the following ways:
- **Apps** - Connect 3rd party apps to trigger flows and receive the response directly within the application.
- **Widgets** - Customizable pre-built components that you can drop into your applications (e.g., chat widget).
- **GraphQL API** - User-specific Schema API that performs different operations. This includes GraphQL object caching on the edge for faster response to repeated requests.
- **Webhooks** - Trigger flows using webhooks and receive an asynchronous response in your application.
### Studio
This is the Visual layer on top of Core. Lamatic Studio allows non-technical users to configure, monitor, and maintain system operation and flows.
- **IAM** - Manage external API keys for your development team.
- **Dashboard** - Complete overview of operating metrics for your active projects.
- **Cache Control** - Control the cache (semantic and vector) to your specification and performance goals.
- **Schema** - Specify the Schema of API query input and responses based on your data structure.
- **Logs** - Log all incoming requests and query them for analysis.
- **Reports** - Dashboard and Charts for your execution
- **Evals** - Test Flows and prompts
- **Agents** - Use our library of agents for specific tasks or create your own agents using custom prompts.
- **Flow Management** - Manage complex flows (i.e., series of Agents) collaborating to complete tasks. You can also integrate apps to perform actions or fetch information.
- **Experiments** - Set up A/B tests and experiments that help you evaluate the best model, prompts, and agents.
- **Logic** - Set up failover/fallback/retry/ Test models.
- **Predictions** - Cost predictions based on consumption.
- **Keys** - Manage your model subscriptions in one place.
### Managed Infrastructure
Lamatic's managed infrastructure hosts everything required for a performant application including edge deployed functions and cluster nodes that autoscales according to customer demands.
### Data ETL
Hosted vector database that includes ETL pipeline to integrate data from third party sources and transform them into vectors for use in RAG use cases.
### Core
Here's the text with the main headings converted to bold:
This holds all the code logic that enables the reliable execution of our GraphQL API.
- **Request Monitoring** - Monitors and authenticates incoming requests.
- **Cache** - Semantic caching modules based on query vectors.
- **Query Controls** - Maps the right data along with Object Retrieval for downstream queries. Includes checking JSON format for response validation and quality control. Optionally could be used for privacy data filtering and redaction.
- **Agents** - Setup prompts and conditions to pass to models.
- **Flows** - Organize Agents into a flow chain to perform specific tasks.
- **Memory** - Memory for Chatbots and context-related queries.
- **A/B Module** - Perform optimization across Agents, Rules, and Models.
- **Model Relay** - Managed connections across multiple models.
### Model Integration
Integration with third-party models and APIs.
## Architecture Diagram
We have this interactive Miro board that explains the architecture of Lamatic.ai in detail and is continuously updated. Please feel free to check it out and drop any comments.
---
# Lamatic CLI (Beta)
Source: https://lamatic.ai/docs/cli.md
# Lamatic CLI (Beta)
`@lamatic/cli` is the official command-line interface for managing your Lamatic organization. Create projects, manage flows, trigger deployments, and configure contexts and integrations, all from the terminal.
---
## Installation
Install globally to use the `lamatic` command anywhere:
```bash
npm install -g @lamatic/cli
```
Or run on demand without installing:
```bash
npx @lamatic/cli
```
---
## Authentication
Authenticate once with your API key, organization ID, and user ID. Credentials are cached locally so subsequent commands don't require re-entering them.
```bash
lamatic auth login \
--api-key \
--org-id \
--user-id
```
Your organization ID and API key come from **Studio → Settings → API Keys**, same as [API Keys](/docs/api-integration/api-key). Your user ID is your Lamatic account identifier, visible in your organization's members list in Studio.
| Command | Description |
|---|---|
| `lamatic auth login` | Authenticate with your API key |
| `lamatic auth status` | Check current auth status |
| `lamatic auth logout` | Logout and clear credentials |
---
## Help
```bash
lamatic --help
lamatic --help
```
---
## Commands
### Projects
| Command | Description |
|---|---|
| `lamatic init ` | Create a new Lamatic project |
| `lamatic project list` | List all projects in your org |
| `lamatic project get` | Fetch and download a project locally |
| `lamatic project delete` | Delete a project |
```bash
# Create a new project
lamatic init my-project --scratch
# List all projects
lamatic project list
# Download an existing project locally
lamatic project get --project-id
# Delete a project
lamatic project delete --project-id
```
### Flows
| Command | Description |
|---|---|
| `lamatic flows create` | Create a new flow in a project |
| `lamatic flows list` | List all flows in a project |
| `lamatic flows rename` | Rename a flow |
| `lamatic flows delete` | Delete a flow |
| `lamatic flows status` | Update flow status (active/inactive) |
```bash
# Create a flow
lamatic flows create --project-id --name "My Flow"
# List all flows
lamatic flows list --project-id
# Rename a flow
lamatic flows rename --project-id --flow-id --name "New Name"
# Delete a flow
lamatic flows delete --project-id --flow-id
# Update flow status
lamatic flows status --project-id --flow-id --status active
```
### Deployments
| Command | Description |
|---|---|
| `lamatic deploy` | Trigger a deployment for a project |
| `lamatic deployments list` | List all deployments |
| `lamatic deployments get` | Get details of a specific deployment |
```bash
# Trigger a deployment
lamatic deploy --project-id
# List all deployments
lamatic deployments list --project-id
# Get deployment details
lamatic deployments get --project-id --deployment-id
```
### Contexts
| Command | Description |
|---|---|
| `lamatic contexts list` | List all contexts in a project |
| `lamatic contexts create` | Create a new context (vector or memory) |
| `lamatic contexts delete` | Delete a context |
```bash
# List contexts
lamatic contexts list --project-id
# Create a context
lamatic contexts create --project-id --name "my-context" --type vector
# Delete a context
lamatic contexts delete --project-id --context-id
```
### Models
| Command | Description |
|---|---|
| `lamatic models list` | List all model credentials |
| `lamatic models add` | Add a new model credential |
```bash
# List model credentials
lamatic models list --project-id
# Add a model credential
lamatic models add --project-id
```
### Integrations
| Command | Description |
|---|---|
| `lamatic integrations list` | List all integration credentials |
| `lamatic integrations add` | Add a new integration |
```bash
# List integrations
lamatic integrations list --project-id
# Add an integration
lamatic integrations add --project-id
```
---
## Example Workflow
A typical end-to-end flow: log in, create a project, add a flow, deploy, and verify.
```bash
# 1. Login
lamatic auth login --api-key --org-id --user-id
# 2. Create a new project
lamatic init my-project --scratch
# 3. List your projects to grab the project ID
lamatic project list
# 4. Create a flow inside the project
lamatic flows create --project-id --name "My Flow"
# 5. Deploy the project
lamatic deploy --project-id
# 6. Check deployment status
lamatic deployments list --project-id
# 7. Download an existing project locally
lamatic project get --project-id
```
---
## Links
- [npm package](https://www.npmjs.com/package/@lamatic/cli)
- [API Keys](/docs/api-integration/api-key): where to find the credentials this CLI uses
- [SDK](/docs/sdk): programmatic access from your application code
- [Graph MCP](/docs/mcp/graph-mcp): execute deployed flows from any AI assistant
---
# Containers (Beta)
Source: https://lamatic.ai/docs/containers.md
# Containers (Beta)
Run your flows on a dedicated container runtime rather than the standard serverless edge, which is built for long-running workflows and sandboxed code execution.
## What it is
Containers provide an alternative execution environment for Lamatic flows. Instead of running on the standard serverless edge, a container-enabled flow runs inside an isolated, dedicated runtime with its own compute and memory.
This is useful for flows that need more room to run than the default edge environment allows.
## What it does
- **Longer execution windows**: container-backed flows can run well beyond typical edge execution limits, making them a fit for long-running or multi-step workflows.
- **Sandboxed code execution**: Code nodes run in an isolated container environment, separate from the rest of your project.
- **Same flow engine**: container execution uses the same underlying workflow engine as the standard runtime, so your flow logic doesn't change. Only where it runs does.
## Containers vs Edge
| | Serverless Edge (default) | Containers (beta) |
| ------------------ | --------------------------------------- | ------------------------------------------------------ |
| **Execution time** | Short, optimised for latency | Long, suited to multi-step or batch workloads |
| **Best for** | Quick API calls and real-time responses | Document processing, multi-agent chains, heavy compute |
| **Availability** | All projects, default-on | Closed beta, opt-in per project and per flow |
## When to use Containers
Reach for container execution when your flow runs into the limits of the standard serverless edge. Typical cases:
- **Document-processing pipelines** that scrape, chunk, and embed hundreds of pages in a single run.
- **Multi-agent workflows** that chain ten or more LLM calls before returning a result.
- **Heavy Code-node workloads**: image processing, large-file transforms, custom ML inference, anything CPU- or memory-intensive.
- **Long-running ingestion jobs** that periodically sync a data source (CRM, file storage, database).
- **Polling or wait-based logic**: `setTimeout`, retry loops, or queue-draining patterns that would otherwise blow past edge timeouts.
If your flow comfortably finishes in a few seconds on edge, you don't need Containers. Stay on the default runtime.
## How it works
Container execution is opt-in at both the project and flow level. A flow only runs in a container when both:
1. The project has container execution enabled.
2. The individual flow has container execution enabled.
Flows that don't opt in continue to run on the standard serverless edge as usual, so enabling containers for a project doesn't change the behavior of existing flows.
## Current status
Containers is currently in **closed beta**. It's not yet available as a self-serve toggle in Studio.
## Request beta access
If you'd like to try container execution for your project, request access using the form below.
---
# Context
Source: https://lamatic.ai/docs/context.md
# Context in Lamatic
## Prerequisites
- Basic understanding of [Flows](/docs/flows) and [Nodes](/docs/nodes)
- Understanding of [LLMs](/docs/models) (Large Language Models)
- A Lamatic Project in Studio
## What's Context?
Context refers to additional information provided to a Large Language Model during text generation or chat interactions. This supplementary data enhances the LLM's understanding of the specific topic or task at hand, leading to more accurate and relevant outputs.
**Simple analogy**: If an LLM is a student, context is the textbook or notes you give them. Without context, they can only rely on what they learned during training. With context, they can answer questions about your specific data, company, or use case.
---
### LLMs Have Limitations:
1. **Knowledge Cut-off**: LLMs lack real-time access to the most current information.
2. **Limited Access**: Some information may not be publicly available, and thus, not included in the model's training data.
3. **Private Information**: Certain data may be part of confidential interactions with the AI system.
> **Note**: LLMs operate within these limitations, which can affect the quality and relevance of their outputs.
---
### Benefits of Providing Context:
- **Improved Understanding**: Additional context helps LLMs better comprehend tasks, resulting in more relevant and accurate responses.
- **Reduced Hallucinations**: By narrowing the scope, LLMs are less likely to generate false or irrelevant information.
- **Enhanced Efficiency**: Context allows LLMs to focus on specific information, leading to faster and more precise responses.
> **Tip**: Providing context results in higher quality outputs with fewer iterations and less training.
---
## Methods of Providing Context
### Direct Prompt Inclusion
The simplest method involves incorporating relevant information directly into the prompt. However, this approach has limitations due to LLMs' context limits.
### Retrieval using Vector Databases
Vector databases are a powerful solution for context-related challenges in AI. They store and retrieve information based on semantic meaning, allowing for more nuanced and relevant context retrieval.

#### Understanding Vectors and Vector Databases
Vectors in this context are mathematical representations of words, phrases, or entire documents. They capture semantic meaning, allowing for comparison and retrieval based on similarity rather than exact matching. Vector databases efficiently store and query these high-dimensional vectors, enabling rapid retrieval of relevant context.
> **Quick Fact**: Vectors enable semantic searches, making them highly effective for contextual queries.
#### When to Use Vector Databases
Vector databases are particularly useful when dealing with large amounts of unstructured data, such as documents, articles, or product descriptions. They excel in scenarios where semantic similarity is more important than exact keyword matching, making them ideal for providing relevant context to LLMs.
> **Best Practice**: Use vector databases for unstructured data retrieval when accuracy based on meaning is essential.
#### Lamatic's Built-in Vector Database Powered by Weaviate
Lamatic integrates **Weaviate**, a powerful vector database, to provide efficient and accurate context retrieval. This integration allows users to leverage the benefits of vector-based search and retrieval without the need for complex setup or management.
> **Pro Tip**: Take advantage of Lamatic’s Weaviate-powered system for easy and precise context management.
---
### Memories
Memory systems offer another approach to providing context, particularly useful for maintaining continuity in conversations and personalizing interactions over time.
#### When to Use Memories
Memories are particularly valuable in scenarios requiring long-term context retention, such as ongoing customer support interactions, personalized tutoring, or any application where user preferences and history play a crucial role in generating appropriate responses.
> **Pro Tip**: Use memories for long-term user preferences and ongoing conversations.
#### Lamatic's Built-in Memories Powered by mem0
Lamatic incorporates **mem0**, a cutting-edge memory system, to enhance its context-awareness capabilities. This feature allows the platform to remember and utilize important information across multiple interactions, leading to more personalized and contextually relevant outputs.
> **Tip**: Leverage mem0 for enhanced personalization and context awareness over time.
---
## Other Methods
### API Calling
API calling involves retrieving real-time information from external sources to provide up-to-date context. This method is particularly useful when dealing with dynamic data such as weather information, stock prices, or current events.
> **Quick Note**: Use API calls to fetch real-time data for the most current context.
---
### Tools in Agents
Agent-based systems can utilize various tools to gather and process context. These tools may include web scrapers, database queries, or specialized algorithms that can analyze and summarize large amounts of data to provide relevant context to the LLM.
> **Pro Tip**: Implement agent tools to enhance the breadth and depth of context provided to LLMs.
## Choosing the Right Context Method
| **Method** | **Best For** | **When to Use** |
|------------|--------------|-----------------|
| **Direct Prompt** | Small amounts of static data | Simple use cases, one-time context |
| **Vector Database** | Large documents, semantic search | RAG applications, knowledge bases |
| **Memories** | Long-term user preferences | Chatbots, personalized experiences |
| **API Calling** | Real-time, dynamic data | Weather, stock prices, current events |
| **Agent Tools** | Complex data processing | Multi-step context gathering |
## Troubleshooting
- **Context not being used**: Verify your Flow is passing context to the LLM node correctly
- **Vector search not finding relevant data**: Check that your data was properly chunked and indexed
- **Memory not persisting**: Ensure Memory Store is configured and enabled in your Flow
- **Context too long**: Use chunking or vector search instead of including everything in the prompt
## Next steps
- **Learn about RAG**: Read [What is RAG?](/docs/concepts/rag) for detailed information on Retrieval-Augmented Generation
- **Set up Vector Database**: Follow guides on [Data Storage](/docs/context/vectordb) to index your documents
- **Build a RAG application**: Check out [RAG Tutorials](/guides) for step-by-step examples
---
# Contributing
Source: https://lamatic.ai/docs/contributing.md
# Contributing to Lamatic.ai Documentation
We're thrilled that you're interested in contributing to the Lamatic.ai documentation! Your efforts help improve the experience for all users of our platform. This guide will walk you through the process of contributing.
## Documentation style guide
When writing or editing docs, follow these principles so the docs stay clear and consistent:
- **Second person, active voice.** Write "Click Deploy" not "The Deploy button should be clicked."
- **Outcome-first.** Lead with what the reader can do or when to use a feature, not a list of capabilities. Example: "Use the JSON Agent when you need structured JSON from an LLM" rather than "The JSON Agent has customizable schemas and multi-model support."
- **One idea per sentence.** Avoid long chains of clauses; use full stops instead of em-dashes or commas when in doubt.
- **Use callouts for important notes.** Use the `` (or `type="info"`, `type="error"`) component for gotchas, tips, and prerequisites. Example: **Save before you deploy** — changes after the last save won't appear in the deployed Flow.
- **Standardize placeholders.** In code examples, use angle brackets for values the user must replace: ``, ``, ``, ``. Add a short "Prerequisites" or "Replace these values" line before the snippet.
- **Terminology.** Use **Flow** and **Node** (capitalized) as the product terms. Avoid "workflow" when you mean Flow unless the UI uses it. Keep terms consistent with the [Glossary](/docs/glossary).
## Getting Started
1. **Understand Our Docs Structure**
- Our documentation is built using Nextra, a Next.js and MDX-powered static site generator. To get a better understanding of how our docs work, visit our repository at https://github.com/lamatic/lamatic-docs and learn more about Nextra at https://nextra.site/docs.
2. **Join Our Community**
- Have questions or need help? Join our Slack community. We're always happy to assist contributors!
3. **Get Beta Access**
- As a token of our appreciation, we'd like to offer all contributors beta access to our platform. Use this link to sign up: https://studio.lamatic.ai/signup?code=earlybetauser
## Steps to Contribute
1. **Fork the Repository**
- Visit the [Lamatic Docs GitHub repository](https://github.com/lamatic/lamatic-docs).
- Click the "Fork" button in the top-right corner to create a copy of the repository in your GitHub account.
2. **Clone Your Fork**
- Clone your forked repository to your local machine:
```
git clone https://github.com/your-username/lamatic-docs.git
cd lamatic-docs
```
3. **Create a New Branch**
- Create a new branch for your changes:
```
git checkout -b your-branch-name
```
- Use a descriptive name for your branch, e.g., `add-new-feature-doc` or `fix-typo-in-quickstart`.
4. **Install Dependencies and Run the Development Server**
- Install the necessary dependencies:
```
npm install
```
- Start the development server:
```
npm run dev
```
- Open your browser and go to `http://localhost:3333/docs` to see your changes in real-time.
5. **Make Your Changes**
- Edit or add the necessary files in your local repository.
- Ensure your changes adhere to the existing style and formatting of the documentation.
- If you're adding new documentation, update the `_meta.json` file to include the new page.
- If you're modifying existing documentation, update the corresponding `.mdx` file.
- Refresh your browser to see your changes reflected immediately.
6. **Commit Your Changes**
- Stage and commit your changes:
```
git add .
git commit -m "Brief description of your changes"
```
7. **Push Your Changes**
- Push your changes to your forked repository:
```
git push origin your-branch-name
```
8. **Create a Pull Request**
- Go to the [original Lamatic Docs repository](https://github.com/lamatic/lamatic-docs).
- Click on "Pull requests" and then the "New pull request" button.
- Click "compare across forks" and select your fork and branch.
- Review your changes and click "Create pull request".
- Provide a clear title and description for your pull request.
9. **Wait for Review**
- The Lamatic.ai team will review your contribution.
- They may request changes or provide feedback.
- Once approved, your changes will be merged into the main documentation.
## Issue Types
When contributing or reporting issues, it's helpful to categorize them. Here are the main types of issues you might encounter or want to report:
1. **Bug**: An error, flaw, or fault in the documentation that produces an incorrect or unexpected result. This could include broken links, incorrect information, or formatting issues.
2. **Feature Request**: A suggestion for a new addition to the documentation. This could be a request for documentation on a new feature of Lamatic.ai or a proposal for a new section in the existing docs.
3. **Improvement**: A suggestion to enhance existing documentation. This could involve clarifying explanations, adding more examples, or restructuring content for better readability.
4. **Typo**: A small error in the text, such as a misspelling or grammatical mistake.
When creating an issue or pull request, please prefix your title with the appropriate issue type in square brackets or assign appropriate labels. For example:
- [Bug] Broken link in Quick Start guide
- [Feature Request] Add documentation for new API endpoint
- [Improvement] Clarify explanation in Authentication section
- [Typo] Fix misspelling in Contributing guide
This categorization helps the maintainers prioritize and address issues more efficiently.
Thank you for contributing to Lamatic.ai documentation! Your efforts are greatly appreciated and help make our platform better for everyone. If you have any questions during the process, don't hesitate to reach out on our Slack channel.
---
# Edge Deployment
Source: https://lamatic.ai/docs/deployments.md
# Edge Deployment

[Lamatic.ai](http://Lamatic.ai) seamlessly and automatically deploys your Project to a globally distributed edge network, ensuring exceptional performance, ultra-low latency, and unparalleled scalability. This advanced deployment strategy leverages strategically positioned servers worldwide, bringing your application closer to end-users and significantly reducing response times. By utilizing this cutting-edge infrastructure, [Lamatic.ai](http://Lamatic.ai) empowers your Project to deliver lightning-fast experiences and effortlessly handle varying loads, providing a robust foundation for your application's success in today's competitive digital landscape.
**Applying changes**
When you change any project configuration you also need to redeploy your project to take those into effect.
---
## What is Edge Deployment?
Edge deployment is an innovative approach to running applications and services that brings computation closer to the end-users. This method utilizes a network of geographically distributed nodes or servers strategically positioned around the globe. By implementing this decentralized architecture, edge deployment significantly reduces latency and enhances overall performance. The key principle behind this technology is minimizing the distance that data needs to travel between the user and the application, resulting in faster response times and improved user experiences.
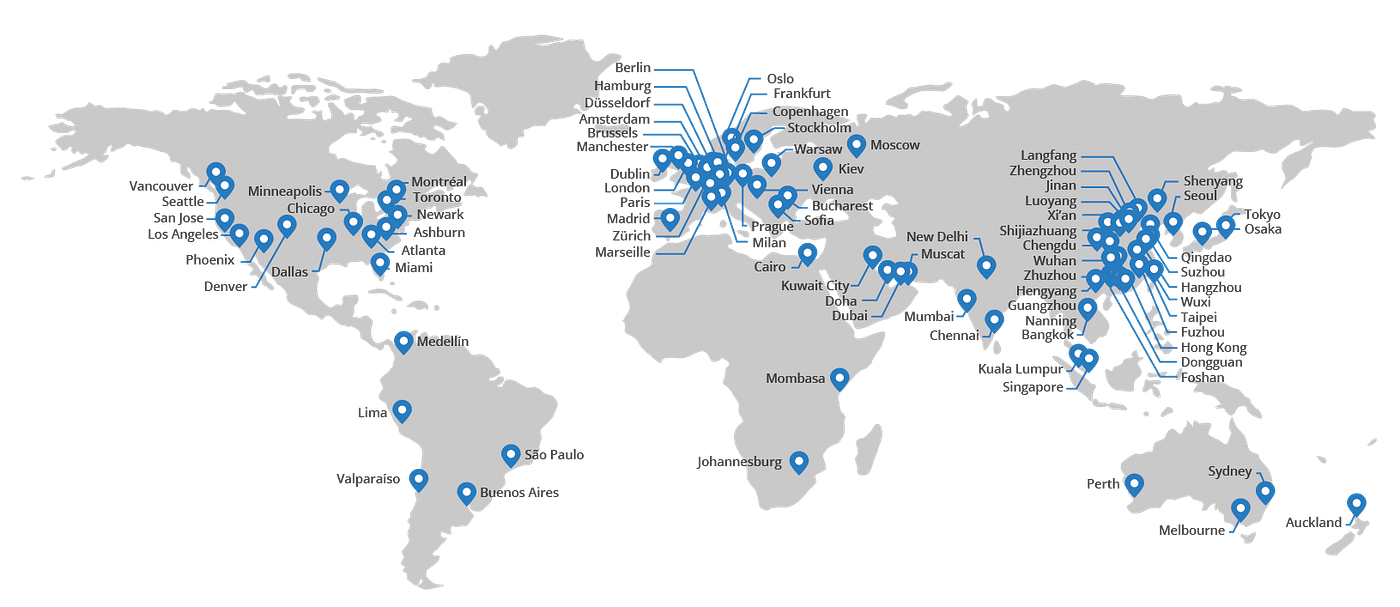
> **Built on Cloudflare**: Our cutting-edge infrastructure leverages Enterprise-grade Cloudflare Workers for optimal performance and reliability. For organizations requiring on-premise solutions or custom network deployments tailored to specific needs, we invite you to reach out to our dedicated team at [hello@lamatic.ai](mailto:hello@lamatic.ai). We're here to provide personalized solutions that align with your unique requirements.
---
## Why Choose Edge Deployment?
1. **Exceptional Low Latency**: By strategically positioning edge servers in close proximity to end-users, [Lamatic.ai](http://Lamatic.ai) applications achieve remarkably low latency. This proximity ensures lightning-fast response times, resulting in exceptionally snappy and responsive user experiences that keep your audience engaged and satisfied.
2. **Unparalleled Global Availability**: Our extensive global edge network guarantees that your applications remain highly available and performant, regardless of your users' geographic locations. This global reach empowers you to serve a truly international audience without compromising on speed or reliability, opening up new markets and opportunities for your business.
3. **Advanced Serverless Architecture**: [Lamatic.ai](http://Lamatic.ai) projects operate on a cutting-edge serverless architecture, which automatically scales to meet fluctuating demand while optimizing resource utilization. This intelligent system eliminates the need for manual provisioning and scaling of infrastructure, allowing you to focus on developing your application while we handle the complexities of server management.
4. **Intelligent Auto-Scaling Capabilities**: One of the most significant advantages of edge deployment with [Lamatic.ai](http://Lamatic.ai) is its sophisticated automatic scaling feature. As traffic demands fluctuate, our platform dynamically and intelligently adjusts the number of workers running your application. This ensures optimal performance and efficient resource utilization at all times, providing a seamless experience for your users even during unexpected traffic spikes.
5. **Robust Security and Unmatched Reliability**: [Lamatic.ai](http://Lamatic.ai)'s globally distributed network is fortified with advanced security features, including state-of-the-art DDoS protection and a comprehensive Web Application Firewall (WAF). These robust security measures work in tandem to ensure that your applications remain secure and highly available, even when faced with sophisticated malicious attacks or unexpected surges in traffic. Our multi-layered approach to security provides peace of mind, allowing you to focus on your core business objectives.
Whether you're a forward-thinking global enterprise aiming to harness the full potential of GenAI for mission-critical applications, or an ambitious, rapidly growing startup poised to develop the next revolutionary GenAI solution, [Lamatic.ai](http://Lamatic.ai)'s advanced edge deployment capabilities provide the robust, scalable, and secure foundation essential for your success in the competitive digital landscape.
---
### The Inner Workings of Edge Deployment
1. **Initiation**: The process begins when you click the `🚀 Deploy` button. This action triggers the system to save your meticulously crafted Flow as a comprehensive LowCode Configuration, capturing all the intricacies of your application design.
2. **Transformation**: The LowCode Configuration undergoes a sophisticated transpilation process, converting it into a highly optimized TypeScript bundle. This bundle is enriched with essential resources, including your specified Model parameters and secure App Credentials, ensuring a complete package for deployment.
3. **Distribution**: The final step involves the seamless deployment of the TypeScript bundle across our expansive, distributed Edge network. This strategic distribution ensures that your application is readily available at numerous points of presence worldwide, primed for high performance and low latency.
> **Note**: While our advanced systems typically complete this intricate deployment process in less than a minute, please note that during periods of high deployment volume across our platform, the process might require additional time. Rest assured, we're continuously optimizing our systems to maintain the fastest possible deployment times without compromising on quality or security.
---
## Deployment Logs
To provide you with full transparency and control over your deployment process, we offer detailed deployment logs. These logs allow you to monitor the entire build process, providing a step-by-step breakdown of each stage. This feature is invaluable for troubleshooting, as it allows you to quickly identify and address any errors or issues that may arise during the build and deployment phases, ensuring smooth and efficient application launches.
---
# Environments
Source: https://lamatic.ai/docs/environment.md
# Environments in Lamatic AI

Environments in Lamatic AI allow you to create isolated workspaces for your flows, enabling you to develop, test, and deploy changes safely. Built on top of Version Control System (VCS) functionality, environments use branching and merging to help you manage different stages of your workflow—from development to staging to production—without affecting your live flows.
Each environment is represented by a branch, allowing you to work on multiple versions of your flows simultaneously and merge changes between environments when ready.
## Setup Environments with GitHub
Before you can create environments, you need to set up Version Control with GitHub:

1. Navigate to the Flow Editor and click **Connect with GitHub**.
1. Alternatively, you can go to the **Integrations** section under your project settings.
1. Choose an existing repository or create a new one.
1. Select the desired branch for your production environment, and optionally enable auto-deployment on commit.
1. Click **Save** to complete the setup.
## Working with Environments
Environments in Lamatic AI are managed through branches. The production branch serves as your main environment, and you can create additional environments (development, staging, etc.) by creating new branches.
### Accessing Environments
1. Open the desired Flow.
1. From the top navigation bar, click on the **Select Branch** dropdown. The production branch (your main environment) is selected by default.
1. From here, you can switch between environments, create new environments, or merge changes between environments.
### Create a New Environment
To create a new environment (e.g., development or staging) for your flow:
1. Click on the **Select Branch** dropdown in the top navigation bar.
1. Click on **Create New Branch** or the **+** icon.
1. Enter a descriptive name for your new environment (e.g., `development`, `staging`, `feature/new-integration`, or `bugfix/fix-validation`).
1. Optionally, select a base branch to branch from (defaults to the current environment/branch).
1. Click **Create** to create the new environment.
Once created, you can switch to the new environment and make changes without affecting your production environment. This allows you to test new features, configurations, or integrations in isolation.

### Merge Changes Between Environments
To merge changes from one environment into another (e.g., from development to production):
1. Ensure you're on the source environment (the branch you want to merge from).
1. Click on the **Select Branch** dropdown in the top navigation bar.
1. Click on **Merge Icon Button** or the merge icon.
1. Select the target environment (branch) you want to merge into.
1. Review the changes that will be merged.
1. Click **Confirm Merge** to complete the merge.
Your changes will now be available in the target environment. This workflow allows you to promote changes from development → staging → production, ensuring a controlled deployment process.

### Pull Changes from Another Environment
To pull the latest changes from another environment (e.g., pulling production changes into your development environment):
1. Ensure you're on the environment where you want to pull changes (not the source environment).
1. Click on the **Select Branch** dropdown in the top navigation bar.
1. Click on **Pull Icon Button** or the pull icon.
1. Select the source environment you want to pull from.
1. Review any potential conflicts that may arise from the merge.
1. If there are conflicts, resolve them in the Flow Editor.
1. Click **Confirm Pull** to complete the pull operation.
This ensures your environment stays up-to-date with the latest changes from another environment, reducing the likelihood of merge conflicts and keeping your environments synchronized.

## Best Practices for Environments
- **Use descriptive names**: Name your environments clearly (e.g., `development`, `staging`, `production`) to avoid confusion.
- **Keep environments in sync**: Regularly pull changes from production into your development and staging environments to stay current.
- **Test before merging**: Always test changes in a development or staging environment before merging to production.
- **Use feature branches**: Create separate environments for specific features or bug fixes to isolate work and make reviews easier.
---
# Error Codes
Source: https://lamatic.ai/docs/error-reference.md
# Error Reference
Use this page to diagnose failed requests and Flow runs. When the API or a Flow returns an error, check the HTTP status code and the error message in the response body or in [Logs](/docs/logs), then find the matching entry below.
## HTTP status codes
| Code | Meaning | What to do |
|------|--------|------------|
| **200** | Success (check `data` / `errors` in body) | GraphQL can return 200 with errors in the body, such as `Workflow not found!`. Inspect `response.data` and `response.errors`. |
| **400** | Bad Request — invalid JSON, invalid GraphQL query, or a payload that doesn't match the trigger schema | See [GraphQL request errors](#graphql-request-errors) and check your payload against the Flow's trigger input schema. |
| **403** | Access Denied — missing or invalid API key | The API never returns 401. A missing or invalid key returns `{"errors":[{"message":"Access Denied"}]}`. Verify `Authorization: Bearer ` and that the key is active in Studio → Settings → API Keys. |
| **404** | Not found — returned for credential errors | A missing Flow doesn't return 404. See [Flow not found](#flow-not-found) and [Credential errors](#credential-errors). |
| **429** | Plan quota exceeded for the last 24 hours or 30 days | Upgrade your plan or wait for the window to reset. See [Limits & Quotas](/docs/limits). |
| **500** | Server error | Retry; if it persists, check [Platform Status](https://status.lamatic.ai) and contact support. |
## Common errors and fixes
### Authentication (403)
- **Cause:** Missing or invalid API key. The API returns 403 with `{"errors":[{"message":"Access Denied"}]}`, not 401.
- **Fix:** Use the exact key from Studio → Settings → API Keys. Format: `Authorization: Bearer `. Confirm `x-project-id` matches the project that owns the Flow.
### Flow not found
A missing or invalid Flow doesn't produce an HTTP 404. The error comes back in the response body as one of:
- `Workflow not found!`
- `Invalid workflow id - `
**Cause:** Wrong endpoint, project ID, or workflow/Flow ID; or the Flow isn't deployed.
**Fix:** Get the project URL and project ID from project settings. Get the workflow/Flow ID from the Flow's Connect or API panel. Deploy the Flow and use the ID of the deployed Flow.
### Payload / variable mismatch (400)
- **Cause:** The `payload` doesn't match the input schema on the GraphQL trigger (field names or types). The message starts with `Invalid trigger payload:`.
- **Fix:** Open the Flow in the Editor and check the trigger node's input schema. Align your request payload with that schema.
### Plan quota exceeded (429)
This is a plan quota, not short-term rate limiting. The message is one of:
- `Project exceeded max requests for last 30 days, max requests: X, current requests: Y. Please upgrade your plan or contact support.`
- `Project exceeded max requests for last 24 hours, max requests: X, current requests: Y. Please upgrade your plan or contact support.`
**Fix:** Upgrade your plan, or wait for the 24-hour or 30-day window to reset. Retrying with backoff won't help while the quota is exhausted. See [Limits & Quotas](/docs/limits) for plan limits.
## GraphQL request errors
Request-level errors come back in the `errors` array of the response body:
```json
{
"errors": [
{
"message": "Access Denied"
}
]
}
```
| Message | Status | Cause and fix |
|---------|--------|---------------|
| `Invalid JSON in request body` | 400 | The request body isn't valid JSON. Check quoting and escaping in your client. |
| `Invalid GraphQL query` | — | The query can't be parsed or validated. Check the syntax against the [GraphQL reference](/docs/interface/graphql). |
| `Query exceeds maximum allowed aliases (N)` | — | The query uses more aliases than allowed. Reduce the aliases to N or fewer. |
| `Query exceeds maximum allowed depth (N)` | — | The query nests deeper than allowed. Flatten the query to N levels or fewer. |
| `GraphQL introspection is disabled` | — | Introspection queries aren't accepted. Use the documented schema instead. |
| `Access Denied` | 403 | Missing or invalid API key. See [Authentication (403)](#authentication-403). |
| `Internal server error` | 500 | Retry. If it persists, check [Platform Status](https://status.lamatic.ai) and contact support. |
## Flow execution and log status codes
The status codes you see in Studio [Logs](/docs/logs) show what happened to a node or a Flow run. Some codes don't have their standard HTTP meaning.
| Code | Meaning in logs |
|------|-----------------|
| **200** | Node or Flow succeeded. |
| **500** | Node or Flow failed (default error code). |
| **400** | Trigger payload didn't match the GraphQL trigger's input schema. The message starts with `Invalid trigger payload: ...`. |
| **408** | Primary config timed out and the fallback config ran (fallback logic step with a timeout). |
| **509** | Node attempt failed and will be retried (Flow-level retries enabled). Also the error code for runs started via "retry flow". |
| **204** | Success on a retry attempt or a retried run. |
| **304** | Node skipped (branch not taken). |
| **208** | Node skipped during a retried run. |
Flow-level retries go up to 5, with a delay of up to 30 seconds between attempts. Each failed attempt is logged separately.
## Flow execution errors
| Message | Cause and fix |
|---------|---------------|
| `No trigger node found!` | The Flow has no trigger node. Add one and redeploy. |
| `Workflow not found!` / `Invalid workflow id - ` | Wrong Flow ID, or the Flow isn't deployed. See [Flow not found](#flow-not-found). |
| `Invalid trigger payload: ` | The request payload doesn't match the advanced schema on the GraphQL trigger. Status 400. |
| `Max retries reached for node ` | The node failed every Flow-level retry. Check that node's own error in the logs. |
| `Timeout after ms` | The primary config exceeded the fallback timeout, so the fallback config ran. |
| `All parallel requests failed` | Every config in a parallel logic step failed. |
| `All logic steps failed` | Every configured logic step (retry, fallback, parallel, A/B) failed for the node. |
| `Unsupported step type: ` / `Invalid step` | A logic step is misconfigured on the node. Review the node's [logic configuration](/docs/nodes/node-logic). |
| `Previous request id is required` | You used "retry from failed node" without the original request ID. Provide the request ID of the failed run. |
| `Cache not found, please reach out to lamatic support` | Platform-side error. Contact support. |
## Credential errors
| Message | Status | Cause and fix |
|---------|--------|---------------|
| `credentialId is required` / `Invalid credentialId` | 400 | The request is missing a credential ID, or the ID is malformed. Provide a valid `credentialId`. |
| `Credential not found or not accessible` | 404 | The credential doesn't exist or belongs to another project. These two cases are deliberately indistinguishable. Confirm the ID and that the credential is in the same project as the Flow. |
| `Credential resolution is not available for this project, please contact support` | 500 | Platform-side. Contact support. |
## Reading an error in the logs
When a Flow run fails, open the run in [Logs](/docs/logs) and check these fields:
- **`errorMsg`**: The error message.
- **`failedNode`**: The node that failed. It includes `nodeId`, `nodeName`, `nodeSlug`, and `loopBatchId` if the node ran inside a loop or batch.
- **`logicStep`** (on node logs): Which logic step produced the failure. For example:
- `retry (attempt 2/3 with Config B)`
- `parallel (Config A)`
- `abTest (selected Config B)`
- `fallback (Config A timed out)`
## Node-specific errors
Most errors in logs come from individual nodes, such as integration, LLM, code, and API nodes. They're shown verbatim in `errorMsg` together with `failedNode`. Common categories are:
- Integration authentication or credential failures
- Upstream HTTP errors, shown as `HTTP : `
- [Code node](/docs/nodes/logic/code-node) runtime errors
For node configuration and requirements, see the per-node docs, such as the [API node](/docs/nodes/data/api-node), [Generate Text node](/docs/nodes/ai/generate-text-node), and the full [Nodes](/docs/nodes) list.
## Flow failures: next steps
If the request succeeds but the Flow run fails:
- Check **Logs** in Studio for the run's trace and the failing node.
- Use the **Feedback API** or **Reports** if you're capturing run outcomes.
- See the node's documentation for required config (e.g. model credentials, input shape).
---
*If you hit an error not listed here, check [Limits & Quotas](/docs/limits) and [Support](https://support.lamatic.ai) or community Slack.*
---
# Feedback API
Source: https://lamatic.ai/docs/feedback-api.md
# Feedback API

The Feedback API allows you to collect user feedback from any flows, specifically GraphQL APIs. This enables you to gather ratings, comments, and metadata about API responses, which can be viewed in the Reports section to improve your AI applications.
## Overview
When executing flows via GraphQL API, you receive a `requestId` in the response. This `requestId` can be used to submit feedback about the flow execution, helping you track user satisfaction and identify areas for improvement.
## Getting the Request ID
After executing a flow via GraphQL API, you'll receive a `requestId` in the response. This unique identifier is used to associate feedback with a specific flow execution.
```json
{
"data": {
"executeWorkflow": {
"requestId": "your_request_id",
"status": "success",
"result": { ... }
}
}
}
```
## Authentication
To submit feedback, you'll need to include your API key in the request headers:
```
Authorization: Bearer your_api_key
```
You'll also need to include your project ID:
```
x-project-id: your_project_id
```
> Click Here to know how to get your own [API Key](/docs/studio/Project/Settings/keys)
## Submit Feedback
The `submitFeedback` mutation allows you to submit feedback for a specific flow execution.
### Request Parameters
| Parameter | Type | Required | Description |
| --- | --- | --- | --- |
| `requestId` | String | Yes | The unique identifier from the flow execution response |
| `rating` | Int | No | A numeric rating (e.g., 1-5) |
| `comment` | String | No | Text feedback or comments |
| `metadata` | JSON | No | Additional metadata as a JSON object |
### Response Fields
| Field | Type | Description |
| --- | --- | --- |
| `success` | Boolean | Indicates if the feedback was submitted successfully |
| `message` | String | A message describing the result |
| `data` | JSON | Optional additional data |
| `error` | String | Error message if submission failed |
### Code Examples
```bash
curl -X POST \
https://sandbox566-acridxylophone.lamatic.dev/graphql \
-H "Authorization: Bearer ${LAMATIC_API_KEY}" \
-H 'Content-Type: application/json' \
-H 'x-project-id: 93628611-e45c-4895-a807-7e6f950b295c' \
-d '{
"query": "mutation SubmitFeedback($requestId: String!, $rating: Int, $comment: String, $metadata: JSON) { submitFeedback(requestId: $requestId, rating: $rating, comment: $comment, metadata: $metadata) { success message data error } }",
"variables": {
"requestId": "your_request_id",
"rating": 5,
"comment": "Great response!",
"metadata": {
"source": "api",
"user_id": "123"
}
}
}'
```
```javascript
const axios = require('axios');
// Export your Lamatic API key as an environment variable
const lamatic_api_key = process.env.LAMATIC_API_KEY;
const query = `
mutation SubmitFeedback(
$requestId: String!
$rating: Int
$comment: String
$metadata: JSON
) {
submitFeedback(
requestId: $requestId
rating: $rating
comment: $comment
metadata: $metadata
) {
success
message
data
error
}
}
`;
const variables = {
requestId: "your_request_id",
rating: 5,
comment: "Great response!",
metadata: {
source: "api",
user_id: "123"
}
};
const options = {
method: 'POST',
url: 'YOUR_PROJECT_ENDPOINT',
headers: {
Authorization: `Bearer ${lamatic_api_key}`,
'Content-Type': 'application/json',
'x-project-id': 'YOUR_PROJECT_ID',
},
data: { query, variables }
};
axios(options)
.then(response => console.log(response.data))
.catch(error => console.error(error));
```
```python
import os
import requests
# Export your Lamatic API key as an environment variable
lamatic_api_key = os.getenv('LAMATIC_API_KEY')
gqlQuery = """
mutation SubmitFeedback(
$requestId: String!
$rating: Int
$comment: String
$metadata: JSON
) {
submitFeedback(
requestId: $requestId
rating: $rating
comment: $comment
metadata: $metadata
) {
success
message
data
error
}
}
"""
variables = {
"requestId": "your_request_id",
"rating": 5,
"comment": "Great response!",
"metadata": {
"source": "api",
"user_id": "123"
}
}
data = {"query": gqlQuery, "variables": variables}
headers = {
"Authorization": f"Bearer {lamatic_api_key}",
"Content-Type": "application/json",
"x-project-id": "YOUR_PROJECT_ID"
}
url = "YOUR_PROJECT_ENDPOINT"
response = requests.post(url, headers=headers, json=data)
if response.status_code == 200:
print(response.json())
else:
print(f"Error: {response.status_code}")
print(response.text)
```
## Response Example
### Success Response
```json
{
"data": {
"submitFeedback": {
"success": true,
"message": "Feedback submitted successfully",
"data": null,
"error": null
}
}
}
```
### Error Response
```json
{
"data": {
"submitFeedback": {
"success": false,
"message": "Failed to submit feedback",
"data": null,
"error": "Invalid requestId"
}
}
}
```
## Viewing Feedback
After submitting feedback, you can view all collected feedback in the **Reports** section of your Lamatic dashboard. The reports provide insights into:
- User ratings and satisfaction levels
- Comments and textual feedback
- Metadata associated with feedback submissions
- Trends and patterns over time
This data helps you identify areas for improvement and track the quality of your AI applications.
---
# Flow Integration
Source: https://lamatic.ai/docs/flow-integration.md
# Flow Integration
Once you've developed your flow along with testing and deployment, you can integrate it into your application. Lamatic provides a **Connect to your project** experience in the Studio that gives you instructions to execute flows based on your trigger and implementation methods.
If your application, API, or webhook receiver is behind a firewall, review [IP Allowlisting](/docs/ips) before going live.
## Integration checklist
1. **Confirm deployment**: Make sure your latest version of the flow is deployed and passing tests.
2. **Open the Connect modal**: From the flow canvas, click **Connect to your project** to get the endpoint, IDs, and example code.
3. **Choose an integration path**:
- Use **Vibe Code Prompt** to generate app-specific code via your AI assistant.
- Use the **API** tab for raw GraphQL requests (see also API Overview and Integration Guide).
- Use **App Frameworks** for framework-specific snippets (e.g. Next.js + SDK).
## Connect to your project
In the flow editor, use **Connect to your project** to open a modal that shows integration options for the current flow (e.g. your agent or workflow). The modal includes:

- **Open API Playground** — Test the API interactively.
- **View Docs** — Link to full documentation.
You can choose how you want to integrate:
| Tab | Use when |
|-----|----------|
| **Vibe Code Prompt** | You want a ready-made prompt to paste into an AI assistant (e.g. Cursor, ChatGPT) to get integration code. |
| **API** | You want to call the flow via GraphQL from any backend or script (cURL, Node.js, Python, etc.). |
| **App Frameworks** | You are building with a supported framework (e.g. Next.js) and want framework-specific setup and files. |
---
## Vibe Code Prompt
The **Vibe Code Prompt** tab gives you a generated prompt you can copy and use with an AI coding assistant. It includes:
- **Flow ID** — Unique identifier for this flow.
- **API URL** — Your project’s GraphQL endpoint (e.g. `https://.lamatic.dev/graphql`).
- **Project ID** — Your project’s identifier.
- **Flow type** — e.g. Synchronous.
You can optionally add your own integration idea or requirement in the text area. Use **Open With** or the copy button to paste the prompt into your preferred tool and get tailored integration code.
---
## API integration
The **API** tab shows the main operations and code examples for calling your flow from code.

### executeWorkflow
Use this to run the flow with a payload.
- **Payload:** Depends on your flow’s inputs (e.g. `symbol: string`).
- **Response (`data.executeWorkflow`):** `result` (object), `status` (string).
**Example (cURL):**
```bash
curl -X POST "https://.lamatic.dev/graphql" \
-H "Authorization: Bearer $(LAMATIC_API_KEY)" \
-H "Content-Type: application/json" \
-H "x-project-id: " \
-d '{
"query": "query ExecuteWorkflow($workflowId: String!, $symbol: String) { executeWorkflow(workflowId: $workflowId, payload: { symbol: $symbol }) { status result } }",
"variables": {
"workflowId": "",
"symbol": "symbol"
}
}'
```
**Example (Node.js):**
```javascript
const axios = require('axios');
// Export your Lamatic API key as an environment variable
const lamatic_api_key = process.env.LAMATIC_API_KEY;
const query = `
query ExecuteWorkflow($workflowId: String!, $symbol: String) {
executeWorkflow(workflowId: $workflowId, payload: { symbol: $symbol }) {
status
result
}
}
`;
const variables = {
workflowId: "",
symbol: "symbol"
};
const options = {
method: 'POST',
url: process.env.LAMATIC_PROJECT_ENDPOINT,
headers: {
'Authorization': `Bearer ${lamatic_api_key}`,
'Content-Type': 'application/json',
'x-project-id': process.env.LAMATIC_PROJECT_ID
},
data: { query, variables }
};
axios(options)
.then(response => console.log('Success:', response.data))
.catch(error => console.error('Error:', error.response?.data || error.message));
```
Replace ``, ``, and the endpoint with the values from the Connect modal. Get your API key from **Studio → Settings → API Keys** or the **Get API Key** link in the modal. See [API Overview](/docs/api-integration) and [API Keys](/docs/api-integration/api-key) for more.
### submitFeedback
Use this to send feedback for a workflow run (e.g. ratings or comments).
- **Payload:** `requestId` (string, required), `rating` (number, optional), `comment` (string, optional), `metadata` (JSON, optional).
- **Response (`data.submitFeedback`):** `success` (boolean), `message` (string), `data` (JSON, optional).
**Example (cURL):**
```bash
curl -X POST "https://.lamatic.dev/graphql" \
-H "Authorization: Bearer $(LAMATIC_API_KEY)" \
-H "Content-Type: application/json" \
-H "x-project-id: " \
-d '{
"query": "mutation SubmitFeedback($requestId: String!, $rating: Int, $comment: String, $metadata: JSON) { submitFeedback(requestId: $requestId, rating: $rating, comment: $comment, metadata: $metadata) { success message data error } }",
"variables": {
"requestId": "your_request_id",
"rating": 5,
"comment": "Great response!"
}
}'
```
---
## App Frameworks
The **App Frameworks** tab provides framework-specific setup (e.g. **Next.js**). It typically includes:

1. **Install the package** — e.g. `npm i lamatic`.
2. **Add files to your app** — e.g. `.env.local`, a page component, and a `utils` (or similar) file.
### Environment variables
Add the following to `.env.local` (or your framework’s env file), using values from the Connect modal:
```bash
LAMATIC_PROJECT_ENDPOINT=https://.lamatic.dev/graphql
LAMATIC_FLOW_ID=
LAMATIC_PROJECT_ID=
LAMATIC_PROJECT_API_KEY=your-project-api-key
```
Replace `your-project-api-key` with your actual API key from **Get API Key** in the modal or from [Studio → Settings → API Keys](/docs/api-integration/api-key).
### Next steps
- Copy the generated **page** and **utils** snippets from the App Frameworks tab into your app.
- Ensure the payload you send matches your flow’s input schema (e.g. required fields like `symbol`).
- For more API details, see [API Overview](/docs/api-integration) and [Integration Guide](/docs/sdk/integration-guide).
---
# Flows
Source: https://lamatic.ai/docs/flows.md
# Lamatic Flows
Flows are the core building blocks of Lamatic. A Flow connects multiple **Nodes** into a sequence so you can process data, call tools/models, and return a final output.
## What you’ll learn
- What a Flow is and when to use one
- The key parts of a Flow (Trigger → Actions → Response)
- How to create, test, share, and deploy a Flow
## Prerequisites
- A Lamatic Project in Studio
- Basic understanding of [Nodes](/docs/nodes)
## What are Flows?
Flows are sequences of interconnected nodes that process and transform data. They allow you to build complex automation and data-processing pipelines with ease.
### When should I use a Flow?
Use a Flow when you want to:
- Trigger work from an event or request (API, widget, Slack, schedules, database sync)
- Chain multiple steps (retrieve data → transform → call an LLM → store results)
- Add reliability features (retries, logging, consistent outputs)
## Creating a Flow

To create a flow:
1. **Select a Trigger Node:** Begin by choosing a trigger node to initiate your flow.
2. **Add Processing Nodes:** Add subsequent nodes that will handle and process your data.
3. **Arrange Nodes:** Drag and place nodes in the desired order to shape your flow.
## Key Components of a Flow

### Trigger Node
A trigger initiates the flow. It can be a built-in tool or an integration with an external application. There are two main trigger types:
- **Event Trigger:** Triggered by a single event, resulting in one-time execution (e.g., a Slack message).
- **Example:** A new message in a Slack channel starts the flow.
- **Batch Trigger:** Triggered by batch processing, executing the flow multiple times based on the number of items in the batch (e.g., a PostgreSQL sync for new records).
- **Example:** A database sync that processes 100 new records will run the flow 100 times.
### Action Nodes
Action nodes perform the main operations in your flow, processing data step-by-step based on your configuration.
- **Built-in Tools & Integrations:** Choose from built-in tools like AI nodes or connect with external applications that support similar functionality.
- **Logical Arrangement:** Arrange nodes sequentially to ensure a smooth data-processing pipeline.
- **Parallel Processing (Branch Node):** Use branch nodes to execute nodes in parallel for faster, more efficient flow when applicable.
### Final Node (Response)
The final step of your flow can send output to an external system, which is particularly useful for flows initiated by triggers like Chat or GraphQL API integrations.
## Test and Debug
Before deploying, test your Flow to catch configuration and payload issues early.
- **Test**: run the entire Flow with sample input
- **Debug**: inspect node-level outputs and logs when something fails
See: [Flow Editor](/docs/flows/editor) and [Testing](/docs/tests)
## Share Flow

The **Share Flow** feature in Lamatic.ai allows users to collaborate, distribute, and reuse their workflows efficiently. There are three primary ways to share a flow:
### 1. Save As Template
- This option enables users to **create a reusable template** from an existing flow.
- Templates can be **shared with team members** for consistency and easy duplication.
- Ideal for standardizing workflows across an organization.
### 2. Publish Flow
- This option allows users to **publish their flow to the community**.
- By publishing, users can share their work with others, enabling collaboration and reuse.
- Useful for open-source sharing or showcasing best practices.
### 3. Export Flow
- Users can **export their flow as a YAML file**.
- This makes it easy to **backup, transfer, or migrate** workflows.
- Useful for version control and integrating with other systems.
### Use Cases
- **Team Collaboration**: Share standard workflows with colleagues.
- **Knowledge Sharing**: Contribute flows to the community.
- **Backup & Portability**: Save workflows in YAML format for external use.
## How to Access
1. Navigate to your desired flow.
2. Click on the **Share Flow** option.
3. Choose from **Save as Template, Publish Flow, or Export Flow**.
This feature enhances workflow management, enabling better collaboration and efficiency in building AI-powered solutions.
## Best Practices
- **Clear Goal:** Design each flow with a specific objective.
- **Thorough Testing:** Test flows with various input scenarios to validate reliability.
- **Descriptive Naming:** Use descriptive node names to enhance readability.
- **Regular Optimization:** Periodically review and optimize flows to ensure they run efficiently.
By mastering these elements, you’ll be equipped to build robust, efficient flows that streamline and automate complex workflows in Lamatic.
## Troubleshooting
- **My changes aren’t reflected**: Deploy your project so the latest Flow is active.
- **A node fails**: Open logs, confirm required credentials/inputs are set, and re-run the test with a small payload.
- **Payload missing fields**: Verify field names/types match what downstream nodes expect.
## Next steps
- Learn more about building blocks: [Nodes](/docs/nodes)
- Learn about deployment: [Deployments](/docs/deployments)
---
# Quickstart Guide
Source: https://lamatic.ai/docs/get-started.md
# Quickstart Guide
This guide helps you go from **zero → deployed Lamatic project** and test it end-to-end. Use UI-first with Studio approach or API-first: code and API calls approach.
## UI-first - What you'll learn
- How to create a project and build your first Flow
- How to test a Flow in Studio
- How to deploy so your Flow is accessible from integrations (API / widget / apps)
## Prerequisites
- A Lamatic account: [lamatic.ai](https://lamatic.ai/)
- Basic understanding: a **Flow** is a set of connected **Nodes** that run in order
- Optional (recommended): pick a Template to move faster
If you’re brand new, start with a template first. You can always customize it later.
The quickest way to get started is using a **pre-built template**, then editing it to fit your use case.
### Create (or pick) a Project
1. Open Studio (you’ll land on your dashboard).
2. Create a new Project (or open an existing one).
Each Project is isolated — it has its own settings, credentials, and deployments.
### Select a Template
1. Go to **Templates**.
2. Pick a template that matches your goal (API, chatbot, RAG, automation).
3. Add it to your Project.
If you prefer starting from scratch, you can create a new Flow directly from the **Flows** section.
### Configure the Nodes (make it run)
1. Open the Flow in the **Editor**.
2. Click each Node and fill required fields (you’ll usually configure):
- Model/provider credentials (for AI Nodes)
- App connections (for Apps Nodes like Slack / Postgres)
- Inputs and payload fields (what your Flow consumes)
### Test the Flow
1. Click **Test** in the Editor.
2. Provide sample inputs (if your trigger expects them).
3. Verify outputs at the final node (Response) and check logs if anything fails.
### Deploy the Project
Deployment makes your latest Flow changes available for integrations.
1. Click **Deploy**.
2. Wait for deployment to finish.
3. Copy the integration details from Studio (endpoint / keys / ids) as needed.
Save your Flow before deploying. Changes made after the last save will not take effect in the deployed version.
If you update keys, variables, or the Flow, deploy again so changes take effect.
## API-first (5 minutes)
Get from signup to your first API call without using the Editor.
### Step 1: Create a project and get your API key (1 min)
1. Open [Studio](https://studio.lamatic.ai) and create a new Project (or use an existing one).
2. Go to **Settings → API Keys** and click **Create a New API Key**. Copy the key — you won't see it again.
3. Note your **Project ID** (in project settings) and your **Project URL** (GraphQL endpoint).
Store the API key in an environment variable. Never commit it to version control.
### Step 2: Create a Flow from a template (1 min)
1. Go to **Templates** and add the **RAG** (or **Simple Chat**) template to your project.
2. Open the Flow in the Editor. Optionally configure model credentials, then **Save**.
### Step 3: Deploy (30 sec)
1. Click **Deploy** in the Editor and wait for the deployment to finish.
2. From the Connect/API panel, copy the **Workflow ID** (or Flow ID) for the Flow you just deployed.
### Step 4: Call the API from your terminal (2 min)
**Prerequisites:** Replace ``, ``, ``, and `` with your real values. Find them in Studio: Settings → API Keys, project settings, and the Flow's API/Connect panel.
```bash
curl -X POST "" \
-H "Authorization: Bearer " \
-H "Content-Type: application/json" \
-H "x-project-id: " \
-d '{
"query": "query ExecuteWorkflow($workflowId: String!, $payload: JSON) { executeWorkflow(workflowId: $workflowId, payload: $payload) { status result } }",
"variables": {
"workflowId": "",
"payload": { "question": "Hello, what can you do?" }
}
}'
```
You should get a JSON response with `status` and `result`. If you see `401`, check your API key and `x-project-id`. If you see `404`, confirm the Flow is deployed and the workflow ID is correct.
### Step 5: Integrate the SDK (optional)
```bash
npm install lamatic
```
See [API & SDK](/docs/sdk) and [GraphQL](/docs/interface/graphql) for full examples in JavaScript, Python, and cURL.
## Common beginner mistakes (and how to avoid them)
- **Saving the flow**: Always save your Flow before deploying, or your latest changes won’t take effect.
- **Forgetting to deploy**: If you updated keys, variables, or a Flow, deploy so changes take effect.
- **Missing credentials**: Many nodes require a model/API connection. Check the node config panel for required fields.
- **Payload mismatch**: Ensure your input payload matches what your trigger and nodes expect (field names + types).
## What’s next?
- **Core building blocks:** [Flows](/docs/flows), [Nodes](/docs/nodes), [Agents](/docs/agents)
- **Integrating from an app:** [API Overview](/docs/api-integration), [Authentication with API Keys](/docs/api-integration/api-key)
- **Hands-on tutorials:** [Guides](/guides)
---
# Glob Patterns
Source: https://lamatic.ai/docs/glob-patterns.md
# Glob Patterns
A glob is a small pattern language for matching file paths, `**/*.pdf` matches every PDF anywhere in a folder tree, for example. Several of Lamatic's file-sync integrations use globs to control which files get pulled in and indexed, instead of syncing everything.
This page is the single reference for that syntax so you don't have to guess or search elsewhere.
These integrations are built on Airbyte's file-based source connectors, which use Python's `wcmatch.glob`. **There is no working exclusion syntax.** A pattern that starts with `!` (e.g. `!**/draft/**`) is matched literally and won't match anything, this is a common mistake since `!prefix` negation works in other glob dialects (`.gitignore`, VS Code, shells), but not here. Use a positive pattern instead, see [Including only what you want](#including-only-what-you-want) below.
## Where globs are used in Lamatic
| Integration | Config field |
| --- | --- |
| [Google Drive](/integrations/apps-data-sources/google-drive#action-node-configuration) | Globs (Path Patterns) |
| [AWS S3](/integrations/apps-data-sources/aws-s3#globs-path-patterns) | Globs (Path Patterns) |
| [OneDrive](/integrations/apps-data-sources/onedrive#supported-file-types) | Globs (Path Patterns) |
| [SharePoint](/integrations/apps-data-sources/sharepoint#file-filtering-patterns) | Globs (Path Patterns) |
The field is optional on all four. If you leave it empty, the default is `**`, every file.
## Syntax
| Pattern | Meaning |
| --- | --- |
| `*` | Matches any characters within a single path segment (does not cross a `/`). |
| `**` | Matches any characters, including across folder boundaries. Used to mean "any depth" or, on its own, "everything." |
| `\|` | Separates alternatives within a single pattern (`a\|b` matches `a` or `b`). |
You can supply a single pattern as a string, or a list of patterns. A file matches if it satisfies any pattern in the list. Patterns are purely additive, there is no way to exclude or subtract.
## Common patterns
| Pattern | Matches |
| --- | --- |
| `**` | Every file, at any depth. |
| `**/*.pdf` | Every `.pdf` file, at any depth. |
| `myFolder/**/*.csv` | Every `.csv` file anywhere under `myFolder`. |
| `*/**` | Everything at least one folder deep (excludes files in the root). |
| `*/*/*/**` | Everything at least three folders deep. |
| `x/*/y/*` | Files directly inside `x//y/`. |
| `**/prefix*.csv` | `.csv` files whose name starts with `prefix`. |
| `**/file.*\|**/file` | Any file named `file`, with or without an extension. |
### Multiple patterns
```yaml
# Everything under two specific folders
globs:
- "HR/**/*"
- "Legal/**/*"
```
### Including only what you want
There is no exclusion syntax that reliably works end to end (through Studio testing and into a deployed sync). If you want everything except a subfolder or file type, don't try to subtract it, list what you *do* want instead:
```yaml
# Instead of trying to exclude "draft", include the folders you actually want
globs:
- "HR/**/*"
- "Legal/**/*"
- "Finance/**/*"
```
### Scoping to supported file types
Each file-sync integration only parses a specific set of extensions (`.pdf`, `.txt`, `.docx`, `.pptx`, `.md` as of this writing, check the integration's own page for the current list). Scoping your glob to those extensions avoids sync errors from unsupported files:
```yaml
globs:
- "**/*.pdf"
- "**/*.txt"
- "**/*.docx"
- "**/*.pptx"
- "**/*.md"
```
## Tips
- Start narrow. Test a glob against a small folder before pointing it at your whole drive, an overly broad `**` on a large source can mean a very large first sync.
- Extension filters (`**/*.pdf`) are the most common and least error-prone pattern. Folder-scoped patterns (`HR/**/*`) are useful when only part of a source is relevant.
- If files aren't syncing that you expect to, check the glob first, it's the most common cause, ahead of credentials or permissions issues.
- If you need something not covered here, [Airbyte's S3 connector docs](https://docs.airbyte.com/integrations/sources/s3) document the same `wcmatch.glob`-based syntax these integrations run on.
---
# Glossary
Source: https://lamatic.ai/docs/glossary.md
# Glossary
This glossary explains common terms and concepts you'll encounter when using Lamatic.ai. Terms are explained in beginner-friendly language.
## A
### Agent
An AI-powered component that can execute specific tasks independently or as part of a Flow. Agents are reusable and can be called via API endpoints after deployment. See [Agents](/docs/agents) for more details.
### API Key
A secret key used to authenticate requests to your Lamatic project. You include it in the `Authorization` header when making API calls. See [Authentication with API Keys](/docs/studio-keys) for more details.
### API Request (Trigger)
A trigger type that starts a Flow when an HTTP request is made to your project's endpoint. This allows external applications to trigger your workflows.
## B
### Batch Trigger
A trigger type that processes multiple items at once. For example, if a database sync finds 100 new records, the Flow runs 100 times (once per record).
## C
### Chunking
The process of breaking down large documents or data into smaller, manageable pieces. This is commonly used in RAG (Retrieval-Augmented Generation) workflows to make data easier to process and search.
### Context
In Lamatic, Context refers to your data storage system, including Vector Databases and Memory Store. This is where you store information that your AI applications can retrieve and use.
## D
### Deployment
The process of making your Flow changes live and accessible. After deploying, your latest Flow configuration becomes active and can be triggered by integrations.
## E
### Embedding
A numerical representation of text or data that captures its semantic meaning. Embeddings are used in vector databases to enable similarity searches. For example, "dog" and "puppy" would have similar embeddings even though they're different words.
### Event Trigger
A trigger type that starts a Flow when a single event occurs (e.g., a new Slack message, a webhook call). The Flow runs once per event.
## F
### Flow
A sequence of connected Nodes that process data step-by-step. Flows are the core building blocks of Lamatic - think of them as recipes that define what happens when triggered. See [Flows](/docs/flows) for more details.
## G
### GraphQL
A query language for APIs that allows you to request exactly the data you need. Lamatic uses GraphQL for triggering workflows and querying results. You don't need to know GraphQL to use Lamatic, but it's helpful for integrations.
## I
### Index
The process of storing data (usually as embeddings) in a Vector Database so it can be quickly retrieved later. When you "index" a document, you're making it searchable.
## L
### LLM (Large Language Model)
An AI model trained on vast amounts of text data that can understand and generate human-like text. Examples include GPT-4, Claude, and Gemini. Lamatic integrates with many LLM providers.
## M
### Memory Store
A storage system that allows your AI applications to remember information across multiple interactions. Useful for chatbots and applications that need context from previous conversations.
### Model
In Lamatic, a Model refers to an AI model configuration (like GPT-4, Claude, Gemini) that you can use in your Nodes and Agents. You configure models in Studio under the Models section.
## N
### Node
A single step in a Flow that performs a specific action. Nodes are the building blocks of Flows - each node takes input, processes it, and produces output for the next node. See [Nodes](/docs/nodes) for more details.
**Node Categories:**
- **Apps Nodes**: Connect to external services (Slack, PostgreSQL, etc.)
- **AI Nodes**: Perform AI operations (text generation, RAG, etc.)
- **Data Nodes**: Manipulate and transform data
- **Logic Nodes**: Control flow execution (conditions, loops, code)
## P
### Payload
The input data sent to a Flow when it's triggered. The payload structure must match what your Flow expects (defined by your trigger and nodes).
### Project
A container in Lamatic Studio that holds all your Flows, Agents, Models, and configurations. Each Project is isolated with its own settings, credentials, and deployments.
### Project ID
A unique identifier for your Project. You'll need this when making API calls to specify which project to use.
### Project URL
The GraphQL endpoint URL for your Project. This is where you send requests to trigger your Flows.
## R
### RAG (Retrieval-Augmented Generation)
An AI technique that enhances LLM responses by retrieving relevant information from a knowledge base before generating a response. This makes AI responses more accurate and up-to-date. See [RAG Concept](/docs/concepts/rag) for more details.
### Response Node
The final node in a Flow that sends output back to the caller. This is what external systems receive when they trigger your Flow.
## S
### Schema
A definition of the structure of data (what fields exist, their types, etc.). In Lamatic, you define schemas for Flow inputs and outputs to ensure data consistency.
### Studio
Lamatic's web interface where you build, test, and deploy your AI applications. Access it at [studio.lamatic.ai](https://studio.lamatic.ai).
### Supervisor Agent
An Agent type that orchestrates multiple other Agents, routing tasks and managing execution flow. Useful for complex multi-step AI workflows.
## T
### Template
A pre-built Flow that you can use as a starting point. Templates help you get started quickly without building everything from scratch.
### Trigger
The starting point of a Flow - the event or request that initiates execution. Common triggers include API requests, webhooks, scheduled jobs, and app integrations (like Slack messages).
## V
### Vector Database
A database that stores data as embeddings (vectors) and enables fast similarity searches. When you search a vector database, it finds items that are semantically similar to your query, not just exact matches.
### Vectorize
The process of converting text or data into embeddings (numerical vectors) that can be stored in a Vector Database.
## W
### Workflow
Another term for Flow - a sequence of steps that process data.
### Workflow ID
A unique identifier for a specific Flow. You'll need this when triggering a Flow via API.
---
## Still have questions?
- Check out our [Quickstart Guide](/docs/get-started) to get hands-on experience
- Browse our [Guides](/guides) for step-by-step tutorials
- Review our [Concepts](/docs/concepts) section for deeper explanations
---
# IDE
Source: https://lamatic.ai/docs/ide.md
# IDE (Integrated Development Environment) in Lamatic
In Lamatic, the IDE refers to the built-in interactive tools that help you easily build, debug, and optimize flows within the platform. Similar to traditional code IDEs, Lamatic's IDE provides a comprehensive environment for creating and managing flows efficiently.
Lamatic offers three specialized IDEs to cater to different aspects of flow development:
1. Prompt IDE
2. Code IDE
3. GraphQL IDE
## Current Capabilities
| **Capability** | **Prompt IDE** | **Code IDE** | **GraphQL IDE** |
| -------------- | -------------- | ------------ | --------------- |
| **Examples** | ✅ | ✅ | ✅ |
| **Test** | ✅ | ✅ | ✅ |
| **Debug Info** | ✅ | ⚠️ | ✅ |
| **Automatic Generation** | ❌ | ❌ | ✅ |
| **Chat** | ❌ | ❌ | ❌ |
---
# Lamatic Docs
Source: https://lamatic.ai/docs.md
export const JsIcon = () => (
);
export const PythonIcon = () => (
);
export const ReactIcon = () => (
);
export const NextIcon = () => (
);
export const GoIcon = () => (
);
export const ApiIcon = () => (
);
export const McpIcon = () => (
);
# Lamatic.ai Docs
Build, deploy, and monitor production AI applications. Lamatic gives cross-functional teams a single platform to design **Flows**, run **Agents**, and ship them to the edge.
---
## Start here
Quickstart
Go from zero to a deployed Flow in about 5 minutes.
Templates
Start from a working Flow instead of a blank canvas.
Architecture
How Flows, Nodes, and the edge runtime fit together.
## Learn the concepts
Flows
Build agents, processes, and automations with no-code and low-code interfaces.
Nodes
The building blocks of every flow: AI generation, data lookup, branching, integrations.
Agents
Specialised AI nodes that reason, route, and orchestrate multi-step work.
Models
Connect any LLM provider: OpenAI, Anthropic, Bedrock, Gemini, and more.
Data & Context
Vector and memory stores attached to your project for RAG and stateful agents.
Studio
The collaborative editor where teams design, test, and deploy flows.
## Deploy and monitor
Ship to production, schedule recurring runs, and watch everything in real time.
Deployments
Ship a Flow to Lamatic's global edge network.
Jobs & Scheduling
Run recurring syncs and scheduled Flow executions.
Logs
Trace every request, node by node, in real time.
Reports
Track usage, cost, and feedback across your Flows.
## Connect with code
Drive Lamatic from anywhere: your app, your terminal, or an AI assistant.
JavaScriptReactNext.jsPythonGoGraphQL APICLIMCP
## See it in action
## Frequently asked questions
## Stay updated
Lamatic ships fast. The [changelog](https://product.lamatic.ai/changelog) lists every release. Join our [Slack](/slack) for product chat, file requests on the [feature board](https://product.lamatic.ai/), or report bugs via [GitHub issues](https://github.com/Lamatic/docs/issues).
Get major-feature announcements in your inbox:
---
# Interfaces
Source: https://lamatic.ai/docs/interface.md
# Interfaces for Integrating AI Features
After your project is deployed and your flows are passing tests, these interfaces are the ways you plug Lamatic into real products and channels.
Interfaces provide various options to seamlessly integrate and embed AI features into your application. These interfaces offer flexibility and power, allowing you to harness the full potential of AI within your project. Once your project is deployed, you can easily access the automatically generated setup documentation. This documentation is conveniently located within the flow or at the top bar of your project, ensuring you have all the necessary information at your fingertips.
## Methods
### GraphQL API
The GraphQL API enables both synchronous and asynchronous API requests. It uses a configurable schema for input and output responses, providing maximum flexibility. To use it, send a request to the API endpoint with a flowID. Our system manages the request queue and ensures timely, accurate resolution, letting you focus on your application logic.
[**Set up GraphQL →**](/docs/interface/graphql)
### Mailhook
Mailhook is a trigger node that runs your flow when an email is received. Any email sent to the mailhook address triggers the flow, with metadata and content (subject, body, attachments) included in the payload for processing.
[**Set up Mailhook →**](/docs/interface/mailhook)
### Webhooks
For third-party applications or services, webhooks offer a seamless solution for running asynchronous requests. Webhooks provide real-time updates and trigger actions based on specific events, automating processes across your application ecosystem. This integration allows for smooth interaction with external systems.
[**Set up Webhooks →**](/docs/interface/webhooks)
### Widgets
The widget solution allows for quick integration of Generative AI features into your website. With just a few lines of code, you can embed powerful AI capabilities into web pages. The pre-built widgets are user-friendly and designed to enhance your website’s functionality without extensive development work. Whether you’re adding chatbots, content generation, or other AI-powered features, these widgets make it simple to bring advanced AI to your users.
[**Explore Widgets →**](/docs/interface/widgets/chat)
---
# IP Allowlisting
Source: https://lamatic.ai/docs/ips.md
# IP Allowlisting
Use this page when your database, API, webhook receiver, or self-hosted tool is protected by a firewall, IP allowlist, private network rule, or reverse proxy policy.
Lamatic can connect to external systems through more than one network path depending on the feature you use. In practice, most teams should allowlist the Lamatic static IPs below and also include the published Cloudflare IP ranges when traffic originates from edge workers.
Always keep your allowlist as narrow as possible. Only allow the Lamatic IPs and network ranges required for the features you use.
## When you need to allowlist IPs
You may need to update your firewall or network policy when:
- Lamatic connects to your **database** such as PostgreSQL, MySQL, or Microsoft SQL Server
- Lamatic sends requests to your **internal APIs** or external applications
- Lamatic calls your **webhook endpoints**
- Your self-hosted tools such as **n8n**, **Firecrawl**, or similar services only accept traffic from approved source IPs
- Your cloud services use **security groups**, **network ACLs**, or **IP-based access policies**
## Why there are multiple IP groups
Lamatic uses different infrastructure paths for different workloads:
- **Global IPs** cover core Lamatic platform traffic used for general external connectivity
- **Data ETL IPs** are dedicated static egress IPs for data sync and connector workloads
- **Cloudflare worker IP ranges** are relevant for Lamatic edge and worker-based traffic because Lamatic runs on Cloudflare-backed infrastructure
If you are unsure which path applies to your setup, allowlist all IPs on this page first, verify connectivity, and then narrow the policy if needed.
## Lamatic IPs to allowlist
### Global
Allowlist these IPs for general Lamatic outbound connectivity:
- `68.183.131.192`
- `167.99.227.79`
### Data ETL
Allowlist these IPs for database sync, ETL, and connector workloads:
| Environment | IP address |
| --- | --- |
| Pro | `138.197.51.144` |
| Enterprise | `138.197.234.83` |
## Cloudflare worker IP ranges
Lamatic edge traffic can also originate from Cloudflare worker infrastructure. If your target system uses strict IP-based rules, include the current Cloudflare IP ranges in addition to the Lamatic static IPs above.
### IPv4 ranges
- `103.21.244.0/22`
- `103.22.200.0/22`
- `103.31.4.0/22`
- `104.16.0.0/12`
- `108.162.192.0/18`
- `131.0.72.0/22`
- `141.101.64.0/18`
- `162.158.0.0/15`
- `172.64.0.0/13`
- `173.245.48.0/20`
- `188.114.96.0/20`
- `190.93.240.0/20`
- `197.234.240.0/22`
- `198.41.128.0/17`
### IPv6 ranges
- `2400:cb00::/32`
- `2405:8100::/32`
- `2405:b500::/32`
- `2606:4700::/32`
- `2803:f800::/32`
- `2c0f:f248::/32`
- `2a06:98c0::/29`
Cloudflare can update these ranges over time. Before finalizing a production firewall policy, verify the latest published ranges at cloudflare.com/ips.
## Which IPs to use by scenario
| Scenario | Allowlist |
| --- | --- |
| PostgreSQL, MySQL, Microsoft SQL Server, or other database connectors | Lamatic **Global** IPs and **Data ETL** IPs |
| Outbound API calls from flows or the API Node | Lamatic **Global** IPs and **Cloudflare worker IP ranges** |
| Incoming webhook receivers exposed behind your firewall | Lamatic **Global** IPs and **Cloudflare worker IP ranges** |
| Self-hosted integrations such as n8n or Firecrawl | Lamatic **Global** IPs, **Data ETL** IPs if used, and **Cloudflare worker IP ranges** |
| Unsure which feature path applies | Allowlist **all IPs and ranges on this page** first, then narrow after testing |
## Recommended setup steps
1. Identify every Lamatic feature that will reach your system, such as a database sync, webhook trigger, API node call, or self-hosted integration.
2. Add the required IPs and ranges from this page to your firewall, reverse proxy, security group, or network ACL.
3. Confirm the target port is open for the required protocol, such as `443`, `5432`, `3306`, or `1433`.
4. Keep TLS or SSL enabled where supported. IP allowlisting should complement transport security, not replace it.
5. Test the connection from Lamatic again.
6. Review logs on both sides to confirm the request is reaching your service.
## Additional guidance
### For databases
- Prefer a dedicated read-only user where possible
- Restrict access to the minimum set of schemas, tables, and ports required
- If your database is behind a bastion or SSH tunnel, update those network rules as well
### For webhooks and APIs
- Make sure your WAF, API gateway, or reverse proxy trusts the same IPs
- If you use rate limiting or bot protection, create an allow rule for Lamatic traffic
- Verify that your endpoint accepts HTTPS requests and returns the expected status codes
### For self-hosted services
- Apply allowlist rules at every layer that can block traffic, including load balancers, ingress controllers, host firewalls, and cloud security groups
- Re-test after infrastructure changes, certificate rotations, or firewall updates
## Troubleshooting checklist
- Confirm the host, port, and DNS record are correct
- Check whether the block is happening at the firewall, proxy, VPN, or database level
- Verify SSL or TLS settings independently from the IP allowlist
- If connectivity still fails, temporarily allow all IPs from this page together to rule out a missing source range
## Related docs
- [API Keys](/docs/api-integration/api-key)
- [Flow Integration](/docs/flow-integration)
- [Webhooks](/docs/interface/webhooks)
- [API Node](/docs/nodes/data/api-node)
- [PostgreSQL](/integrations/apps-data-sources/postgres)
- [MySQL](/integrations/apps-data-sources/mysql)
- [Microsoft SQL Server](/integrations/apps-data-sources/microsoft-sql-server)
---
# Jobs
Source: https://lamatic.ai/docs/jobs.md
# Automated Data Synchronization and Scheduled Processes in Flows

Explore the automated data synchronization and scheduled process configuration within the flows. Our system provides a comprehensive view of these automated operations, allowing you to monitor and manage your data flows efficiently.
Jobs are automatically generated when you configure a **Batch Trigger** node within a flow. This automation streamlines the process of setting up recurring tasks, ensuring that your data operations run smoothly without manual intervention.
---
## Connections
Each Job is uniquely represented as a distinct setup, identified by its corresponding flow name. This organization allows for easy management and customization of your data processes. You have the flexibility to activate or deactivate these jobs directly, and then deploy the project to implement these changes across your system.
---
### Job History
Access a comprehensive historical record of all job executions. This feature provides valuable insights into the performance and consistency of your data operations over time.
- **Size**: The total volume of all records processed in batch requests, giving you an overview of the data throughput.
- **Records extracted**: The quantity of records successfully retrieved from the source, indicating the effectiveness of your data extraction process.
- **Records loaded**: The number of records successfully processed and loaded as individual requests, showing the efficiency of your data loading mechanism.
- **Time**: The duration required to complete the job execution, helping you monitor and optimize performance.
> **Important**: The job time differs from the complete execution time of the entire batch. The total execution duration depends on the completion of all requests within the batch, which may vary based on complexity and volume.
---
### Config
Configure the settings for your job to align with your specific requirements and operational needs.
- **Schedule Type**: This parameter determines the triggering mechanism for your data synchronizations, allowing you to set up the most suitable timing for your operations.
- **Cron Expression**: A CRON-formatted schedule to define when the job should run, providing precise control over the timing of your data processes.
| **Cron String** | **Sync Timing** |
| --- | --- |
| 0 0 * * * ? | Every hour, at 0 minutes past the hour |
| 0 0 15 * * ? | At 15:00 every day |
| 0 0 15 * * MON,TUE | At 15:00, only on Monday and Tuesday |
| 0 0 0,2,4,6 * * ? | At 12:00 AM, 02:00 AM, 04:00 AM, and 06:00 AM every day |
| 0 0 _/15 _ * ? | At 0 minutes past the hour, every 15 hours |
- **Timezone**: Specify the timezone for your sync to ensure that jobs run at the appropriate local time, regardless of server location.
---
### Force Sync
For situations requiring immediate action, you can manually initiate a job using the **force sync** option. This feature instantly triggers the job execution, allowing you to run data synchronizations on-demand outside of the scheduled times.
> **Note**: When operating in **Incremental Sync Mode** (which only loads new and updated records), force syncing will not process records from failed requests. This limitation is in place to maintain data integrity and prevent potential duplications.
To address records in failed requests, you should adjust the Sync Mode to **Full Refresh** and execute a complete synchronization. It's crucial to ensure that a **primary key attribute** is properly configured in the Index Node setup to facilitate accurate record matching and updating during this process.
---
# Limits & Quotas
Source: https://lamatic.ai/docs/limits.md
# Limits & Quotas
Practical limits for building and running workflows on Lamatic. Use this when designing flows, sizing jobs, or explaining plan differences.
**Enforced** means a hard limit. Exceeding it fails or is blocked in Studio.
**Recommended** means it isn't always blocked, but ignoring it makes runs more likely to time out, run out of memory, or fail under load.
---
## How long a flow can run
| Mode | Limit | Notes |
|------|-------|-------|
| **Sync** (waits for a response) | ~2 minutes on Pro, ~5 minutes on Enterprise | Best for APIs and widgets that return a result immediately. Keep the flow small. |
| **Async** | Up to ~20 minutes on the standard path | Trigger response type must be set to **async**. Returns a request ID right away, and the flow continues in the background. |
| **Container mode** (opt-in, for memory-heavy flows) | Up to 1 hour | For flows that need more memory. Turn it on at the project or flow level when standard runs are running out of memory. |
**Recommended flow size**
| Mode | Guidance |
|------|----------|
| Sync | ~20 nodes max |
| Async | ~50 nodes max |
Larger flows are harder to debug and more likely to hit time or memory limits. Split big workflows into smaller flows and call them with a **Flow** node.
---
## Memory
| Runtime | Limit |
|---------|-------|
| Standard execution | 128 MB |
| Container mode (opt-in) | 6 GB |
If a flow consistently fails with memory errors, enable **container mode** for that project or flow, reduce batch concurrency, or shrink payloads.
---
## Loops, batches, and agents
| Limit | Value | Type |
|-------|-------|------|
| Nodes inside a loop, batch, or agent body | 20 | Enforced for Starter and Pro. Unlimited on Enterprise. |
| Nodes inside a batch body | 5 or fewer recommended | More nodes per iteration raise memory use. Prefer a sub-flow for larger logic. |
| Batch concurrency (parallel items) | 1 to 50, default 10 | Configurable on the Batch node. |
| Nested Batch nodes | Not allowed | Enforced. |
| Batch iterations (Starter / free) | 100 max | Enforced. |
If you need more than 20 nodes inside a loop or batch, put the extra logic in a separate flow and call it with a **Flow** node.
---
## Code node
| Limit | Value |
|-------|-------|
| Processing time | ~2 minutes on Pro, ~5 minutes on Enterprise |
| Code size | 10,000 characters max |
| Restricted APIs | Node process APIs such as `require`, `eval`, and `child_process` are blocked |
---
## Jobs (data syncs)
Jobs are scheduled syncs from sources such as databases, sheets, and storage.
| Limit | Pro / Starter | Enterprise |
|-------|----------------|------------|
| Active jobs | 10 or fewer recommended | Higher, contact Lamatic |
| Sync capacity | Shared infrastructure (~2 GB) | Dedicated infrastructure with higher capacity |
Need more jobs or larger syncs? Use **Enterprise**.
**Default job processing settings** (Settings → Jobs)
| Setting | Default |
|---------|---------|
| Batch size | 5 |
| Max concurrency | 5 |
| Max retries | 3 |
---
## Plan limits
### Starter
| Resource | Limit |
|----------|-------|
| Flows per project | 5 |
| Starter projects per organization | 1 active |
| Workflow executions | 3,000 per 30 days, 100 per day |
| Vector records / writes | 1,000 each |
| Reports & charts history | 7 days |
| Team members | 3 (unless the org has a Pro project or is Enterprise) |
| AI Assistant | Not available |
### Pro / Trial
| Resource | Limit |
|----------|-------|
| Workflow executions | 100,000 |
| Vector records / writes | 10,000 each |
| Reports & charts history | 30 days |
| Sync flow duration | ~2 minutes of processing time per run |
| AI Assistant | Available |
### Enterprise
| Resource | Limit |
|----------|-------|
| Workflow executions | Unlimited |
| Vector / request caps | Unlimited |
| Sync flow duration | ~5 minutes of processing time per run |
| Nodes inside loops / batches | Unlimited |
| Jobs / sync capacity | Dedicated, higher capacity |
| Reports & charts history | Up to 90 days |
---
## Other limits
| Limit | Value |
|-------|-------|
| Nested Flow calls (flow calling flow) | 100 levels max |
| Large async payloads | Inputs above ~125 KB are stored automatically and still work |
| Flow retries (configurable) | Max retries 5 or fewer, retry delay 30 seconds or less |
---
## Quick tips
1. Keep 5 or fewer nodes inside a Batch. Use a sub-flow for more.
2. Keep sync flows to about 20 nodes, or switch the trigger to async.
3. Keep Code node work under the plan's processing time budget (~2 minutes on Pro).
4. Keep active jobs to about 10 or fewer on Pro. Use Enterprise for more.
5. For memory-heavy flows, enable container mode or reduce batch concurrency and payload size.
---
Hitting a `429` or a failed run? See the [Error Reference](/docs/error-reference) page for what each status code means and how to fix it.
---
# Logs
Source: https://lamatic.ai/docs/logs.md
# Logs: Monitoring and Analyzing Requests in Real Time

Logs provide an invaluable way to monitor and analyze requests to your project in real-time, offering deep insights into your application's performance and behavior. This powerful feature allows you to track and troubleshoot issues efficiently, ensuring optimal functionality of your system.
---
The Log Dashboard provides a centralized view of workflow executions, showing details about each trigger, flow, and execution status.
- **Date and Time**: Logs when each event occurred (Local & UTC).
- **Status**: Indicates the status code of the execution (e.g., 200 for success).
| Status Code | Description |
|-------------|--------------------------------------------------------------------------------------------------------------|
| 200 | Success - Indicates that the request was processed successfully without any errors. |
| 204 | Successful execution of retried request. |
| 208 | Node has skipped its execution when retried the request. Applicable for retries triggered from a failed node.|
| 303 | Fallback Model is used. |
| 400 | Bad Request. Malformed request payload or invalid input. |
| 401 | Unauthorized. Invalid or missing API key. |
| 403 | Forbidden. Valid credentials, insufficient permissions. |
| 404 | Not Found. Flow, node, or resource doesn't exist. |
| 422 | Unprocessable Entity. Input didn't match expected schema/validation. |
| 429 | Too Many Requests. Rate limit exceeded. |
| 500 | Flow Error - Signifies that an error occurred during the request processing, requiring further investigation. |
| 509 | Failed execution of retried request. |
**Upstream/Provider Errors** — errors from the LLM provider, not your flow:
| Status Code | Description |
|-------------|--------------------------------------------------------------------------------------------------------------|
| 502 | Bad Gateway. The model provider (OpenAI, Anthropic, etc.) itself errored. |
| 503 | Service Unavailable. Provider overloaded/down, no fallback model available. |
| 504 | Gateway Timeout. Model provider took too long to respond. |
- **Flow**: Unique FlowID associated with the request, enabling you to trace the entire lifecycle of a specific operation through your system..
- **Trigger Node**: The source of the trigger (e.g., API Request, Slack, Google Drive).
- **Input**: Inputs provided to the Flow (partial text is visible).
- **Process Time**: Total turnaround time of the requests, providing valuable insights into performance metrics and potential bottlenecks in your application..
- **Tokens**: Token usage in the Flow
---
## Node Level Traces

To gain a more granular understanding of your system's operations, you can examine the logs of individual nodes within a request.
1. Select any request of interest to open the complete request trace.
2. Navigate to the **Node Execution Logs** section.
3. Click on the specific node you wish to investigate.
This detailed view allows you to pinpoint exactly where issues occur in your processing pipeline, facilitating more efficient debugging and optimization.
---
## Search and Filtering Logs
To efficiently manage and analyze your log data, the system provides powerful search and filtering capabilities. These features enable you to quickly locate specific information and identify patterns or issues within your logs.

> **Note**: The comprehensive search capability ensures that you can locate even the most specific details within your log data.
- **Search**: Offers deep, query-level results, allowing you to find any keyword in request inputs, outputs, or within individual node inputs and outputs.
- **Date Range**: The Date Range filter allows users to focus on logs generated within a specific time period.
- **Filter**: Filters refine the logs based on specific attributes such as Status, Flow, Process Time, and more.
You can reload the logs by clicking on the Refresh icon.
---
## Exporting Logs
The Export feature allows users to download the filtered or complete log data in a file format for external storage, sharing, or analysis.
---
# Models
Source: https://lamatic.ai/docs/models.md
# Models in Generative AI Projects
Models are the fundamental building blocks of any Generative AI project. They serve as the cognitive engines that power agentic flows, enabling sophisticated decision-making and content generation. These models are the cornerstone of AI-driven applications, providing the intelligence and capabilities that make advanced functionalities possible. [Lamatic.ai](http://Lamatic.ai) offers seamless integration with a diverse array of models through built-in connections and efficient proxies, streamlining the development process for AI practitioners.
## Prerequisites
- A Lamatic Project in Studio
- Basic understanding of [Flows](/docs/flows) and [Nodes](/docs/nodes)
- API keys from model providers (OpenAI, Anthropic, etc.) if you want to use external models
## Understanding Models
**Models** are AI systems trained on vast amounts of data that can understand and generate content. In Lamatic, you configure models once in your Project, then use them across multiple Flows and Nodes.
Think of models as "AI engines" - you set them up once, then your Flows can use them to generate text, analyze images, or process other types of content.
---
## Model Types
| **Model Type** | **Description** | **Availability** |
|--------------------|-------------------------------------------------------------------------------------------------------------------------------------------------------|------------------|
| **Text** | Sophisticated text generation based on input prompts, capable of producing coherent and contextually relevant content | ✅ |
| **Chat** | Interactive text generation that considers both the initial prompt and the ongoing conversation history, enabling dynamic and context-aware responses | ✅ |
| **Multimodal** | Advanced text generation with comprehensive understanding capabilities, including the ability to process and interpret images, documents, and more | ✅ |
| **Image Generation** | Creation of visual content based on textual descriptions, allowing for the production of unique and customized images | ✅ |
| **Audio Transcript** | Accurate conversion of spoken language into written text, facilitating the transcription of audio content | 🚧 |
| **Audio Generation** | Transformation of written text into natural-sounding speech, enabling voice synthesis for various applications | 🚧 |
| **Video** | Production of video content from textual prompts, allowing for the creation of dynamic visual narratives | ❌ |
---
## Providers
Models are typically offered by providers, which are companies or organizations responsible for the development, training, and hosting of these AI models. These providers invest significant resources in creating and maintaining state-of-the-art models that can be leveraged by developers and businesses. For open-source models, the provider may be the organization or company that hosts and maintains the model infrastructure, even if they didn't originally develop the model.
### Available Providers
> **Note**: You can explore a variety of providers to find the models that best suit your specific project requirements using [Benchmarks](/ ).
---
## Adding a New Provider → Model
To use a model in your flow, you first add API credentials for that provider. Lamatic stores these keys securely and only uses them when making requests. You can delete or rotate credentials at any time, and you can maintain separate credentials per provider—or separate sets for Development and Production for better usage tracking.
> **Tip**: Set up separate API credentials for Development and Production in Lamatic for clearer monitoring and management of usage across stages.
**High-level steps:** Get API keys from the provider → add and configure the model in Studio (see below) → test and save.
---
## Setting Up a Model in Studio
Configure your model credentials in Studio so they’re available to your flows.
**Navigate to the Models page:**
1. Go to **Studio**
2. Open **Connections**
3. Click on **Models**
4. Click **Add Model** (or select an existing model to edit)

**Configure the model:**
1. **Credential Name**: A human‑readable name for this model credential (e.g. "Prod OpenAI GPT‑4").
2. **Provider**: Select the model provider (e.g. `openai`, `anthropic`, etc.).
3. **API Key / Auth**: Paste the API key or other authentication secret required by the provider.
4. **Custom Models (Optional)**: Add a custom model ID or configuration if you're using a non‑default model from that provider.
You can **Save as Draft** (keep the configuration without using it in flows yet) or **Test & Save** to validate the credentials and make the model available to your flows.
---
## Using Models in a Flow
Lamatic's flexible architecture allows you to incorporate multiple models, either of the same type or different types, within a single flow. To integrate a model into your flow, begin by dragging a compatible node (such as a Text LLM node) into the flow builder interface. Once placed, you can select the desired model from the list of available options, which are populated based on the credentials you've added for various providers.
---
## Model Defaults
Lamatic offers a convenient feature that allows you to establish default models for your entire project. When you drag a compatible node into the flow, these default models are automatically selected, streamlining your flow. If you decide to modify the default model settings, the changes will be reflected across all instances where the default option is selected. This functionality provides a quick and efficient method to switch between models on a project-wide scale, eliminating the need to manually update individual model selections throughout your flow.
> **Quick Tip**: Setting up default models allows you to quickly switch models project-wide without having to change them individually in each flow node.
## Troubleshooting
- **Model not appearing in node**: Make sure you've added credentials for that model provider in Studio > Models
- **API key errors**: Verify your API key is correct and has sufficient credits/quota
- **Model not responding**: Check your internet connection and the model provider's status page
- **Default model not applying**: Ensure you've saved the default model settings in Project Settings
## Next steps
- **Learn about specific model types**: Explore [Model Integrations](/integrations) for detailed setup guides
- **Use models in Flows**: Read about [AI Nodes](/docs/nodes) to see how to use models in your workflows
- **Optimize model usage**: Check [Best Practices](/docs/models/model-logic#best-practices) for tips on choosing the right model for your use caseUsing Models in a Flow
---
# Nodes
Source: https://lamatic.ai/docs/nodes.md
# Nodes
Nodes are the fundamental building blocks of a flow in Lamatic. Each node serves a specific purpose, acting as a self-contained unit that processes input and produces output. This modular approach allows users to create complex flows by interconnecting various nodes.
## What you’ll learn
- What Nodes are and how they fit into a Flow
- The main Node categories (Apps, AI, Data, Logic)
- How to choose the right Node for your use case
## Prerequisites
- Basic understanding of [Flows](/docs/flows)
## How to think about Nodes
If a Flow is a “recipe”, then **Nodes are the steps**:
- Each node has **inputs**
- It performs one job
- It produces **outputs** that the next node can use
## Node Categories
Lamatic organizes nodes into four main categories, each with a unique function in building flows:
| **Category** | **Purpose** | **Examples** | **Method** |
|--------------|-------------------------------------------------|------------------------------------------------|--------------------------------------------------------------------------------------------------------------------------------------------------|
| **Apps** | Integrate third-party applications into workflow | Slack, PostgreSQL, Google Sheets | These nodes act as bridges, enabling data exchange and action execution between Lamatic and external services. |
| **AI** | Perform artificial intelligence operations | Vector operations, text generation, natural language understanding | AI nodes use machine learning models to process and analyze data, allowing for tasks such as sentiment analysis, text classification, or content generation. |
| **Data** | Manipulate and transform data | Indexing, chunking, filtering | Data nodes provide tools for structuring, organizing, and processing information, ensuring data is in the right format for subsequent nodes. |
| **Logic** | Control the flow of execution | Conditional statements, loops, custom code execution | Logic nodes allow for decision-making and branching, enabling dynamic, responsive flow based on specific conditions or criteria. |
## How to choose the right Node
- **Need to talk to another tool/app?** Use an **Apps** node.
- **Need an LLM or AI operation?** Use an **AI** node.
- **Need to clean/transform/store/search data?** Use a **Data** node.
- **Need conditions/branching/code?** Use a **Logic** node.
Not sure what to pick? Start from your trigger and ask: “what’s the next step in my pipeline?” Then add the node that does only that step.
## Here are the Nodes
## Troubleshooting
- **Can’t find a node**: make sure you’re in the Flow Editor and click **Add Node**.
- **Node requires credentials**: check the node config panel for required connections (models/apps).
- **Output doesn’t match expectation**: run a test and inspect node outputs step-by-step.
## Next steps
- Learn how to build with Nodes in the [Flow Editor](/docs/flows/editor)
- Browse common patterns in [Guides](/guides)
---
# Confidential Reporting
Source: https://lamatic.ai/docs/report-issue.md
# Confidential Whistleblower Reporting
Speak up safely and securely about potential violations or concerns
This Whistleblower Form is intended to encourage and enable employees and others to communicate potential legal and ethical concerns to appropriate leadership and oversight teams to allow Vanta to address and correct inappropriate conduct and actions. It is the responsibility of all board members, officers, employees, and contractors to report concerns about violations of code of ethics or suspected violations of law or regulations that govern Vanta’s operations.
All information gathered will remain anonymous and only provided to appropriate teams
to facilitate escalation and remediation. It is prohibited by Vanta for anyone to
retaliate against any individual who in good faith reports an ethics violation or
a suspected violation of law, such as a complaint of discrimination, suspected fraud,
or potential violation of any regulation related to Vanta's operations. Any employee
who retaliates against an individual who has reported a violation in good faith is
subject to disciplinary measures, up to and including termination of employment.
Reports of violations or suspected violations will be kept confidential to the extent
possible, consistent with the need to conduct an adequate investigation.{" "}
## What Happens Next?
1. Your report is securely transmitted to our compliance team.
1. A preliminary review will be conducted.
1. If additional information is needed, it will be requested through this system.
1. Appropriate action will be taken based on the investigation findings.
---
# Reports
Source: https://lamatic.ai/docs/reports.md
# Reports
**Reports are in alpha**
Reports is currently an alpha feature, and not publicly available. If you see inaccuracies please report to support.

Gain comprehensive insights into your project's performance with our centralized reporting system. Access critical project metrics and analytics all in one convenient location, enabling you to make data-driven decisions efficiently.
---
The **Reports Dashboard** provides detailed analytics and insights into your project usage in Lamatic.
It helps you track tokens, costs, response times, and error rates across different flows.
---
## Overview
At the top of the dashboard, you’ll find quick stats:
- **Avg Response Time** → Average time taken to respond (e.g., `1.8s`)
- **Total Tokens** → Total tokens consumed across flows (e.g., `29.1k`)
- **Total Cost** → Total cost calculated based on token usage (e.g., `$0.00`)
- **Error Rate** → Percentage of requests that resulted in errors (e.g., `100%`)
- **Total Requests** → Number of total requests processed (e.g., `350`)
You can filter the reports by **Time Range** and **Flows**.
---
## Report Widgets
| Widget | Description |
|-----------------------|-----------------------------------------------------------------------------|
| **Requests by Flow** | Pie chart showing the distribution of requests across flows. Helps identify which flow is used most frequently. |
| **Token Usage by Flow** | Bar graph showing how many tokens each flow consumed. Useful for understanding resource-heavy flows. |
| **Response Time Trends** | Line graph tracking average response times over the selected period. Helps detect performance degradation. |
| **Cost Trends** | Chart showing token cost trends over time. Useful for monitoring budget and cost efficiency. |
| **Token Usage Over Time** | Line chart showing how token usage changes throughout the selected timeframe. |
| **Hourly Distribution** | Bar chart showing requests distribution per hour. Useful for identifying peak usage times. |
| **Error Trends** | Chart showing error rate trends over time. Helps debug recurring issues. |
| **Token Costs by Flow** | Breakdown of token costs per flow. Identifies the most expensive flows. |
---
## Usage
Use this dashboard to:
- Track performance across different flows
- Monitor errors and optimize flows accordingly
- Analyze token usage and cost trends
- Understand when your project is most active
---
> **Tip:** Use filters (`Time Range`, `Flows`) to narrow down the insights for specific scenarios.
---
# Templates
Source: https://lamatic.ai/docs/templates.md
# Templates in Lamatic

Templates in Lamatic provide a streamlined way to create flows using pre-configured node sets, reducing the need for manual setup. This guide covers key processes for using templates effectively.
## Creating a New Flow from a Template
To create a flow using a template in Lamatic Studio:
- Start a new flow in the Studio interface.
- Navigate to the **Template Selection** menu.
- Choose a template from the available options.
- Complete all required fields within the template.
- Test the flow thoroughly to ensure it works as expected.
- Once verified, deploy your flow.
## Sharing Templates
### Sharing Within Your Team
To share templates with team members:
- Click the **Export** button in the left sidebar.
- Select **Share with Team**.
- Shared templates will appear under **Team Templates** for organization members.
### Publishing Templates to the Lamatic Hub
To contribute to the Lamatic community by publishing templates:
**Important:** Avoid sharing sensitive information like API keys or private URLs, especially within code nodes.
- Click the **Export** button in the left sidebar.
- Choose **Publish Flow**.
- Complete all required information for your template.
- Submit the template for review by the Lamatic team.
- Once approved, your template will be available on the Hub, credited to you as the creator.
Following these steps enables efficient creation, sharing, and publication of templates, enhancing your workflow and contributing to the Lamatic community.
---
# Version Control
Source: https://lamatic.ai/docs/version-control.md
# Version Control in Lamatic AI
Lamatic AI introduces Version Control System (VCS) functionality at the project level, enabling users to efficiently manage, track, and revert to previous iterations of their flows. This project-level VCS feature allows for better organization, debugging, and iteration without losing prior configurations across all flows within a project.
## Setup Version Control with GitHub

1. Navigate to the Flow Editor and click Connect with GitHub.
1. Alternatively, you can go to the Integrations section under your project settings.
1. Authenticate your GitHub account and grant access to the required repositories or organization.
1. Choose an existing repository or create a new one.
1. Select the desired branch, and optionally enable auto-deployment on commit.
1. Click Save to complete the setup.
## How to Use Version Control in Flows
1. Open the desired Flow.
1. From the top navigation bar, click on the Select Branch dropdown, the production branch is selected by default.
1. From here, you can create a new branch, switch between branches, or merge and create pull requests (PRs) as needed.
### Create a new Branch
To create a new branch for your flow:
1. Click on the **Select Branch** dropdown in the top navigation bar.
1. Click on **Create New Branch** or the **+** icon.
1. Enter a descriptive name for your new branch (e.g., `feature/new-integration` or `bugfix/fix-validation`).
1. Optionally, select a base branch to branch from (defaults to the current branch).
1. Click **Create** to create the new branch.
Once created, you can switch to the new branch and make changes without affecting the production branch.

### Merge it into production Branch
To merge your branch changes into the production branch:
1. Ensure you're on the branch you want to merge (not the production branch).
1. Click on the **Select Branch** dropdown in the top navigation bar.
1. Click on **Merge Icon Button** or the merge icon.
1. Review the changes that will be merged.
1. Click **Confirm Merge** to complete the merge.
Your changes will now be available in the production branch. You can continue working on your feature branch or switch back to production.

### Pull Changes from production branch
To pull the latest changes from the production branch into your current branch:
1. Ensure you're on the branch where you want to pull changes (not the production branch).
1. Click on the **Select Branch** dropdown in the top navigation bar.
1. Click on **Pull Icon Button** or the pull icon.
1. Review any potential conflicts that may arise from the merge.
1. If there are conflicts, resolve them in the Flow Editor.
1. Click **Confirm Pull** to complete the pull operation.
This ensures your branch stays up-to-date with the latest changes from production, reducing the likelihood of merge conflicts later.

---
# Vibe Build Overview
Source: https://lamatic.ai/docs/vibe-build.md
# Build With Vibe
The Vibe Build surface is the fastest way to spin up a new Lamatic agent. From a single screen you can describe what you want to build, choose the interaction style, connect data, and start from curated templates.

## 1. Describe the agent you need
1. Start with the prompt at the top of the page and describe your goal (e.g., “Build an AI chatbot trained on my Google Drive data”).
1. Use the mode toggles (`Automation`, `Assistant`, `Embed`, `Agentic`) to hint at how the agent should behave. These presets auto-adjust the scaffolding when you create the flow.
## 2. Pick a launch shortcut
- **Integrate Google Drive** – OAuth into Drive and immediately index files for retrieval.
- **Build a chatbot with Google Drive** – Combines the Drive data source with the chatbot scaffold so you can deploy faster.
- **Chatbot on Website** – Generates an embeddable widget with starter copy and styling hooks.
- **Hiring Agent** – Loads a workflow tuned for screening candidates with resume parsing.
These shortcuts appear as pills under the prompt and can be triggered before or after editing the description.
## 3. Explore templates
Templates live in the AgentKit carousel just below the hero. Each card shows:
- The template name and quick success metrics from the community.
- A summary of what the template does (e.g., `Semantic Search`, `Knowledge Chatbot`, `Document Parsing Bundle`).
- Icons indicating the data sources or automations bundled in.
Click **Explore** or the card itself to open a preview, review the ingredients, and clone it into your workspace.
## 4. Navigate the creation workspace
The left sidebar keeps global navigation close by:
- `Flows` for editing the new agent once it’s created.
- `Prompts`, `Data`, and `Connections` to iterate on knowledge sources and prompt engineering.
- `Deployments`, `Jobs`, `Reports`, and the `API Playground` for testing and shipping.
Use the **Create** button at the top of the sidebar whenever you want to start from scratch instead of a template.
## 5. Deploy when ready
After selecting a template or shortcut, Lamatic opens the Flow Editor preloaded with the necessary blocks. From there you can:
1. Adjust the stages in the flow builder.
1. Add or remove data sources from the right rail.
1. Test the agent in the inline console before hitting **Deploy**.
Once deployed, the green `Project Deployed` badge in the header confirms the latest version is live. You can redeploy as you iterate—the Vibe Build entry point is always a click away for starting additional agents.
---
# Vulnerability Disclosure
Source: https://lamatic.ai/docs/vulnerability-disclosure.md
# Vulnerability Disclosure Program
At Lamatic, we believe in collaborating with the global security researcher community to enhance the security of our products. By welcoming researchers to identify vulnerabilities in our systems, we aim to make our products more secure while fostering a cooperative security ecosystem. To this end, we reward researchers for their valuable contributions.
## Scope of the Program
### In Scope
The following areas and vulnerabilities are included in the Vulnerability Disclosure Program:
1. **Products**
- [Lamatic.ai Studio](https://studio.lamatic.ai/) — only the web application hosted at **studio.lamatic.ai** is in scope.
2. **Vulnerability Categories**
- Cross-Site Scripting (XSS)
- SQL Injection
- Authentication flaws
- Data leakage
- Privilege escalation
### Out of Scope
The following are **not covered** by the program:
1. Any asset or subdomain other than **studio.lamatic.ai**
2. Social engineering attacks (e.g., phishing)
3. Physical security vulnerabilities
4. Denial of Service (DoS) or Distributed Denial of Service (DDoS) attacks
5. Brute-force attacks against authentication or rate-limited endpoints
6. Use of non-application attack vectors such as machine takeover, cookie takeover, local privilege escalation, or network sniffing
7. Findings based on use of intrusive tools such as **Burp Suite**, **Wireshark**, or similar packet interception/analyzer tools
8. Third-party integrations, dependencies, or services not owned or controlled by Lamatic
## Submission Guidelines
Security researchers are required to provide detailed information about identified vulnerabilities. Submissions should include:
1. A clear description of the vulnerability
2. Step-by-step instructions to reproduce the issue
3. An impact analysis outlining the potential risk
4. Supporting evidence such as screenshots, videos, or scripts
5. Recommendations for remediation
### Submission
## Response Times
We strive to provide timely responses to all submissions:
1. Initial response: **24 hours**
2. Severity assessment: **20 business days**
3. Status updates: **Every 30 business days**
4. Payment processing: **Within 60 days of validation**
## Review Process
| **Step** | **Description** |
| ---------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **1. Acknowledgment** | Confirm receipt of the report within **24–48 hours**. Assign a unique **Reference ID** to track the submission. |
| **2. Initial Assessment** | - Validate the authenticity of the issue. - Perform a **Duplicate Check** to ensure the bug hasn’t been previously reported. - Note that **multiple reports within the same exploit chain are considered one vulnerability**. - Share an NDA if necessary. |
| **3. Severity Analysis** | Assess the severity using a standard rating system such as **CVSS**: - **Critical**: Immediate, widespread impact (e.g., RCE, data breaches). - **High**: Significant functionality or security risks. - **Medium**: Moderate impact. - **Low**: Minor risks. |
| **4. Assignment & Prioritization** | Assign the validated issue to the appropriate team and prioritize based on severity. |
| **5. Development & Fixing** | Address the issue based on priority and ensure timely resolution. |
| **6. Researcher Verification** | Notify the researcher upon resolving the issue. Provide testing environments or evidence (e.g., logs, screenshots) for verification. |
| **7. Reward & Closure** | Issue the reward based on the severity, impact, and uniqueness of the vulnerability. |
| **8. Post-Resolution Analysis** | Conduct a root cause analysis to identify gaps in code review, testing, or system architecture. |
## Rules of Engagement
To ensure ethical conduct, researchers are required to adhere to the following guidelines:
| **Do’s** | **Don’ts** |
|----------------------------------------------|------------------------------------------------------------------------------------------------------|
| Test **only** within the defined scope (**studio.lamatic.ai**). | Do not test on any other Lamatic domains or services. |
| Avoid impacting production systems. | Do not use automated tools (e.g., Burp Suite, Wireshark) or network-level scanners. |
| Report vulnerabilities immediately. | Do not exploit vulnerabilities beyond proof-of-concept or attempt denial of service. |
| Operate responsibly and respect user privacy. | Do not attempt brute-force, credential stuffing, or machine-level exploitation. |
| Submit logically distinct vulnerabilities as separate reports. | Do not submit **multiple reports from the same exploit chain**, as these will be **grouped as one vulnerability**. |
## Legal Protections
### Safe Harbor Clause
Lamatic provides safe harbor for researchers acting in good faith, ensuring protection from legal consequences as long as they:
1. Operate within the defined scope and guidelines
2. Avoid compromising user data
3. Do not disrupt services
4. Responsibly report vulnerabilities through the program
## Disclosure Restrictions
By submitting a vulnerability report, you agree to abide by Lamatic’s [Terms & Conditions](https://lamatic.ai/docs/legal/terms-of-service) and the conditions outlined in this program.
- All submitted reports are **confidential** and must **not** be shared publicly — including on social media, blogs, forums, or other channels — regardless of their resolution status.
- Even if a vulnerability report is marked as **invalid**, it is **strictly prohibited** to disclose any details of the finding without explicit written consent from Lamatic.
- Breaching these terms may disqualify you from receiving a reward and could result in legal action under applicable laws.
## Rewards
| **Severity Level** | **Example Vulnerabilities** | **Reward Range** |
| ------------------ | ------------------------------------------------- | ----------------- |
| Critical | Remote code execution, data breaches | $300–$500 |
| High | Privilege escalation, bypassing authentication | $100–$300 |
| Medium | Sensitive data exposure, API misuse | $50–$100 |
| Low | Minor misconfigurations, non-sensitive info leaks | Goodies and swag |
**Note:** Rewards are determined based on the severity, reproducibility, and uniqueness of the submission.
Thank you for contributing to the security of Lamatic's products!
---
# AI Middleware
Source: https://lamatic.ai/docs/concepts/ai-middleware.md
# AI Middleware

Lamatic AI serves as a powerful **Generative AI middleware** that simplifies the integration of AI capabilities into your applications. Acting as an intelligent layer between your applications and AI models, Lamatic abstracts away the complexities of GenAI engineering, making it easy to implement, deploy, and scale AI-powered features.
Lamatic AI middleware is designed with redundancy and scalability in mind. The architecture is divided into different layers that work together to provide a seamless experience. Even if our main system fails, it will not affect your deployed applications and APIs.
## Why Use Lamatic as Your AI Middleware?
Traditional GenAI development requires significant engineering effort to handle:
- Connecting and managing multiple AI models
- Building prompt management systems
- Implementing caching and optimization layers
- Creating APIs and integration points
- Managing data pipelines and vector databases
- Handling authentication and request monitoring
**Lamatic AI eliminates all of this complexity** by providing a fully managed middleware solution that handles these concerns out of the box.
## Easy Implementation
Implementing Lamatic AI as your middleware is straightforward and can be done in just a few steps:
### Create a Flow
Build your AI workflow by connecting required nodes in our visual flow builder. No complex coding required - just drag, drop, and connect.
### Connect Your Data and Apps
Integrate your data sources, third-party applications, and custom data directly into your flow. Lamatic supports a wide range of integrations.
### Connect AI Models
Add your model credentials and configure which AI models to use. Switch between models easily without changing your application code.
### Deploy on Edge
Deploy your workflow to the edge with a single click. Your deployed flow is isolated from the Lamatic Studio platform, ensuring reliability and independence.
### Integrate with Your Application
Trigger your AI flows using GraphQL API, widgets, or webhooks - choose the integration method that best fits your application architecture.
## Architecture Layers
Lamatic AI middleware is built on a layered architecture that ensures reliability, scalability, and ease of use. For detailed information, see the [Architecture documentation](/docs/ai-middleware/architecture).
### Integration Layer
The integration layer provides multiple ways to connect your applications with Lamatic AI:
- **GraphQL API** - User-specific Schema API that performs different operations with GraphQL object caching on the edge for faster responses
- **Widgets** - Customizable pre-built components (like chat widgets) that you can drop into your applications
- **Apps** - Connect third-party apps to trigger flows and receive responses directly within the application
- **Webhooks** - Trigger flows asynchronously and receive responses in your application
### Studio Layer
The visual interface that allows non-technical users to configure, monitor, and maintain AI operations:
- **Flow Management** - Manage complex flows with series of Agents collaborating to complete tasks
- **Agents** - Use our library of agents or create your own with custom prompts
- **Cache Control** - Control semantic and vector caching for optimal performance
- **Experiments** - Set up A/B tests to evaluate the best models, prompts, and agents
- **Logs & Analytics** - Monitor all incoming requests and analyze performance
### Core Layer
The execution engine that powers reliable AI operations:
- **Request Monitoring** - Monitors and authenticates incoming requests
- **Semantic Cache** - Intelligent caching based on query vectors
- **Query Controls** - Maps the right data with object retrieval, JSON validation, and quality control
- **Memory Management** - Context-aware memory for chatbots and conversational AI
- **Model Relay** - Managed connections across multiple AI models
- **A/B Testing Module** - Optimize across Agents, Rules, and Models
### Managed Infrastructure
Lamatic's fully managed infrastructure handles:
- Edge-deployed functions for low-latency responses
- Auto-scaling cluster nodes based on demand
- Vector database with ETL pipelines
- Data transformation and vectorization for RAG use cases
## Key Benefits
### Rapid Deployment
Deploy AI capabilities in hours, not weeks. The visual flow builder and pre-built components accelerate development.
### Enterprise Security
Your data can be hosted on-premise or in a private cloud, ensuring complete security and compliance with your organization's requirements.
### Scalability
Auto-scaling infrastructure handles traffic spikes automatically. Edge deployment ensures low latency globally.
### Model Flexibility
Switch between AI models without changing your application code. Test different models and choose the best one for each use case.
### Cost Optimization
Built-in caching, request optimization, and cost prediction tools help you manage and reduce AI operational costs.
### No Vendor Lock-in
Your deployed flows are isolated and independent. Even if you stop using Lamatic Studio, your deployed applications continue to work.
## Privacy and On-Premise Hosting
Lamatic can be customized to host your organization's private data on-premise or on a private cloud. This ensures that sensitive information is not shared with any third party and remains completely secure while still leveraging Lamatic's powerful middleware capabilities.
## Getting Started
Ready to implement Lamatic AI as your middleware? Check out our [Quickstart guide](/docs/get-started) to get up and running in minutes, or explore our [Templates](/docs/templates) to see pre-built solutions for common use cases.
For a deeper dive into how Lamatic works under the hood, see the [Architecture documentation](/docs/ai-middleware/architecture).
---
# LLM Prompting Techniques
Source: https://lamatic.ai/docs/concepts/llm-prompting.md
# LLM Prompting Techniques
Large Language Models are AI systems that understand and generate text. How you ask questions matters a lot for getting good answers! This concept covers various prompting techniques with practical examples to help you get the most out of LLMs.
## Effective Ways to Talk to AI
### 1. Zero-Shot Prompting
Zero-shot prompting involves asking the LLM to perform a task without any examples.
Example
```text
Summarize the following paragraph:
Climate change is accelerating at an unprecedented rate. Global temperatures have increased by approximately 1.1°C since pre-industrial times, primarily due to human activities. This warming is causing more frequent and severe weather events, rising sea levels, and disruptions to ecosystems worldwide. Immediate and coordinated action is essential to mitigate these effects and prevent catastrophic outcomes for future generations.
```
### 2. Few-Shot Prompting
Few-shot prompting provides the LLM with a few examples before asking it to complete a similar task.
Example
```text
Convert these sentences to past tense:
Original: I walk to the store.
Past Tense: I walked to the store.
Original: She runs every morning.
Past Tense: She ran every morning.
Original: They build sandcastles at the beach.
Past Tense:
```
### 3. Chain-of-Thought (CoT) Prompt
Chain-of-thought prompting encourages the LLM to break down complex problems into logical steps.
Example
```text
Problem: If a shirt originally costs $50 and is on sale for 30% off, then there's an additional 15% discount at checkout, what is the final price?
Let's think through this step by step:
```
### 4. Self-Consistency Prompting
This technique involves generating multiple independent responses and then selecting the most consistent answer.
Example
```text
Generate three different solutions to this math problem, then determine which answer is correct:
If a rectangle has a length that is twice its width, and its perimeter is 36 cm, what is the area of the rectangle?
```
### 5. Role-Based Prompting
In role-based prompting, you ask the LLM to assume a specific role or perspective.
Example
```text
You are an experienced data scientist with expertise in machine learning. Explain how to handle imbalanced datasets to a junior programmer who has basic knowledge of classification algorithms.
```
### 6. Template-Based Prompting
Template-based prompting uses a consistent structure for similar tasks.
Example
```text
Article Title: {The Rise of Sustainable Fashion}
Audience: {Environmentally conscious young adults}
Tone: {Informative and inspiring}
Word Count: {800}
Write a blog post following the above parameters.
```
### 7. Instruction-Based Prompting
This approach provides clear, explicit instructions for the LLM to follow.
Example
```text
Create a product description for a wireless noise-canceling headphone. Follow these instructions:
1. Begin with an attention-grabbing headline
2. Include 3-5 key features and benefits
3. Mention battery life and connectivity options
4. End with a clear call-to-action
5. Keep the description under 200 words
6. Use a professional but enthusiastic tone
```
### 8. Persona-Based Prompting
Persona-based prompting defines both who the LLM is and who it's talking to.
Example
```text
You are a financial advisor with 15 years of experience talking to a 28-year-old who has just received their first promotion and salary increase. Provide advice on how they should adjust their financial planning.
```
### 9. Constraint-Based Prompting
This technique clearly defines limitations or requirements for the response.
Example
```text
Write a short story about an unexpected friendship with the following constraints:
- Maximum 250 words
- Set in a post-apocalyptic world
- No human characters
- Must include the themes of trust and sacrifice
- Should end on a hopeful note
```
### 10. Output Format Specification
This approach explicitly defines how you want the output structured.
Example
```text
Analyze the strengths and weaknesses of using renewable energy sources. Present your analysis in this format:
Introduction: (brief overview)
Strengths:
- [Strength 1]
- [Strength 2]
- [Strength 3]
Weaknesses:
- [Weakness 1]
- [Weakness 2]
- [Weakness 3]
Conclusion: (summary and future outlook)
```
### 11. System Prompting
System prompts set the overall behavior and capabilities of the LLM for the entire interaction.
Example
```text
You are a patient, encouraging math tutor who specializes in making algebra accessible to students with math anxiety. You break down complex problems into simple steps, use encouraging language, and provide multiple approaches to solving problems.
```
### 12. Recursive Prompting
This technique involves using the output of one prompt as input for another.
Example
```text
Step 1: Generate five potential titles for an article about sustainable urban gardening.
Step 2: For each title, write a compelling opening paragraph that would grab a reader's attention.
Step 3: Select the best title and opening paragraph combination, then outline the main sections for the complete article.
```
## Lamatic Prompt Editor

In Lamatic Studio, you can implement different types of prompts with Dynamic variables.
## Best Practices for Effective Prompting
1. Be specific: The more precise your instructions, the better the results.
1. Provide context: Give the LLM relevant background information.
1. Use clear structure: Organize your prompt logically.
1. Iterate and refine: If the first attempt doesn't give desired results, refine your prompt.
1. Control the length: Specify how detailed you want the response to be.
1. Set the tone: Indicate the desired writing style or tone.
1. Use delimiters: Separate different parts of your prompt with markers like triple quotes or brackets.
---
# What is Retrieval-Augmented Generation (RAG)?
Source: https://lamatic.ai/docs/concepts/rag.md
# What is Retrieval-Augmented Generation (RAG)?
Retrieval-Augmented Generation (RAG) is an AI framework that enhances the performance of Large Language Models (LLMs) by integrating external information retrieval mechanisms. This approach addresses limitations inherent in LLMs, such as outdated knowledge and potential inaccuracies, by enabling models to access and incorporate up-to-date, relevant data from external sources during the generation process.
In a RAG system, when a user poses a query, the model retrieves pertinent documents
or data from designated databases or knowledge bases. The LLM then synthesizes this
retrieved information with its existing knowledge to generate responses that are
more accurate, contextually relevant, and tailored to the user's specific needs.
## Understanding Retrieval-Augmented Generation (RAG)

Retrieval-Augmented Generation (RAG) is an AI framework that enhances Large Language Models (LLMs) by integrating external data retrieval mechanisms. This combination allows for more accurate, up-to-date, and contextually relevant responses. The process involves several key steps:
1. **Data Collection and Chunking**:
- **External Data Sources**: Gather information from various repositories such as documents, databases, or other structured and unstructured data.
- **Chunking**: Break down the collected data into smaller, manageable pieces or "chunks" to facilitate efficient retrieval.
2. **Embedding and Storage**:
- **Text Embedding Model**: Convert each data chunk into numerical representations known as embeddings. These embeddings capture the semantic meaning of the text.
- **Vector Database**: Store these embeddings in a vector database, enabling rapid similarity searches.
3. **Query Processing and Retrieval**:
- **User Query**: When a user submits a question or prompt, the system processes this input to understand the intent.
- **Retrieval**: The system searches the vector database to find embeddings that closely match the user's query, retrieving the most relevant data chunks.
4. **Response Generation**:
- **Large Language Model (LLM)**: The retrieved information is combined with the user's original query and fed into the LLM.
- **Augmented Response**: The LLM generates a response that incorporates both its pre-existing knowledge and the newly retrieved external information, ensuring the answer is accurate and contextually relevant.
## Benefits of RAG
- **Accuracy**: By grounding responses in real-time data, RAG reduces the chances of generating incorrect or outdated information.
- **Relevance**: The integration of external data ensures that responses are tailored to the user's specific context and needs.
- **Efficiency**: Utilizing a vector database allows for quick retrieval of relevant information, enhancing the responsiveness of the system.
## Implementing RAG with Lamatic.ai
Here are the Lamatic.ai Nodes associated with Retrieval-Augmented Generation (RAG)
| Node Name | Description | Docs |
| ----------------------- | ------------------------------------------------------------------------------------------------------------- | ------------------------ |
| **Chunking Node** | Parses data into manageable chunks for vectorization and semantic retrieval, improving processing efficiency. | [View Docs](/docs/nodes/chunking-node) |
| **Vectorize Node** | Converts data chunks into numeric vector representations using an embedding model. | [View Docs](/docs/nodes/vectorize-node) |
| **Index Node** | Inserts records into a vector database, enabling fast semantic retrieval. | [View Docs](/docs/nodes/index-node) |
| **Vector Search Node** | Retrieves information using vector-based search rather than plain text matching. | [View Docs](/docs/nodes/vector-search-node) |
| **Hybrid Search Node** | Embeds vector search within a Lamatic flow, combining multiple retrieval methods. | [View Docs](/docs/nodes/hybrid-search-node) |
| **Keyword Search Node** | Searches for specific keywords within a Vector Database. | [View Docs](/docs/nodes/keyword-search-node) |
| **RAG Node** | Enhances responses from a Language Learning Model (LLM) using Retrieval-Augmented Generation (RAG). | [View Docs](/docs/nodes/rag-node) |
## Simple Example
1. **Create a New Flow** in Lamatic.ai.
2. **Set up an API Node as the Trigger Node**, allowing data to be passed in the schema.
3. **Add a Chunking Node** to split the input data into manageable chunks for processing.
4. **Vectorize the Chunks** using the Vectorize Node to convert them into numerical vector representations.
5. **Store the Vectorized Data** in a Vector Database using the Index Node for efficient semantic retrieval.
6. **Use the RAG Node** in your Flow to generate responses from an LLM using Retrieval-Augmented Generation.
You can explore [guides](/guides) on implementing RAG with Google Drive, S3, and other integrations.
---
# Vibe Coding with Lamatic.ai
Source: https://lamatic.ai/docs/concepts/vibe-coding-setup.md
# Vibe Coding with Lamatic.ai
Developers working on **Lamatic.ai Docs** can now supercharge productivity using AI‑assisted coding tools. This guide explains how to configure and use **Vibe Coding tools**—such as GitHub Copilot, Cursor, and Claude—for a deeply contextualized coding experience powered by the `llm.txt` file.
## 1. Prerequisites
* Node.js **18+** and Git installed
* Access to the Lamatic.ai Docs repository
* Any LLM‑based coding assistant installed:
* GitHub **Copilot** (extension enabled in VS Code)
* **Cursor** IDE (with Lamatic project workspace loaded)
* **Continue.dev** (community‑compatible setup)
## 2. Understanding `llm.txt`
The **`llm.txt`** file defines the directories and configuration files that AI tools should prioritize when offering suggestions. This ensures the assistant understands **Lamatic.ai’s architecture**, ensuring relevant and structured completions.
The file includes:
* /components/ — Core UI and React elements
* /pages/docs/ — Lamatic documentation and integration guides
* /next.config.mjs — Next.js configuration
* /package.json — Node.js project manifest
* /pyproject.toml — Python project configuration
By guiding your LLM here, you prevent distractions from build artifacts or external modules.
## 3. Setting Up Vibe Coding Tools
### GitHub Copilot Setup
1. Ensure the **Copilot extension** is installed in VS Code.
2. **Context Note:** Copilot does **not** automatically read the `llm.txt` file. To ensure Copilot uses the project context:
* **Use `Attach Context`:** In the Copilot Chat pane, click the paperclip icon and manually attach the necessary component folders (e.g., `/components/`, `/pages/docs/`).
* **Use Tags:** Explicitly reference files in your prompts (e.g., `#file:components/Header.tsx`).
3. For specialized instruction, ensure `github.copilot.chat.codeGeneration.useInstructionFiles` is enabled to read any `.instructions.md` files you may create in the `.github` folder.
### Cursor Integration
1. Open the Lamatic Docs root folder in **Cursor IDE**.
2. Cursor **automatically respects** the `llm.txt` file as its project context.
3. Use the in‑line prompt (`Cmd/Ctrl + K`) to generate or refactor code.
Example prompt:
> “Based on Lamatic’s `DocsNav` component, generate a collapsible section with AI‑powered section titles.”
Cursor lets you connect custom AI APIs too—ideal for contributors using their own OpenAI or Anthropic credentials for Lamatic.ai development.
## 4. Example Prompts and Best Practices
| Scenario | Basic Prompt | Context‑Aware Prompt |
|-----------|---------------|----------------------|
| **Component Creation** | "Make a new button" | "Using Lamatic’s `Button.tsx` design from `/components/ui/`, create a `PrimaryBadge` variant matching Lamatic.ai styling." |
| **Documentation Enhancement** | "Add integration doc" | "Following `/pages/docs/integrations`, create a doc titled `AI Automation Setup` demonstrating Lamatic.ai’s workflow configuration." |
| **API Logic** | "Write API route" | "In reference to `pyproject.toml` dependencies, implement a Python FastAPI route for Lamatic.ai’s webhook ingestion." |
**Pro Tip:** Include component or page paths in prompts (e.g., `components/ui/Button.tsx`)—LLMs use them as explicit context anchors.
## 5. Troubleshooting
| Issue | Possible Cause | Recommended Solution |
|-------|----------------|----------------------|
| **AI not responding contextually** | IDE not loading `llm.txt` | Restart your environment or reload the Lamatic Docs workspace. |
| **Off‑theme code suggestions** | Outdated assistant cache | Clear Copilot/Cursor cache or reload Lamatic configuration. |
| **Code format mismatches** | Local ESLint not running | Execute `npm run lint` or `npm run format`. |
---
### Why This Matters
Lamatic.ai thrives on collaborative, intelligent documentation. By configuring context correctly and aligning Vibe Coding tools, your LLM assistant effectively “understands” Lamatic’s structure—making your prompts smarter, faster, and fully contextual.
These improvements allow new contributors to **get productive immediately**, reducing setup friction and ensuring Lamatic.ai remains a pioneer in developer‑friendly AI documentation integration.
---
---
# Authentication with API Keys
Source: https://lamatic.ai/docs/studio/studio-keys.md
# Authentication with API Keys
To ensure secure access to our platform, Lamatic.ai employs API keys for authentication. When triggering flows via GraphQL, you'll need to include your API key in the request headers. This key serves as a unique identifier, granting you authorized access to our services while maintaining the integrity and confidentiality of your data.

## How to Get the API Key
Follow these steps to create and retrieve your API key:
1. **Navigate to Studio**: Open your Lamatic.ai Studio
2. **Go to Settings**: Click on **Settings** in the navigation menu
3. **Access API Keys**: Select **API Keys** from the settings options
4. **Create New Key**: Click the **Create a New API Key** button
5. **Copy Your Key**: Once created, copy your API key immediately (you won't be able to see it again)
**Important**: Store your API key securely. If you lose it, you'll need to create a new one. After creating a new API key, make sure to redeploy your project for the changes to take effect.
### Using the API Key
Include your API key in the `Authorization` header of all GraphQL requests using the Bearer token format:
```js
Authorization: Bearer your_api_key
```
By including the API key in the `Authorization` header, our platform can verify your identity and grant you access to trigger the desired flow.
## Integrating Lamatic into Your Application
This section provides a comprehensive guide for integrating Lamatic.ai into your application. Follow these steps to seamlessly connect your application with Lamatic workflows.
### Integration Overview
Lamatic.ai integrates with your application through GraphQL API endpoints. You can trigger workflows programmatically from any application that can make HTTP requests, including web applications, mobile apps, backend services, and serverless functions.
### Required Information
Before integrating, gather the following information from your Lamatic Studio:
1. **API Key**: Your authentication key (from Studio > Settings > API Keys)
2. **Project ID**: Unique identifier for your project (found in project settings)
3. **Project URL**: Your GraphQL endpoint URL (provided in your project dashboard)
4. **Workflow ID**: The ID of the specific workflow you want to trigger (visible in the workflow editor)
### Integration Steps
#### Step 1: Set Up Environment Variables
Store your API key securely as an environment variable. Never hardcode credentials in your source code.
**For local development:**
- Create a `.env` file (add it to `.gitignore`)
- Add: `LAMATIC_API_KEY=your_api_key_here`
**For production:**
- Use your platform's secret management system (AWS Secrets Manager, Azure Key Vault, etc.)
- Or set environment variables in your deployment configuration
#### Step 2: Install Required Dependencies
Depending on your technology stack:
- **JavaScript/Node.js**: `npm install axios` or `npm install node-fetch`
- **Python**: `pip install requests`
- **Other languages**: Use your language's standard HTTP client library
#### Step 3: Configure Request Headers
Every request must include these headers:
```js
{
"Authorization": "Bearer YOUR_API_KEY",
"Content-Type": "application/json",
"x-project-id": "YOUR_PROJECT_ID"
}
```
#### Step 4: Structure Your GraphQL Query
Use the `executeWorkflow` mutation with your workflow ID and payload:
```graphql
query ExecuteWorkflow($workflowId: String!, $payload: JSON) {
executeWorkflow(workflowId: $workflowId, payload: $payload) {
status
result
}
}
```
#### Step 5: Map Your Data to Workflow Inputs
Ensure your payload matches the input schema defined in your workflow. Check your workflow's input variables in the Studio to ensure correct field names and types.
#### Step 6: Handle Responses and Errors
Always implement proper error handling:
- Check HTTP status codes
- Parse GraphQL errors from the response
- Handle network failures gracefully
- Implement retry logic for transient failures
### Common Integration Patterns
**Synchronous Integration**: Make a request and wait for the response before proceeding. Best for workflows that complete quickly.
**Asynchronous Integration**: Trigger the workflow and handle the response in a callback or promise. Best for longer-running workflows.
**Webhook Integration**: Configure your workflow to send results to a webhook endpoint in your application. Best for workflows that may take time to complete.
**Batch Processing**: Trigger multiple workflows in parallel or sequence. Ensure you respect rate limits.
### Troubleshooting
**Authentication Errors (401)**
- Verify your API key is correct and not expired
- Check that the API key is properly set in environment variables
- Ensure the `Bearer` prefix is included in the Authorization header
**Project Not Found (404)**
- Verify your Project ID is correct
- Check that the Project URL is correct
- Ensure your project is deployed
**Rate Limit Exceeded (429)**
- Ensure you’re not exceeding the allowed number of requests for your plan
- Check if multiple requests are being sent in parallel or in rapid succession
- Implement request throttling or retries with exponential backoff
**Workflow Execution Errors**
- Verify the Workflow ID is correct
- Check that payload structure matches workflow inputs
- Review workflow logs in the Studio
**Network Errors**
- Check your internet connection
- Verify the Project URL is accessible
- Check firewall settings
- Implement retry logic with exponential backoff
## Triggering Flows with GraphQL
Lamatic.ai's GraphQL integration allows you to trigger your GenAI flows seamlessly using GraphQL queries. This approach provides a standardized and efficient way to interact with our platform, enabling you to execute your GenAI flows on-demand or as part of larger application flows.
### Prerequisites
Before you begin, make sure you have:

- Your **API Key** (from Studio > Settings > API Keys)
- Your **Project ID** (found in your project settings)
- Your **Project URL** (your GraphQL endpoint)
- Your **Workflow ID** (the ID of the workflow you want to trigger)
### Setup Instructions
1. Set your API key as an environment variable:
- **JavaScript/Node.js**: `export LAMATIC_API_KEY=your_api_key_here`
- **Python**: `export LAMATIC_API_KEY=your_api_key_here` (or add to `.env` file)
- **cURL**: `export LAMATIC_API_KEY=your_api_key_here`
2. Replace the following placeholders in the code:
- `YOUR_PROJECT_URL` - Your GraphQL endpoint URL
- `YOUR_PROJECT_ID` - Your project ID
- `YOUR_WORKFLOW_ID` - The workflow ID you want to execute
- `url` - Your input data (modify based on your workflow's requirements)
Here's an example GraphQL query that demonstrates how you can trigger a flow:
**Note**: In this example, we're using `url` as a payload variable. You should adjust the payload variables based on your workflow's input requirements.
```javascript
const axios = require('axios');
// Step 1: Get your API key from environment variable
const lamatic_api_key = process.env.LAMATIC_API_KEY;
// Step 2: Define your GraphQL query
const query = `
query ExecuteWorkflow(
$workflowId: String!
$url: String
) {
executeWorkflow(
workflowId: $workflowId
payload: {
url: $url
}
) {
status
result
}
}
`;
// Step 3: Define your query variables
const variables = {
workflowId: "YOUR_WORKFLOW_ID",
url: "url"
};
// Step 4: Configure the request
const options = {
method: 'POST',
url: 'YOUR_PROJECT_URL',
headers: {
'Authorization': `Bearer ${lamatic_api_key}`,
'Content-Type': 'application/json',
'x-project-id': 'YOUR_PROJECT_ID',
},
data: {
query,
variables
}
};
// Step 5: Make the request
axios(options)
.then(response => {
console.log('Success:', response.data);
})
.catch(error => {
console.error('Error:', error.response?.data || error.message);
});
```
```python
import os
import requests
# Step 1: Get your API key from environment variable
lamatic_api_key = os.getenv('LAMATIC_API_KEY')
if not lamatic_api_key:
raise ValueError("LAMATIC_API_KEY environment variable is not set")
# Step 2: Define your GraphQL query
gql_query = """
query ExecuteWorkflow(
$workflowId: String!
$url: String
) {
executeWorkflow(
workflowId: $workflowId
payload: {
url: $url
}
) {
status
result
}
}
"""
# Step 3: Define your query variables
variables = {
"workflowId": "YOUR_WORKFLOW_ID",
"url": "url"
}
# Step 4: Prepare the request payload
data = {
"query": gql_query,
"variables": variables
}
# Step 5: Set up request headers
headers = {
"Authorization": f"Bearer {lamatic_api_key}",
"Content-Type": "application/json",
"x-project-id": "YOUR_PROJECT_ID"
}
# Step 6: Set your project URL
url = "YOUR_PROJECT_URL"
# Step 7: Make the request
try:
response = requests.post(url, headers=headers, json=data)
response.raise_for_status() # Raises an error for bad status codes
# Step 8: Handle the response
result = response.json()
print("Success:", result)
except requests.exceptions.RequestException as e:
print(f"Error: {e}")
if hasattr(e, 'response') and e.response is not None:
print(f"Status Code: {e.response.status_code}")
print(f"Response: {e.response.text}")
```
```bash
# Step 1: Set your API key (if not already set)
export LAMATIC_API_KEY=your_api_key_here
# Step 2: Set your project details
PROJECT_URL="YOUR_PROJECT_URL"
PROJECT_ID="YOUR_PROJECT_ID"
WORKFLOW_ID="YOUR_WORKFLOW_ID"
# Step 3: Make the GraphQL request
curl -X POST "$PROJECT_URL" \
-H "Authorization: Bearer ${LAMATIC_API_KEY}" \
-H "Content-Type: application/json" \
-H "x-project-id: ${PROJECT_ID}" \
-d '{
"query": "query ExecuteWorkflow($workflowId: String!, $url: String) { executeWorkflow(workflowId: $workflowId, payload: { url: $url }) { status result } }",
"variables": {
"workflowId": "'"$WORKFLOW_ID"'",
"url": "url"
}
}'
```
### Understanding the Response
The response structure can be configured in the **Schema** of the GraphQL Response node in your workflow. The response will follow this structure:
```json
{
"data": {
"executeWorkflow": {
"status": "success",
"result": {
// Your custom output as configured in the Schema
}
}
}
}
```
### Important Notes
- **Workflow ID**: You can find your workflow ID in the Studio when viewing your workflow
- **Payload Variables**: The `payload` object should match the input variables defined in your workflow. In this example, we're using `url`, but you should adjust this based on your workflow's requirements
- **Error Handling**: Always check the response status and handle errors appropriately in your application
- **API Key Security**: Never commit your API key to version control. Always use environment variables or secure secret management
---
# Studio Overview
Source: https://lamatic.ai/docs/studio/studio-overview.md
# Studio: Command and Control for Lamatic Projects
Studio is your comprehensive platform for managing, building, and deploying all your **GenAI** projects. This powerful tool allows seamless collaboration, enabling you to invite team members and work together efficiently throughout the project lifecycle.
> **Tip**: Ready to unlock the full potential of Studio? Head over to: [studio.lamatic.ai](https://studio.lamatic.ai)
## Prerequisites
- A Lamatic account ([sign up here](https://lamatic.ai/))
- Basic understanding of what a Project is (a container for your Flows, Models, and configurations)
## First-time user guide
If you're new to Studio, here's what to do first:
1. **Create or select a Project**: Projects are where you build your AI applications
2. **Explore the sidebar**: The left sidebar contains all the main sections
3. **Start with Templates**: Use pre-built templates to get started quickly
4. **Check your Project Settings**: Configure your project name, API keys, and team members
Don't worry about understanding everything at once. Start by creating a Flow from a template, and you'll learn the interface as you go.
---
## Navigation

### Project and Organization Management
- **Switch Organization, Profile, Theme, and Logout**: Change organizations, manage profile/theme, or sign out.
- **Switch Project**: Quickly jump between projects in the current organization.
### Flow Workspace
- **Create New Flow/Prompt**: Start a new flow or author a new prompt.
- **Flow Directory**: Browse all flows in the project.
- **Prompt Directory**: Browse and manage prompts.
- **Flow Tags**: Tag flows to organize and filter them.
- **Templates**: Open the template library from the bottom toolbar.
### Data and Context
- **Data/Database**: Store vector embeddings and long‑term memory for your applications.
### Integrations and Interfaces
- **Models**: Configure LLMs and other AI models.
- **MCP/Tools & Integrations**: Connect external tools and MCP servers.
- **Interface (Chat/Search Widget)**: Configure AI-powered chat and search widgets.
- **Connect GitHub**: Link a GitHub repository to your project.
### Monitoring and Deployment
- **Editor / Logs / Reports**: Switch the canvas mode to build, inspect logs, or view reports.
- **Logs**: Inspect request and run logs for monitoring and debugging.
- **Deployments**: Track and manage deployment history.
- **Reports**: Generate and review analytics reports.
### Testing and Automation
- **Trigger**: The entry node that starts a flow run.
- **Testing**: Create and run test cases for validation.
- **Scheduled Jobs**: Manage and track automated jobs and batch processes.
### Project Settings
- **Settings**: Manage project-specific configuration and preferences.
---
Each menu item provides specialized functionalities to manage, deploy, and monitor project components efficiently.
---
## Theme Customization

Studio offers flexible theme options to match your working environment and preferences. You can customize the appearance of the interface to suit your needs.
### Available Theme Options
1. **System**: Automatically matches your device's system theme preference (light or dark mode). The interface will switch between light and dark themes based on your operating system settings.
2. **Light**: Forces the interface to use a light theme, providing a bright and clean workspace ideal for well-lit environments.
3. **Dark**: Activates the dark theme, reducing eye strain in low-light conditions and providing a modern, focused interface.
### How to Change Theme
1. Navigate to the left sidebar in Studio.
2. Click on the **Theme** option in the menu.
3. Select your preferred theme from the dropdown:
- **System** - Follows your device settings
- **Light** - Always use light theme
- **Dark** - Always use dark theme
Your theme preference is saved automatically and will persist across sessions.
> **Pro Tip**: Use **System** theme to automatically adapt to your environment, or choose a specific theme for consistent visual experience regardless of your device settings.
---
## Projects

Studio allows you to create flexible **Projects** tailored to your organization's structure. These Projects provide:
- **Multi-team collaboration**: Members can join multiple Projects and switch between them as needed.
- **Custom roles**: Assign specific permissions through **Member Roles** to control access and responsibilities.
- **Transparency**: All members within a Project have full access to all projects within it.
> **Pro Tip**: Customize your Projects to fit your organization's flow, enhancing both collaboration and security.
---
### Inviting Members to Your Projects

Expanding your Projects is easy:
1. **Invite Members**: Go to **Organization Settings** and invite new members.
2. **Onboarding**: If your invitee isn't registered with Lamatic.ai, they will receive an email guiding them through the signup process.
3. **Manage Membership**: Add or remove members as needed to keep your team up to date.
> **Quick Start**: Inviting new collaborators is seamless, ensuring smooth onboarding for team growth.
---
### Billing Management
Studio simplifies billing by offering a centralized dashboard for viewing and managing all financial details:
- **Centralized Billing**: Access all billing info in one place.
- **Flexible Plans**: Different projects in the same Project can run on separate plans, but billing is consolidated for simplicity.
- **Clear Overview**: Get a comprehensive picture of your overall investment across projects.
> **Pro Tip**: Take advantage of Studio's flexible billing model to customize financial plans for each project while keeping the process streamlined.
## Troubleshooting
- **Can't find a feature**: Use the search bar at the top or check the left sidebar navigation
- **Project not showing**: Make sure you're in the correct Organization (check the top-left dropdown)
- **Team member can't access**: Verify they've been invited and accepted the invitation
- **Theme not changing**: Refresh the page after changing theme settings
## Next steps
Now that you understand Studio's interface:
- **Build your first Flow**: Start with the [Quickstart Guide](/docs/get-started)
- **Learn about Projects**: Read [Project Settings](/docs/studio-project) for detailed configuration
- **Set up Authentication**: Configure [API Keys](/docs/studio-keys) for integrations
- **Explore Templates**: Browse available templates to see what's possible
---
# Projects
Source: https://lamatic.ai/docs/studio/studio-project.md
# Projects
In the context of Studio, a project represents an individual **GenAI** application you're developing. The workspace structure allows for multiple projects to coexist, each representing a unique GenAI application with its own set of requirements and functionalities. Studio ensures that each project maintains its independence by providing dedicated resources and endpoint controls. This separation is crucial for maintaining the integrity and security of your applications. Even within the same workspace, projects are designed to operate without interference, and they do not share credentials, ensuring that each project remains a self-contained unit with its own secure environment.
---
## Home View

The Home View in Studio offers an intuitive and comprehensive overview of your project and along with Onboarding Guide. This interactive project plan view provides a visual representation of all the features and integrations currently in use within your project.
> **Insight**: At a glance, you can assess the complexity, scope, and capabilities of your GenAI application, making it easier to manage and strategize your development efforts.
---
### Shared Resources within the Project
Studio provides a set of versatile resources that can be leveraged across various features within your project. These shared resources enhance the functionality and efficiency of your GenAI application. The following key resources are available for integration throughout your project:
1. **Models**: Utilize pre-trained or custom AI models to power your application's core functionality.
2. **App Integrations**: Seamlessly connect your project with external applications and services to extend its capabilities.
3. **VectorDB**: Implement vector databases for efficient storage and retrieval of high-dimensional data, crucial for many AI applications.
4. **Test Cases**: Develop and manage a suite of test cases to ensure the reliability and performance of your GenAI application.
> **Pro Tip**: These resources can be easily integrated and reused across various features, saving time and boosting efficiency.
---
## Project Settings

### 1. General Settings
In the General Settings, you can update project details such as the project name and view the Project ID. You also have the option to pause or delete the project from this section.
### 2. Configuration
The Configuration section allows you to manage project-level settings that control how your flows behave and handle errors. These settings provide fine-grained control over retry mechanisms to ensure your flows are resilient and reliable.
#### Smart Retries for Flows
Smart Retries is a powerful feature that automatically retries failed flows from the last successfully executed node. When enabled, this feature helps maintain flow continuity and reduces manual intervention by intelligently resuming execution from the point of failure.
Once enabled, your flows will be retried automatically from the last successfully executed node if they fail.
##### Configuration Options
- **Enable Smart Retries**: Toggle this switch to enable or disable the Smart Retries feature for all flows in your project.
- **Max Retries**: Specify the maximum number of retry attempts for a failed flow. The default value is `1`.
- **Retry Delay (in seconds)**: Set the delay between retry attempts in seconds. The default value is `1` second.
> **Pro Tip**: Smart Retries can significantly improve the reliability of your flows by automatically handling transient failures and network issues. Adjust the retry delay based on your flow's requirements and the expected recovery time of external services.
After configuring these settings, click the **Save Changes** button to apply your changes to the project.
---
### 3. Integration

Studio recognizes the importance of a robust development ecosystem. To this end, it offers integration capabilities with various developer tools, allowing you to enhance and optimize your project's capabilities. These integrations can significantly streamline your flow and provide valuable insights into your application's performance.
As of now, the following developer integrations are available for your Studio projects:
1. **[Langfuse (Beta)](/docs/reports/langfuse-integration)**: Advanced LLM observability and analytics to track, debug, and improve GenAI performance.
2. **GitHub**: Connect a repository to commit workflow updates for seamless version control and team collaboration.
> **Developer Note**: These integrations can help you keep your GenAI project optimized and data-driven.
---
### 3. Authentication
#### API Keys
Security and controlled access are paramount in GenAI projects. Studio provides robust API key management features, allowing you to generate, monitor, and revoke API keys as needed. This key serves as a unique identifier, granting you authorized access to our services while maintaining the integrity and confidentiality of your data.
#### Secret Keys
Allow external services to access the project on behalf of a user. Checkout the Lamatic SDK to understand how to use the secret keys.
Note: Any addition or removal of secret keys will be reflected only after the project has been deployed.
---
### 4. Variables & Secrets
With Variables and Secrets you can Safeguard your API keys and credentials with our new Secrets Management system, ensuring your data stays protected while maintaining easy access for authorized use.
A new Deployment is required for your changes to take effect.
---
> **Security Tip**: Maintain granular control over project access, ensuring security while facilitating authorized integration.
---
# Role-Based Access
Source: https://lamatic.ai/docs/studio/studio-role-based-access.md
# Role-Based Access Guide
This guide outlines the permissions and capabilities for different user roles within organizations and projects on Lamatic.ai.

## Permission Tables
### 1. Organization Level Permissions
| Permission | Owner | Admin | Editor | Developer | Viewer |
|------------|-------|--------|---------|------------|---------|
| Update organization name | ✅ | ✅ | ❌ | ❌ | ❌ |
| Invite new users | ✅ | ✅ | ❌ | ❌ | ❌ |
| Change user roles | ✅ | ✅ | ❌ | ❌ | ❌ |
| Delete organization | ✅ | ❌ | ❌ | ❌ | ❌ |
| Create Admin | ✅ | ❌ | ❌ | ❌ | ❌ |
Note that to handle billing and organization settings, you need to be an Owner.
### 2. Project Level Permissions
| Permission | Admin/Owner | Editor | Developer | Viewer |
|------------|-------------|---------|------------|---------|
| Create new projects | ✅ | ❌ | ❌ | ❌ |
| Update project name | ✅ | ❌ | ❌ | ❌ |
| Pause/resume project | ✅ | ❌ | ❌ | ❌ |
| Delete project | ✅ | ❌ | ❌ | ❌ |
| Create/delete API keys | ✅ | ✅ | ❌ | ❌ |
| Secret | ✅ | ✅ | ❌ | ❌ |
| Secret Keys | ✅ | ✅ | ❌ | ❌ |
| Configure job settings | ✅ | ✅ | ❌ | ❌ |
| Deploy project | ✅ | ✅ | ❌ | ❌ |
### 3. Flows and Agents Level Permissions
| Permission | Admin/Owner | Editor | Developer | Viewer |
|------------|-------------|---------|------------|---------|
| Create new flow | ✅ | ✅ | ✅ | ❌ |
| Update flow | ✅ | ✅ | ✅ | ❌ |
| Delete flow | ✅ | ✅ | ✅ | ❌ |
| Deploy flow | ✅ | ✅ | ❌ | ❌ |
| Test flows | ✅ | ✅ | ✅ | ✅ |
| View flows | ✅ | ✅ | ✅ | ✅ |
| Create new agent | ✅ | ✅ | ✅ | ❌ |
| Update agent | ✅ | ✅ | ✅ | ❌ |
| Delete agent | ✅ | ✅ | ✅ | ❌ |
| Deploy agent | ✅ | ✅ | ❌ | ❌ |
| Test agent | ✅ | ✅ | ✅ | ✅ |
| View agent | ✅ | ✅ | ✅ | ✅ |
### 4. Prompts and Tools Level Permissions
| Permission | Admin/Owner | Editor | Developer | Viewer |
|------------|-------------|---------|------------|---------|
| Create prompt | ✅ | ✅ | ❌ | ❌ |
| Update prompt | ✅ | ✅ | ❌ | ❌ |
| View prompt | ✅ | ✅ | ✅ | ✅ |
| Delete prompt | ✅ | ✅ | ❌ | ❌ |
| Create tool | ✅ | ✅ | ✅ | ❌ |
| Update tool | ✅ | ✅ | ✅ | ❌ |
| View tool | ✅ | ✅ | ✅ | ✅ |
| Delete tool | ✅ | ✅ | ✅ | ❌ |
### 5. Context Level Permissions
| Permission | Admin/Owner | Editor | Developer | Viewer |
|------------|-------------|---------|------------|---------|
| Create new database | ✅ | ✅ | ❌ | ❌ |
| Update database name | ✅ | ✅ | ❌ | ❌ |
| Delete database | ✅ | ✅ | ❌ | ❌ |
### 6. Models and Configuration Level Permissions
| Permission | Admin/Owner | Editor | Developer | Viewer |
|------------|-------------|---------|------------|---------|
| Create new credential | ✅ | ✅ | ❌ | ❌ |
| Update credential | ✅ | ✅ | ❌ | ❌ |
| Delete credential | ✅ | ✅ | ❌ | ❌ |
| Create new configuration | ✅ | ✅ | ❌ | ❌ |
| Update configuration | ✅ | ✅ | ❌ | ❌ |
| Delete configuration | ✅ | ✅ | ❌ | ❌ |
| Update default models | ✅ | ✅ | ✅ | ❌ |
### 7. Integrations Level Permissions
| Permission | Admin/Owner | Editor | Developer | Viewer |
|------------|-------------|---------|------------|---------|
| Create integration | ✅ | ✅ | ❌ | ❌ |
| Update integration name | ✅ | ✅ | ❌ | ❌ |
| Delete integration | ✅ | ✅ | ❌ | ❌ |
| Update default integrations | ✅ | ✅ | ❌ | ❌ |
### 8. Test Suites Permissions
| Permission | Admin/Owner | Editor | Developer | Viewer |
|------------|-------------|---------|------------|---------|
| Create test suite | ✅ | ✅ | ✅ | ❌ |
| Update test suite | ✅ | ✅ | ✅ | ❌ |
| Delete test suite | ✅ | ✅ | ✅ | ❌ |
### 9. Jobs Permissions
| Permission | Admin/Owner | Editor | Developer | Viewer |
|------------|-------------|---------|------------|---------|
| Sync/pause job | ✅ | ✅ | ✅ | ❌ |
## Key Points
1. **Role Hierarchy**
- Owner has full system access
- Admin has organizational management rights
- Editor can manage content and configurations
- Developer can create and modify flows
- Viewer has read-only access
2. **Best Practices**
- Assign minimum necessary permissions
- Regularly review user roles
- Document permission changes
- Audit access periodically
3. **Important Notes**
- Only Owners can delete organizations
- Editors can't create new projects
- Developers can create flows but can't deploy them
- Viewers can test flows but can't modify them
Need help? Contact [support@lamatic.ai](mailto:support@lamatic.ai) for assistance with roles and permissions.
---
# Tags
Source: https://lamatic.ai/docs/studio/studio-tags.md
# Tags
Tags are a powerful organizational feature in Lamatic Studio that help you categorize, organize, and filter your flows for better accessibility and management. By applying tags to your flows, you can quickly locate specific flows, group related flows together, and streamline your development process.

## What are Tags?
Tags are customizable labels that you can assign to flows to categorize them based on various criteria such as:
- **Project type** (e.g., "API", "Chatbot", "Automation")
- **Status** (e.g., "Production", "Staging", "Development")
- **Team or department** (e.g., "Marketing", "Engineering", "Support")
- **Functionality** (e.g., "Data Processing", "Content Generation", "Integration")
- **Any custom category** that fits your workflow
## Benefits of Using Tags
### 1. Improved Organization
Tags help you organize flows logically, making it easier to understand the purpose and status of each workflow at a glance.
### 2. Enhanced Filtering
Quickly filter flows by tags to find exactly what you're looking for, especially useful when working with multiple flows in a project.
### 3. Better Accessibility
Tags make flows more discoverable and accessible, allowing team members to quickly locate relevant workflows without scrolling through long lists.
### 4. Team Collaboration
Standardized tags across your organization ensure consistent categorization, making it easier for team members to understand and navigate flows.
## How to Add Tags to a Flow
1. **Open your flow** in the Studio editor.
2. **Locate the "+ Tags" button** next to the flow title in the top bar of the canvas.
3. **Click "+ Tags"** to open the tag management interface.
4. **Add tags** by typing tag names and pressing Enter, or select from existing tags.
5. **Save** your changes.
> **Tip**: Use consistent naming conventions for tags across your project to maximize their effectiveness for filtering and organization.
## Filtering Flows by Tags

Once you've tagged your flows, you can filter them in the Flow Directory:
1. **Navigate to the Flow Directory** in the left sidebar.
2. **Use the tag filter** to select one or more tags.
3. **View filtered results** showing only flows matching your selected tags.
This filtering capability is especially valuable when:
- Working on a specific feature or project
- Reviewing flows by status (e.g., all production flows)
- Finding flows related to a particular integration or functionality
## Best Practices
### Tag Naming
- **Use clear, descriptive names**: Choose tag names that are immediately understandable (e.g., "API Integration" instead of "API").
- **Maintain consistency**: Establish a tagging convention and stick to it across your organization.
- **Avoid duplicates**: Use similar tags consistently rather than creating variations (e.g., use "Production" consistently, not "Prod", "production", and "PROD").
### Tag Categories
Consider organizing tags into categories:
- **Environment**: `production`, `staging`, `development`
- **Type**: `api`, `chatbot`, `automation`, `data-processing`
- **Status**: `active`, `deprecated`, `testing`
- **Team**: `backend`, `frontend`, `marketing`
### Tag Management
- **Review regularly**: Periodically review and clean up unused or redundant tags.
- **Limit tag count**: Avoid over-tagging flows; 2-5 relevant tags per flow is usually sufficient.
- **Document conventions**: Share your tagging conventions with your team to ensure consistency.
> **Quick Start**: Start tagging your flows today! Even a simple tagging system with 3-5 common tags can significantly improve your workflow management and accessibility.
---
# Variables & Secrets
Source: https://lamatic.ai/docs/studio/studio-variables-and-secrets.md
# Variables & Secrets
The **Variables & Secrets** page allows users to securely store API keys, authentication tokens, and other sensitive data for seamless use across their flow. By defining these secrets in the settings, you can reference them within any flow without exposing them directly.

## Why Use Variables & Secrets?
- **Security:** Keep sensitive data hidden and reusable without hardcoding values in flows.
- **Efficiency:** Quickly integrate API keys and secrets into flow without manual entry.
- **Reusability:** Use stored secrets across multiple flows without reconfiguration.
## How to Add Secrets
1. Navigate to **Settings** > **Secrets**.
2. Click on **Add Secrets**.
3. Enter a **Secret Name** and its corresponding **Secret Value**.
4. Click **Create** to save the secret.
> Secrets are encrypted and stored securely, ensuring safe access in your flow.
## Using Stored Secrets in a Flow

Once a secret is stored, you can reference it dynamically in any flow as shown in the example above.
This ensures that the actual value remains hidden while still being accessible.
## Managing and Updating Secrets
- To **edit** a secret, update its value and redeploy your project.
- To **delete** a secret, remove it from the list and confirm deletion.
By utilizing **Variables & Secrets**, you maintain a secure and scalable approach to handling credentials in your flows.
---
# Flow Editor
Source: https://lamatic.ai/docs/flows/editor.md
# Flow Editor

The Editor provides a comprehensive interface for building and editing GenAI flow with an intuitive flowchart approach. This guide walks through key features and methods to help you utilize the Editor effectively.
## Node Actions
Nodes are essential components of any flow. Each node carries out a unique function using defined inputs and configurations. Here’s how to work with nodes:
### Adding Nodes

**Method**:
1. Locate the ➕ icon in empty spaces or when hovering over connecting lines.
2. Click the ➕ icon to open the node selection menu.
3. Select the desired node type from the menu.
4. The chosen node will be added to your flow at the selected location.
### Configuring Nodes

**Method**:
1. Click on a node in your flow to select it.
2. The configuration panel will appear on the right side of the screen.
3. Modify settings (e.g., input parameters, output options) as needed.
4. Changes apply automatically in real-time.
### Reordering Nodes
**Method**:
1. Click and hold the node you want to move.
2. Drag the node to its new position within the flow.
3. Release the mouse to place the node; the flow will adjust automatically.
4. Reordering nodes enables access to upstream variables, improving data flow between nodes.
## Config

The Config tab provides a low-code method to define flows using a YAML-like syntax, offering flexibility similar to GitHub Actions.
**Method**:
1. Go to the Config tab in the Editor.
2. Edit YAML directly in the text area to specify nodes, properties, and connections.
3. Follow YAML syntax to maintain proper structure.
4. Changes automatically sync with the visual representation of your flow.
5. Switch between visual and Config views to see updates in real-time.
## Debugging
The Editor includes robust debugging tools to ensure your flows work as expected.
### Individual Node Debugging
**Method**:
1. Select the node you wish to debug.
2. Find the debug option in the node’s configuration panel.
3. Click the debug button to execute the node independently.
4. Review outputs and any error messages in the debug console.
5. Adjust node configurations based on the results.
### Full Flow Testing

**Method**:
1. Click "Test" in the main toolbar to execute the entire flow.
2. Observe each node’s progress in the debug console.
3. Review the final output and any intermediate results.
4. Adjust nodes as needed to optimize performance.
### Deployment Testing
**Method**:
1. Open deployment settings for your project.
2. Configure automated tests that run before each deployment.
3. Set success criteria (e.g., expected outputs, performance).
4. Deploy your flow; if tests fail, deployment will roll back.
5. Review test results, make changes, and redeploy as needed.
## Saving and Sharing
Save and share flows to maintain work continuity and foster collaboration.
### Saving Flows
**Method**:
1. Click the "Save" button in the main toolbar.
2. Optionally, add a commit message to document your changes.
3. Save regularly, as autosave is not supported.
### Sharing Flows
**Method**:
1. Click "Share" in the Editor to generate a unique URL.
2. Copy and distribute this URL within your organization.
3. Recipients can access and edit shared flows, enhancing collaborative efforts.
### Creating Templates
**Method**:
1. Open the flow you wish to template.
2. Choose "Create Template" from the Editor menu.
3. Select sharing scope:
- **Organization**: Share within your team.
- **Public**: Publish to the hub for broad access.
4. Add a title and description to guide other users.
5. Click "Create" to finalize and publish.
## Duplicating Flows
Duplicate flows to create variations or backups without affecting the original.
### Duplicating Flows
**Method**:
1. On the flow dashboard, find the flow you wish to duplicate.
2. Click the three-dot menu icon to open additional options.
3. Choose "Duplicate" to create a copy of the flow.
## Deployment
Deploy your completed flow to make it operational.
### Deploying Flows

**Method**:
1. Ensure all changes are saved and tested.
2. Click "Deploy" in the main toolbar.
3. Confirm deployment in the summary view, which lists flows and changes.
4. Monitor progress and resolve any errors or warnings.
### Flow Activation
**Method**:
1. Go to the project dashboard or flow management section.
2. Find the list of deployed flows.
3. Toggle the activation switch to enable or disable specific flows.
### Integration Setup
**Method**:
1. After deployment, open the "Integration" or "API" section in your dashboard.
2. Follow the provided instructions for integration, including:
- API endpoint details
- Authentication methods
- Sample code snippets in various languages
3. Use these resources to integrate your GenAI flow with external applications.
By following these step-by-step methods, you can effectively utilize the Editor to create, configure, debug, and deploy GenAI flows, maximizing the potential of your AI-driven projects.
---
# Flow AI Assistant
Source: https://lamatic.ai/docs/flows/flow-assistant.md
# Flow AI Assistant

**Note**: The Flow AI Assistant may occasionally provide improper or inaccurate responses. Please manually verify all instructions and configurations provided by the assistant. Our team is continuously working to improve this feature for better accuracy and reliability.
The Flow AI Assistant is an intelligent helper integrated directly into the Flow Editor that guides you through building and configuring flows with step-by-step instructions. It simplifies complex workflows and makes the flow editor more accessible, whether you're creating simple automation or sophisticated multi-node flows.
## What is the Flow AI Assistant?
The Flow AI Assistant is a contextual AI-powered panel that appears on the right side of the Flow Editor. It provides real-time guidance, step-by-step instructions, and answers to questions about building flows in Lamatic. The assistant understands your workflow context and offers relevant help based on what you're trying to accomplish.
## Key Features
### Step-by-Step Guidance
The AI Assistant provides detailed, numbered instructions for common tasks, such as:
- Creating new nodes for specific purposes
- Configuring AI models and credentials
- Setting up prompts and templates
- Connecting nodes in the correct sequence
- Testing and debugging flows
### Contextual Help
The assistant understands your current flow context and provides relevant suggestions:
- **Node Creation**: Get instructions on how to add and configure specific node types
- **Configuration Help**: Learn how to set up credentials, models, and parameters
- **Flow Logic**: Understand how to structure complex flows with multiple nodes
- **Best Practices**: Receive tips on optimizing your workflows
### Interactive Chat Interface
Use the "@" to Select Specific Node:
- Ask questions about specific nodes or configurations
- Get help with error messages
- Request examples for your use case
- Learn about advanced features and techniques
## How to Use the Flow AI Assistant
### Accessing the Assistant
**Method:**
1. Open any flow in the Flow Editor
2. Click on the "AI Assistant" tab on the right side of the screen
3. The assistant panel will open, ready to help
### Getting Help with Node Creation
The AI Assistant can guide you through creating and configuring nodes:
**Example: Creating an AI Content Generation Node**
1. Ask the assistant: "How do I create a node for AI content generation?"
2. The assistant will provide step-by-step instructions:
- Click the ➕ icon to add a new node
- Choose "Generate Text" from the node selection menu
- Configure the AI model (select credentials and choose a model like `gpt-4-turbo`)
- Add a prompt in the Prompts section
- Test your implementation to ensure it works correctly
### Building Complex Flows
The AI Assistant excels at helping you create sophisticated workflows:
**Method:**
1. Describe your goal or use case to the assistant
2. The assistant will break down the task into manageable steps
3. Follow the provided instructions to build your flow node by node
4. Ask follow-up questions if you need clarification on any step
**Example Use Cases:**
- Multi-step data processing pipelines
- Conditional logic and branching flows
- Integration with external APIs and services
- Complex AI workflows with multiple models
- Error handling and retry mechanisms
### Getting Configuration Help
When configuring nodes, the assistant can help with:
- **Credentials Setup**: Learn how to connect external services
- **Model Selection**: Understand which AI models work best for your use case
- **Prompt Engineering**: Get tips on writing effective prompts
- **Variable Mapping**: Learn how to reference outputs from previous nodes
**Method:**
1. Select a node in your flow
2. Ask the assistant about specific configuration options
3. Follow the detailed instructions provided
## Benefits of Using the AI Assistant
### Easier Flow Creation
- **Reduced Learning Curve**: New users can quickly understand how to build flows
- **Guided Workflows**: Step-by-step instructions eliminate guesswork
- **Contextual Help**: Get relevant information based on what you're working on
### Building Complex Flows
- **Break Down Complexity**: The assistant helps decompose complex requirements into manageable steps
- **Best Practices**: Learn optimal patterns for structuring flows
- **Error Prevention**: Get guidance that helps avoid common mistakes
- **Advanced Techniques**: Discover features and methods you might not know about
### Time Savings
- **Quick Answers**: Get immediate help without searching documentation
- **Focused Guidance**: Receive specific instructions for your exact use case
- **Troubleshooting**: Quickly resolve issues with targeted help
## Best Practices
1. **Be Specific**: When asking questions, provide context about what you're trying to achieve
2. **Follow Instructions**: The assistant provides detailed steps—follow them in order
3. **Ask Follow-ups**: If something isn't clear, ask for clarification
4. **Test as You Go**: After following instructions, test your flow to ensure it works correctly
5. **Learn Patterns**: Pay attention to the patterns the assistant teaches—they apply to many use cases
The Flow AI Assistant transforms the Flow Editor into a more intuitive and powerful tool, making it easier to build both simple automations and complex, multi-node workflows. Whether you're a beginner or an advanced user, the assistant provides valuable guidance to help you create flows more efficiently and effectively.
---
# Flow Config
Source: https://lamatic.ai/docs/flows/flow-config.md
# Flow Config (YAML Format)

At Lamatic.ai, we’ve enhanced our Flow Configuration to use YAML syntax, enabling a clear and organized way to define GenAI flow. This new structure supports both Low Code and No Code flexibility, allowing users to design and implement flows that meet specific needs efficiently. The YAML configuration is composed of `triggerNode`, `nodes`, and `responseNode`, each playing a distinct role in the workflow setup.
## What is Flow Config?
Flow Config is a way to define, structure, and control GenAI flow in Lamatic.ai’s platform. It represents each workflow as a series of interconnected components (or nodes) that perform specific tasks, with connections indicating the flow of data or control between these tasks. Using YAML, users can clearly configure these flow, benefiting both developers seeking fine-tuned control and non-technical users leveraging a simplified, visual interface.
## Key Definitions
| **Parameter** | **Type** | **Definition** | **Example** |
|------------------|------------------------|---------------------------------------------------------------------------------------------------------|-------------------------------------------------------------------------------------------------------------------------------|
| **nodeId** | `string` | A unique identifier for each node in the workflow. It is used to connect nodes and establish dependencies. | `LLMNode_6dek86wu8w` |
| **nodeType** | `string` | The type of node, indicating the functionality or purpose of the node (e.g., `graphqlNode`, `LLMNode`, `branchNode`). | `LLMNode` |
| **nodeName** | `string` | A human-readable name for the node, helping users understand the node’s role in the workflow. | `Demo Script Generator` |
| **values** | `object` | A dictionary of key-value pairs that contain specific settings and configurations for the node. Common values include prompts, model details, and mappings. | ```promptTemplate: "{{triggerNode_1.output.input}}", systemPrompt: "AI Assistant", messages: "[]", generativeModel: { provider: "openai", cred: "Gpt-4o", type: "text", id: "afd7b91d", model: "gpt-4o-mini" }``` |
| **needs** | `array` | Specifies dependencies, indicating the preceding nodes required for the current node’s operation. | `[ plus-node-branch-graphqlNode_0gnka1xu15804 ]` |
## Different Parts of the Config
### a. `triggerNode`
**What is it?**
The `triggerNode` is the starting point of the Flow. It initiates the workflow and is generally configured to retrieve or generate initial data. For example, a `graphqlNode` can be used as a triggerNode to pull data from a GraphQL source.
**Syntax and Values:**
```yaml
triggerNode:
nodeId: triggerNode_1
nodeType: graphqlNode
nodeName: API Request
values:
advance_schema: |-
{
"input": "string"
}
responeType: realtime
```
- **nodeId**: Unique identifier for the trigger node.
- **nodeType**: Typically `graphqlNode`, identifying it as a data retrieval point.
- **nodeName**: Descriptive name (e.g., `Graphql`).
- **values**: Settings specific to the trigger node, such as `responseType` and `advance_schema`.
### b. `nodes`
**What is it?**
The `nodes` section defines each step in the workflow. These nodes perform specific tasks, such as generating content or making decisions. Nodes can be dynamic (e.g., `LLMNode` for language models) or static (e.g., `branchNode` for logic branches).
**Syntax and Values:**
```yaml
nodes:
- nodeId: LLMNode_187
nodeType: LLMNode
nodeName: Text Generate
values:
promptTemplate: Prompt Goes here {{triggerNode_1.output.input}}
systemPrompt: You are an AI Assistant
messages: '[]'
generativeModelName:
provider_name: openai
credential_name: Gpt-4o Lamatic
type: generator/text
credentialId: afd7b91d-1c69-40cd-a9d6-cdca1ac5927a
model_name: gpt-4o-mini
needs:
- triggerNode_1
```
> Note: The `nodes` are indented under the `nodes` key in the YAML configuration one level below the Nodes and there adjacent nodes are listed on same level with `-` prefix.
- **nodeId**: Unique identifier for each node in the nodes list.
- **nodeType**: Indicates the node’s function, like `LLMNode` or `branchNode`.
- **nodeName**: Human-readable name to help identify the node.
- **values**: Contains settings like `promptTemplate` for content generation and `generativeModelName` for AI model selection.
- **needs**: Dependencies specifying prior nodes required for this node’s execution.
**Example of Branching Node:**
```yaml
- nodeId: branchNode_423
nodeType: branchNode
nodeName: Branching
values:
branches:
- label: Branch 1
value: branchNode_423-addNode_754
- label: Branch 2
value: branchNode_423-addNode_151
needs:
- LLMNode_187
branches:
- label: Branch 1
value: plus-node-addNode_754941
- label: Branch 2
value: plus-node-addNode_151825
```
- **branches**: Lists branching options, each with a label and value that defines the connection to subsequent nodes.
### c. `responseNode`
**What is it?**
The `responseNode` is the endpoint of the Flow, aggregating and outputting the results from the previous nodes. It often combines results from multiple nodes into a single response format.
**Syntax and Values:**
```yaml
responseNode:
nodeId: responseNode_triggerNode_1
nodeType: graphqlResponseNode
nodeName: API Response
values:
outputMapping: |-
{
"output": "{{LLMNode_187.output.generatedResponse}}"
}
needs:
- plus-node-addNode_161562
```
- **nodeId**: Unique identifier for the response node.
- **nodeType**: Identifies the node type, commonly `graphqlResponseNode`.
- **values**: Contains `outputMapping`, which organizes outputs from previous nodes.
- **needs**: Lists dependencies, generally the final node or merge nodes that lead into the response node.
Each part of the YAML configuration plays a crucial role in defining, structuring, and executing flow in a clear and flexible format, enabling both developers and non-technical users to create robust GenAI applications on Lamatic.ai’s platform.
## Common Issues
1. **Missing Fields**: See what nodes are missing required fields and retry after adding them.
2. **Flow Breaking**: Ensure that the flow is logically structured and all dependencies are correctly defined.
---
# Node Configuration
Source: https://lamatic.ai/docs/flows/node-config.md
# Node Configuration

The Node Configuration panel provides a comprehensive interface for configuring individual nodes within your flow. When you select a node in the Editor, the configuration panel appears on the right side of the screen, allowing you to customize the node's behavior, define its schema, and monitor its execution logs.
The configuration panel is organized into three main tabs: **Config**, **Schema**, and **Logs**. Each tab serves a specific purpose in managing and debugging your nodes.
## Config
The Config tab contains node-specific configuration settings that determine how the node operates within your flow. The exact configuration options vary depending on the node type, but common sections include:
## Schema
The Schema tab displays the node's input and output schema definitions. This helps you understand:
- **Input Schema**: The expected structure and types of data the node accepts
- **Output Schema**: The structure and types of data the node produces
- **Schema Validation**: Ensures data integrity throughout the flow
**Method**:
1. Select a node in your flow.
2. Click on the "Schema" tab in the configuration panel.
3. Review the input schema to understand what data the node expects.
4. Review the output schema to see what data will be available for subsequent nodes.
5. Use this information when connecting nodes and referencing outputs in your flow.
Understanding the schema is crucial for:
- Properly connecting nodes in your flow
- Using variable references correctly
- Ensuring data type compatibility between nodes
- Debugging flow issues related to data structure
## Logs
The Logs tab provides detailed execution logs when you test a flow or individual nodes. This is essential for debugging and monitoring node behavior:
- **Execution History**: View logs from previous test runs
- **Real-time Logging**: Monitor node execution in real-time during testing
- **Error Messages**: Identify and diagnose issues with detailed error information
- **Performance Metrics**: Track execution time and resource usage
**Method**:
1. Select the node you want to monitor.
2. Click on the "Logs" tab in the configuration panel.
3. Execute a test by clicking the "Test" button in the Config tab.
4. Review the logs to see:
- Execution steps and progress
- Input and output data
- Any errors or warnings
- Performance information
5. Use log information to identify and fix configuration issues.
### Understanding Log Information
Logs typically include:
- **Timestamp**: When the node executed
- **Status**: Success, error, or warning indicators
- **Input Data**: The data received by the node
- **Output Data**: The data produced by the node
- **Error Details**: Specific error messages and stack traces if issues occurred
## Best Practices
1. **Configure Before Testing**: Complete all required fields in the Config tab before running tests.
2. **Review Schema**: Always check the Schema tab to understand data structures before connecting nodes.
3. **Monitor Logs**: Regularly review logs during development to catch issues early.
4. **Test Incrementally**: Test individual nodes before testing the entire flow.
5. **Use Descriptive Prompts**: Write clear, specific prompts in the PROMPTS section for better AI performance.
6. **Validate Outputs**: Ensure output schemas match the expected format for downstream nodes.
By effectively using the Config, Schema, and Logs tabs, you can build, configure, and debug nodes efficiently, ensuring your flows operate as intended.
---
# Nodes
Source: https://lamatic.ai/docs/flows/nodes.md
# Nodes in Lamatic

Nodes are the fundamental building blocks of a flow in Lamatic. Each node serves a specific purpose, acting as a self-contained unit that processes input and produces output. This modular approach allows users to create complex flows by interconnecting various nodes.
## Node Categories
Lamatic organizes nodes into four main categories, each with a unique function in building flows:
### 1. Apps
- **Purpose**: Integrate third-party applications into your workflow.
- **Examples**: Slack, PostgreSQL, Google Sheets
- **Method**: These nodes act as bridges, enabling data exchange and action execution between Lamatic and external services.
### 2. AI
- **Purpose**: Perform artificial intelligence operations within your flow.
- **Examples**: Vector operations, text generation, natural language understanding
- **Method**: AI nodes use machine learning models to process and analyze data, allowing for tasks such as sentiment analysis, text classification, or content generation.
### 3. Data
- **Purpose**: Manipulate and transform data within your flow.
- **Examples**: Indexing, chunking, filtering
- **Method**: Data nodes provide tools for structuring, organizing, and processing information, ensuring data is in the right format for subsequent nodes.
### 4. Logic
- **Purpose**: Control the flow of execution in your workflow.
- **Examples**: Conditional statements, loops, custom code execution
- **Method**: Logic nodes allow for decision-making and branching, enabling dynamic, responsive flow based on specific conditions or criteria.
## Working with Nodes
### Configuring Input Fields
1. Click on the white space of a node to access its configuration panel.
2. Complete the required fields, marked with a red asterisk (*).
3. Configure optional fields based on your specific needs.
4. Ensure all required fields are filled to prevent flow errors.
### Understanding Node States
Nodes in Lamatic have visual indicators representing their current state:
- **Default (Grey)**: The initial state of a newly added node.
- *Method*: Add the node to your flow, then configure it.
- **Requires Fields (Yellow)**: Indicates missing required fields.
- *Method*: Review the configuration and complete all fields marked with a red asterisk (*).
- **Error (Red)**: Indicates an issue occurred during the last test run.
- *Method*: Check the error message, review your configuration, and make necessary adjustments.
- **Success (Green)**: Node is correctly configured and ready for deployment.
- *Method*: Connect this node to others in your flow or proceed with deployment.
### Working with Node Outputs
1. Each node generates output based on its configuration and input.
2. Output schemas vary depending on the node type and settings.
3. Consult individual node documentation for detailed output information.
4. Use the variable selector tool to understand and work with node outputs effectively.
5. Connect node outputs to subsequent nodes to create a cohesive workflow.
## Best Practices for Node Usage
1. Start with a clear understanding of your workflow requirements.
2. Choose appropriate nodes from each category to build a comprehensive flow.
3. Ensure all nodes are properly configured, with attention to required fields.
4. Regularly test your flow and address any errors or warnings.
5. Leverage diverse node categories to create powerful, automated workflows combining third-party integrations, AI capabilities, data manipulation, and logical operations.
---
# Sticky notes
Source: https://lamatic.ai/docs/flows/sticky-notes.md
# Sticky Notes in Lamatic Flows
## Overview
**Sticky Notes**, a feature in Lamatic that allows users to add rich-text notes directly within their workflow. This feature enhances collaboration, documentation, and organization by enabling users to jot down ideas, reminders, or comments seamlessly.
## Key Features
- **Multi-color Notes**: Choose different colors for better categorization.
- **Rich Text Formatting**: Options for **bold**, *italic*, and _underline_ text.
- **Text Sizing**: Set text to **small, medium, or large** for better visibility.
- **Draggable and Resizable**: Position notes anywhere within your flow.
## How to Use Sticky Notes

1. **Access the Sticky Note Tool**
- You can find the Sticky Note button in the bottom menu (last button on the left after undo, redo, zoom in/out).
- Click on it to create a new note in your flow.
2. **Customizing Your Note**
- Type your text inside the note.
- Format it using the available rich-text options.
- Resize and reposition the note as needed.
3. **Enhancing Workflow**
- Use different colors to classify notes (e.g., **yellow for reminders, blue for important updates**).
- Keep track of changes or comments without needing external documentation.
Sticky Notes add a **new layer of flexibility** to Lamatic flow, making it easier than ever to manage and organize complex automation flows.
---
# Variables
Source: https://lamatic.ai/docs/flows/variables.md
# Understanding Variables in Node-Based Systems

Variables are fundamental in node-based systems, enabling data flow between nodes. They serve two main functions:
- **Inputting data** into nodes
- **Transferring output** from one node to another
This setup allows for creating logical chains, where the output from one node acts as the input for the next. Imagine variables as water flowing through pipes, linking various parts of your system.
> **Note**: You can only access variables logically connected to a node within the flow, preserving data integrity and preventing unintended interactions.
## Working with the Variable Selector

The Variable Selector simplifies selecting and implementing variables in your workflow. Here’s how to use it:
### Method 1: Using the "Add Variables" Button
1. Find the "➕ Add Variables" button.
2. Click to open the variable selection menu.
3. Browse the available nodes and their variables.
4. Select a variable to add it to your current node.
### Method 2: Using Curly Braces Notation
1. In an input field, type two opening curly braces: `{{`.
2. This triggers the variable selection menu.
3. Choose your variable from the list.
4. The system will automatically close the curly braces for you.
The Variable Selector only displays nodes logically connected above the current node. After selecting a node, you can choose the specific variable from that node.
#### Limitations to Be Aware Of
- **Code Node Output**: New structures in custom code node schemas may not appear immediately. You may need to manually select nested variables.
- **Custom Webhook Schema**: Webhook schema variables may require a refresh or manual input due to varying structures.
## Understanding Variable Schema
Variable schemas define the structure of node output variables. They can be:
- **Preconfigured** for standard nodes
- **Customizable** for specific nodes (e.g., API or JSON generator schemas)
To view variables for a node:
1. Select the node in your workflow.
2. Review the list of variables and their structures.
### Accessing Nested Values
To access a nested value:
1. Start with the node’s output variable.
2. Add a dot (`.`) after the variable name.
3. Follow with the key of the nested value.
Example: `nodeOutput.nestedValue`
## Manipulating Lists (Arrays)
Lists, or arrays, are collections of items sharing the same schema. Common operations on lists include:
| Operation | Syntax | Example | Explanation |
|--------------------------|------------|-----------------|----------------------------------------------------------------------------------|
| Access item by index | `[n]` | `list[2]` | Retrieves the 3rd item (indexing starts at 0) |
| Select a range | `[a:b]` | `list[1:4]` | Retrieves items from index 1 to 4 (2nd to 5th items) |
| Extract specific key | `[:].key` | `list[:].child` | Returns a new list containing the `child` key from each item in the original list |
> **Note**: Indexing starts at 0, so the first item is at position 0.
## Configuring Output in Code Nodes
With code nodes, you can set up a custom output schema as follows:
1. Write your code logic within the code node.
2. Assign your desired output value to the `output` variable.
3. Structure your output using objects, arrays, or primitives.
#### Example
```javascript
// Define an initial object
const obj = { a: 1, b: 2, c: 3 };
// Create a new object, spreading properties of 'obj' and adding a new property
const newObj = { ...obj, d: 4 };
// Set the output
output = {
"newObj": newObj
};
---
# Agentic Doc Extraction
Source: https://lamatic.ai/docs/nodes/ai/agentic-doc-extraction.md
# Agentic Doc Extraction (Beta)
## Overview
The **Agentic Doc Extraction** node turns a document into structured, machine-readable output in a single flow step. Point it at a document URL, pick what you want back, and it runs OCR through a **per-run isolated container** and returns any combination of:
- **Clean Markdown** of every page, per page, or joined into one document.
- **Structured JSON** shaped to a schema you define, native document annotation, no separate parsing step.
- **Every image** in the document, stored for you and returned with its bounding box, an optional per-image annotation, a ready-to-use link, and a permanent storage key.
The key idea: extraction quality lives in your **Output Schema field descriptions**, not in a prompt. You describe what each field means and the OCR model reads the document for it. Each run spins up its own fresh container, so extractions are isolated from one another and scale independently.

This node accepts both **PDFs and images** (JPEG, PNG, WebP) by URL. It replaces the deprecated [Doc Extractor node](/docs/nodes/ai/doc-extractor), with native structured extraction, image storage, and bounding-box annotations built in. See [Migrating from Doc Extractor](#migrating-from-doc-extractor) below if you're moving existing flows.
## Features
**Key Functionalities**
1. **Markdown extraction**: clean, page-aware Markdown, returned per page or joined into a single document.
2. **Structured JSON extraction**: define an **Output Schema** and the model returns a JSON object matching it, driven entirely by your per-field descriptions.
3. **Image extraction + storage**: every image is stored in Lamatic-managed storage and returned with both a **presigned URL** (ready to use immediately) and a **durable storage key** (for retrieving the asset later).
4. **Bounding boxes & per-image annotations**: each image comes back with its coordinates, and an optional **BBox Annotations** schema attaches a structured reading of each figure/chart.
5. **Advanced OCR pipeline controls**: table format, page headers/footers, low-level layout blocks, per-word or per-page confidence scores, and image count/size limits, each individually toggleable.
6. **Multiple providers**: Mistral (public API) and **Azure AI Foundry** (private endpoint), selected by the credential you lock in. Self-hosted Mistral endpoints are supported too.
7. **Multi-config models**: attach more than one model configuration to the node.
8. **Cost & usage telemetry**: every run returns a `_meta` block with pages processed, token/page usage, and a two-tier cost (plain vs. annotated).
9. **Loop & batch aware**: inside a For Loop or Batch, each iteration writes its images under its own storage prefix, so runs never overwrite each other.
10. **Per-run isolated execution**: one fresh container per run keeps extractions isolated and lets them scale independently.
**Benefits**
1. **One step, three outputs**: Markdown, structured JSON, and stored images from a single node, instead of chaining OCR + parsing + upload.
2. **Schema-first accuracy**: extraction rules live in the schema's field descriptions, so results are consistent and easy to tune without prompt engineering.
3. **Durable, shareable assets**: extracted images persist beyond the run, addressable by a stable key and a signed URL.
4. **RAG-ready**: clean Markdown and structured fields drop straight into vectorization and indexing flows.
5. **Provider-flexible**: start on Mistral's public API and move to a private Azure AI Foundry endpoint without changing the flow.
## What Can I Build?
1. Invoice and receipt data extraction pipelines with structured JSON output.
2. Contract or report ingestion pipelines that need clean Markdown for search and summarization.
3. Form-processing pipelines with schema-driven field extraction from scanned or digital forms.
4. RAG ingestion pipelines that need both text and stored figures with durable references.
---
## How It Works
1. You provide a **document URL** and select an **OCR provider + model**.
2. The node hands the job to a **per-run container**, which downloads the document, splits every page, and OCRs the pages in parallel.
3. When images are enabled, the container stores each extracted image in Lamatic-managed storage and returns a signed URL plus a durable key.
4. The node assembles the response, `extractedText`, `structuredData`, `images`, `_meta`, and returns it to your flow.
The endpoint is decided entirely by the **credential** you lock in: a Mistral key uses the public API; an Azure AI Foundry credential uses its private endpoint.
---
## Prerequisites
Before adding the node, make sure you have:
- An **OCR provider credential**: a Mistral API key, or an Azure AI Foundry credential (endpoint + key).
- A **document reachable by URL**: either a direct URL or a value mapped from an upstream node.
The document host (and any custom OCR endpoint) must be reachable and allowlisted by the doc-extractor service. If a document fails to download, confirm the URL is public and, for private setups, that its host is on the service allowlist.
---
## Setup
### Step 1: Configure OCR Credentials
Create a credential for your provider. The credential determines which endpoint the node calls.
**Mistral (public API)**
| **Key Name** | **Description** | **Example Value** |
|---|---|---|
| **Credential Name** | Name to identify this credential | `mistral-ocr` |
| **API Key** | Your Mistral API key | `••••••••••••` |
**Azure AI Foundry (private endpoint)**
| **Key Name** | **Description** | **Example Value** |
|---|---|---|
| **Credential Name** | Name to identify this credential | `foundry-ocr` |
| **Endpoint URL** | Your Azure AI Foundry OCR endpoint | `https://.services.ai.azure.com/...` |
| **API Key** | Endpoint key | `••••••••••••` |
Any `url` set in the model params is ignored, the endpoint comes only from the locked-in credential. This keeps the call target trusted and predictable.
### Step 2: Add the Node to Your Flow
1. Add the **Agentic Doc Extraction** node.
2. Set the **Document URL** (direct or mapped, e.g. `{{triggerNode_1.output.document_url}}`).
3. Pick an **OCR Model** and its credential.
4. Choose an **Output Format**, Markdown or JSON, and toggle **Include Images** / **Join Pages** to taste.
5. (Optional) For JSON, define an **Output Schema**; for images, add a **BBox Annotations** schema; open **Advanced Settings** for pipeline knobs.
---
## Configuration Reference
### Settings
| **Field** | **Description** | **Options / Examples** | **Requirement / Default** |
|---|---|---|---|
| **Document URL** | URL of the document (PDF or image). Direct URL or a variable from an upstream node. | `https://.../report.pdf`, `{{triggerNode_1.output.document_url}}` | **Mandatory** |
| **OCR Model** | OCR provider + model. The credential decides the endpoint (Mistral public API vs. Azure AI Foundry private endpoint). | `mistral / mistral-ocr-latest` | **Mandatory** |
| **Output Format** | Format of the extraction. **JSON** unlocks the Output Schema for native structured extraction. | `Markdown`, `JSON` | Default: `Markdown` |
| **Join Pages** | Concatenates page Markdown into one entry. `extractedText` is **always** an array either way (see [Output](#output)). | On / Off | Default: `On` |
| **Include Images** | Store document images and return them with coordinates, a signed URL, a durable key, and (optionally) an annotation. Off = plain OCR, nothing stored. | On / Off | Default: `On` |
| **Advanced Settings** | Reveal the advanced Mistral pipeline options. When off, none of them are shown *or* sent. | On / Off | Default: `Off` |
| **Prompt (Optional)** | Extra guidance for structured extraction. Sent **only** when non-empty **and** a JSON Output Schema is set. | System prompt text | Default: empty |
Put your extraction rules and edge cases in the **schema field descriptions**, not the prompt. The prompt is optional and is ignored unless you're in JSON mode with a schema.
### Outputs Pane: Schemas
These two schemas appear under the **Outputs** pane and are each gated on a setting:
| **Schema** | **Shown when** | **What it does** |
|---|---|---|
| **Output Schema (JSON Schema)** | **Output Format = JSON** | Defines the JSON object to extract. Per-property `description` text tells the model what each field means. Switching back to Markdown clears it. |
| **BBox Annotations (JSON Schema)** | **Include Images = On** | Per-image annotation schema. Each extracted image is annotated with this structure and the result appears as `image_annotation` on the image. Turning Include Images off clears it. |
Both schemas require an **annotation-capable OCR model** (`mistral-ocr-2505` or newer). On older models the annotation fields are simply not produced.
### Advanced Configs
Revealed by **Advanced Settings**. Every knob is optional, anything left off is never sent, and the provider default applies.
| **Field** | **Description** | **Options** | **Default** |
|---|---|---|---|
| **Table Format** | `Off` keeps tables **inline** in the page Markdown. `Markdown`/`HTML` return tables as a separate `tables` field. | `Off`, `Markdown`, `HTML` | `Off` |
| **Extract Header** | Include page headers in the output. | On / Off | `Off` |
| **Extract Footer** | Include page footers in the output. | On / Off | `Off` |
| **Include Layout Blocks** | Return low-level layout blocks per page (adds a `blocks` field). | On / Off | `Off` |
| **Confidence Scores** | Attach OCR confidence at the chosen granularity. | `Off`, `Word`, `Page` | `Off` |
| **Image Limit** | Max images to extract per page. `0` = no limit. | Integer ≥ 0 | `0` |
| **Image Minimum Size (px)** | Skip images smaller than this. `0` = no minimum. | Integer ≥ 0 | `0` |
**Table Format** requires OCR `2512` or newer; older models ignore it and tables stay inline. Only the advanced outputs you turn **on** ride into `extractedText`, anything left off is excluded even if the model returns it by default.
---
## Output
The node returns four outputs. `extractedText`, `structuredData`, and `images` are **always arrays**; `_meta` is an object.
| **Field** | **Type** | **Additional Info** |
|---|---|---|
| **`extractedText`** | `Array` | **Join Pages On**: one merged entry `[{ markdown, ...enabled advanced outputs }]` (no `pageNumber`). **Off**: one entry per page `[{ pageNumber, markdown, ...enabled advanced outputs }]`. |
| **`structuredData`** | `Array` | One `{ pageNumber, annotation }` per page. Populated only when **Output Format = JSON**. |
| **`images`** | `Array` | One entry per stored image: `{ pageNumber, id, key, url, top_left_x, top_left_y, bottom_right_x, bottom_right_y, image_annotation? }`. `url` is a presigned link (expires, up to 7 days); `key` is the durable storage key; `image_annotation` is present only when a BBox schema was set. |
| **`_meta`** | `Object` | Usage & cost telemetry, pages processed, model, and a two-tier cost (annotated rate replaces the plain rate when any annotation schema is in play). |
### Example Output (Markdown mode, images on)
```json
{
"extractedText": [
{ "pageNumber": 1, "markdown": "# Quarterly Report\n\nRevenue grew 12%..." },
{ "pageNumber": 2, "markdown": "## Regional Breakdown\n\n" }
],
"structuredData": [],
"images": [
{
"pageNumber": 2,
"id": "img-0",
"key": "proj_abc/flow_123/req_789/agenticDocExtractionNode_1/2/000-img-0.png",
"url": "https://...storage.../000-img-0.png?X-Amz-Expires=3600&...",
"top_left_x": 72,
"top_left_y": 140,
"bottom_right_x": 520,
"bottom_right_y": 460,
"image_annotation": { "chartType": "bar", "title": "Revenue by region" }
}
],
"_meta": {
"model_name": "mistral-ocr-latest",
"pages_processed": 2,
"total_cost": 0.002
}
}
```
### Example Output (JSON mode)
```json
{
"extractedText": [{ "pageNumber": 1, "markdown": "..." }],
"structuredData": [
{
"pageNumber": 1,
"annotation": {
"invoiceNumber": "INV-2025-0042",
"total": 1284.50,
"dueDate": "2025-02-01"
}
}
],
"images": [],
"_meta": { "model_name": "mistral-ocr-latest", "pages_processed": 1 }
}
```
---
## Low-Code Example
### Markdown extraction
```yaml
- nodeId: agenticDocExtractionNode_1
nodeType: agenticDocExtractionNode
nodeName: Agentic Doc Extraction
values:
documentUrl: "{{triggerNode_1.output.document_url}}"
outputFormat: markdown
joinPages: false
includeImages: true
ocrModelName:
- configName: configA
type: ocr/document
provider_name: mistral
model_name: mistral-ocr-latest
credential_name: mistral-ocr
needs:
- triggerNode_1
```
### Structured JSON extraction
```yaml
- nodeId: agenticDocExtractionNode_2
nodeType: agenticDocExtractionNode
nodeName: Agentic Doc Extraction
values:
documentUrl: "{{triggerNode_1.output.document_url}}"
outputFormat: json
includeImages: false
schema: |
{
"type": "object",
"properties": {
"invoiceNumber": { "type": "string", "description": "The invoice number, usually top-right" },
"total": { "type": "number", "description": "Grand total including tax" },
"dueDate": { "type": "string", "description": "Payment due date in YYYY-MM-DD" }
}
}
ocrModelName:
- configName: configA
type: ocr/document
provider_name: mistral
model_name: mistral-ocr-latest
credential_name: mistral-ocr
needs:
- triggerNode_1
```
---
## Providers & Models
| **Provider** | **Endpoint** | **Notes** |
|---|---|---|
| **Mistral** | Public Mistral API | Default. Use `mistral-ocr-latest` (or a pinned version). |
| **Azure AI Foundry** | Your private Foundry endpoint | Endpoint comes from the credential. |
**Model capability notes**
- **Structured extraction & image annotations** (Output Schema, BBox Annotations) require `mistral-ocr-2505` or newer.
- **Table Format** requires `mistral-ocr-2512` or newer.
- Older OCR models still do Markdown extraction and image storage, they just skip the newer annotation/table features.
---
## Limits & Security
- **Document size**: up to ~1,200 pages and ~100 MB per document (service defaults).
- **Supported inputs**: PDF and image files (JPEG, PNG, WebP) by URL.
- **SSRF protection**: document and OCR hosts are validated; private/internal addresses (localhost, `10.x`, `172.16-31.x`, `192.168.x`, link-local, and IPv6 equivalents) are blocked, and redirects are re-checked at every hop.
- **Encrypted or non-PDF files** are rejected with a clear error rather than a partial result.
- **Image storage**: signed URLs are capped at 7 days; the durable `key` never expires and can be re-signed later.
Signed image URLs **expire** (up to 7 days). For long-lived access, store the returned `key` and re-generate a URL when you need one, rather than persisting the signed URL.
---
## Troubleshooting
| **Problem** | **Solution** |
|---|---|
| **Empty output / node returns `{}`** | The node isn't available on the pod running the test (or the container host isn't deployed for that environment). Confirm the node is deployed and try again. |
| **"Document URL is required"** | No `documentUrl` was provided or resolved. Check the field and any upstream mapping. |
| **"Unsupported OCR provider"** | The selected provider isn't `mistral` or `azure-ai-foundry`. Re-pick the model/credential. |
| **Document fails to download / "host not allowed"** | The document host isn't reachable or allowlisted. Use a public URL, or add the host to the service allowlist. |
| **`storage_not_configured` (500)** | Include Images is on but the service has no storage configured. Turn Include Images off, or configure storage on the doc-extractor service. |
| **HTTP 400 from the OCR provider in Markdown mode** | A prompt was set without a JSON Output Schema. Prompts are only valid alongside a schema, switch to JSON + schema, or clear the prompt. |
| **No structured fields returned** | Output Format isn't JSON, no Output Schema is set, or the model predates `mistral-ocr-2505`. Set JSON + schema and use a 2505+ model. |
| **No image annotations** | No BBox Annotations schema, Include Images is off, or the model predates `mistral-ocr-2505`. |
| **Tables missing from a separate field** | Table Format is `Off` (tables stay inline) or the model predates `mistral-ocr-2512`. |
| **Encrypted / not-a-PDF error** | The file is password-protected or isn't a real PDF/image. Provide an unencrypted, supported file. |
| **`too_large`** | The document exceeds the page/byte limit. Split it or reduce its size. |
---
## Example Use Cases
### Document Intelligence
- **Invoices & receipts**: extract totals, line items, and dates as structured JSON.
- **Contracts & reports**: clean Markdown for search, summarization, and review.
- **Forms**: schema-driven field extraction from scanned or digital forms.
- **Figures & charts**: pull images with bounding boxes and per-figure annotations.
### RAG Applications
- **Ingestion**: turn PDFs and scans into clean Markdown for vectorization and indexing.
- **Multimodal retrieval**: index both text and stored figures with durable references.
- **Question answering**: build assistants that answer over document content and structured fields.
---
## Migrating from Doc Extractor
The **[Doc Extractor](/docs/nodes/ai/doc-extractor) node is deprecated** in favor of Agentic Doc Extraction, the same OCR/document-extraction job, rebuilt with native structured extraction, image storage with bounding boxes, and a per-run isolated container.
**Doc Extractor is deprecated.** You can no longer add a *new* Doc Extractor node from the palette. Your **existing flows keep running unchanged**, nothing breaks. New extraction work should use **Agentic Doc Extraction**.
### Why migrate
Agentic Doc Extraction is a superset of Doc Extractor for the providers it supports, and adds:
- **Image storage**: images come back as durable storage keys + signed URLs (not inline base64), and their URLs are rewritten into the Markdown.
- **Per-image bounding-box annotations**: an optional schema reads each figure/chart.
- **A structured `images` output** and richer `_meta` cost telemetry.
- **Advanced pipeline controls**: headers/footers, layout blocks, confidence scores, image count/size limits.
- **Isolated, scalable execution**: one fresh container per run.
### Before you start: three breaking changes
Read these before re-pointing production flows:
1. **Gemini is not supported.** Doc Extractor accepted Mistral, Azure AI Foundry, **and Gemini**. Agentic Doc Extraction supports **Mistral and Azure AI Foundry only**. Gemini flows must switch provider.
2. **`extractedText` is now an array, not a string.** Any downstream reference that treated it as text must be updated (see [Output mapping](#output-mapping)).
3. **`structuredData` is now an array, not an object.** Same, update downstream references.
### Field mapping
| Doc Extractor (old) | Agentic Doc Extraction (new) | Notes |
|---|---|---|
| **OCR Model** (`ocrModelName`) | **OCR Model** (`ocrModelName`) | Same field. **Providers changed:** Gemini removed; Mistral + Azure AI Foundry only. |
| **Output Format**: `Markdown` / `Plain Text` / `JSON` | **Output Format**: `Markdown` / `JSON` | **`Plain Text` removed.** Use Markdown. |
| **Output Schema** (`schema`) | **Output Schema** (`schema`) | Unchanged, still gated on `Output Format = JSON`. |
| **Document URL** (`documentUrl`) | **Document URL** (`documentUrl`) | Unchanged. |
| **Join Pages** (`joinPages`) | **Join Pages** (`joinPages`) | Same toggle, but the **output shape differs**, `extractedText` is always an array now. |
| **Custom Extraction Prompt** (`customPrompt`, Gemini-only) | **Prompt (Optional)** (`prompts`) | Now a single system prompt, sent **only** alongside a JSON Output Schema. The Gemini-specific prompt override is gone. |
| **Include Annotations** (`mistralIncludeAnnotations`) | **Include Images** (`includeImages`) | Behavior changed, images are **stored** and returned as `url` + durable `key` + bbox (+ optional annotation), instead of inline base64. |
| **Table Format** (`mistralTableFormat`, default `Markdown`) | **Table Format** (`tableFormat`, default `Off`, under **Advanced Settings**) | **Default changed to `Off`** (tables stay inline). Now lives under the Advanced Settings toggle. |
| — | **BBox Annotations** (`bboxSchema`) | **New**, per-image annotation schema (shown when Include Images is on). |
| — | **Advanced Settings** + Extract Header / Extract Footer / Include Layout Blocks / Confidence Scores / Image Limit / Image Minimum Size | **New**, advanced Mistral pipeline knobs. |
### Output mapping
| Doc Extractor (old) | Agentic Doc Extraction (new) | Change |
|---|---|---|
| **`extractedText`**: `String` | **`extractedText`**: `Array` | **Breaking.** Join Pages On: `[{ markdown, ... }]`; Off: `[{ pageNumber, markdown, ... }]`. |
| **`structuredData`**: `Object` | **`structuredData`**: `Array` | **Breaking.** Now one `{ pageNumber, annotation }` per page. |
| — | **`images`**: `Array` | **New.** One entry per stored image with `url`, durable `key`, bbox coordinates, and optional `image_annotation`. |
| **`_meta`**: `Object` | **`_meta`**: `Object` | Unchanged in spirit (usage + cost telemetry). |
#### Updating downstream references
| If you had... | Change it to... |
|---|---|
| `{{docExtractor.output.extractedText}}` (as text) | `{{node.output.extractedText[0].markdown}}` (Join Pages **on**), or iterate the array (Join Pages **off**) |
| `{{docExtractor.output.structuredData.someField}}` | `{{node.output.structuredData[0].annotation.someField}}` |
| Inline base64 images from **Include Annotations** | `{{node.output.images[0].url}}` (signed link) or `.key` (durable storage key) |
### Migration steps
1. **Add an Agentic Doc Extraction node** next to (or in place of) the old one. Doc Extractor can't be re-added, so build the new step fresh.
2. **Re-select the provider + model.** Pick a Mistral or Azure AI Foundry credential. **Gemini users:** move to a supported provider.
3. **Map the basics**: `Document URL`, `Output Format` (Markdown or JSON), `Output Schema` (if JSON), `Join Pages`.
4. **If you used Include Annotations**, turn on **Include Images**, and (optionally) add a **BBox Annotations** schema. Update anything downstream to read from the new `images` output.
5. **Update downstream references** for the new array shapes of `extractedText` and `structuredData` (see the table above).
6. **Test the node**, then re-point the rest of the flow and remove the old step.
### Migration FAQ
**Will my existing Doc Extractor flows break?**
No. Deployed flows keep executing exactly as before, only the ability to add *new* Doc Extractor nodes is removed.
**Can I still use Gemini for OCR?**
Not in Agentic Doc Extraction. Use Mistral or Azure AI Foundry. If you specifically need Gemini, keep the existing Doc Extractor flow until you can switch providers.
**Where did the inline base64 images go?**
Images are now stored in Lamatic-managed storage and returned as a signed `url` plus a durable `key`, which is more efficient and keeps large payloads out of the flow. Store the `key` for long-lived access, signed URLs expire (up to 7 days).
**Do I have to switch to JSON output?**
No. Markdown is still the default and works the same way (just returned as an array now). JSON is only needed when you want native structured extraction via an Output Schema.
---
## Additional Resources
- [Mistral OCR Documentation](https://docs.mistral.ai/)
- [Azure AI Foundry Documentation](https://learn.microsoft.com/azure/ai-foundry/)
- [JSON Schema Reference](https://json-schema.org/)
---
# Classifier Node
Source: https://lamatic.ai/docs/nodes/ai/classifier-node.md
# Classifier Node
## Overview
The Classifier Node is a powerful AI component that enables users to automatically categorize and classify data based on predefined criteria or machine learning models. This node is essential for applications requiring intelligent data sorting, sentiment analysis, content moderation, and automated decision-making processes.

## Features
**Key Functionalities**
1. **Multi-Input Classification:** Supports both text and structured data inputs
for classification. 2. **Customizable Categories:** Allows defining specific categories
for classification based on application needs. 3. **Intent Recognition:** Identifies
user intent from textual input and maps it to predefined intents. 4. **Automated
Routing:** Routes data or user queries to the appropriate workflow based on classification
results. 5. **LLM Integration:** Uses large language models to enhance classification
accuracy and contextual understanding. 6. **Enhanced Classifier Editor:** Two-field editor (Name + Description) for better clarity, with inline editing enabled for both fields, making quick updates seamless.
**Benefits**
1. **Improved Automation:** Reduces manual intervention by automatically categorizing
input data. 2. **Enhanced User Experience:** Directs queries or data to the appropriate
processing module efficiently. 3. **Scalability:** Supports multiple classification
tasks across different domains. 4. **Efficiency:** Streamlines flow by integrating
classification and routing into a single node. 5. **AI-Powered Accuracy:** Leverages
advanced AI models for context-aware classification.
## What Can I Build?
1. Automate customer support by categorizing and routing user queries to the correct department.
1. Enhance chatbot interactions with intent-based responses.
1. Implement dynamic content recommendations based on user input classification.
1. Build intelligent document categorization systems for large-scale data management.
## Prompt Examples
### Support Ticket Router
The LLM reads the input and routes the flow down the matching branch.
**System Prompt**
```
You are a support ticket classifier.
Analyze the user's message and route it to the correct department.
Use the description of each classifier to make your decision.
Only pick one classifier. Do not explain your choice.
```
**User Prompt**
```
Classify this support message and route it to the right department:
{{triggerNode_1.message}}
```
**Classifiers**
| Name | Description |
|---|---|
| `Billing` | Payment issues, invoices, failed charges |
| `Technical` | Bugs, errors, integration problems |
Each classifier becomes a **branch in your flow**. Add the next nodes
(e.g. send to Slack, trigger an email) inside each branch.
> The Description field helps the LLM decide which branch to pick on ambiguous inputs.
## Setup
### Select the Classifier Node
1. Fill in the required parameters.
1. Build the desired flow
1. Select Classifier Node.
1. Deploy the Project
## Configuration Reference

| **Parameter** | **Description** | **Example Value** |
| ------------------------- | -------------------------------------------------------------------------------------------------------------- | ---------------------------- |
| **Generative Model Name** | Select the model to generate text based on the prompt. | Gemini Model |
| **Prompt Template** | Define the instructions for generating the text output.Define the instructions for generating the text output. | Tell me something about Bali |
| **Classifier** | Add Classifier with optional description. The two-field editor (Name + Description) supports inline editing for both fields, enabling quick and seamless updates. | `Classifier 1` |
| **System Prompt** | System prompt to guide the LLM | You are Travel Planner |
### Classifier Editor
Classifier nodes now support optional descriptions alongside names. The enhanced two-field editor provides:
- **Name Field:** The classifier label used for identification and routing
- **Description Field (Optional):** Additional context or details about the classifier
- **Inline Editing:** Both fields support inline editing, allowing you to make quick updates directly in the editor without opening additional dialogs
## Low-Code Example
```yaml
nodes:
- nodeId: agentClassifierNode_885
nodeType: agentClassifierNode
nodeName: Agent Classifier
values:
promptTemplate: ""
systemPrompt: ""
classifier:
- label: Classifier 1
value: agentClassifierNode_885-addNode_248
- label: Classifier 2
value: agentClassifierNode_885-addNode_671
needs:
- triggerNode_1
classifier:
- label: Classifier 1
value: plus-node-addNode_248884
- label: Classifier 2
value: plus-node-addNode_671526
- nodeId: plus-node-addNode_248884
nodeType: addNode
nodeName: ""
values: {}
needs:
- agentClassifierNode_885
- nodeId: plus-node-addNode_671526
nodeType: addNode
nodeName: ""
values: {}
needs:
- agentClassifierNode_885
- nodeId: plus-node-addNode_605143
```
## Output
### `_meta`
- A nested object containing metadata about the request processing.
- **`prompt_tokens`**: The number of tokens in the input prompt provided to the model.
- **`completion_tokens`**: The number of tokens generated in the model's output.
- **`total_tokens`**: The total sum of `prompt_tokens` and `completion_tokens`.
- **`model_name`**: The identifier of the AI model utilized for processing the request.
- **`model_provider`**: The organization or entity supplying the AI model.
### `class`
- The classification label or result determined by the classifier.
### `condition`
- A secondary attribute indicating the condition or context of the classification.
### Example Output
```json
{
"_meta": {
"prompt_tokens": 56,
"completion_tokens": 4,
"total_tokens": 60,
"model_name": "gemini-1.5-pro-latest",
"model_provider": "google"
},
"class": "Classifier 1",
"condition": "Classifier 1"
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------- | --------------------------------------------------------------- |
| **Invalid API Key** | Adjust the confidence threshold or refine system prompts. |
| **Low Classification Accuracy** | Increase the `Wait for Page Load` time in the configuration. |
| **Incorrect Routing** | Review and update routing rules based on classification output. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
1. Verify classification model settings.
1. Test different system prompts for improved accuracy.
---
# Doc Extractor Node (Deprecated)
Source: https://lamatic.ai/docs/nodes/ai/doc-extractor.md
# Doc Extractor Node (Deprecated)
**This node is deprecated.** You can no longer add a *new* Doc Extractor node from the palette. Existing flows keep running unchanged, nothing breaks. For new extraction work, use **[Agentic Doc Extraction](/docs/nodes/ai/agentic-doc-extraction)**, which supports the same job plus native structured extraction, stored images with bounding boxes, and a per-run isolated container. See [Migrating from Doc Extractor](/docs/nodes/ai/agentic-doc-extraction#migrating-from-doc-extractor) if you want to move an existing flow.
## Overview
The Doc Extractor node extracts content from a document URL (PDF or image), sends it to a selected LLM, and applies prompt-based instructions during extraction. You can control both the extraction behavior and the final response shape so downstream nodes receive output in the format you need.
## Features
**Key Functionalities**
1. **LLM-Guided Extraction**: Select an LLM model to interpret document content and extract relevant information intelligently.
2. **Instruction-Driven Parsing**: Provide extraction instructions with a custom prompt so the model returns only the fields and structure you need.
3. **Document URL Input**: Use a direct PDF/image URL or pass a URL dynamically from an upstream node.
4. **Configurable Output Format**: Return output as `markdown`, `json`, or `plain text` based on your workflow requirements.
5. **Page Handling Control**: Choose whether to join multi-page documents into a single response.
**Benefits**
1. **Flexible Automation**: Adapt extraction logic for invoices, reports, forms, receipts, and other document types.
2. **Consistent Downstream Processing**: Standardized output format simplifies chaining into parser, logic, and storage nodes.
3. **Reduced Manual Parsing**: Replace brittle OCR-only pipelines with prompt-guided extraction.
4. **Reusable Configuration**: Keep prompts and model settings reusable across multiple flows.
## What Can I Build?
1. Invoice and receipt data extraction pipelines
2. Resume and profile parsing automations
3. Contract or policy document summarization workflows
4. Document-to-JSON enrichment pipelines for databases and APIs
## Prompt Examples
### Invoice Data Extractor
Extracts key fields from an invoice PDF.
**Document URL**
```
{{triggerNode_1.document_url}}
```
**System Prompt**
```
Extract the following fields from this invoice:
- Invoice number
- Vendor name
- Invoice date
- Due date
- Line items (description, quantity, unit price)
- Total amount
Return as JSON. Use null for any field not found in the document.
```
**Settings**
- Output Format: `JSON`
- Join Pages: `On`
---
### Resume Parser
Extracts candidate details from a resume PDF.
**Document URL**
```
{{triggerNode_1.document_url}}
```
**System Prompt**
```
Extract the following details from this resume:
- Full name
- Email address
- Phone number
- Current job title
- Years of experience
- Top 5 skills
Return as JSON. Use null for any field not found.
```
**Settings**
- Output Format: `JSON`
- Join Pages: `On`
> Use `JSON` output format when passing data to downstream nodes. Switch to `Markdown` only for human-readable reports.
## Setup
### Select the Doc Extractor Node
1. Add the Doc Extractor node to your flow.
2. Select the LLM model for extraction.
3. Enter a document URL (PDF or image), or map it from an upstream node.
4. Add extraction instructions and optional custom extraction prompt.
5. Select the output format and page-join behavior.
6. Run and validate the output in node logs or downstream nodes.
## Configuration Reference
| Parameter | Description | Required | Example |
| --- | --- | --- | --- |
| LLM Model | Model used to extract and structure document content. | Yes | Gemini 2.5 Flast Lite |
| Prompt | Instructions that define what to extract and how to structure it. | Yes | Extract invoice number, vendor, line items, totals, and due date. |
| Document URL | URL of the document (PDF or image). Accepts direct URL or variable input from upstream node. | Yes | `{{trigger.document_url}}` |
| Custom Extraction Prompt | Overrides the default OCR prompt sent to the Gemini model. Leave empty to use the built-in prompt. | No | Focus on tabular data and preserve numeric precision. |
| Output Format | Output response format: `markdown`, `json`, or `plain text`. | Yes | json |
| Join Pages | If `true`, combines all pages into one extraction output. If `false`, keeps page-level granularity. | Yes | true |
## Prompting Tips
- Be explicit about required fields, output keys, and formatting rules.
- For JSON output, list expected keys and types to reduce malformed responses.
- Add fallback instructions for missing values (for example: `"null"` when field not found).
- If precision matters (amounts, IDs, dates), explicitly tell the model to avoid normalization.
## Low-Code Example
```yaml
nodeName: Doc Extractor
documentUrl: '{{triggerNode_1.output.url}}'
customPrompt: ''
mistralIncludeAnnotations: false
mistralTableFormat: markdown
outputFormat: markdown
joinPages: true
schema: ''
ocrModelName:
- configName: configA
type: ocr/document
provider_name: gemini
credential_name: MODEL_CRED_NAME
credentialId: 1f2d5b1e-9e8e-4b82-9996-70e351f8f720
model_name: gemini/gemini-2.5-flash-lite
params: {}
prompts:
- id: ID
role: user
content:""
```
## Output
The node returns extracted content in the format you selected:
- **`markdown`**: Useful for human-readable summaries and reports.
- **`json`**: Best for structured automation and downstream programmatic parsing.
- **`plain text`**: Lightweight output for quick processing or logging.
## Troubleshooting
### Common Issues
| Problem | Solution |
| --- | --- |
| Document URL not accessible | Verify URL is public/reachable and points to a valid PDF or image file. |
| Missing fields in output | Tighten extraction instructions and add explicit required keys in your prompt. |
| Output format mismatch | Confirm `Output Format` selection and ensure prompt aligns with that format. |
| Weak OCR quality | Use a clearer source document and add a `Custom Extraction Prompt` emphasizing OCR precision. |
### Debugging
1. Test with a known sample document before production input.
2. Start with JSON output for easier validation.
3. Check node logs to compare prompt, model response, and final parsed output.
---
# Generate Image Node
Source: https://lamatic.ai/docs/nodes/ai/generate-image-node.md
# Generate Image Node
## Overview
The Generate Image Node is a powerful AI component that creates images from text descriptions using advanced image generation models. This node enables users to generate custom visuals for various applications including content creation, design prototyping, and creative workflows.

## Features
**Key Functionalities**
1. **Generative Images**: Allows users to select credentials for their preferred generative model, ensuring flexibility and compatibility with various LLMs.
1. **Customizable Prompts**: Features a field for creating prompt templates, enabling tailored input for specific use cases.
**Benefits**
1. **Flexibility**: Supports integration with multiple LLMs, allowing users to utilize different models based on their specific needs and use cases.
1. **User-Centric Design**: Provides intuitive interfaces for prompt customization and system prompt definition, making it accessible to both beginners and advanced users.
## What Can I Build?
1. Automated generation of visual content for marketing campaigns.
1. Integration of custom image generation into e-commerce platforms for product visualization.
1. Creation of personalized artwork or graphics for social media posts.
1. Development of dynamic website features that adapt visuals based on user input.
## Prompt Examples
### Product Visual Generator
Generates a product image based on a description.
**User Prompt**
```
A high-quality product photo of {{triggerNode_1.product_name}}.
Clean white background, studio lighting, sharp focus, photorealistic.
```
---
### Social Media Banner
Generates a banner image for a social media post.
**User Prompt**
```
A modern social media banner for {{triggerNode_1.topic}}.
Vibrant colors, bold typography, minimalist design, 16:9 ratio.
```
> The more specific your prompt, the better the output. Always include style, lighting, background, and mood for best results.
## Setup
### Select the Image Generate Node
1. Fill in the required parameters.
1. Build the desired flow
1. Deploy the Project
1. Click Setup on the workflow editor to get the automatically generated instruction and add it in your application.
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| ------------------------- | -------------------------------------------------------------------------------------------------------------- | ----------------------------- |
| **Generative Model Name** | Select the model to generate text based on the prompt. | Open AI Model |
| **User Prompt** | Define the instructions for generating the text output.Define the instructions for generating the text output. | Create a Image of Car in Bali |
## Low-Code Example
```yaml
nodes:
- nodeId: ImageGenNode_135
nodeType: ImageGenNode
nodeName: ImageGen
values:
promptTemplate: make image on ${{triggerNode_1.output.topic}}
imageGenModelName:
provider_name: openai
type: generator/image
credential_name: Test
credentialId: b552a29b-69b6-4951-84c3-a6555bb132d1
model_name: hd/1024-x-1024/dall-e-3
needs:
- triggerNode_1
- nodeId: plus-node-addNode_401321
nodeType: addNode
nodeName: ""
values: {}
needs:
- ImageGenNode_135
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ------------------------------------------------------------ |
| **Invalid API Key** | Ensure the API key is correct and has not expired. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# Generate JSON Node
Source: https://lamatic.ai/docs/nodes/ai/generate-json-node.md
# Generate JSON Node
## Overview
The Generate JSON Node is a specialized AI component that generates structured JSON data based on user input and predefined schemas. This node is particularly useful for applications requiring consistent data structures, API integrations, and automated data formatting.

## Features
Key Functionalities
1. **Generative Model Selection**: Allows users to select credentials for their preferred generative model, ensuring flexibility and compatibility with various LLMs.
2. **Customizable Prompts**: Features a field for creating prompt templates, enabling tailored input for specific use cases.
3. **System Prompt Definition**: Includes an option to define a system-level prompt to guide the AI's behavior, ensuring context-aware and role-specific responses.
4. **Additional Properties Management**: Offers expandable sections for configuring advanced properties to fine-tune AI-generated outputs.
Benefits
1. **Flexibility**: Supports integration with multiple LLMs, allowing users to utilize different models based on their specific needs and use cases.
2. **User-Centric Design**: Provides intuitive interfaces for prompt customization and system prompt definition, making it accessible to both beginners and advanced users.
3. **Enhanced Control**: Enables precise control over the AI's behavior and output quality through customizable prompts and system configurations.
4. **Scalability**: Facilitates the creation of reusable prompt templates for diverse flow, ensuring consistency across projects.
## What Can I Build?
1. Create AI-driven applications that require structured data output from natural language inputs.
1. Develop automated systems for generating specific data formats for use in analytics and reporting.
1. Build interactive tools that convert conversational inputs into structured JSON for use in various applications.
1. Design flow for content generation that require consistency in data formatting across different platforms.
## Prompt Examples
### Structured Data Generator
Extracts key information from a user input and returns it as structured JSON.
**System Prompt**
```
You are a data extraction assistant.
Read the input and return only a valid JSON object.
Do not add any explanation or extra text outside the JSON.
```
**User Prompt**
```
Extract the following details from this text and return as JSON:
{{triggerNode_1.message}}
```
**Output Schema Example**
```json
{
"type": "object",
"properties": {
"name": { "type": "string" },
"email": { "type": "string" },
"issue": { "type": "string" }
}
}
```
> Define your schema fields clearly so the LLM knows exactly what to extract. Add more fields to the schema as needed.
## Setup
### Select the JSON Generate Node
1. Fill in the required parameters.
1. Build the desired flow
1. Deploy the Project
1. Click Setup on the workflow editor to get the automatically generated instruction and add it in your application.
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| ---------------------------- | -------------------------------------------------------------------------------------------------------------- | ------------------------------------- |
| **Generative Model Name** | Select the model to generate text based on the prompt. | Gemini Model |
| **Output Schema (Zod JSON)** | Define the output structure and validation rules using Zod JSON. | JSON Schema |
| **User Prompt** | Define the instructions for generating the text output.Define the instructions for generating the text output. | Tell me travel from Bali to Singapore |
| **System Prompt** | System prompt to guide the LLM | You are Travel Planner |
## Low-Code Example
```yaml
nodes:
- nodeId: InstructorLLMNode_774
nodeType: InstructorLLMNode
nodeName: JSON Generator
values:
schema: |-
{
"type": "object",
"properties": {
"output": {
"type": "string"
}
}
}
promptTemplate: tell me something about ${{triggerNode_1.output.topic}}
attachments: "[]"
messages: "[]"
generativeModelName:
provider_name: mistral
type: generator/text
credential_name: Mistral API
credentialId: 32bf5e3b-a8fc-4697-b95a-b1af3dcf7498
model_name: mistral/mistral-large-2402
needs:
- triggerNode_1
```
## Output Schema
### `_meta`
- A nested object containing metadata about the processing of the generation request.
### Token Usage Details
- **`prompt_tokens`**: Number of tokens in the input prompt provided to the model.
- **`completion_tokens`**: Number of tokens in the generated output.
- **`total_tokens`**: Sum of `prompt_tokens` and `completion_tokens`.
### `prompt_tokens_details`
- A nested object providing a breakdown of token usage in the prompt.
- **`cached_tokens`**: Number of tokens reused from a cache.
- **`audio_tokens`**: Number of tokens associated with audio input (if applicable).
### `completion_tokens_details`
- A nested object detailing token usage in the generated output.
- **`reasoning_tokens`**: Number of tokens used for reasoning processes (if applicable).
- **`audio_tokens`**: Number of tokens associated with audio output (if applicable).
- **`accepted_prediction_tokens`**: Number of tokens from accepted predictions (if applicable).
- **`rejected_prediction_tokens`**: Number of tokens from rejected predictions (if applicable).
### Model Information
- **`model_name`**: The name of the AI model used for generation.
- **`model_provider`**: The provider or organization supplying the model.
### Example Output
```json
{
"name": "Adelaide",
"_meta": {
"prompt_tokens": 56,
"completion_tokens": 7,
"total_tokens": 63,
"prompt_tokens_details": {
"cached_tokens": 0,
"audio_tokens": 0
},
"completion_tokens_details": {
"reasoning_tokens": 0,
"audio_tokens": 0,
"accepted_prediction_tokens": 0,
"rejected_prediction_tokens": 0
},
"model_name": "gpt-4-turbo",
"model_provider": "openai"
}
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ------------------------------------------------------------ |
| **Invalid API Key** | Ensure the API key is correct and has not expired. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# Generate Text Node
Source: https://lamatic.ai/docs/nodes/ai/generate-text-node.md
# Generate Text Node
## Overview
The Generate Text node allows users to programmatically generate text outputs by submitting prompts to selected LLMs. These text outputs can be further processed within each flow. This node is particularly useful for applications requiring dynamic text creation, such as chatbots, content creation, and automated report generation.

## Features
**Key Functionalities**
1. **Generative Model Selection**: Allows users to select credentials for their preferred generative model, ensuring flexibility and compatibility with various LLMs.
2. **Customizable Prompts**: Features a field for creating prompt templates, enabling tailored input for specific use cases.
3. **System Prompt Definition**: Includes an option to define a system-level prompt to guide the AI's behavior, ensuring context-aware and role-specific responses.
4. **Additional Properties Management**: Offers expandable sections for configuring advanced properties to fine-tune AI-generated outputs.
**Benefits**
5. **Flexibility**: Supports integration with multiple LLMs, allowing users to utilize different models based on their specific needs and use cases.
6. **User-Centric Design**: Provides intuitive interfaces for prompt customization and system prompt definition, making it accessible to both beginners and advanced users.
7. **Enhanced Control**: Enables precise control over the AI's behavior and output quality through customizable prompts and system configurations.
8. **Scalability**: Facilitates the creation of reusable prompt templates for diverse flow, ensuring consistency across projects.
## What Can I Build?
1. Automated content creation flow for blogs and social media posts.
1. Intelligent chatbots capable of generating dynamic and personalized responses.
1. Automated report generation systems for business intelligence and data analysis.
1. Customizable email and message drafting tools for improved communication efficiency.
## Prompt Examples
### Summarize
Condenses a long piece of text into a short, clear summary.
**System Prompt**
```
You are a summarization assistant.
Summarize the given text in 3-5 sentences.
Be concise and keep only the most important points.
Do not add any information that is not in the original text.
```
**User Prompt**
```
Summarize the following text:
{{triggerNode_1.content}}
```
> Note: To make the summary shorter or longer, update the sentence count in the System Prompt.
---
### Score Generator
Evaluates an input and returns a score with a short reason.
**System Prompt**
```
You are a scoring assistant.
Read the input and give it a score from 1 to 10 based on quality and relevance.
Return the score followed by a one-line reason.
Format: Score: X/10 — Reason:
```
**User Prompt**
```
Score the following response:
{{triggerNode_1.response}}
```
> Update the scoring criteria in the System Prompt to match your use case (e.g. clarity, tone, accuracy).
## Setup
### Select the Text LLM Node
1. Fill in the required parameters.
1. Build the desired flow
1. Deploy the Project
1. Click Setup on the workflow editor to get the automatically generated instruction and add it in your application.
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| ------------------------- | -------------------------------------------------------------------------------------------------------------- | ---------------------------- |
| **Generative Model Name** | Select the model to generate text based on the prompt. | Gemini Model |
| **User Prompt** | Define the instructions for generating the text output.Define the instructions for generating the text output. | Tell me something about Bali |
| **System Prompt** | System prompt to guide the LLM | You are Travel Planner |
## Low-Code Example
```yaml
nodes:
- nodeId: LLMNode_565
nodeType: LLMNode
nodeName: Text Generate
values:
promptTemplate: Tell me something about Bali
systemPrompt: You are an AI Assistant
messages: "[]"
generativeModelName:
provider_name: openai
type: generator/text
credential_name: Test OpenAI
credentialId: aeeb2922-a7d3-431a-a376-77e01e725c51
model_name: gpt-4-turbo
needs:
- triggerNode_1
```
## Output
### `_meta`
- A nested object containing metadata about the processing of the text generation request.
- **`prompt_tokens`**: Number of tokens in the input prompt.
- **`completion_tokens`**: Number of tokens in the generated output.
- **`total_tokens`**: Sum of `prompt_tokens` and `completion_tokens`.
- **`prompt_tokens_details`**: Breakdown of token usage in the prompt.
- **`cached_tokens`**: Tokens reused from cache.
- **`audio_tokens`**: Tokens from audio input (if applicable).
- **`completion_tokens_details`**: Breakdown of token usage in the generated output.
- **`reasoning_tokens`**: Tokens used for reasoning.
- **`audio_tokens`**: Tokens from audio output (if applicable).
- **`accepted_prediction_tokens`**: Tokens from accepted predictions.
- **`rejected_prediction_tokens`**: Tokens from rejected predictions.
- **`model_name`**: Name of the AI model used for text generation.
- **`model_provider`**: The provider or organization supplying the model.
### `generatedResponse`
- A string containing the text output generated by the model based on the input prompt.
### Example Output
```json
{
"_meta": {
"prompt_tokens": 19,
"completion_tokens": 212,
"total_tokens": 231,
"prompt_tokens_details": {
"cached_tokens": 0,
"audio_tokens": 0
},
"completion_tokens_details": {
"reasoning_tokens": 0,
"audio_tokens": 0,
"accepted_prediction_tokens": 0,
"rejected_prediction_tokens": 0
},
"model_name": "gpt-4-turbo",
"model_provider": "openai"
},
"generatedResponse": "Response"
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ------------------------------------------------------------ |
| **Invalid API Key** | Ensure the API key is correct and has not expired. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# MCP Node
Source: https://lamatic.ai/docs/nodes/ai/mcp-node.md
# MCP Node
## Overview
The MCP Node enables seamless integration with external data sources, APIs, and tools through the Model Context Protocol (MCP). This node allows AI models to securely access external resources, retrieve real-time data, and execute specific functions in a structured manner. It's particularly useful for applications requiring dynamic data access, real-time information retrieval, and integration with third-party services.

## Features
**Key Functionalities**
1. **MCP Server Integration**: Connect to configured MCP servers to access external data sources and tools.
1. **Function Execution**: Execute specific functions provided by MCP servers to retrieve data or perform operations.
1. **Real-time Data Access**: Access live data feeds, APIs, and dynamic content through MCP connections.
1. **Secure Communication**: Utilize secure protocols (HTTP/SSE) with proper authentication for data access.
1. **Flexible Configuration**: Support for custom headers, authentication methods, and connection parameters.
**Benefits**
1. **External Data Integration**: Seamlessly integrate with databases, APIs, and external services without compromising security.
1. **Real-time Information**: Access live data such as weather updates, stock prices, news feeds, and more.
1. **Tool Ecosystem**: Leverage custom tools and functions provided by MCP servers for enhanced AI capabilities.
1. **Scalable Architecture**: Connect to multiple MCP servers and handle complex data retrieval scenarios.
1. **Standardized Protocol**: Use a consistent interface for all external data interactions.
## What Can I Build?
1. **Weather Information Systems** - Retrieve real-time weather data for specific locations
2. **Financial Data Applications** - Access stock prices, currency conversion rates, and market data
3. **Document Processing Systems** - Search and retrieve documents from various sources
4. **API Integration Workflows** - Connect to third-party services and APIs
5. **Real-time Monitoring Systems** - Access live data feeds for monitoring and alerts
6. **Custom Tool Integration** - Use specialized tools and functions provided by MCP servers
## Prompt Examples
### GitHub User Lookup
Fetches GitHub user details using the GitHub MCP server.
**Query**
```
{{triggerNode_1.user_query}}
```
**Prompt (optional)**
```
You are a GitHub assistant. Use the available tools to fetch the
requested information and return a clear, concise summary.
Only use information returned by the tools. Do not make up details.
```
**Selected Tools**
- Select credentials first to load available tools, then enable the tools relevant to your use case (e.g. `get_user`, `list_issues`)
---
### Slack Notification Sender
Sends a message to a Slack channel based on flow output.
**Query**
```
Send a message to the #{{triggerNode_1.channel}} channel:
{{triggerNode_1.message}}
```
**Prompt (optional)**
```
You are a Slack assistant.
Use the available tools to send the message to the correct channel.
Confirm once the message has been sent successfully.
```
**Selected Tools**
- Select credentials first, then enable the `send_message` tool
> Selected Tools only appear after you select your MCP Server credentials. Connect your MCP Server first before configuring this node.
## Setup
### Configure MCP Server
1. Go to Lamatic Studio
2. Navigate to MCP/Tools > MCP
3. Click on + Add MCP
4. Configure the MCP server with connection details:
- **Credential Name**: Enter a descriptive name for your MCP server
- **Host**: Provide the MCP server URL (required field)
- **Type**: Select the protocol type (http or sse)
- **Headers**: Configure authentication and custom headers
5. Click "Test & Save" to validate the connection
### Select the MCP Node
1. Add the MCP node to your flow
2. Select the configured MCP server
3. Choose the specific function or tool to execute
4. Configure input parameters for the selected function
5. Deploy the project
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| ------------------------- | --------------------------------------------------------- | ----------------- |
| **Query** | Define the instructions for generating the text output. | `User Query` |
| **MCP Server** | Select the MCP server to use for the MCP node. | `Server 1` |
| **Generative Model Name** | Select the model to generate text based on the prompt. | `openai` |
| **Selected Tools** | Select the tools to be used for the MCP node. | Tools |
| **Messages (History)** | Pass your messages history here | [] |
| **Memories** | Pass your memories here | [] |
| **Attachments** | Select the attachments to be used for the Text generate LLM. | [] |
## Low-Code Example
```yaml
nodes:
- nodeId: mcpNode_195
nodeType: mcpNode
nodeName: MCP
values:
memories: "[]"
messages: "[]"
attachments: ""
credentials: MCP Server
selectedTools:
- add_comment_to_pending_review
- add_issue_comment
- assign_copilot_to_issue
- cancel_workflow_run
- create_and_submit_pull_request_review
promptTemplate: Tell me details about github user ABC
generativeModelName:
type: generator/text
model_name: default
credentialId: Credential
provider_name: openai
credential_name: AI_API
modes: {}
needs:
- triggerNode_1
```
## Output
```json
{
"_meta": {
"prompt_tokens_cost": 0.07718000000000001,
"completion_tokens_cost": 0.0027,
"total_cost": 0.07988,
"cached_prompt_tokens_cost": 0,
"prompt_tokens": 7718,
"completion_tokens": 90,
"total_tokens": 7808,
"prompt_tokens_details": {
"cached_tokens": 0,
"audio_tokens": 0
},
"completion_tokens_details": {
"reasoning_tokens": 0,
"audio_tokens": 0,
"accepted_prediction_tokens": 0,
"rejected_prediction_tokens": 0
},
"model_name": "gpt-4-turbo-preview",
"model_provider": "openai",
"info": {
"max_tokens": 4096,
"max_input_tokens": 128000,
"max_output_tokens": 4096,
"input_cost_per_token": 0.00001,
"output_cost_per_token": 0.00003,
"supports_pdf_input": true,
"supports_function_calling": true,
"supports_parallel_function_calling": true,
"supports_prompt_caching": true,
"supports_system_messages": true,
"supports_tool_choice": true
}
},
"generatedResponse": "response"
}
```
### `_meta`
- A nested object containing metadata about the MCP function execution and model usage.
- **`prompt_tokens_cost`**: Cost of prompt tokens used in the request.
- **`completion_tokens_cost`**: Cost of completion tokens generated.
- **`total_cost`**: Total cost of the entire operation.
- **`cached_prompt_tokens_cost`**: Cost of cached prompt tokens (if any).
- **`prompt_tokens`**: Number of prompt tokens used.
- **`completion_tokens`**: Number of completion tokens generated.
- **`total_tokens`**: Total number of tokens used.
- **`prompt_tokens_details`**: Detailed breakdown of prompt token usage.
- **`cached_tokens`**: Number of cached tokens used.
- **`audio_tokens`**: Number of audio tokens (if applicable).
- **`completion_tokens_details`**: Detailed breakdown of completion token usage.
- **`reasoning_tokens`**: Number of reasoning tokens used.
- **`audio_tokens`**: Number of audio tokens generated.
- **`accepted_prediction_tokens`**: Number of accepted prediction tokens.
- **`rejected_prediction_tokens`**: Number of rejected prediction tokens.
- **`model_name`**: Name of the AI model used (e.g., "gpt-4-turbo-preview").
- **`model_provider`**: Provider of the AI model (e.g., "openai").
- **`info`**: Model capabilities and configuration information.
- **`max_tokens`**: Maximum tokens allowed for output.
- **`max_input_tokens`**: Maximum tokens allowed for input.
- **`max_output_tokens`**: Maximum tokens allowed for output.
- **`input_cost_per_token`**: Cost per input token.
- **`output_cost_per_token`**: Cost per output token.
- **`supports_pdf_input`**: Whether the model supports PDF input.
- **`supports_function_calling`**: Whether the model supports function calling.
- **`supports_parallel_function_calling`**: Whether the model supports parallel function calling.
- **`supports_prompt_caching`**: Whether the model supports prompt caching.
- **`supports_system_messages`**: Whether the model supports system messages.
- **`supports_tool_choice`**: Whether the model supports tool choice.
### `generatedResponse`
- The response generated by the MCP node, which includes the result of the MCP function execution processed through the AI model.
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------- | -------------------------------------------------------------------- |
| **Connection Timeout** | Check network connectivity and increase timeout settings. |
| **Authentication Errors** | Verify API keys and authentication credentials. |
| **Function Not Found** | Ensure the function name is correct and available on the MCP server. |
| **Invalid Parameters** | Check parameter format and requirements for the selected function. |
### Debugging
1. Check Lamatic Flow logs for error details.
2. Verify MCP server configuration and connectivity.
3. Test the MCP server connection independently.
4. Review function documentation for correct parameter usage.
---
# Multimodal Node
Source: https://lamatic.ai/docs/nodes/ai/multimodal-node.md
# Multimodal Node
## Overview
The Multimodal Node is an advanced AI component that can process and analyze multiple types of data including text, images, and audio using various AI models. This node enables complex multimodal workflows where different types of input data need to be processed together.

## Features
**Key Functionalities**
1. **Textual and Visual Input Support**: Accepts both text and image inputs, enabling
seamless integration of multimodal data for processing. 2. **Text Generation**:
Produces textual outputs from selected large language models (LLMs) based on the
provided input. 3. **Image-Based Text Generation**: Generates captions and descriptive
text based on the content of images, making it suitable for applications like image
captioning. 4. **LLM Integration**: Supports integration with multiple large language
models, offering flexibility to choose the best-suited model for specific use cases.
5. **Context-Aware Processing**: Combines textual and visual data inputs to enhance
the accuracy and relevance of the generated output.
**Benefits**
1. **Versatility**: Enables applications in various domains, such as image captioning,
multimodal analysis, and AI-driven content generation. 2. **Enhanced User Experience**:
Provides seamless handling of both text and image inputs, improving workflow efficiency.
3. **Scalability**: Adapts easily to a wide range of use cases, from simple text
generation to complex multimodal data analysis. 4. **Efficiency**: Consolidates
textual and visual processing into a single node, reducing the need for separate
tools and streamlining flow. 5. **Advanced AI Integration**: Leverages the capabilities
of modern LLMs to deliver accurate and contextually rich outputs.
## What Can I Build?
1. Develop applications that seamlessly integrate text and image data processing for tasks like image captioning.
1. Create tools for automatic generation of descriptive content for visual data, enhancing accessibility.
1. Build interactive applications where user actions on images are analyzed to generate contextual feedback.
1. Design systems that maintain consistent tone and style across generated content based on previous interactions.
## Prompt Examples
### Image Analyser
Analyses an uploaded image and returns a detailed description.
**System Prompt**
```
You are an image analysis assistant.
Describe the content of the image in detail.
Include objects, colors, layout, and any visible text.
```
**User Prompt**
```
Analyse this image and describe what you see:
{{triggerNode_1.image_url}}
```
**Attachments**
```
{{triggerNode_1.image_url}}
```
---
### Product Image Reviewer
Reviews a product image and returns quality feedback.
**System Prompt**
```
You are a product image quality reviewer.
Look at the image and evaluate it on: background clarity,
lighting, product visibility, and overall quality.
Return a short assessment with improvement suggestions if needed.
```
**User Prompt**
```
Review this product image:
{{triggerNode_1.image_url}}
```
**Attachments**
```
{{triggerNode_1.image_url}}
```
> Always pass the image URL in both the Attachments field and the User Prompt so the model has full context.
## Setup
### Select the Multimodal Text Node
1. Fill in the required parameters.
1. Build the desired flow
1. Deploy the Project
1. Click Setup on the workflow editor to get the automatically generated instruction and add it in your application.
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| ------------------------- | -------------------------------------------------------------------------------------------------------------- | -------------------------------- |
| **Generative Model Name** | Select the model to generate text based on the prompt. | Gemini Model |
| **Prompt Template** | Define the instructions for generating the text output.Define the instructions for generating the text output. | Tell me something about Bali |
| **Attachments** | Select the attachments to be used for the multi modal LLM. | `{{triggerNode_1.output.topic}}` |
| **Messages (History)** | Pass your messages history herePass | [] |
| **System Prompt** | System prompt to guide the LLM | You are Travel Planner |
## Low-Code Example
```yaml
nodes:
- nodeId: multiModalLLMNode_924
nodeType: multiModalLLMNode
nodeName: Multi Modal
values:
promptTemplate: Tell me something about ${{triggerNode_1.output.topic}}
attachments: "{{triggerNode_1.output.topic}}"
systemPrompt: You are an AI Assistant
messages: "[]"
generativeModelName:
provider_name: mistral
type: generator/text
credential_name: Mistral API
credentialId: 32bf5e3b-a8fc-4697-b95a-b1af3dcf7498
model_name: mistral/mistral-large-2402
needs:
- triggerNode_1
- nodeId: plus-node-addNode_704346
nodeType: addNode
nodeName: ""
values: {}
needs:
- multiModalLLMNode_924
```
## Output
### `_meta`
- A nested object containing metadata about the processing of the text generation request.
- **`prompt_tokens`**: The number of tokens in the input prompt provided to the model.
- **`completion_tokens`**: The number of tokens in the generated output.
- **`total_tokens`**: The sum of `prompt_tokens` and `completion_tokens`.
- **`prompt_tokens_details`**: Breakdown of token usage in the prompt.
- **`cached_tokens`**: The number of tokens reused from a cache.
- **`audio_tokens`**: The number of tokens associated with audio input (if applicable).
- **`completion_tokens_details`**: Breakdown of token usage in the generated output.
- **`reasoning_tokens`**: The number of tokens used for reasoning processes (if applicable).
- **`audio_tokens`**: The number of tokens associated with audio output (if applicable).
- **`accepted_prediction_tokens`**: The number of tokens from accepted predictions (if applicable).
- **`rejected_prediction_tokens`**: The number of tokens from rejected predictions (if applicable).
- **`model_name`**: The name of the AI model used for text generation.
- **`model_provider`**
### Example Output
```json
{
"_meta": {
"prompt_tokens": 276,
"completion_tokens": 130,
"total_tokens": 406,
"prompt_tokens_details": {
"cached_tokens": 0,
"audio_tokens": 0
},
"completion_tokens_details": {
"reasoning_tokens": 0,
"audio_tokens": 0,
"accepted_prediction_tokens": 0,
"rejected_prediction_tokens": 0
},
"model_name": "gpt-4-turbo",
"model_provider": "openai"
},
"generatedResponse": "Response"
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ------------------------------------------------------------ |
| **Invalid API Key** | Ensure the API key is correct and has not expired. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# RAG Node
Source: https://lamatic.ai/docs/nodes/ai/rag-node.md
# RAG Node
## Overview
The RAG (Retrieval-Augmented Generation) Node is a sophisticated AI component that combines information retrieval with text generation. It first retrieves relevant information from a knowledge base or vector database, then uses that context to generate more accurate and informed responses.
The RAG Node generates more relevant responses from a Language Learning Model (LLM) by using Retrieval Augmented Generation (RAG). This approach incorporates additional context retrieved from a vector database to improve the accuracy and relevance of the generated text.
The node allows users to configure parameters such as the embedding model, generative model, and query specifics to tailor the response generation process to their needs. By leveraging RAG, users can efficiently create context-aware, concise, and helpful responses, making it a valuable tool for projects requiring advanced AI-driven text generation.

## Features
**Key Functionalities**
1. **Database Integration**: Allows integration with a specified database (e.g., `IndexCrawler`) to fetch relevant data for downstream processes.
2. **Dynamic Query Handling**: Supports dynamic query generation using variables (e.g., `{'{'}{'{'}}triggerNode.output.topic{'{'}{'}'}}`) for flexible search and data retrieval.
3. **Embedding and Generative Models**: Enables the use of embedding models (e.g., `mistral-embed`) and generative models (e.g., `mistral-large-2402`) for advanced AI-powered search and content generation tasks.
4. **API Modular Configuration**: Offers seamless customization with additional properties for tailored AI and search flow.
**Benefits**
1. **Flexibility**: Supports a variety of databases and AI models, making it adaptable for diverse use cases.
2. **Efficiency**: Utilizes embedding and generative models to provide relevant, high-quality outputs.
3. **Scalability**: Ensures the capability to handle large datasets and complex queries without performance issues.
4. **User-Friendly Design**: Simplifies workflow creation and configuration through an intuitive interface.
## What Can I Build?
1. Develop AI-driven chatbots that provide context-aware responses using RAG for improved user interactions.
1. Create automated customer support systems that deliver precise answers based on user queries and contextual data retrieval.
1. Build educational tools that generate tailored learning content and explanations by leveraging context from a vector database.
1. Design content creation platforms that use RAG to produce more relevant and concise articles or reports based on user input.
## Prompt Examples
### Knowledge Base Q&A
Answers user questions using content from your vector database.
**System Prompt**
```
You are a helpful assistant. Answer the user's question using only
the context retrieved from the knowledge base.
If the answer is not in the context, say "I don't have that information."
Do not make up answers.
```
**Search Query**
```
{{triggerNode_1.question}}
```
**Settings**
- No. of References: `5`
- Certainty: `0.7`
---
### Product Documentation Assistant
Helps users find answers from your product docs.
**System Prompt**
```
You are a product support assistant. Use the retrieved documentation
to answer the user's question clearly and concisely.
Always reference the relevant section when possible.
```
**Search Query**
```
{{triggerNode_1.user_query}}
```
**Settings**
- No. of References: `3`
- Certainty: `0.75`
> Increase Certainty closer to 1.0 for more precise matches. Lower it (e.g. 0.5) to return broader results when your knowledge base is small.
## Setup
### Select the RAG Node
1. Fill in the required parameters.
1. Build the desired flow
1. Deploy the Project
1. Click Setup on the workflow editor to get the automatically generated instruction and add it in your application.
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| ------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------- |
| **Database** | Select the vector database to be queried. | Database |
| **Search Query** | Input the query to search the vector database. | Tell me something about Bali |
| **Embedding Model Name** | This field allows the user to select the embedding model used to embed the query into vector space. It loads available embedding models through the listModels method. | Embedding Model Name |
| **Generative Model Name** | Select the model to generate responses from the query results. | LLM Model |
| **System Prompt** | System prompt to guide the LLM | You are Travel Planner |
| **No. of References** | Number of results to return | 3 |
| **Certainty** | It's the distance score into a value between 0 <= certainty <= 1, where 1 would represent identical vectors and 0 would represent opposite vectors. | 0.7 |
| **Filters** | Apply JSON-based filters to refine search results. | |
| **Messages (History)** | Pass your messages history here | [] |
## Low-Code Example
```yaml
nodes:
- nodeId: RAGNode_666
nodeType: RAGNode
nodeName: RAG
values:
systemPrompt: >-
You are a helpful AI assistant that answers user queries based on the
context provided to you.
vectorDB: IndexCrawler
queryField: "{{triggerNode.output.topic}}"
limit: "3"
certainty: "0.7"
filters: |-
{
"operator": "And",
"operands": [
{
"path": [
"title"
],
"operator": "Equal",
"valueText": "Test"
}
]
}
messages: "[]"
embeddingModelName:
provider_name: mistral
type: embedder/text
credential_name: Mistral API
credentialId: 32bf5e3b-a8fc-4697-b95a-b1af3dcf7498
model_name: mistral/mistral-embed
generativeModelName:
provider_name: mistral
type: generator/text
credential_name: Mistral API
credentialId: 32bf5e3b-a8fc-4697-b95a-b1af3dcf7498
model_name: mistral/mistral-large-2402
needs:
- triggerNode
```
## Output
### `modelResponse`
- The AI-generated text response based on the retrieved information and reasoning.
### `references`
- A list of source documents or data points used to generate the response.
- **`_additional`**: Contains extra metadata about the reference.
- **`certainty`**: A confidence score (float) indicating how relevant the reference is.
- **`data`**: The extracted content from the reference (can be a string or `null`).
- **`rr`**: An additional attribute or identifier, which can be `null`.
- **`certainty`** (duplicate at the top level): Same as the one inside `_additional`.
### `_meta`
- Metadata about the model's processing of the request.
- **`prompt_tokens`**: Number of tokens in the input prompt.
- **`completion_tokens`**: Number of tokens in the AI's response.
- **`total_tokens`**: Sum of `prompt_tokens` and `completion_tokens`.
- **`prompt_tokens_details`**: Breakdown of token usage in the prompt.
- **`cached_tokens`**: Tokens reused from cache.
- **`audio_tokens`**: Tokens from audio input (if applicable).
- **`completion_tokens_details`**: Breakdown of token usage in the generated output.
- **`reasoning_tokens`**: Tokens used for reasoning.
- **`audio_tokens`**: Tokens from audio output (if applicable).
- **`accepted_prediction_tokens`**: Tokens from accepted predictions.
- **`rejected_prediction_tokens`**: Tokens from rejected predictions.
- **`model_name`**: Name of the AI model used.
- **`model_provider`**: The provider or organization supplying the model.
### Example Output
```json
{
"modelResponse": "Response",
"references": [
{
"_additional": {
"certainty": 0.8730262517929077
},
"data": null,
"rr": "wr",
"certainty": 0.8730262517929077
},
{
"_additional": {
"certainty": 0.8614917993545532
},
"data": "info",
"rr": null,
"certainty": 0.8614917993545532
}
],
"_meta": {
"prompt_tokens": 112,
"completion_tokens": 111,
"total_tokens": 223,
"prompt_tokens_details": {
"cached_tokens": 0,
"audio_tokens": 0
},
"completion_tokens_details": {
"reasoning_tokens": 0,
"audio_tokens": 0,
"accepted_prediction_tokens": 0,
"rejected_prediction_tokens": 0
},
"model_name": "gpt-4-turbo",
"model_provider": "openai"
}
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ------------------------------------------------------------ |
| **Invalid API Key** | Ensure the API key is correct and has not expired. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# Supervisor Node
Source: https://lamatic.ai/docs/nodes/ai/supervisor-node.md
# Supervisor Node
## Overview
The **Supervisor Node** is an advanced AI component that provides oversight and management capabilities for workflow execution. It can monitor the performance of other nodes, make decisions about workflow routing, and ensure quality control throughout the process.

## Features
**Key Functionalities**
1. **Multi-Agent Coordination**: Manages multiple agent paths dynamically, ensuring structured workflow execution.
2. **Memory Retention**: Stores and recalls context from prior messages, enabling an ongoing conversation-like experience.
3. **Agent Path Definition**: Supports multiple agent branches, allowing customized execution flows.
4. **Loop Control**: Manages iterative agent execution with stopping conditions for efficient process completion.
**Benefits**
1. **Scalability**: Supports multiple agents within a single node, enabling scalable AI flow.
2. **Efficient Context Handling**: Reduces redundant data collection by recalling user-provided information.
3. **Adaptive Execution**: Allows for flexible branching based on AI-generated responses.
4. **User-Centric Design**: Provides a visual representation of multi-agent execution paths.
## What Can I Build?
- AI-powered personal assistants that dynamically route tasks across sub-agents.
- Multi-step flow for data collection, processing, and decision-making.
- Automated AI systems that require iterative questioning to refine responses.
- Intelligent customer support agents that engage in structured dialogues.
## Prompt Examples
### Research + Writer Agent
Coordinates a Research agent and a Writer agent to produce final content.
Each agent becomes a branch in your flow, add the relevant nodes inside each.
**System Prompt**
```
You are a supervisor coordinating two agents: Research and Writer.
First, send the task to the Research agent to gather information on the topic.
Then pass that research to the Writer agent to produce a clear, structured response.
Stop once the Writer has completed the response.
```
**Agent Paths**
| Name | Description |
|---|---|
| `Research` | Searches and retrieves relevant information on the given topic |
| `Writer` | Takes the research and writes a clear, structured response |
**Settings**
- Max Iterations: `5`
- Stop Word: `DONE`
---
### Customer Support Triage
Collects the user's issue and routes to the right agent.
**System Prompt**
```
You are a customer support supervisor.
Ask the user to describe their issue, then route to the correct agent:
Billing for payment issues, Technical for product problems.
Stop once the issue is resolved.
```
**Agent Paths**
| Name | Description |
|---|---|
| `Billing` | Handles payment, invoice, and subscription issues |
| `Technical` | Handles bugs, errors, and product problems |
**Settings**
- Max Iterations: `5`
- Stop Word: `RESOLVED`
> The Supervisor loops through agents until the Stop Word appears in the response or Max Iterations is reached. Always set both to avoid infinite loops.
## Setup
### Configuring the Supervisor Node
1. Define the **Agent Paths** to specify branching logic.
2. Set up the **Prompt Template** to control AI responses.
3. Assign an **LLM Model** for text generation.
4. Configure **Stop Words** and **Iteration Limits** for loop control.
### Deployment
1. Integrate the Supervisor Node into the workflow.
2. Connect relevant agent nodes for branching execution.
3. Deploy the project and trigger workflow execution.
---
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
|---------------------|--------------------------------------------------------------|------------------|
| **Prompts** | Add prompts for system,users and assistants | `System Prompt, User Prompt` |
| **Agent Paths** | Defines execution paths for multiple agents. | `Agent 1, Agent 2` |
| **Memory Retention** | Retains context across iterations. | `Enabled` |
| **Max Iterations** | Sets the maximum loops before termination. | `5` |
| **Stop Word** | Terminates execution when a condition is met. | `end` |
| **LLM Model** | Selects the AI model for text generation. | `GPT-4 Turbo` |
---
## Low-Code Example
```yaml
nodes:
- nodeId: agentNode_960
nodeType: agentNode
nodeName: Supervisor
values:
tools: []
agents:
- name: Research
schema: {}
description: Agent 1 description
- name: Writer
schema: {}
description: Agent 2 description
prompts:
- id: 9ed337ec-a4c0-4885-9066-f2853347d20b
role: system
content: >-
Research on the topic {{triggerNode_1.output.topic}} and pass on
your search to the writer to give the ideal text.
messages: '[]'
stopWord: ''
connectedTo: agentLoopEndNode_242
maxIterations: 5
generativeModelName:
type: generator/text
model_name: gpt-4o-mini-2024-07-18
credentialId: f6930a0d-9947-472c-b64b-2244a131cad0
provider_name: openai
credential_name: OPEN_AI_KEY
needs:
- triggerNode_1
- agentLoopEndNode_242
connections:
- condition: Research
value: webSearchNode_852
type: conditionEdge
invisible: false
- condition: Writer
value: LLMNode_238
type: conditionEdge
invisible: false
- condition: Agent Loop End
value: agentLoopEndNode_242
type: agentLoopEdge
invisible: true
```
## Output
A nested object containing the output generated by the Supervisor Node. This depends and modifies based on the
paths and agents defined in the configuration.
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ----------------------------------------------------------------- |
| **Invalid API Key** | Ensure the API key is correct and has not expired. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# API Node
Source: https://lamatic.ai/docs/nodes/data/api-node.md
# API Node
## Overview
The Lamatic.ai API Node enables users to integrate external REST APIs effortlessly into their flow.

## Features
**Key Functionalities**
1. **Custom Logic Integration:** Seamlessly incorporate JavaScript code to create tailored flow.
2. **Data Manipulation:** Process and transform large datasets dynamically within your flows.
3. **Third-Party API Support:** Extend your flow by connecting to external APIs and services.
4. **Dynamic Report Generation:** Automate the creation of insightful reports based on real-time data.
5. **Testing and Deployment Tools:** Easily test and deploy JavaScript logic directly in the Lamatic platform.
**Benefits**
1. **Enhanced Flow Customization:** Tailor flows to meet specific business or operational needs.
2. **Streamlined Automation:** Minimize manual intervention with robust, automated processes.
3. **Improved Efficiency:** Optimize flow by integrating complex operations directly into your flows.
4. **Reduced Development Overhead:** Empower developers to build and deploy custom logic without external systems.
5. **Scalable Design:** Create reusable logic components that adapt to various use cases and scale with your needs.
## What Can I Build?
1. **Automated Data Processing Flow:** Handle large datasets within the Lamatic platform effortlessly by automating repetitive tasks and calculations.
1. **Custom Notification Systems:** Send alerts based on specific criteria or data changes, ensuring timely communication.
1. **Third-Party API Integration:** Extend the functionality of existing Lamatic flows by incorporating external APIs.
1. **Dynamic Report Generation:** Compile and present data insights automatically for real-time analysis and decision-making.
If the target API is protected by a firewall, security group, or IP allowlist,
review [IP Allowlisting](/docs/ips) before testing the node.
## Setup
### Select the API Node
1. Fill in the required parameters.
1. Build the desired flow
1. Deploy the Project
1. Click Setup on the workflow editor to get the automatically generated instruction and add it in your application.
## Configuration Reference
| **Parameter** | **Description** | **Required** | **Example Value** |
| -------------------------------- | ------------------------------------------------------------------------------------------------- | ------------ | ---------------------------- |
| **Endpoint URL** | Specify the URL of the API endpoint that this node will connect to for sending or receiving data. | Yes | https://api.github.com/users |
| **Method** | API Request Method (Get/Post) | Yes | Get |
| **Body** | Body Parameters | Yes | {} |
| **Headers** | API Headers | No | [] |
| **Number of Retries** | Set the number of retry attempts if the API request fails. | No | 0 |
| **Delay between retry (sec)** | Specify the wait time in seconds between each retry. | No | 0 |
| **Convert XML Response to JSON** | Automatically convert XML responses to JSON format. | No | true |
## Low-Code Example
```yaml
nodes:
nodes:
- nodeId: apiNode_601
nodeType: apiNode
nodeName: API
values:
url: https://api.github.com/users
method: GET
headers: ''
body: '{}'
retries: '0'
retry_deplay: '0'
needs:
- triggerNode_1
- nodeId: plus-node-addNode_259786
nodeType: addNode
nodeName: ''
values: {}
needs:
- apiNode_601
```
## Output
The data retrieved from the API request.
### Example Output
```json
{ "key": "value" }
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ------------------------------------------------------------ |
| **Invalid API** | Ensure the API is correct. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# Chunking Node
Source: https://lamatic.ai/docs/nodes/data/chunking-node.md
# Chunking Node
## Overview
The Chunking Node is a data processing component that breaks down large text documents into smaller, manageable chunks. This is essential for processing large documents with AI models that have token limits, enabling efficient text analysis and processing.

## Features
**Key Functionalities**
1. **Custom Chunking Logic:** Configure specific methodologies and separators to divide text into meaningful units while preserving context.
1. **Semantic Preparation:** Break data into manageable chunks optimized for vectorization and semantic retrieval processes.
1. **Flexible Integration:** Incorporate Lamatic.ai's Chunking node into various flow for tailored data processing solutions.
1. **Contextual Integrity:** Ensure the resulting chunks maintain relevance and logical flow for downstream analysis.
1. **Configurable Parameters:** Customize chunk size, overlap, and separators to match the needs of your dataset.
**Benefits**
1. **Optimized Data Processing:** Enhance the performance of vectorization and semantic retrieval with pre-processed chunks.
1. **Scalable Flow:** Manage large datasets effectively, enabling flow to scale seamlessly with increasing data.
1. **Improved Accuracy:** Maintain context and relevance in chunked data for better insights during analysis.
1. **Streamlined Automation:** Automate text parsing tasks to save time and reduce manual effort.
1. **Enhanced Insights:** Facilitate meaningful information extraction from structured and unstructured datasets.
## What Can I Build?
1. Develop a system for efficient text vectorization and semantic retrieval.
1. Create flow that handle large datasets by breaking them into manageable chunks.
1. Implement automation processes to parse and prepare data for machine learning models.
1. Build data processing pipelines that maintain context and relevance through custom chunking methodologies.
## Setup
### Select the Chunking Node
1. Fill in the required parameters.
1. Build the desired flow
1. Deploy the Project
1. Click Setup on the workflow editor to get the automatically generated instruction and add it in your application.
## Configuration Reference
| **Parameter** | **Description** | **Required** | **Example Value** |
| -------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------ | ----------------------------------- |
| **Text to chunk** | The text data to be split into smaller chunks. | Yes | `${{data}}` |
| **Number of Characters** | Max length (in characters) for each chunk. | Yes | 200 |
| **Overlapping Characters** | Number of characters overlapping between chunks. | Yes | 20 |
| **Chunking Type** | Choose the method to split the text into chunks.
`Recursive Character Text Splitter` method splits text into smaller chunks while preserving as much context as possible. It works by recursively breaking down the text, starting with larger logical units like paragraphs, then sentences, and so on, until the desired chunk size is achieved. This approach is ideal for use cases where maintaining coherence within chunks is important, such as natural language processing or document indexing.
`Character Text Splitter` is a simpler method that divides text into chunks based on a fixed number of characters. It does not consider the structure of the text, such as paragraphs or sentences, and while it is faster and easier to implement, it may cut off sentences or disrupt the logical flow of the text. | Yes | `Recursive Character Text Splitter` |
| **List of separators** | Characters or strings used to define chunk boundaries. | No | `\n\n` `\n` ` ` |
## Low-Code Example
```yaml
nodes:
- nodeId: chunkNode_262
nodeType: chunkNode
nodeName: chunking
values:
chunkField: "{{triggerNode_1.output.content}}"
numOfChars: 200
separators:
- \n\n
- \n
- " "
chunkingType: recursiveCharacterTextSplitter
overlapChars: "20"
needs:
- triggerNode_1
```
## Output
### `chunks`
- An array of objects, each representing a segmented portion of the input text and its associated metadata.
### `pageContent`
- The textual content of the chunk, extracted from the input data.
### `metadata`
- A nested object providing additional details about the chunk's origin or properties.
### `loc`
- Location information within `metadata`, indicating where in the source text the chunk starts and ends (e.g. line numbers).
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ----------------------------------- | ------------------------------------------------------------------------------------------------------ |
| **No chunks returned** | Ensure **Text to chunk** resolves to a non-empty string; check the upstream node's output. |
| **Chunks cut off mid-sentence** | Switch to `Recursive Character Text Splitter`, which respects paragraph and sentence boundaries better than `Character Text Splitter`. |
| **Overlap larger than chunk size** | Keep **Overlapping Characters** smaller than **Number of Characters**, otherwise chunking may behave unpredictably. |
| **Separators not taking effect** | Double-check the **List of separators** field matches the actual line breaks or delimiters in your source text. |
### Debugging
1. Check Lamatic Flow logs for the node's input and output to confirm the text reaching the node.
2. Inspect the `chunks` output array to verify chunk count and size match your configuration.
---
# Document Handling Node
Source: https://lamatic.ai/docs/nodes/data/document-handling-node.md
# Document Handling Node
## Overview
Working with PDFs in a flow used to mean piecing together multiple nodes just to merge a couple of files or pull out a few pages. The Document Handling node does it in one step: pick what you want done, point it at your documents, and get a ready-to-use file back.
It covers 14 operations across five types: Merge, Split, Pages, Bookmarks, and Metadata. You pick a **Type** first, then the specific **Operation** for that type, so you only ever see the fields relevant to what you're doing instead of one long list of every option at once.

## Features
Key Functionalities
1. **Merge**: Combine multiple PDFs into one, with optional per-document page ranges and bookmark preservation.
2. **Split**: Break a PDF apart every N pages, at specific page numbers, or into one file per page.
3. **Pages**: Extract, delete, insert blank pages, insert pages from another document, or reorder/duplicate pages.
4. **Bookmarks**: List, set, or remove a PDF's bookmarks.
5. **Metadata**: Get or set document metadata, title, author, subject, creator, and keywords.
Benefits
1. **One Node, Not a Chain**: Handle common PDF editing tasks without wiring together multiple nodes.
2. **Only Relevant Fields**: The two-step Type → Operation picker keeps the panel focused on what you're actually configuring.
3. **Safe by Default**: Each run executes in its own isolated container, and documents flow in and out as URLs rather than inline data.
4. **Predictable I/O**: Every operation that produces a file returns the same shape, a presigned URL plus a durable storage key, so downstream nodes always know what to expect.
## What Can You Build?
- Merge a cover page, generated report, and appendix into a single client-facing PDF.
- Split a large scanned document into per-page or per-chapter files for downstream processing.
- Strip a fixed cover page or insert a signed addendum into an existing contract.
- Read or stamp document metadata (title, author, keywords) as part of a publishing pipeline.
- Preserve or rebuild a PDF's bookmark outline when reassembling documents.
---
## How It Works
Drop the node into a flow, provide your document URL(s), and run it. Each run spins up in its own isolated container.
- **Inputs are URLs only.** Base64 input is rejected with a message pointing you at a URL instead, this keeps whole PDF files out of your workflow state and run logs.
- **Outputs that produce a file** return a presigned URL and a durable storage key, ready to pass to the next step or store for later.
- **List Bookmarks and Get Metadata** return their data directly instead of a file.
**Two things worth knowing before you rely on this node:**
Password-protected PDFs are rejected. The node can't process an encrypted file it can't open. **Get Metadata** is the one exception, it can still inspect an encrypted document without the password.
Some operations (**Extract**, **Insert**, and ranged **Merge**) can drop annotations, outlines, or form fields from the source PDF. This is a limitation of the underlying processing, not a bug, the node UI calls it out directly so it isn't a surprise.
## Setup
### 1. Merge
Combines multiple PDFs into a single document.
#### Configuration Reference
| Parameter | Description | Required | Example |
| --- | --- | --- | --- |
| Documents | The PDF files to merge, in order. Accepts URLs. | Yes | `["{{node1.output.url}}", "{{node2.output.url}}"]` |
| Page Ranges | Optional per-document page ranges. Leave empty to include a document in full. | No | `1-3` |
| Preserve Bookmarks | If enabled, carries each source document's bookmarks into the merged output. | No | true |
#### Output
- `files`: an array with one entry: `{ url, key, pageCount }` for the merged document.
### 2. Split
Breaks a single PDF into multiple files.
#### Configuration Reference
| Parameter | Applies to | Description | Required | Example |
| --- | --- | --- | --- | --- |
| Document | All | The PDF to split. Accepts a URL. | Yes | `{{node1.output.url}}` |
| Operation | All | Which split mode to use. | Yes | `At Specific Page Numbers` |
| Pages per File | Every N Pages | Number of pages per output file. | Yes, for this operation | `5` |
| Pages | At Specific Page Numbers | Page numbers to split at. | Yes, for this operation | `3, 7, 12` |
Every Page needs no additional field, each page becomes its own file.
#### Output
- `files`: an array with one entry per resulting file: `{ url, key, pageCount }`.
### 3. Pages
Adds, removes, or reorders pages within a document.
#### Configuration Reference
| Parameter | Applies to | Description | Required | Example |
| --- | --- | --- | --- | --- |
| Document | All | The PDF to modify. Accepts a URL. | Yes | `{{node1.output.url}}` |
| Operation | All | Extract, Delete, Insert Blank Pages, Insert From Document, or Reorder/Duplicate. | Yes | `Extract` |
| Pages | Extract, Delete | Page numbers or ranges to extract or delete. | Yes, for these operations | `1-2, 5` |
| Position | Insert Blank Pages, Insert From Document | Where to insert the new pages. | Yes, for these operations | `after page 3` |
| Count | Insert Blank Pages | Number of blank pages to insert. | Yes, for this operation | `1` |
| Source Document | Insert From Document | URL of the PDF to pull pages from. | Yes, for this operation | `{{node1.output.url}}` |
| Source Pages | Insert From Document | Page numbers or ranges to pull from the source document. | Yes, for this operation | `1-2` |
| Page Order | Reorder/Duplicate | The new page order. Repeat a page number to duplicate it. | Yes, for this operation | `1, 1, 2, 4, 3` |
Extract and Insert can drop annotations, outlines, and form fields from the affected pages.
#### Output
- `files`: an array with one entry: `{ url, key, pageCount }` for the resulting document.
### 4. Bookmarks
Reads or modifies a PDF's bookmark outline.
#### Configuration Reference
| Parameter | Applies to | Description | Required | Example |
| --- | --- | --- | --- | --- |
| Document | All | The PDF to read or modify. Accepts a URL. | Yes | `{{node1.output.url}}` |
| Operation | All | List, Set, or Remove. | Yes | `Set` |
| Bookmarks (JSON) | Set | The bookmark outline to write, as JSON. | Yes, for this operation | `[{"title": "Chapter 1", "page": 1}]` |
| Replace Existing Bookmarks | Set | If enabled, replaces the document's entire bookmark outline. If disabled, adds to the existing outline. | No | true |
#### Output
- **List**: `bookmarks`, the document's current bookmark outline.
- **Set / Remove**: `files`, an array with one entry: `{ url, key, pageCount }` for the updated document.
### 5. Metadata
Reads or writes a PDF's document metadata.
#### Configuration Reference
| Parameter | Applies to | Description | Required | Example |
| --- | --- | --- | --- | --- |
| Document | All | The PDF to read or modify. Accepts a URL. | Yes | `{{node1.output.url}}` |
| Operation | All | Get or Set. | Yes | `Set` |
| Title | Set | Document title. | No | `Q3 Board Report` |
| Author | Set | Document author. | No | `Finance Team` |
| Subject | Set | Document subject. | No | `Quarterly Results` |
| Creator | Set | Creating application or person. | No | `Lamatic` |
| Keywords | Set | Search keywords for the document. | No | `finance, quarterly, board` |
#### Output
- **Get**: `metadata`, an object with the document's current title, author, subject, creator, and keywords. Works even on password-protected PDFs, since reading metadata doesn't require decrypting content.
- **Set**: `files`, an array with one entry: `{ url, key, pageCount }` for the updated document.
## Troubleshooting
### Common Issues
| Problem | Solution |
| --- | --- |
| Request rejected with a password/encryption error | The source PDF is password-protected. Remove the password before running the node, or use Get Metadata if you only need to read its metadata. |
| Base64 input rejected | This node only accepts document URLs. Upload the file first (for example, via a storage node) and pass its URL instead. |
| Annotations, form fields, or outlines missing after Extract, Insert, or a ranged Merge | Expected for these operations. If you need to preserve them, avoid page-range operations on the affected pages. |
| Split or Pages operation returns an error about page numbers | Confirm the page numbers or ranges you supplied exist in the source document, out-of-range pages are rejected rather than silently ignored. |
---
# Extract from File Node
Source: https://lamatic.ai/docs/nodes/data/extract-from-file-node.md
# Extract from File Node
## Overview
The Extract from File Node is a powerful data extraction component that can process and extract content from various file formats including PDFs, Word documents, text files, and more. This node enables users to convert unstructured file content into structured data for further processing.

## Features
**Key Functionalities**
1. **Multiple Format Support**: Handles CSV, JSON, Text, HTML, PDF, DOCX, and XLSX files with format-specific parsing options.
2. **Configurable Parsing**: Offers detailed configuration options for each file type to control how data is extracted and processed.
3. **Encoding Options**: Supports multiple file encodings including UTF-8, ASCII, and UTF-16LE for text-based formats.
4. **Data Transformation**: Provides options to clean and transform data during extraction (trimming, filtering, etc.).
5. **Base64 Encoding**: Supports encoding the extracted data as base64.
**Benefits**
1. **Versatility**: Single node solution for handling various file formats commonly used in data processing.
2. **Precision Control**: Fine-grained control over data extraction through format-specific configuration options.
3. **Data Quality**: Built-in options for data cleaning and validation during extraction.
4. **Seamless Integration**: Easy integration with other nodes in the workflow for comprehensive data processing.
## What Can I Build?
1. Data processing pipelines that handle multiple file formats
2. Automated document parsing systems
3. Data extraction flow for business intelligence
4. Content aggregation systems from various file sources
5. Extract data from files as base64 and use it in AI nodes
## Setup
### Select the Extract from File Node
1. Choose the appropriate operation for your file type
2. Configure format-specific parameters
3. Provide the file URL
4. Deploy and test the extraction
## Configuration Reference
### Common Parameters
| Parameter | Description | Required | Default |
| -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------- | -------- | ------------------- |
| nodeName | Name of the node instance | Yes | "Extract from File" |
| operation | Type of file to extract from | Yes | "extractFromCSV" |
| fileUrl(s) | URL or path to the file/Array of URLs | Yes | "" |
| format | file format | Yes | "auto" |
| encodeAsBase64 | encode the extracted data as base64 of structure: data:content-type;base64,encodedString. Eg: data:text/plain;base64,SW52YWxpZCBwYXJhbWV0ZXJzCg== | No | false |
### Format-Specific Parameters
**CSV Configuration**
| Parameter | Description | Required | Default |
| ---------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------- | ------- |
| delimiter | The delimiter that will separate columns, usually a comma | No | "," |
| headers | If selected than will return data as list of objects with keys as column names | No | true |
| quote | The character to use to quote fields that contain a \',\' delimiter. (e.g. "first,name",last name => ["first,name", "last name"]) | No | "\"" |
| ignoreEmpty | If true this will discard columns that are all white space or delimiters. | No | false |
| comment | If your CSV contains comments you can use this option to ignore lines that begin with the specified character (e.g. #) | No | null |
| discardUnmappedColumns | If you want to discard columns that do not map to a header. This is only valid in the case when the number of parsed columns is greater than the number of headers. | No | true |
| trim | Trim all white space from columns if true | No | false |
| rtrim | Right trim all columns if true | No | false |
| ltrim | Left trim all columns if true | No | false |
| maxRows | Maximum number of rows to parse. 0 means no limit | No | 0 |
| skipRows | Number of rows to skip at the beginning | No | 0 |
| encoding | Select the encoding of the file | No | "utf8" |
**JSON Configuration**
| Parameter | Description | Required | Default |
| --------- | ------------------------------- | -------- | ------- |
| encoding | Select the encoding of the file | No | "utf8" |
**Text Configuration**
| Parameter | Description | Required | Default |
| --------- | ------------------------------- | -------- | ------- |
| encoding | Select the encoding of the file | No | "utf8" |
**HTML Configuration**
| Parameter | Description | Required | Default |
| ------------- | ----------------------------------------------------- | -------- | ------- |
| returnRawText | Set to true to return the raw data instead of parsing | No | false |
**PDF Configuration**
| Parameter | Description | Required | Default |
| ----------- | ---------------------------------------------------------------------------------- | -------- | ------- |
| joinPages | Combine all pages into a single string | No | false |
| password(s) | Password/ Array of Passwords for the PDF file to try from, if the PDF is encrypted | No | "" |
**DOCX Configuration**
No additional config required
**Image Configuration**
No additional config required
**XLSX Configuration**
| Parameter | Description | Required | Default |
| ----------- | ------------------------------------------------------------------------------ | -------- | ------- |
| ignoreEmpty | Discard empty columns/rows | No | false |
| headers | If selected than will return data as list of objects with keys as column names | No | true |
**PDF to Image Configuration**
| Parameter | Description | Required | Default |
| ----------- | ---------------------------------------------------------------------------------------------------------------------------- | -------- | ------- |
| Password(s) | Password for the PDF file, if the PDF is encrypted. You can also send an array of passwords to try. Used for pdf file types. | No | false |
## Sample Input
```
File URL(s): ["https://calibre-ebook.com/downloads/demos/demo.docx","https://example-files.online-convert.com/document/txt/example.txt","https://sedl.org/afterschool/toolkits/science/pdf/ast_sci_data_tables_sample.pdf"]
Format: Auto Detect
Everything Else Default
```
## Low-Code Example
```yaml
nodes:
- nodeId: extractFromFileNode_983
nodeType: extractFromFileNode
nodeName: Extract from File
values:
trim: false
ltrim: false
quote: '"'
rtrim: false
comment: "null"
fileUrl: >-
["https://calibre-ebook.com/downloads/demos/demo.docx","https://example-files.online-convert.com/document/txt/example.txt","https://sedl.org/afterschool/toolkits/science/pdf/ast_sci_data_tables_sample.pdf"]
headers: true
maxRows: "0"
encoding: utf8
maxPages: "0"
password: ""
skipRows: "0"
delimiter: ","
joinPages: true
format: auto
skipLines: "0"
ignoreEmpty: false
returnRawText: false
discardUnmappedColumns: false
needs:
- triggerNode_1
```
## Output
### `files`
- An array of objects, each representing a file and its extracted content along with associated metadata.
### `metadata`
- A nested object containing descriptive attributes of the file.
- **`mime_type`**: Specifies the file's MIME type, indicating its format and encoding.
- **`type`**: Categorizes the file's general type.
- **`filename`**: The name of the file.
- **`extension`**: The file's extension.
- **`url`**: The source URL of the file.
- **`size`**: The file size in bytes, or `null` if not available.
- **`file_id`**: A unique identifier for the file within the processing context.
### `data`
- An array of strings containing the extracted content from the file.
### `additional_fields`
- A nested object containing supplementary data or metadata about file processing.
### `raw`
- An array of objects providing unprocessed or detailed extraction data.
- **`metadata`**: A nested object within `raw` detailing file format and creation metadata.
- **`format`**: The file's format version.
- **`title`**: The file's title.
- **`author`**: The file's author.
- **`subject`**: A description of the file's subject.
- **`keywords`**: Keywords associated with the file.
- **`creator`**: The software or tool used to create the file.
- **`producer`**: The software or library that produced the file.
- **`creationDate`**: The file's creation date.
- **`modDate`**: The file's last modification date.
- **`trapped`**: Related to PDF trapping status.
- **`encryption`**: Indicates the file's encryption status, or `null` if not encrypted.
### `file_path`
- A string specifying the temporary or local file path used during processing.
### `page_count`
- An integer indicating the total number of pages in the file.
### `page`
- An integer specifying the page number of the extracted content.
### `toc_items`
- An array containing the table of contents items.
### `tables`
- An array of objects describing tables extracted from the file.
- **`bbox`**: An array of coordinates defining the bounding box of a table.
- **`rows`**: The number of rows in a table.
- **`columns`**: The number of columns in a table.
### `images`
- An array of image data extracted from the file.
### `graphics`
- An array of graphic elements extracted from the file.
### `text`
- A string containing the raw text content extracted from a specific page or section.
### `words`
- An array of individual words extracted from the text.
### Example Output
```json
"files": [
{
"metadata": {
"mime_type": "application/vnd.openxmlformats-officedocument.wordprocessingml.document",
"type": "document",
"filename": "demo.docx",
"extension": "docx",
"url": "https://calibre-ebook.com/downloads/demos/demo.docx",
"size": 1311881,
"file_id": 0
},
"data": [
"data"
]
},
{
"metadata": {
"file_id": 1,
"type": "document",
"url": "https://example-files.online-convert.com/document/txt/example.txt",
"filename": "example.txt",
"extension": "txt",
"mime_type": "text/plain; charset=UTF-8",
"size": null
},
"data": [
"data"
]
}
]
```
## Troubleshooting
### Common Issues
| Problem | Solution |
| --------------- | --------------------------------------------------- |
| File Not Found | Verify the file URL is accessible and correct |
| Parsing Errors | Check file format matches selected operation |
| Encoding Issues | Try different encoding options for text-based files |
### Debugging
1. Check file accessibility
2. Verify file format matches operation
3. Review format-specific configuration
4. Check node logs for detailed error messages
---
# Hybrid Search Node
Source: https://lamatic.ai/docs/nodes/data/hybrid-search-node.md
# Hybrid Search Node
## Overview
The Hybrid Search Node is an advanced search component that combines multiple search strategies including semantic search, keyword search, and other retrieval methods to provide comprehensive and accurate results from vector databases.

## Features
**Key Functionalities**
1. **Hybrid Search Capability**: Combines text-based queries and vector database searches for precise and contextually relevant results.
1. **Dynamic Query Integration**: Supports dynamic input parameters (e.g., `{'{'}{'{'}}triggerNode_1.output.topic{'{'}{'}'}}`) to tailor search queries.
1. **Vector Database Support**: Integrates seamlessly with vector databases for advanced search and retrieval.
1. **Embedding Model Integration**: Leverages embedding models, such as Mistral API (`mistral-embed`), for enhanced semantic understanding.
1. **Customizable Boost Properties**: Includes options to adjust parameters like `Alpha` for fine-tuning search results.
**Benefits**
1. **Enhanced Precision**: Delivers accurate results by combining traditional search with semantic vector-based techniques.
1. **Flexibility**: Supports dynamic query generation and multiple embedding models, catering to diverse use cases.
1. **Scalability**: Works effectively with large-scale vector databases for high-performance search applications.
1. **Ease of Use**: Provides an intuitive interface for configuring search parameters, boosting usability for non-technical users.
1. **Optimized Results**: Allows fine-tuning with boost properties like `Alpha` to balance relevance and diversity in outputs.
## What Can I Build?
1. Create a dynamic search interface within your application to query a vector database.
1. Develop a personalized recommendation system using text and vector based search results.
1. Integrate real-time search capabilities to enhance user experience in your app.
## Setup
### Select the Hybrid Search Node
1. Fill in the required parameters.
1. Build the desired flow
1. Deploy the Project
1. Click Setup on the workflow editor to get the automatically generated instruction and add it in your application.
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| --------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------- |
| **Search Query** | Input the query to search the vector database. | Tell me something about Bali |
| **Vector DB** | Select the vector database to be queried. | Database |
| **Embedding Model Name** | This field allows the user to select the embedding model used to embed the query into vector space. It loads available embedding models through the listModels method. | Embedding Model Name |
| **Boost Properties** | Specific properties can be boosted by a factor specified as a number | True/False |
| **Alpha** | Hybrid search results can favor the keyword component or the vector component. To change the relative weights of the keyword and vector components, set the alpha value in your query.Hybrid search results can favor the keyword component or the vector component. To change the relative weights of the keyword and vector components, set the alpha value in your query. | 0.25 |
| **Certainty** | It's the distance score into a value between 0 <= certainty <= 1, where 1 would represent identical vectors and 0 would represent opposite vectors. | 0.7 |
| **Limit** | Number of results to return. Set to `0` to return all records. | 3 |
| **Group Similar Distance upto N Jumps** | Automatically groups and limits search results by detecting significant gaps in similarity scores. When N > 0, the function will include results until it finds N large differences in scores between consecutive results. This helps filter out less relevant results that are notably different from the top matches. | 0 |
| **Fusion Type** | This field allows the user to select the fusion type used to combine the keyword and vector search results. | Relative/Ranked |
| **Filters** | Apply JSON-based filters to refine search results. | [] |
## Low-Code Example
```yaml
nodes:
- nodeId: hybridSearchNode_217
nodeType: hybridSearchNode
nodeName: Hybrid Search
values:
searchQuery: "Tell me something about {{triggerNode_1.output.topic}}"
vectorDB: ""
alpha: "0.25"
certainty: "0.85"
limit: "3"
autocut: "0"
fusionType: relativeScoreFusion
boostProperties: false
filters: "[]"
embeddingModelName:
provider_name: mistral
type: embedder/text
credential_name: Mistral API
credentialId: 32bf5e3b-a8fc-4697-b95a-b1af3dcf7498
model_name: mistral/mistral-embed
needs:
- triggerNode_1
- nodeId: plus-node-addNode_378459
nodeType: addNode
nodeName: ""
values: {}
needs:
- hybridSearchNode_217
```
## Output
### `searchResults`
- An array of objects, each representing a search result with its associated data and scoring information.
- **`_additional`**: Contains extra metadata about the search result.
- **`score`**: A string indicating the relevance or confidence score of the result, as provided in the additional metadata.
- **`data`**: A string containing the content or information retrieved for the search result.
- **`score`** (duplicate at the top level): Same as the one inside `_additional`.
### Example Output
```json
{
"searchResults": [
{
"_additional": {
"score": "0.25"
},
"data": "info",
"score": "0.25"
}
]
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ------------------------------------------------------------ |
| **Invalid API Key** | Ensure the API key is correct and has not expired. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# Keyword Search Node
Source: https://lamatic.ai/docs/nodes/data/keyword-search-node.md
# Keyword Search Node
## Overview
The Keyword Search Node is a search component that performs text-based searches using specific keywords and phrases. This node enables users to find relevant content based on exact keyword matches and text patterns.

## Features
**Key Functionalities**
1. **Dynamic Search Query Input**: Allows for customizable search queries using dynamic placeholders like `{{triggerNode_1.output.topic}}`.
2. **Vector Database Selection**: Provides an option to select a specific vector database for efficient retrieval of information.
3. **Boost Properties**: Enables users to prioritize specific attributes for search results by activating the boost properties option.
4. **Result Limitation**: Allows limiting the number of search results returned with a configurable limit.
5. **Grouping of Similar Results**: Supports grouping similar search results based on configurable distance thresholds.
6. **Filters Integration**: Lets users apply filters for more refined search results.
**Benefits**
1. **Customizability**: Dynamic query capabilities ensure search inputs can adapt to varying flow and datasets.
2. **Relevance**: Boost properties and grouping enhance the quality of search results, ensuring higher relevance.
3. **Scalability**: Seamless integration with vector databases supports large-scale and complex applications.
4. **Efficiency**: Configurable limits and filters save resources by optimizing the retrieval process.
## What Can I Build?
1. Create a dynamic search interface within your application to query a vector database.
2. Develop a personalized recommendation system by combining keyword search and vector-based similarity.
3. Build real-time search capabilities with grouped and filtered results for enhanced user experience.
## Setup
### Select the Keyword Search Node
1. Fill in the required parameters.
1. Build the desired flow
1. Deploy the Project
1. Click Setup on the workflow editor to get the automatically generated instruction and add it in your application.
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| --------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------- |
| **Search Query** | Input the query to search the vector database. | Tell me something about Bali |
| **Vector DB** | Select the vector database to be queried. | Database |
| **Boost Properties** | Specific properties can be boosted by a factor specified as a number | True/False |
| **Limit** | Number of results to return. Set to `0` to return all records. | 3 |
| **Group Similar Distance upto N Jumps** | Automatically groups and limits search results by detecting significant gaps in similarity scores. When N > 0, the function will include results until it finds N large differences in scores between consecutive results. This helps filter out less relevant results that are notably different from the top matches. | 0 |
| **Filters** | Apply JSON-based filters to refine search results. | [] |
## Low-Code Example
```yaml
nodes:
nodes:
- nodeId: fullTextSearchNode_335
nodeType: fullTextSearchNode
nodeName: Keyword Search
values:
searchQuery: '{{triggerNode_1.output.topic}}'
vectorDB: ''
limit: '3'
boostProperties: false
autocut: '0'
filters: ''
needs:
- triggerNode_1
```
## Output
- `searchResults`: An array of objects representing the results of the keyword search.
### Example Output
```json
{
"searchResults": []
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ------------------------------------------------------------ |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# Memory Add Node
Source: https://lamatic.ai/docs/nodes/data/memory-add-node.md
# Memory Add Node
## Overview
The Memory Add Node is a data storage component that stores and manages information in memory for use across workflow executions. This node enables persistent data storage and retrieval within workflows.

## Features
**Key Functionalities**
1. **Persistent Storage**: Store and manage contextual information that persists across workflow executions.
2. **User & Session Management**: Support for both user-level and session-specific memory storage with unique identifiers.
3. **Metadata Support**: Attach additional metadata to stored memories.
**Benefits**
1. **Persistence:** Maintain contextual information across multiple workflow executions.
2. **Scalability:** Efficiently store and retrieve large amounts of contextual data.
3. **Flexibility:** Support for both user-level and session-level memory storage.
## What Can I Build?
1. Chatbots that remember conversation history and user preferences.
2. Personalized recommendation systems based on user interactions.
3. Knowledge management systems with contextual information retrieval.
## Setup
### Configure the Memory Node
1. Select the Memory Add Node in your workflow.
2. Configure the unique user identifier.
3. Choose or create a memory collection.
4. Set up the embedding and generative models.
5. Define optional session ID and metadata.
6. Add the Memory Value
7. Deploy the project.
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| ------------------------- | ---------------------------------------------------------------------- | -------------------------------------- |
| **Unique Id** | Identifier for the user whose memory is being stored | `29fcd52e-0813-4fa2-821c-1428a05636ba` |
| **Session Id** | Optional identifier for specific user sessions | `2 (Defaults to Global)` |
| **Memory Store** | The collection where memories will be stored | `MemoryStore` |
| **Memory Value** | The actual data from which facts to be retrieved and updated in memory | `I like cats` |
| **Embedding Model Name** | Model used for converting text to vectors | `text-embedding-ada-002` |
| **Generative Model Name** | Model used for processing stored information | `gpt-3.5-turbo` |
| **Metadata** | Additional JSON data to store with the memory | `{"source": "chat"}` |
## Low-Code Example
```json
- nodeId: memoryNode_858
nodeType: memoryNode
nodeName: Memory Add
values:
uniqueId: '{{triggerNode_1.output.userId}}'
sessionId: ''
memoryValue:
- role: user
content: User likes to watch Pokemon
memoryCollection: finalTest
embeddingModelName:
type: embedder/text
model_name: default
credentialId: some-id
provider_name: openai
credential_name: NEW PROVIDER
generativeModelName:
type: generator/text
model_name: default
credentialId: Some Credential Id
provider_name: openai
credential_name: Testing OpenAI
```
## Output
-`memoryActions`: An array of objects representing actions or operations performed on the memory, which may be empty if no actions are recorded.
-`extractedFacts`: An array of strings containing facts or insights derived from the input data and added to the memory.
### Example Output
```json
{
"memoryActions": [],
"extractedFacts": [
"User expressed a positive opinion about lamatic."
]
}
```
## Common Issues and Debugging
1. **Memory Not Being Stored**
- Verify the Unique Id is properly configured and not empty
- Check that the Memory Collection name matches exactly across nodes
- Ensure the Memory Value contains valid content.
- Confirm the embedding model is accessible and running
### Troubleshooting Steps
1. **Check Node Configuration**
- Verify all required fields are filled
2. **Monitor Workflow Logs**
- Look for error messages in the execution logs
- Check for timeout or rate limit errors
3. **Test Memory Operations**
- Use the workflow testing feature to verify storage
- Confirm immediate retrieval after storage
- Test with simple data before complex implementations
---
# Memory Retrieve Node
Source: https://lamatic.ai/docs/nodes/data/memory-retrieve-node.md
# Memory Retrieve Node
## Overview
The Memory Retrieve Node is a data retrieval component that fetches stored information from memory for use in current workflow executions. This node enables access to previously stored data and context.

## Features
**Key Functionalities**
1. **Memories Search**: Search memories using natural language queries.
2. **Filtering**: Apply filters to refine search results and restrict them to particular uniqueId and sessionId.
3. **Configurable Results**: Control the number of memories returned.
**Benefits**
1. **Contextual Retrieval:** Access relevant memories based on similarity.
2. **Precision:** Fine-tune results using filters.
3. **Flexibility:** Support for both raw and processed memory formats, allowing the retrieved memory to be passed directly to any AI Node.
## What Can I Build?
1. AI Nodes that can reference past memories for context-aware responses.
2. Knowledge bases with natual language querying capabilities.
3. Personalized recommendation systems based on user's memories.
## Setup
### Configure the Memory Retrieve Node
1. Select the Memory Retrieve Node in your workflow.
2. Define your search query.
3. Choose the memory collection to search.
4. Configure the embedding model.
5. Set optional filters and result limits.
6. Deploy the project.
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| ------------------------ | ------------------------------------------------- | ---------------------------------------- |
| **Search Query** | The natural language query to search memories | `What are the user's preferences?` |
| **Memory Store** | The collection to search for memories | `MemoryStore` |
| **Embedding Model Name** | Model used for converting search query to vectors | `text-embedding-ada-002` |
| **Limit** | Maximum number of memories to return | `3` |
| **Filters** | JSON-based filters to refine search results | 'Set them up using UI condition builder' |
## Filter Memory Retrieval

To Apply the Filter in Memory Retrieve Node, Click on the Filters
1. Here you can apply condition on
1. Session Id
1. Meta Data
1. Timestamp
1. Memory
1. Unique Id

## Output Formats
The node provides two output formats:

1. **Memories**: Processed memory objects ready for use in any AI Node
2. **Raw Memories**: Unprocessed memory data including metadata and embeddings
## Low-Code Example
```json
- nodeId: memoryRetrieveNode_951
nodeType: memoryRetrieveNode
nodeName: Memory Retrieve
values:
limit: '3'
filters: |-
{
"operator": "And",
"operands": [
{
"path": [
"uniqueId"
],
"operator": "Equal",
"valueText": "{{triggerNode_1.output.userId}}"
}
]
}
searchQuery: User likes what
memoryCollection: NewMemory
embeddingModelName:
type: embedder/text
model_name: default
credentialId: some id
provider_name: openai
credential_name: NEW PROVIDER
needs:
- memoryNode_858
```
## Output
-`rawMemories`: An array of objects representing unprocessed or original memory data retrieved from storage.
-`memories`: An array of objects containing processed or formatted memory data retrieved based on the node's query or criteria.
### Example Output
```json
{
"rawMemories": [],
"memories": []
}
```
## Using Retrieved Memory in AI Nodes
In the respective AI Node, add memories under Memories inside Additional Properties by clicking the Plus icon.

## Common Issues and Debugging
1. **Memory Not Being Retrieved**
- Verify you're using the same Unique Id used during storage
- Check if the Session Id matches (if using session-specific storage)
- Ensure the Memory Collection name is consistent between add and retrieve nodes
- Validate that the embedding model dimensions match between storage and retrieval
2. **Incorrect Results**
- Verify the search query is properly formatted
- Check if filters are correctly configured
- Ensure the limit parameter is set appropriately
- Test with simpler queries first to isolate issues
### Troubleshooting Steps
1. **Check Node Configuration**
- Verify all required fields are filled
- Ensure model names are spelled correctly
- Validate JSON format in metadata field
2. **Monitor Workflow Logs**
- Look for error messages in the execution logs
- Check for timeout or rate limit errors
- Verify successful model API calls
3. **Test Memory Operations**
- Use the workflow testing feature to verify storage
- Confirm immediate retrieval after storage
- Test with simple data before complex implementations
---
# Tables Node
Source: https://lamatic.ai/docs/nodes/data/tables-node.md
# Tables Node(Beta)
## Overview
The Tables Node is a structured data management component that performs various operations on relational data tables, including querying, inserting, updating, and deleting records. This node provides full CRUD control over your Lamatic Data Tables directly within a flow.
The Tables Node uses **SQLite** as its underlying database engine.

## Features
Key Functionalities
1. **Multi-Action Capability**: Choose between Select, Insert, Update, Delete, or raw SQL Query operations.
2. **Visual Where Clause Builder**: Add filter conditions without writing SQL using the condition builder.
3. **Flexible Column Selection**: Choose all columns (`SELECT *`) or limit to specific fields.
4. **Sorting & Pagination**: Control result order with Order By, and paginate using Limit and Offset.
5. **Raw SQL Support**: Run custom SQL queries directly for advanced use cases.
Benefits
1. **Simplicity**: Manage structured data without leaving the flow editor.
2. **Control**: Fine-tune reads and writes with filters, ordering, and pagination.
3. **Flexibility**: Use the visual builder for common operations or raw SQL for complex queries.
4. **Integration**: Combine with AI nodes to build data-driven pipelines and automations.
## What Can I Build?
- Store user inputs or API responses into a table from a flow.
- Query records to personalise AI responses with real data.
- Update or delete table records based on flow logic or conditions.
- Build admin-style data workflows with full CRUD capability.
---
## Setup
### 1. Select Action
Retrieves rows from a table based on optional column selection, filters, ordering, and pagination.
#### Configuration Reference
| **Parameter** | **Description** | **Required** | **Example Value** |
| ---------------- | ----------------------------------------------------------------- | ------------ | ------------------- |
| **Action** | The action to perform on the table. | Yes | `Select` |
| **Table** | The target table to query. | Yes | `users` |
| **Columns** | Columns to return. Defaults to all (`SELECT *`). | No | `id, name, email` |
| **Where Clause** | Filter conditions to narrow results. Add one or more conditions. | No | `status = 'active'` |
| **Order By** | Column(s) to sort results by, with direction (ASC/DESC). | No | `created_at DESC` |
| **Limit** | Maximum number of rows to return. Defaults to `10`. | No | `10` |
| **Offset** | Number of rows to skip before returning results. Defaults to `0`. | No | `0` |
#### Low-Code Example
```yaml
nodeName: Tables
action: select
tableName: Tables
columns:
- id
- created_at
data: '{}'
where:
conjunction: AND
conditions:
- column: id
operator: '='
value: '1'
orderBy:
- column: ''
order: ASC
limit: '10'
offset: '0'
query: SELECT * FROM your_table WHERE id = ?
```
#### Output
- `rows`: An array of records matching the query criteria.
- `count`: The number of records returned.
##### Example Output
```json
{
"rows": [
{ "id": 1, "name": "Alice", "email": "alice@example.com" },
{ "id": 2, "name": "Bob", "email": "bob@example.com" }
],
"count": 2
}
```
### 2. Insert Action
Inserts one or more new records into the specified table.
#### Configuration Reference
| **Parameter** | **Description** | **Required** | **Example Value** |
| ------------- | -------------------------------------------------------- | ------------ | ------------------------------- |
| **Action** | Set to `Insert`. | Yes | `Insert` |
| **Data** | The record(s) to insert. Accepts a JSON object or array. | Yes | `{{triggerNode_1.output.body}}` |
| **Table** | The target table to insert into. | Yes | `users` |
#### Low-Code Example
```yaml
nodeName: Tables
action: insert
tableName: Tables
columns:
- id
- created_at
data: '{"id": "{{triggerNode_1.output.id}}"}'
where:
conjunction: AND
conditions:
- column: id
operator: '='
value: '1'
orderBy:
- column: ''
order: ASC
limit: '10'
offset: '0'
query: SELECT * FROM your_table WHERE id = ?
```
#### Output
- `insertedCount`: Number of records successfully inserted.
- `message`: A status message summarising the operation.
##### Example Output
```json
{
"insertedCount": 1,
"message": "Record inserted successfully"
}
```
### 3. Update Action
Updates existing records in a table that match the specified where clause.
#### Configuration Reference
| **Parameter** | **Description** | **Required** | **Example Value** |
| ---------------- | ------------------------------------------------------- | ------------ | ------------------------------- |
| **Action** | Set to `Update`. | Yes | `Update` |
| **Data** | The fields and values to update. Accepts a JSON object. | Yes | `{{triggerNode_1.output.body}}` |
| **Table** | The target table to update. | Yes | `users` |
| **Where Clause** | Filter conditions to identify which records to update. | Yes | `id = 1` |
#### Low-Code Example
```yaml
nodeName: Tables
action: update
tableName: Tables
columns:
- id
- created_at
data: '{"id": "{{triggerNode_1.output.id}}"}'
where:
conjunction: AND
conditions:
- column: id
operator: '='
value: '1'
orderBy:
- column: ''
order: ASC
limit: '10'
offset: '0'
query: SELECT * FROM your_table WHERE id = ?
```
#### Output
- `updatedCount`: Number of records successfully updated.
- `message`: A status message summarising the operation.
##### Example Output
```json
{
"updatedCount": 1,
"message": "Record updated successfully"
}
```
### 4. Delete Action
Deletes records from a table that match the specified where clause.
#### Configuration Reference
| **Parameter** | **Description** | **Required** | **Example Value** |
| ---------------- | ------------------------------------------------------ | ------------ | ----------------- |
| **Action** | Set to `Delete`. | Yes | `Delete` |
| **Table** | The target table to delete records from. | Yes | `users` |
| **Where Clause** | Filter conditions to identify which records to delete. | Yes | `id = 1` |
#### Low-Code Example
```yaml
nodeName: Tables
action: delete
tableName: Tables
columns:
- id
- created_at
data: '{{triggerNode_1.output.sampleInput}}'
where:
conjunction: AND
conditions:
- column: id
operator: '='
value: '1'
orderBy:
- column: ''
order: ASC
limit: '10'
offset: '0'
query: SELECT * FROM your_table WHERE id = ?
```
#### Output
- `deletedCount`: Number of records successfully deleted.
- `message`: A status message summarising the operation.
##### Example Output
```json
{
"deletedCount": 1,
"message": "Record deleted successfully"
}
```
### 5. Query Action
Executes a raw SQL query for advanced or complex operations not covered by the visual builder.
#### Configuration Reference
| **Parameter** | **Description** | **Required** | **Example Value** |
| ------------- | -------------------------------------------------------------------- | ------------ | --------------------------------------- |
| **Action** | Set to `Query`. | Yes | `Query` |
| **SQL Query** | A raw SQL statement to execute. Use `?` as a placeholder for values. | Yes | `SELECT * FROM your_table WHERE id = ?` |
#### Low-Code Example
```yaml
nodeName: Tables
action: query
tableName: Tables
columns:
- id
- created_at
data: '{{triggerNode_1.output.sampleInput}}'
where:
conjunction: AND
conditions:
- column: id
operator: '='
value: '1'
orderBy:
- column: ''
order: ASC
limit: '10'
offset: '0'
query: SELECT * FROM your_table WHERE id = 1
```
#### Output
- `rows`: An array of records returned by the query.
- `count`: The number of records returned.
##### Example Output
```json
{
"rows": [
{ "id": 1, "name": "Alice", "email": "alice@example.com" }
],
"count": 1
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ----------------------------- | ------------------------------------------------------------------------------- |
| **No table appears in list** | Click the refresh icon next to the Table field to reload available tables. |
| **Where Clause not working** | Ensure a table is selected first; conditions can only be added after selection. |
| **Insert fails with no data** | Verify the `Data` field contains a valid JSON object or array. |
| **Query returns no results** | Check your SQL syntax and confirm the table name and column names are correct. |
| **Columns field greyed out** | Select a table first; column selection is only available after table selection. |
---
# Keyword Search Node
Source: https://lamatic.ai/docs/nodes/data/vector-search-node.md
# Keyword Search Node
## Overview
The Keyword Search Node is a search component that performs text-based searches using specific keywords and phrases. This node enables users to find relevant content based on exact keyword matches and text patterns.

## Features
**Key Functionalities**
1. **Dynamic Search Query Input**: Allows for customizable search queries using dynamic placeholders like `{{triggerNode_1.output.topic}}`.
2. **Vector Database Selection**: Provides an option to select a specific vector database for efficient retrieval of information.
3. **Boost Properties**: Enables users to prioritize specific attributes for search results by activating the boost properties option.
4. **Result Limitation**: Allows limiting the number of search results returned with a configurable limit.
5. **Grouping of Similar Results**: Supports grouping similar search results based on configurable distance thresholds.
6. **Filters Integration**: Lets users apply filters for more refined search results.
**Benefits**
1. **Customizability**: Dynamic query capabilities ensure search inputs can adapt to varying flow and datasets.
2. **Relevance**: Boost properties and grouping enhance the quality of search results, ensuring higher relevance.
3. **Scalability**: Seamless integration with vector databases supports large-scale and complex applications.
4. **Efficiency**: Configurable limits and filters save resources by optimizing the retrieval process.
## What Can I Build?
1. Create a dynamic search interface within your application to query a vector database.
2. Develop a personalized recommendation system by combining keyword search and vector-based similarity.
3. Build real-time search capabilities with grouped and filtered results for enhanced user experience.
## Setup
### Select the Keyword Search Node
1. Fill in the required parameters.
1. Build the desired flow
1. Deploy the Project
1. Click Setup on the workflow editor to get the automatically generated instruction and add it in your application.
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| --------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------- |
| **Search Query** | Input the query to search the vector database. | Tell me something about Bali |
| **Vector DB** | Select the vector database to be queried. | Database |
| **Boost Properties** | Specific properties can be boosted by a factor specified as a number | True/False |
| **Limit** | Number of results to return. Set to `0` to return all records. | 3 |
| **Group Similar Distance upto N Jumps** | Automatically groups and limits search results by detecting significant gaps in similarity scores. When N > 0, the function will include results until it finds N large differences in scores between consecutive results. This helps filter out less relevant results that are notably different from the top matches. | 0 |
| **Filters** | Apply JSON-based filters to refine search results. | [] |
## Low-Code Example
```yaml
nodes:
nodes:
- nodeId: fullTextSearchNode_335
nodeType: fullTextSearchNode
nodeName: Keyword Search
values:
searchQuery: '{{triggerNode_1.output.topic}}'
vectorDB: ''
limit: '3'
boostProperties: false
autocut: '0'
filters: ''
needs:
- triggerNode_1
```
## Output
- `searchResults`: An array of objects representing the results of the keyword search.
### Example Output
```json
{
"searchResults": []
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ------------------------------------------------------------ |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# VectorDB Node
Source: https://lamatic.ai/docs/nodes/data/vectordb-node.md
# VectorDB Node
## Overview
The VectorDB Node is a comprehensive vector database management component that performs various operations including insertion, deletion, updating, and management of vector data. This node provides full control over vector database operations.

## Features
Key Functionalities
1. **Multi-Action Capability**: Choose between indexing, filtering, or deleting records in a vector DB.
2. **Conditional Filtering**: Apply advanced JSON filters with logical operators (`And`, `Or`, etc.).
3. **Primary Key Matching**: Use custom primary keys to uniquely identify or filter/delete entries.
4. **Duplicate Handling**: Choose to `overwrite` or `skip` on indexing conflicts.
Benefits
1. **Flexibility**: Handle multiple vector operations within one node.
2. **Control**: Fine-tune data updates with filters and duplication settings.
3. **Efficiency**: Manage large vector datasets with scalable indexing and deletion.
4. **Search Precision**: Use rich metadata and filters to retrieve exactly what's needed.
## What Can I Build?
- Automate document indexing pipelines.
- Build search interfaces with filterable vector data.
- Clean up or update vector DBs programmatically.
---
## Setup
### 1. Index Action
Indexes vectors and metadata into the selected vector database.
#### Configuration Reference
| **Parameter** | **Description** | **Required** | **Example Value** |
| ----------------------- | ---------------------------------------------------------------------- | ------------ | --------------------------------- |
| **Vector DB** | Select the vector database where the vectors will be indexed. | Yes | `database` |
| **Vectors** | Enter the vector data to be indexed in the database. | Yes | `{{codeNode_540.output.vectors}}` |
| **Metadata** | Include additional information to enhance vector search and retrieval. | Yes | `{{codeNode_540.output.vectors}}` |
| **Primary Keys (JSON)** | Provide unique identifiers for each vector in JSON format. | Yes | [] |
| **Duplication Records** | Manage duplicates by choosing to `overwrite` or `skip` them. | No | `overwrite` |
#### Low-Code Example
```yaml
- nodeId: IndexNode_543
nodeType: IndexNode
nodeName: Index to DB
values:
vectorDB: IndexCrawler
webhookURL: https://webhook.site/685a66e7-b4d3-40a4-9801-99e3460414f9
primaryKeys: ''
vectorsField: '{{codeNode_540.output.vectors}}'
metadataField: '{{codeNode_540.output.metadata}}'
duplicateOperation: overwrite
embeddingModelName: {}
generativeModelName:
type: embedder/text
nodeId: IndexNode
model_name: text-embedding-ada-002
provider_name: openai
needs:
- codeNode_540
```
#### Output
- `recordsIndexed`: An integer indicating the number of records successfully indexed.
- `duplicateRecordsDeleted`: An integer representing the number of duplicate records removed during the indexing process.
- `message`: A string providing a status or summary of the indexing operation.
##### Example Output
```json
{
"recordsIndexed": 1,
"duplicateRecordsDeleted": 0,
"message": "Data indexed successfully"
}
```
### 2. Filter Action
Filters indexed records using metadata and/or vector queries.
#### Configuration Reference
| **Parameter** | **Description** | **Required** | **Example** |
| ------------- | -------------------------------------------------- | ------------ | ----------- |
| **vectorDB** | Target vector database | Yes | `CallData` |
| **action** | Must be set to `filter` | Yes | `filter` |
| **filters** | JSON filter using logical operators and conditions | Yes | See below |
| **limit** | Number of results to return. Set to `0` to return all records. | No | `20` |
#### Example
```yaml
- nodeId: vectorNode_2
nodeType: vectorNode
nodeName: VectorDB
values:
vectorDB: CallData
action: filter
vectorsField: "[]"
metadataField: "[]"
primaryKeys: ["topic"]
duplicateOperation: overwrite
filters: |-
{
"operator": "And",
"operands": [
{
"path": ["topic"],
"operator": "Equal",
"valueText": "Topic1"
}
]
}
limit: 20
```
#### Output
- `success`: A boolean indicating if the filter operation was successful.
- `data`: An array of records matching the filter criteria.
- `count`: The number of records returned by the filter operation.
##### Example Output
```json
{
"success": true,
"data": [
{
"title": "Lamatic Docs",
"content": "Welcome to the Lamatic documentation!"
}
],
"count": 1
}
```
### 3. Delete Action
Deletes records matching filter criteria.
#### Configuration Reference
| **Parameter** | **Description** | **Required** | **Example** |
| --------------- | -------------------------------------------------- | ------------ | ----------- |
| **vectorDB** | Target vector database | Yes | `CallData` |
| **action** | Must be set to `delete` | Yes | `delete` |
| **filters** | JSON filter for selecting items to delete | Yes | See below |
| **primaryKeys** | Optional fields used to match entries for deletion | No | `["topic"]` |
#### Example
```yaml
- nodeId: vectorNode_3
nodeType: vectorNode
nodeName: VectorDB
values:
vectorDB: CallData
action: delete
vectorsField: "[]"
metadataField: "[]"
primaryKeys: ["topic"]
duplicateOperation: overwrite
filters: |-
{
"operator": "And",
"operands": [
{
"path": ["topic"],
"operator": "Equal",
"valueText": "Topic1"
}
]
}
limit: 20
needs:
- triggerNode_1
```
#### Output
- `deletedCount`: Number of records successfully deleted.
- `matches`: Number of records that matched the filter criteria.
- `failed`: Number of records that failed to delete.
##### Example Output
```json
{
"deletedCount": 2,
"matches": 2,
"failed": 0
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------- | -------------------------------------------------------------------- |
| **Invalid Vector DB** | Ensure the database name exists and is spelled correctly. |
| **Missing Embeddings** | Make sure vectors are provided or an embedding model is configured. |
| **Misconfigured Filters** | Ensure filters use valid JSON and correct field paths and operators. |
| **Primary Key Conflicts** | Resolve using `overwrite` or `skip` options for handling duplicates. |
---
# Vectorize Node
Source: https://lamatic.ai/docs/nodes/data/vectorize-node.md
# Vectorize Node
## Overview
The Vectorize Node is a data transformation component that converts text data into vector embeddings. These embeddings enable semantic search, similarity comparisons, and other AI-powered applications that require numerical representations of text.
## Features
**Key Functionalities**
1. **Custom Embedding Model Selection:** Choose from a variety of embedding models to fit your application's needs.
1. **Parameter Configuration:** Fine-tune embedding parameters for optimal performance and relevance.
1. **Efficient Vectorization:** Quickly convert large volumes of text data into numeric vector representations.
1. **Semantic Retrieval Compatibility:** Enable advanced search and comparison functionalities using semantic understanding.
1. **Scalable Processing:** Handle massive datasets effectively, ensuring seamless vectorization at scale.
**Benefits**
1. **Enhanced Data Analysis:** Leverage semantic vectors to improve search and analysis capabilities.
1. **Streamlined Integration:** Easily incorporate vectorized data into downstream applications and flow.
1. **Improved Accuracy:** Benefit from state-of-the-art embedding models for precise semantic representation.
1. **Operational Flexibility:** Configure and adapt vectorization settings to meet evolving requirements.
1. **Future-Proof Design:** Stay compatible with the latest embedding technologies and methodologies.
## What Can I Build?
1. Build advanced search engines that can understand and retrieve information based on semantic meaning rather than keywords.
1. Create recommendation systems that provide more accurate suggestions by understanding the context and meaning of user preferences.
1. Develop chatbots and virtual assistants that can comprehend and respond to user queries with greater relevance and understanding.
1. Implement content categorization and organization systems that can automatically classify and sort large volumes of text data.
## Setup
### Select the Vectorize Node
1. Fill in the required parameters.
1. Build the desired flow
1. Deploy the Project
1. Click Setup on the workflow editor to get the automatically generated instruction and add it in your application.
## Configuration Reference
| **Parameter** | **Description** | **Required** | **Example Value** |
| ------------------------ | ------------------------------------------------------------------ | ------------ | ------------------------ |
| **Texts to vectorize** | Enter the texts to be transformed into vectors. | Yes | `${{data}}` |
| **Embedding Model Name** | Select the model to convert the texts into vector representations. | Yes | `text-embedding-3-large` |
## Low-Code Example
```yaml
- nodeId: vectorizeNode_448
nodeType: vectorizeNode
nodeName: Get Vectors
values:
inputText: "{{codeNode_234.output}}"
embeddingModelName: {}
generativeModelName:
type: embedder/text
nodeId: vectorizeNode
model_name: text-embedding-ada-002
provider_name: openai
```
## Output
- `vectors`: An array of arrays, each containing numerical values representing the vectorized form of the input data.
### Example Output
```json
{
"vectors": [
[
-0.010908611,
-0.013849079,
-0.0080731595,
-0.03575819,
-0.004489464,
]
]
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ------------------------------------------------------------ |
| **Invalid API Key** | Ensure the API key is correct and has not expired. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# Batch Node
Source: https://lamatic.ai/docs/nodes/logic/batch-node.md
# Batch Node
## Overview
The Batch Node is similar to the Loop (for loop) Node: it iterates over a **List** or a **Range**. The key difference is that Batch runs iterations **in parallel**, and you can control throughput using a **Concurrency Limit**.
Use Batch when you want faster processing (parallelism). Use Loop when you need strict ordering or sequential dependencies between iterations.
## Features
**Key Functionalities**
1. **Range-based batching:** Iterate over numeric ranges using initial, end, and increment values.
2. **List-based batching:** Iterate over arrays/collections for flexible parallel processing.
3. **Concurrency control:** Cap parallel executions with a concurrency limit (1–50) to protect rate limits and downstream systems.
**Benefits**
1. **Higher throughput:** Process items faster by running multiple iterations at once.
2. **Safer scaling:** Control load using concurrency limits instead of “all at once”.
3. **Flexible iteration:** Works with both structured lists and numeric ranges.
## What Can I Build?
1. **Parallel web/page processing:** Run multiple scrapes or fetches concurrently.
2. **Fan-out API calls:** Enrich many records by calling a third-party API with controlled concurrency.
3. **Batch content generation:** Generate summaries/embeddings for many inputs in parallel while staying under model or token rate limits.
## Setup
1. Add the **Batch Node** to your flow.
1. Choose **Iterate Over** as `List` or `Range`.
1. Configure the required fields (marked with *).
1. Set a **Concurrency Limit** based on your downstream limits (API rate limits, model throughput, etc.).
1. Deploy the project.
## Configuration Reference
| **Parameter** | **Required** | **Description** | **Example Value** |
| --- | --- | --- | --- |
| **Iterate Over** | Yes | Select `List` or `Range`. If `List`, provide the list/array to iterate over. | `{{triggerNode_1.output.urls}}` or `Range` |
| **Initial Value** | Yes | Starting value of the batch range. | `0` |
| **End Value** | Yes | Ending value of the batch range (exclusive). | `10` |
| **Increment** | Yes | Step size for each iteration. | `1` |
| **Concurrency Limit** | Yes | Maximum number of parallel executions (min: 1, max: 50). | `10` |
## Low-Code Example
### Iterate over a list (parallel)
```yaml
nodes:
- nodeId: batchNode_692
nodeType: batchNode
nodeName: Batch
values:
endValue: 10
increment: 1
connectedTo: batchEndNode_757
iterateOver: list
initialValue: '1'
iteratorValue: '[]'
concurrencyLimit: '2'
modes: {}
```
### Iterate over a range (parallel)
```yaml
nodes:
- nodeId: batchNode_692
nodeType: batchNode
nodeName: Batch
values:
endValue: 10
increment: 1
connectedTo: batchEndNode_757
iterateOver: range
initialValue: '1'
iteratorValue: '[]'
concurrencyLimit: '2'
modes: {}
```
## Output
The output from the Batch Node is an array containing the outcome of each iteration.
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| --- | --- |
| **Rate limit / 429 errors** | Lower **Concurrency Limit** and/or add retry/backoff downstream. |
| **Downstream overload (timeouts, failures)** | Reduce concurrency, or batch into smaller lists/ranges. |
| **Unexpected iteration values** | Double-check `Initial Value`, `End Value` (exclusive), and `Increment` (step). |
### Debugging Tips
- Start with a low concurrency (e.g., `2–5`) and increase gradually.
- Use flow logs to identify which iteration(s) fail and why.
- If you’re batching API calls, align concurrency with the API’s published limits.
By leveraging the Lamatic.ai Batch Node, you can process lists and ranges quickly while keeping resource usage controlled.
---
# Branch Node
Source: https://lamatic.ai/docs/nodes/logic/branch-node.md
# Branch Node
## Overview
The Branch Node is a workflow control component that creates multiple execution paths based on conditions or data routing logic. This node enables complex workflow branching and parallel processing of different data streams.

## Features
**Key Functionalities**
1. **Parallel Execution:** Execute multiple tasks simultaneously, improving efficiency and reducing processing time.
2. **Flexible Workflow Design:** Easily create complex flow by adding, editing, or removing branches as needed.
3. **Conditional Logic Support:** Implement advanced logic to determine which branches to activate based on specific criteria.
4. **Error Handling:** Ensure robust flow with dedicated error-handling branches for different scenarios.
5. **Real-time Monitoring:** Track the execution of each branch in real time, providing visibility into the workflow's progress.
**Benefits**
1. **Increased Productivity:** Automate and parallelize tasks to reduce completion times and maximize output.
2. **Enhanced Flexibility:** Adapt flow to meet dynamic requirements with easy-to-configure branching structures.
3. **Simplified Complexity:** Manage intricate processes in a streamlined and visual manner.
4. **Error Mitigation:** Minimize risks by isolating and handling errors within specific branches.
5. **Scalability:** Build flow that grow with your needs, supporting additional branches or tasks as required.
## What Can I Build?
1. **Multi-step Automation:** Run several tasks in parallel, such as processing data, sending emails, and updating records, all within a single workflow.
1. **Simultaneous Integrations:** Connect multiple tools or systems at the same time, ensuring efficient data synchronization and faster task execution.
## Setup
1. **Open the Branch Node Configuration Panel:**:
- Here you can manage branches.
2. Define a respected node within each branch.
Note: Minimum two branches are required.
## Low-Code Example
```yaml
nodes:
- nodeId: branchNode_663
nodeType: branchNode
nodeName: Branching
values:
branches:
- label: Branch 1
value: branchNode_663-addNode_484
- label: Branch 2
value: branchNode_663-addNode_801
needs:
- triggerNode_1
branches:
- label: Branch 1
value: plus-node-addNode_484899
- label: Branch 2
value: plus-node-addNode_801189
- nodeId: plus-node-addNode_484899
nodeType: addNode
nodeName: ""
values: {}
needs:
- branchNode_663
- nodeId: plus-node-addNode_801189
nodeType: addNode
nodeName: ""
values: {}
needs:
- branchNode_663
- nodeId: plus-node-addNode_227323
nodeType: addNode
nodeName: ""
values: {}
needs:
- plus-node-addNode_484899
- plus-node-addNode_801189
```
## Output
### `input`
- An object containing the data or parameters provided to the node for processing.
### `output`
- An object representing the result or decision made by the branching logic.
### `skip`
- A boolean indicating whether the branch condition resulted in skipping further processing or execution.
### `status`
- A string denoting the operational status of the node, indicating success or failure of the branching process.
### Example Output
```json
{
"input": {},
"output": {
"skip": true
},
"status": "success"
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ----------------------------- | ------------------------------------------------------------------------------------------ |
| **Parallel Execution Errors** | Verify that all branches are correctly configured and ensure no conflicts in dependencies. |
| **Branch Activation Issues** | Check conditional logic to ensure criteria are correctly defined. |
| **Data Sync Delays** | Ensure proper data mapping and synchronization across branches. |
| **Error Handling Failures** | Review error-handling logic and confirm fallback branches are set up correctly. |
### Debugging Tips
- Verify branch and ensure all connections are correctly established.
- Inspect logs for branch-specific error details to identify the root cause of failures.
- Test individual branches independently before running the entire workflow.
- Confirm input data consistency across all branches to avoid unexpected outcomes.
---
# Code Node
Source: https://lamatic.ai/docs/nodes/logic/code-node.md
# Code Node
## Overview
The Code Node is a programming component that allows users to execute custom JavaScript code within workflows. This node enables custom data processing, logic implementation, and integration with external systems through code.

We will expand support to include additional programming languages.
## Features
**Key Functionalities**
1. **Custom Logic Integration:** Seamlessly incorporate JavaScript code to create tailored flow.
1. **Data Manipulation:** Process and transform large datasets dynamically within your flows.
1. **Third-Party API Support:** Extend your flow by connecting to external APIs and services.
1. **Dynamic Report Generation:** Automate the creation of insightful reports based on real-time data.
1. **Testing and Deployment Tools:** Easily test and deploy JavaScript logic directly in the Lamatic platform.
**Benefits**
1. **Enhanced Flow Customization:** Tailor flows to meet specific business or operational needs.
1. **Streamlined Automation:** Minimize manual intervention with robust, automated processes.
1. **Improved Efficiency:** Optimize flow by integrating complex operations directly into your flows.
1. **Reduced Development Overhead:** Empower developers to build and deploy custom logic without external systems.
1. **Scalable Design:** Create reusable logic components that adapt to various use cases and scale with your needs.
## What Can I Build?
1. **Automated Data Processing Flow:** Handle large datasets within the Lamatic platform effortlessly by automating repetitive tasks and calculations.
1. **Custom Notification Systems:** Send alerts based on specific criteria or data changes, ensuring timely communication.
1. **Third-Party API Integration:** Extend the functionality of existing Lamatic flows by incorporating external APIs.
1. **Dynamic Report Generation:** Compile and present data insights automatically for real-time analysis and decision-making.
## Setup
1. **Open the Code Node Configuration Panel:**:
- Click on the Code Node in your flow to access its configuration options.
1. **Add JavaScript Code**:
- Write or paste your JavaScript code in the provided editor.
- Test your code using the built-in tools to ensure correctness and functionality.
1. **Define Inputs and Outputs**:
- Map input variables and set up the expected outputs to ensure seamless integration with other nodes in your flow.
1. **Test and Debug**:
- Run test cases within the platform to validate your logic.
1. **Save and Deploy**:
- Save the configuration and deploy the flow.
## Low-Code Example
```yaml
nodes:
- nodeId: codeNode_590
nodeType: codeNode
nodeName: Code
values:
code: var a = 5
needs:
- triggerNode_1
- nodeId: plus-node-addNode_392806
nodeType: addNode
nodeName: ""
values: {}
needs:
- codeNode_590
```
## Output
- The result produced by the JavaScript script after execution.
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ---------------------- | ---------------------------------------------------------------------------------- |
| **Syntax Errors** | Review the JavaScript code for typos or errors and use the testing tools to debug. |
| **Unexpected Outputs** | Validate input parameters and ensure proper mapping to outputs. |
| **Execution Failures** | Check node logs for error details and verify all dependencies. |
### Debugging Tips
- Use the built-in code editor to test and validate JavaScript logic.
- Verify the flow structure to ensure nodes are correctly connected.
- Check Lamatic Flow logs for error messages and execution details.
- Monitor input and output data to confirm the correct flow of information.
By leveraging the Lamatic.ai Code Node, you can create highly customized, efficient, and scalable flow tailored to your specific needs.
---
# Condition Node
Source: https://lamatic.ai/docs/nodes/logic/condition-node.md
# Condition Node
## Overview
The Lamatic.ai Condition Node is a versatile component designed to introduce condition logic into your flow. Think of it as the decision-maker for your applications. By evaluating variables and triggers, it determines the next steps in your workflow, enabling a more dynamic and responsive system. Whether you're automating processes, managing data flows, or creating complex logic, this node is the foundation for smarter decision-making.

## Features
**Key Functionalities**
1. **User-Friendly Interface:** Intuitive drag-and-drop design for building flows without coding expertise.
2. **Event Triggering:** Define conditions that react to real-time events, ensuring dynamic responses.
3. **Dynamic Input Handling:** Incorporate variables and real-time data to create adaptive flows.
4. **Multi-Step Optimization:** Streamline lengthy flows by dynamically adjusting based on the outcomes of each step.
5. **Multiple Condition Execution:** Enable flexible multi-value matching with the "Allow Multiple Condition Execution" option for advanced workflow routing.
6. **Enhanced Output Support:** Supports both string and array outputs for condition evaluation, maintaining backward compatibility with existing flows.
**Benefits**
1. **Enhanced Decision-Making:** Automate complex logic with ease, reducing manual intervention.
2. **Increased Efficiency:** Adapt flows to real-time changes, ensuring processes remain optimized.
3. **Reduced Errors:** Automate repetitive decision-making tasks to minimize human error.
4. **Improved Scalability:** Build reusable and adaptable flow components for diverse applications.
## What Can I Build?
1. **Automated Decision-Making Processes:** Create flow that analyze data inputs and execute the appropriate actions automatically.
1. **Dynamic Flow:** Adjust processes based on real-time inputs, such as user actions or external data feeds.
1. **Custom Logic Flows:** Enhance your projects by embedding unique business logic directly into your applications.
1. **Optimized Multi-Step Processes:** Save time and reduce errors by automating repetitive decision-making tasks.
## Setup
1. **Open the Condition Node Configuration Panel**:
- Click on the **Condition Node** in your workflow. This will open the configuration panel on the right side, where you can define conditions.
2. **Define a Condition**:
- Click the **Add Condition** button.
- You will see a condition structure that includes:

- **Operator**: The logic to be applied (e.g., `equals`, `greater than`, `contains`). Select the appropriate operator based on your condition.
- **Operands**: Specify the input values for the condition. These could be variables, constants, or dynamic data.
3. **Edit the Condition**:
- Click the **Edit** button next to the condition to customize it.
- Define:
- **First Operand**: The variable or value to evaluate.
- **Operator**: Select from options such as `equals`, `not equals`, `greater than`, etc.
- **Second Operand**: The value or variable to compare against.
```json
{
"operator": null,
"operands": [
{
"name": "a",
"operator": "<=",
"value": "5"
}
]
}
```
4. **Add Multiple Conditions (Optional)**:
- Use the **Add Condition** button to define additional conditions if needed.
- Combine multiple conditions using logical operators like `AND` or `OR` to create more complex logic.
5. **Enable Multiple Condition Execution (Optional)**:
- Toggle the **Allow Multiple Condition Execution** option to enable flexible multi-value matching.
- When enabled, the node can execute multiple condition paths simultaneously if multiple conditions evaluate to `true`, allowing for more flexible workflow routing.
- This feature is particularly useful when you need to handle scenarios where input values match multiple conditions at once.
6. **Define Outcome Paths**:
- Configure the paths for **Condition 1** and **Else**:
- **Condition 1**: The path the workflow will follow if the condition evaluates to `true`.
- **Else**: The fallback path if the condition evaluates to `false`.
- Select the additional nodes into these paths to define subsequent actions.
7. **Test the Configuration**:
- Use the **Test** option at the bottom right to simulate your workflow and verify that the Condition Node behaves as expected.
8. **Save and Deploy**:
- Once configured, click **Save** to store the changes.
- Click **Deploy** to activate the workflow with the configured Condition Node.
## Low-Code Example
```yaml
- nodeId: conditionNode_347
nodeType: conditionNode
condition:
- label: Condition 1
value: plus-node-addNode_263609
- label: Else
value: plus-node-addNode_784238
nodeName: Condition
values:
conditions:
- label: Condition 1
value: conditionNode_347-addNode_263
condition:
operator: null
operands:
- name: ""
operator: <=
value: ""
- label: Else
value: conditionNode_347-addNode_784
condition: {}
needs:
- triggerNode_1
```
## Output
- `condition`: The evaluated outcome or state determined by the condition node. Can be either:
- **String**: A single condition label when one condition matches (default behavior, maintains backward compatibility).
- **Array**: Multiple condition labels when "Allow Multiple Condition Execution" is enabled and multiple conditions evaluate to `true`.
### Example Output
**Single Condition (String Output):**
```json
{
"condition": "Else"
}
```
**Multiple Conditions (Array Output):**
```json
{
"condition": ["Condition 1", "Condition 2"]
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ----------------------- | ------------------------------------------------------------------------------------------------- |
| **Parameter Mismatch** | Check input parameter format and requirements |
| **Unexpected Behavior** | Validate all conditions and logic within the node to ensure they align with the desired outcomes. |
| **Execution Timeout** | Review flow complexity and timeout settings |
### Debugging Tips
- Check Lamatic Flow logs for error details
- Verify flow deployment status
- Test input parameters independently
- Monitor flow execution time
---
# End Node
Source: https://lamatic.ai/docs/nodes/logic/end-node.md
# End Node
## Overview
The End Node is used to **stop the execution of a flow immediately**. When the flow reaches this node, Lamatic **skips any nodes that would execute after it** and routes execution directly to the **Final Trigger Response** node.
Place an End Node on any branch where you want to stop early (for example, after a validation failure or a “no-op” condition). Any nodes connected after the End Node won’t run.
## Features
**Key Functionalities**
1. **Immediate termination:** Stops the current execution path as soon as it’s reached.
2. **Skip downstream execution:** Prevents any nodes after the End Node from running.
3. **Predictable exit point:** Routes execution to the Final Trigger Response node to finish the run cleanly.
**Benefits**
1. **Cost control:** Avoid unnecessary model calls, API requests, or processing once a result is already decided.
2. **Cleaner flow logic:** Replace complex branching workarounds with a clear “stop here” node.
3. **Safer automation:** Prevent side effects (writes, sends, deletes) when a condition indicates execution should halt.
## What Can I Build?
1. **Guard rails / validation gates:** End the flow when required inputs are missing or invalid.
2. **Early return logic:** Return a response when a cached result exists, without running the rest of the pipeline.
3. **Conditional short-circuiting:** Stop non-relevant branches (for example, when a user is not eligible for a path).
## Setup
1. Add the **End Node** to the point in your flow where execution should stop.
1. Connect your branch/path into the End Node.
1. Ensure your flow has a **Final Trigger Response** node to produce the final output.
1. Deploy the project.
## Configuration Reference
The End Node does not require configuration. Its behavior is defined by its position in the flow.
## Low-Code Example
### Stop execution on a condition
```yaml
nodes:
- nodeId: endNode_192
nodeType: endNode
nodeName: End
values: {}
modes: {}
needs:
- triggerNode_1
allConfigs:
Config A:
nodeName: End
schema: {}
```
## Output
The End Node does not transform data. Its purpose is to **terminate execution** and pass control to the Final Trigger Response node.
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| --- | --- |
| **Nodes after End Node still run** | Ensure the path actually reaches the End Node (check connections and branch conditions). |
| **No final response is returned** | Confirm your flow includes a **Final Trigger Response** node and it is reachable after termination. |
| **End Node placed but flow doesn’t stop** | Verify you’re not executing a different branch/path that bypasses the End Node. |
### Debugging Tips
- Use flow logs to confirm the End Node is reached on the expected path.
- If you have multiple branches, add End Nodes only where you want early termination—other branches will continue unless they also end.
---
# Execute Flow Node
Source: https://lamatic.ai/docs/nodes/logic/execute-flow.md
# Execute Flow Node
## Overview
The Execute Flow Node is a workflow orchestration component that allows users to call and execute other workflows from within a current workflow. This node enables modular workflow design and reusability of workflow components.

## Features
**Key Functionalities**
1. **Sub-flow Execution**: Call and execute other flows
2. **Data Passing**: Transfer current flow data as input 1. **Modular Design**: Create reusable workflow components
**Benefits**
1. **Modularity** : Enables building complex flow in a modular fashion
2. **Reusability** : Promotes code reuse and component sharing
3. **Simplification** : Simplifies flow design and maintenance
## Prerequisites
Before using the Execute Flow, ensure you have:
- Active flows with compatible triggers (API Request, Chat, or Search)
- Necessary permissions to execute target flows
- Understanding of data flow and parameter passing
---
## Configuration Reference
### Execute Flow Parameters
| **Parameter** | **Description** | **Required** | **Example** |
| ----------------- | --------------------------------------- | ------------ | ----------------------------------------- |
| **Flow ID** | Target flow selection from active flows | ✅ | `4be6dea6-d13c-44d8-87cf-5ad46361c890` |
| **Request Input** | Input parameters for target flow | ✅ | `{ "prompt": "{{triggerNode_1.output}}"}` |
---
## Usage Guidelines
### Setting Up Execute Node
1. **Add Execute Node**:
- Drag Flow Node to your workflow
- Select target flow from dropdown
2. **Configure Parameters**:
- Set Flow ID for target flow
- Configure input parameters
- Map data from current flow
3. **Validate Configuration**:
- Ensure all required parameters are set
- Verify data mapping is correct
### Best Practices
1. **Modular Design**
- Break complex flow into smaller flows
- Create reusable components
- Maintain clear flow boundaries
2. **Data Management**
- Plan data flow between flow
- Document parameter requirements
- Handle data transformations appropriately
3. **Error Handling**
- Implement proper error checking
- Provide fallback options
- Monitor flow execution
---
## Low-Code Example
```yaml
- nodeId: flowNode_919
nodeType: flowNode
nodeName: Execute Flow
values:
flowId: flow_id
requestInput: |-
{
"test": "{{triggerNode_1.output.user_name}}"
}
needs:
- node_id
```
## Output
- `flowOutput`: An object containing the results or data generated by the executed flow.
### Example Output
```json
{
"flowOutput": {}
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ---------------------- | --------------------------------------------- |
| **Flow Not Found** | Verify Flow ID and deployment status |
| **Parameter Mismatch** | Check input parameter format and requirements |
| **Permission Denied** | Confirm execution permissions |
| **Execution Timeout** | Review flow complexity and timeout settings |
### Debugging Tips
- Check Lamatic Flow logs for error details
- Verify flow deployment status
- Test input parameters independently
- Monitor flow execution time
- Review permission settings
---
## Example Use Cases
### Multi-step Processing
1. **Data Preparation Flow**:
- Clean and validate input data
- Transform data format
- Apply business rules
2. **Analysis Flow**:
- Process prepared data
- Generate insights
- Create reports
3. **Notification Flow**:
- Send results to stakeholders
- Update systems
- Log completion status
### Chain Processing
- Execute series of specialized flows
- Pass results between flows
- Maintain process isolation
---
# Loop Node
Source: https://lamatic.ai/docs/nodes/logic/loop-node.md
# Loop Node
## Overview
The Loop Node is a control flow component that enables iterative processing of data by repeating operations on collections or arrays. This node is essential for processing large datasets and implementing repetitive logic in workflows.

## Features
**Key Functionalities**
1. **Range-based Iteration:** Define a start and end value to create a numerical loop.
2. **List-based Iteration:** Iterate over an array of objects for flexible iterative processing.
3. **Dynamic Variable Support:** Use dynamic variables for adaptable looping.
**Benefits**
1. **Automation:** Reduces manual effort by handling repetitive operations.
2. **Scalability:** Supports iterative processing for handling multiple inputs efficiently.
3. **Flexibility:** Works with both numerical ranges and structured data arrays.
## What Can I Build?
1. Automate repetitive tasks, such as sending emails to multiple recipients.
1. Process large datasets by iterating over records for transformation or analysis.
1. Generate reports by looping over a list of entities and aggregating results.
## Setup
### Select the Loop Node
1. Choose the Loop Node in your workflow.
1. Define the iteration type (Range or List).
1. Configure the required parameters.
1. Deploy the project.
1. Click Setup on the workflow editor to generate instructions for integration.
## Configuration Reference
| **Parameter** | **Description** | **Example Value** |
| ------------------------------ | ------------------------------------------------------------------ | ------------------------------- |
| **Iterate Over** | Defines whether the loop runs over a List or a Range. | `List` or `Range` |
| **Value** | (For List) Specifies the array or list to iterate over. | `{{triggerNode_1.output.urls}}` |
| **Initial Value** | (For Range) Starting value of the loop. | `0` |
| **End Value** | (For Range) Specifies the ending value (exclusive). | `10` |
| **Increment** | (For Range) Defines the step size for each iteration. | `10` |
| **Wait Before Next Iteration** | The number of seconds to wait before each iteration. Min:0, Max:30 | `10` |
> **Note:** The studio testing API has a timeout limit of 300 seconds. When using the Wait Before Next Iteration parameter with many iterations, be mindful that the total execution time (number of iterations × wait time) should not exceed 300 seconds to avoid API timeouts.
## Low-Code Example
```yaml
nodes:
nodes:
- nodeId: forLoopNode_250
nodeType: forLoopNode
nodeName: For Loop
values:
endValue: "10"
increment: "1000"
connectedTo: forLoopEndNode_984
iterateOver: list
initialValue: "0"
iteratorValue: "{{triggerNode_1.output.urls}}"
needs:
- triggerNode_1
- forLoopEndNode_984
connections:
- condition: Loop Start
value: plus-node-addNode_226284
type: conditionEdge
- condition: Loop
value: forLoopEndNode_984
type: loopEdge
- nodeId: forLoopEndNode_984
nodeType: forLoopEndNode
nodeName: For Loop End
values:
connectedTo: forLoopNode_250
needs:
- scraperNode_351
- forLoopNode_250
connections:
- condition: Loop End
value: plus-node-addNode_257360
type: conditionEdge
- condition: Loop
value: forLoopNode_250
type: loopEdge
invisible: true
- nodeId: plus-node-addNode_226284
nodeType: addNode
nodeName: ""
values: {}
needs:
- forLoopNode_250
- nodeId: plus-node-addNode_257360
nodeType: addNode
nodeName: ""
values: {}
needs:
- forLoopEndNode_984
- nodeId: scraperNode_351
nodeType: scraperNode
condition: Loop Start
nodeName: Scraper
values:
url: "{{forLoopNode_250.output.currentValue}}"
mobile: false
waitFor: 123
credentials: ....
excludeTags: []
includeTags: []
onlyMainContent: false
skipTLsVerification: false
needs:
- plus-node-addNode_226284
```
## Output
The output from the loop will be an array of objects.
### Accessing Output of Looped Nodes

You can select the looped node's output from the variable selector as shown above. After which you can modify the index by modifying the index key to a specific index or a looping variable as per your requirement as show below.
### Iterating Over Outcomes by Replacing Index
This feature allows for iterating over results dynamically by replacing the index placeholder with a specific value. It enables access to individual results from the loop output.
```js
//Replace index with whatever index you want
{{forLoopEndNode_271.output.loopOutput[index].hybridSearchNode_299.output.searchResults}}
//For Example to access output for iteration 0
{{forLoopEndNode_271.output.loopOutput[0].hybridSearchNode_299.output.searchResults}}
for (let i = 0; i < recipeIngredientsFinal.length; i++) {
recipeIngredientsFinal[i].ingredientId={{forLoopEndNode_271.output.loopOutput[i].hybridSearchNode_299.output.searchResults[0].ingredientId}}
//Replace index with whatever index you want
}
```
### Use Case
- Extracting individual results from a looped query
- Processing results dynamically in a template
- Enhancing automation flow by iterating over multiple outcomes
## Testing
You can also check the individual outcome from each iteration using the dropdown in Testing.

## Flow Execution Logs
The flow execution logs provide detailed insights into the execution process of each iteration in the logs sections

## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ---------------------- | --------------------------------------------- |
| **Loop Not Executing** | Ensure valid range or list input is provided. |
| **Performance Issues** | Enable concurrency or optimize list size. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify input parameters to ensure correct configuration.
---
# Variable Node
Source: https://lamatic.ai/docs/nodes/logic/variable-node.md
# Variable Node
## Overview
The Variable Node is a data management component that allows users to define and manage variables for storing and manipulating data within workflows. This node enables dynamic data handling and state management across workflow executions.

You can map variables in the Variable Node using a simple interface. Each variable can be assigned a type (e.g., string, number) and a value, which can be a static value or a reference to another node's output.
## Features
**Key Functionalities**
1. **Variable Mapping:** Easily define and map variables with static values or dynamic references from other nodes.
2. **Reusability:** Use mapped variables throughout your flow, reducing redundancy and improving maintainability.
3. **Dynamic Referencing:** Reference outputs from previous nodes to make your flows adaptable and data-driven.
4. **Centralized Management:** Manage all your flow variables in one place for better organization and clarity.
5. **Seamless Integration:** Integrate mapped variables with any node that supports variable input, enabling flexible and powerful automation.
**Benefits**
1. **Enhanced Flow Customization:** Tailor flows to meet specific business or operational needs.
1. **Streamlined Automation:** Minimize manual intervention with robust, automated processes.
1. **Improved Efficiency:** Optimize flow by integrating complex operations directly into your flows.
1. **Reduced Development Overhead:** Empower developers to build and deploy custom logic without external systems.
1. **Scalable Design:** Create reusable logic components that adapt to various use cases and scale with your needs.
## What Can I Build?
1. **Centralized Variable Management:** Store and manage all key values in one place for use across your entire flow.
2. **Dynamic Data Passing:** Pass outputs from one node as variables to multiple downstream nodes, enabling flexible and dynamic workflows.
3. **Parameterization:** Easily update values (like API keys, thresholds, or user settings) in one node and have changes reflected throughout your flow.
4. **Template Flows:** Create reusable flow templates by defining variables that can be quickly remapped for different use cases or environments.
5. **Conditional Logic Support:** Use mapped variables as conditions or parameters in logic, filter, or branching nodes.
## Variable Mapping and Usage
The Variable Node in Lamatic lets you define variables and assign them values, which can be static or dynamically referenced from other nodes. These mapped variables can then be used in subsequent nodes throughout your flow.
## How to Map Variables
1. **Add a Variable Node to your flow.**
2. **Define variables:** For each variable, specify a name, type (e.g., string, number), and value. The value can be a static value or a reference to another node's output (e.g., `{{nodeId.output.field}}`).
3. **Save the configuration.**
**Example UI Mapping:**
- Variable `a` (type: string) mapped to `{{dndnode_0.output.sampleInput1}}`
- Variable `b` (type: string) mapped to `{{dndnode_0.output.sampleInput2}}`
**Equivalent JSON:**
```json
{
"a": {
"type": "string",
"value": "{{dndnode_0.output.sampleInput}}"
},
"b": {
"type": "string",
"value": "{{dndnode_0.output.sampleInput}}"
}
}
```
## Setup
1. **Add a Variable Node:** Drag and drop a Variable Node into your flow.
2. **Define Variables:** For each variable, specify a name, type (e.g., string, number, boolean), and value. The value can be static or reference another node's output (e.g., `{{nodeId.output.field}}`).
3. **Save the Node:** Confirm your variable mappings and save the configuration.
4. **Use Variables in Other Nodes:** Reference the mapped variables in any compatible node by their names (e.g., `variables.a`).
5. **Update as Needed:** Edit the Variable Node to update values, which will automatically propagate to all nodes using those variables.
## Low-Code Example
```yaml
nodes:
- nodeId: variablesNode_426
nodeType: variablesNode
nodeName: Variables
values:
mapping: |-
{
"test": {
"type": "string",
"value": "{{dndnode_0.output.sampleInput}}"
}
}
modes: {}
needs:
- dndnode_0
```
## Output
- The result produced after execution.
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
|---------------------------|---------------------------------------------------------------------------------------------|
| **Incorrect Variable Value** | Double-check the value mapping and ensure references (e.g., `{{nodeId.output.field}}`) are correct. |
| **Variable Not Found** | Make sure the variable name is spelled correctly and is defined in the Variable Node. |
| **Downstream Node Errors** | Ensure all required variables are mapped and available before they are used in other nodes. |
| **Stale Values** | If you update a variable, verify that all dependent nodes are using the latest mapping. |
| **Type Mismatch** | Confirm that the variable type (string, number, boolean) matches the expected input type. |
### Debugging Tips
- Use clear and descriptive variable names to avoid confusion.
- Check the variable mapping panel for typos or incorrect references.
- Use the platform's preview or test features to inspect variable values at runtime.
- If a node fails, review its input configuration to ensure all variables are correctly mapped.
- Trace the flow to see where a variable might not be set or is being overwritten.
- When referencing outputs from other nodes, always use the correct syntax: `{{nodeId.output.field}}`.
- Update and save the Variable Node whenever you make changes to ensure updates propagate through the flow.
By leveraging the Lamatic.ai Variable Node, you can create highly customized, efficient, and scalable flow tailored to your specific needs.
---
# Wait Node
Source: https://lamatic.ai/docs/nodes/logic/wait-node.md
# Wait Node
## Overview
The Wait Node is a timing control component that introduces delays in workflow execution. This node is useful for rate limiting, scheduling, and ensuring proper timing between workflow steps.

## Features
**Key Functionalities**
1. **Execution Wait:** Wait for a specified time during the flow.
3. **Step Synchronization:** Add wait time between dependent steps in your flow.
4. **Sequential Flow Control:** Ensure proper timing across nodes.
5. **Simple Configuration:** Define wait time with a single value.
**Benefits**
1. **Improved Flow Stability:** Reduces errors caused by premature executions.
2. **Controlled Execution:** Enables better coordination between systems or APIs.
3. **Reduced Failure Rates:** Avoids overloading external systems by spacing out actions.
4. **Flexible Timing:** Wait duration can be set per use case.
5. **No Extra Scripting Required:** Add timing logic directly within your flow visually.
## What Can I Build?
1. **Throttled API Calls:** Wait between API calls to respect third-party rate limits.
2. **Retry Gaps:** Wait before retrying failed operations or requests.
3. **Staggered Alerts:** Wait before sending time-based notifications.
4. **Process Timing Flows:** Add waits to align with expected processing time of external systems.
## Setup
### Select the Wait Node
1. Select the Wait Node into your Lamatic flow.
2. Set the **Wait Time (in seconds)** between 1 and 90.
3. Connect it before the next step that needs to wait.
4. Deploy your flow and test to validate the wait duration.
## Configuration Reference
| **Parameter** | **Description** | **Required** | **Example Value** |
| ------------------- | ----------------------------------------------------- | ------------ | ----------------- |
| **Wait Time (sec)** | Time in seconds to wait before proceeding (1–90 sec). | Yes | 10 |
## Low-Code Example
```yaml
nodes:
- nodeId: waitNode_614
nodeType: waitNode
nodeName: Wait
values:
seconds: 30
modes: {}
needs:
- triggerNode_1
responseNode:
nodeId: responseNode_triggerNode_1
nodeType: graphqlResponseNode
nodeName: API Response
values:
outputMapping: "{}"
needs:
- waitNode_614
```
## Output
The Wait Node return status (true/false). It simply waits for the configured duration before triggering the next node.
```json
{
"output": {
"success": true
},
"input": {
"nodeName": "Wait",
"seconds": 30
},
"logs": null,
"status": "success"
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------- | ---------------------------------------------------------- |
| **Flow Not Continuing** | Ensure the wait time is a number between 1 and 90 seconds. |
| **Unexpected Wait Time** | Check for additional waits or slow nodes in the flow. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Use Lamatic flow logs to verify wait duration execution.
1. Check surrounding nodes to rule out additional delays.
---
# Node Assistant
Source: https://lamatic.ai/docs/nodes/node-assistant.md
# Node AI Assistant

**Note**: The Node AI Assistant may occasionally provide improper or inaccurate responses. Please manually verify all instructions and configurations provided by the assistant. Our team is continuously working to improve this feature for better accuracy and reliability.
The Node AI Assistant is an intelligent helper that provides contextual AI-powered assistance for configuring individual nodes in your flow. Unlike the Flow AI Assistant which helps with overall workflow guidance, the Node Assistant focuses specifically on helping you configure, optimize, and improve individual nodes with targeted suggestions and improvements.
## What is the Node AI Assistant?
The Node AI Assistant is a specialized AI-powered feature that appears within the node configuration panel. It provides real-time, node-specific guidance to help you configure nodes more effectively. The assistant understands the context of the specific node you're working with and offers relevant suggestions, improvements, and step-by-step instructions tailored to that node's configuration.
## Key Features
### Node-Specific Configuration Help
The Node Assistant provides targeted assistance for the specific node you're configuring:
- **Model Selection**: Get recommendations on which AI models work best for your use case
- **Prompt Optimization**: Receive suggestions for improving your prompts based on best practices
- **Parameter Tuning**: Learn about optimal settings for node-specific parameters
- **Input/Output Mapping**: Get help with correctly mapping inputs and outputs
- **Tool Integration**: Receive guidance on selecting and configuring tools for your node
### Contextual Improvements
The assistant analyzes your node configuration and provides contextual suggestions:
- **Configuration Optimization**: Get recommendations to improve your node's performance
- **Best Practices**: Learn node-specific best practices and patterns
- **Error Prevention**: Receive warnings about potential configuration issues
- **Advanced Features**: Discover advanced configuration options you might not be aware of
### Interactive Assistance
Provide context about what you want to achieve, and the assistant will help you:
- **Custom Instructions**: Share your goals and requirements for the node
- **Iterative Refinement**: Get suggestions for improving your configuration step by step
- **Use Case Examples**: Request examples specific to your node type and use case
- **Troubleshooting**: Get help resolving configuration issues or errors
## How to Use the Node AI Assistant
### Accessing the Node Assistant
**Method:**
1. Open a flow in the Flow Editor
2. Click on the node you want to configure
3. The node configuration panel will open on the right side
4. Look for the assistant icon (diamond icon) next to the node's title in the configuration panel
5. Click on the assistant icon to enable the Node Assistant
### Getting Configuration Help
Once the Node Assistant is enabled, you can:
**Method:**
1. **Provide Context**: Share what you're trying to achieve with this node
2. **Ask Questions**: Ask specific questions about configuration options
3. **Request Improvements**: Ask the assistant to suggest improvements to your current configuration
4. **Get Examples**: Request examples of how to configure the node for your use case
**Example: Configuring an AI Text Generation Node**
1. Click on a "Generate Text" node in your flow
2. Open the node configuration panel
3. Click the assistant icon next to the node title
4. Provide context: "I want to create a chatbot that responds in a friendly, professional tone"
5. The assistant will provide suggestions for:
- System prompts that match your tone requirements
- Model selection recommendations
- Temperature and other parameter settings
- Best practices for chatbot configurations
### Providing Context for Improvement
The Node Assistant works best when you provide context about your goals:
**What to Share:**
- **Use Case**: What are you trying to accomplish with this node?
- **Requirements**: What are your specific requirements or constraints?
- **Current Issues**: Are you experiencing any problems with the current configuration?
- **Desired Outcome**: What result are you aiming for?
**Example Context:**
- "I need this node to process customer support tickets and extract key information"
- "I want to optimize this node for faster response times"
- "I'm getting errors when this node processes large text inputs"
- "I want to make this node's output more consistent"
### Working with Different Node Types
The Node Assistant adapts its guidance based on the node type:
**AI Nodes:**
- Model selection and configuration
- Prompt engineering and optimization
- Temperature and parameter tuning
- Tool selection and integration
**App Nodes:**
- Credential setup and authentication
- API endpoint configuration
- Data mapping and transformation
- Error handling and retry logic
**Data Nodes:**
- Data transformation strategies
- Chunking and indexing parameters
- Filtering and query optimization
- Performance tuning
**Logic Nodes:**
- Conditional logic setup
- Variable mapping
- Flow control patterns
- Code optimization
## Benefits of Using the Node Assistant
### Faster Configuration
- **Quick Setup**: Get step-by-step guidance for configuring nodes quickly
- **Reduced Errors**: Receive warnings and suggestions that help prevent configuration mistakes
- **Best Practices**: Learn optimal configuration patterns without extensive trial and error
### Improved Node Performance
- **Optimization Suggestions**: Get recommendations to improve node performance
- **Parameter Tuning**: Learn about optimal parameter settings for your use case
- **Resource Efficiency**: Receive guidance on using resources more efficiently
### Better Understanding
- **Node-Specific Learning**: Deep dive into specific node capabilities and features
- **Advanced Features**: Discover configuration options you might not know about
- **Contextual Examples**: See examples relevant to your specific node and use case
### Iterative Improvement
- **Continuous Refinement**: Get suggestions for improving your configuration over time
- **Context-Aware Help**: Receive assistance that understands your current configuration state
- **Goal-Oriented Guidance**: Get help that aligns with your specific objectives
## Best Practices
1. **Be Specific**: Provide clear context about what you want to achieve with the node
2. **Share Requirements**: Mention any specific requirements, constraints, or preferences
3. **Iterate**: Use the assistant's suggestions as a starting point and refine based on your needs
4. **Test Changes**: After applying suggestions, test your node to ensure it works as expected
5. **Combine with Flow Assistant**: Use the Node Assistant for node-specific help and the Flow Assistant for overall workflow guidance
## Node Assistant vs. Flow Assistant
While both assistants provide AI-powered help, they serve different purposes:
| **Feature** | **Node Assistant** | **Flow Assistant** |
|-------------|-------------------|-------------------|
| **Scope** | Individual node configuration | Overall flow structure and workflow |
| **Location** | Node configuration panel | Right side panel in Flow Editor |
| **Focus** | Node-specific settings, prompts, parameters | Flow structure, node connections, overall logic |
| **Use Case** | "How do I configure this specific node?" | "How do I build this workflow?" |
| **Context** | Current node's configuration | Entire flow context |
Use the Node Assistant when you need help with a specific node's configuration, and use the Flow Assistant when you need guidance on building or structuring your overall workflow.
The Node AI Assistant makes node configuration more intuitive and efficient, helping you get the most out of each node in your flow. Whether you're configuring a simple node or optimizing a complex one, the assistant provides valuable, context-aware guidance to help you achieve your goals.
---
# Node Logic
Source: https://lamatic.ai/docs/nodes/node-logic.md
# Node Logic

Node Logic provides powerful ways to wrap and extend your node's behavior, enabling advanced control mechanisms for flow control, conditional routing, and iterative processing. These logic options help you build more dynamic, responsive, and flexible workflows.
> **Tip**: Node Logic is useful for flow control, conditional routing, and iterative refinement. Add logic to your nodes to enhance workflow flexibility and enable dynamic execution paths.
## Overview
When configuring a node, you can add logic to control how the node executes and routes execution through your workflow. The available logic options include:
- **Fallback** - Automatically switch to a backup node configuration on timeout or failure
- **Retry** - Automatically retry node execution with configurable attempts and delays
- **Go Back** - Conditionally route execution back to a previous node based on output data
- **Parallel** - Execute multiple node configurations simultaneously
- **A/B Test** - Split traffic between two node configurations with configurable percentages
---
## 1. Fallback
Fallback logic enables automatic failover to a backup node configuration when the primary node times out or fails. This ensures your workflow continues executing even if the primary node encounters issues.
### When to Use Fallback
- When you need high availability and reliability
- When working with nodes that may have variable response times
- When you want to ensure your workflow doesn't fail due to node unavailability
### Configuration
When you select **Fallback**, you can configure:
- **Config A (Primary Logic)** - The primary Logic configuration that will be attempted first
- **Config B (Fallback Logic)** - The backup Logic configuration used if Config A fails or times out
- **Timeout** - The maximum time to wait for Config A before switching to Config B
### How It Works
1. The system attempts to execute **Config A** (your primary node configuration)
2. If Config A times out (based on your timeout setting) or fails, the system automatically switches to **Config B**
3. The result from the successful configuration (either A or B) is used to continue the workflow
> **Note**: Make sure Config B uses a different node or configuration that's more reliable or faster, even if potentially less optimal.
---
## 2. Retry
Retry logic automatically retries node execution when it fails, helping you handle transient errors and network issues gracefully.
### When to Use Retry
- When dealing with intermittent network issues or API rate limits
- When you want to automatically recover from temporary failures
- When working with nodes that may occasionally timeout
### Configuration
When you select **Retry**, you can configure:
- **Max Retry Attempts** - The maximum number of times to retry the node execution (e.g., 3, 5, 10)
- **Delay** - The time to wait between retry attempts (e.g., 1 second, 5 seconds)
### How It Works
1. The system attempts to execute the node
2. If the execution fails, it waits for the specified **Delay** period
3. The system retries the execution
4. This process repeats until either:
- The execution succeeds, or
- The maximum number of retry attempts is reached
> **Best Practice**: Set appropriate delay values to avoid overwhelming the node API and to respect rate limits.
---
## 3. Go Back
Go Back logic allows you to conditionally route execution back to a previous node in your workflow based on the node's output data. This enables dynamic flow control and iterative refinement.
### When to Use Go Back
- When you need to refine or reprocess data based on node output
- When implementing iterative workflows that require multiple passes
- When you want to conditionally loop back to previous processing steps
- When you need to retry a process until certain conditions are met
### Configuration
When you select **Go Back**, you can configure:
- **Condition** - A condition based on the output data that determines when to go back
- **Target Node** - The specific node to route execution back to when the condition is met
- **Action** - The action to trigger when routing back (e.g., re-execute, update context)
### How It Works
1. The node executes and produces output
2. The system evaluates the **Condition** against the output data
3. If the condition is met, execution routes back to the specified **Target Node**
4. The target node re-executes with the updated context
5. If the condition is not met, execution continues to the next node in the flow
> **Warning**: Be careful to avoid infinite loops. Ensure your conditions can eventually be false, or set maximum iteration limits.
### Example Use Cases
- **Quality Check Loop**: Route back to a processing node if output quality doesn't meet certain criteria
- **Data Validation**: Return to a data transformation node if validation fails
- **Iterative Refinement**: Loop back to a model node to refine output until it meets specific requirements
- **Retry Logic**: Automatically retry a node's operation until success conditions are met
---
## 4. Parallel Execution
Parallel logic executes two node configurations simultaneously, allowing you to compare results or combine outputs from different Logic.
### When to Use Parallel
- When you want to compare outputs from different Logic
- When you need to combine results from multiple node configurations
- When you want to improve performance by running Logic concurrently
### Configuration
When you select **Parallel**, you can configure:
- **Config A** - The first Logic configuration to execute
- **Config B** - The second Logic configuration to execute
- Both configurations execute simultaneously
### How It Works
1. Both **Config A** and **Config B** start executing at the same time
2. The system waits for both configurations to complete
3. You can access results from both configurations in subsequent Logics
4. Results are typically available as separate outputs or can be combined based on your workflow logic
> **Tip**: Parallel execution can significantly reduce total execution time when you need results from multiple Logic, as they run concurrently rather than sequentially.
---
## 5. A/B Testing
A/B Testing logic allows you to split traffic between two Logic configurations with configurable percentages, enabling you to test and compare different Logic setups.
### When to Use A/B Testing
- When you want to compare the performance of different Logic configurations
- When testing new Logics or configurations against existing ones
- When you need to gradually roll out new Logic configurations
### Configuration
When you select **A/B Test**, you can configure:
- **Config A** - The first Logic configuration
- **Config B** - The second Logic configuration
- **Traffic Split** - The percentage distribution between Config A and Config B
- **Config A Percentage** - e.g., 40% of requests go to Config A
- **Config B Percentage** - e.g., 60% of requests go to Config B
- Percentages must total 100%
### How It Works
1. For each execution, the system randomly selects Config A or Config B based on the configured percentages
2. If Config A is set to 40% and Config B to 60%:
- Approximately 40% of executions use Config A
- Approximately 60% of executions use Config B
3. Results from both configurations can be tracked and compared
4. The system maintains the traffic split distribution over time
> **Analytics**: Use the Logs and Reports tabs to analyze the performance and results of each configuration in your A/B test.
---
## Adding Logic to a Node
To add logic to a node:
1. Select the node in your flow
2. Open the **Config** tab in the right sidebar
3. Navigate to the **LOGIC** section
4. Click on the **Logic** sub-tab
5. Click **+ Add Logic** button
6. Select the logic type you want to add:
- **Fallback** (clock icon)
- **Retry** (refresh icon)
- **Go Back** (back arrow icon)
- **Parallel** (parallel lines icon)
- **A/B Test** (A/B icon)
7. Configure the selected logic type with the appropriate settings
8. Save your configuration
> **Note**: You can combine multiple logic types on a single node for more complex behavior, such as using Retry with Fallback for maximum reliability, or Go Back with conditional checks for sophisticated flow control.
---
## Best Practices
- **Fallback**: Always configure a reliable backup node that's faster or more stable than your primary
- **Retry**: Set reasonable retry limits and delays to avoid excessive API calls and costs
- **Go Back**:
- Always implement safeguards to prevent infinite loops (e.g., iteration counters, maximum retry limits)
- Ensure your conditions are well-defined and can eventually evaluate to false
- Use clear naming conventions for target nodes to make flow logic easier to understand
- Test your loops thoroughly with various input scenarios
- Consider adding logging or monitoring to track loop iterations
- **Parallel**: Use when you genuinely need both results, as it increases resource usage
- **A/B Testing**: Run tests for sufficient duration to gather statistically significant data
---
## Related Resources
- [Model Logic](/docs/models/model-logic) - Learn about logic options for model nodes
- [Node Configuration](/docs/flows/node-config) - General node configuration guide
- [Condition Node](/docs/nodes/logic/condition-node) - Use condition nodes for branching logic
- [Loop Node](/docs/nodes/logic/loop-node) - Learn about loop nodes for iterative processing
- [Flow Control](/docs/flows) - Understanding flow execution and control
---
# Getting Started with Agents
Source: https://lamatic.ai/docs/agents/getting-started.md
# Getting Started with Agents
Agents in Lamatic.ai are AI-driven components designed to automate flow, process data, and generate intelligent responses. Whether you're building a chatbot, structuring data, or orchestrating multiple AI models, agents provide a flexible and efficient way to handle tasks. You can create agents in two ways: **via the Flow Editor** (for seamless integration into flow) or **via the Agent Dashboard** (for standalone configuration and management). Follow the steps below to get started.
## Creating an Agent via Flow Editor

To create an agent via the flow editor :
1. **Navigate to the Flow Editor:** Click on the "Add Node" button.
2. **Select an Agent Node:** Choose the appropriate agent type based on your requirements.
3. **Configure Parameters:** Customize agent settings, such as model selection, prompt templates, agent paths, and output formats.
4. **Connect Nodes:** Link the agent node to other nodes in the flow for data exchange.
5. **Deploy the Flow:** Save and deploy the flow to activate the agent.
---
# JSON Agent
Source: https://lamatic.ai/docs/agents/json-agent.md
# JSON Agent
The **JSON Agent** calls an LLM and returns structured JSON that matches a schema you define. Use it when you need predictable, typed output (e.g. for APIs, data pipelines, or reports) instead of free-form text.

## When to use this
| Use the **JSON Agent** when… | Use the **Generate JSON** node instead when… |
|------------------------------|----------------------------------------------|
| You want an agent you can reuse across Flows (shared config, saved configs) | You only need one LLM step inside a single Flow that outputs JSON |
| You're building from the Agent dashboard and wiring it into multiple Flows | You're building everything in the Flow Editor and want a single node to produce JSON |
Both can produce schema-bound JSON; the JSON Agent is an agent abstraction with its own config and templates.
## Quickstart
1. Add a **JSON Agent** node to your Flow (or create a JSON Agent from the Agents page).
2. Define the **output schema** (JSON Schema) so the model knows the exact shape (e.g. `{ "destination": "string", "activities": ["string"] }`).
3. Set the **prompt** (and optional system instructions) so the model gets clear instructions.
4. Select the **model** and credentials.
5. Connect the node to your trigger and run the Flow.
Save the agent config (Load/Save Config) to reuse the same schema and prompts in other Flows.
## Configuration reference
| Parameter | Description | Example |
|------------|--------------|---------|
| **Prompts** | System, user, and assistant prompts for the LLM | `System Prompt`, `User Prompt` |
| **Models** | AI model used for generation | `GPT-4 Turbo` |
| **Inputs** | Input schema (Zod format) | `{"type": "string"}` |
| **Attachments** | Files sent with the prompt | `{"file": "data.csv"}` |
| **Messages** | Conversation history (user/assistant) | `[{"message": "…"}]` |
| **Memories** | User/assistant memories | `[{"memory": "…"}]` |
## Common patterns
- **API response shaping** — Map user input to a fixed JSON response (e.g. form extraction, search filters).
- **Data extraction** — Turn unstructured text (emails, docs) into JSON for pipelines.
- **Structured reports** — Generate JSON blobs (e.g. summaries, recommendations) for dashboards or downstream systems.
## Troubleshooting
| Problem | What to do |
|--------|------------|
| **Output doesn’t match schema** | Tighten the prompt (e.g. “Return only valid JSON with these keys”) and confirm the schema matches the keys you expect. Re-run and check logs. |
| **Invalid or truncated JSON** | Increase max tokens if the response is cut off; ask the model to return only the JSON object, no markdown or extra text. |
| **Wrong model or credentials** | In the node config, verify the selected model and that the linked credential (e.g. OpenAI key) is valid and has access. |
## Save agent configuration

Click **Load Save Config → Save as New** to save the agent’s configuration. Use **Load Configuration** in another agent or Flow to reuse it.
## Low-code example
```yaml
nodes:
- nodeId: JSONAgent_774
nodeType: JSONAgent
nodeName: Structured JSON Generator
values:
schema: |-
{
"type": "object",
"properties": {
"destination": { "type": "string" },
"description": { "type": "string" },
"recommended_activities": {
"type": "array",
"items": { "type": "string" }
}
}
}
promptTemplate: "Generate structured JSON for ${{triggerNode_1.output.topic}}"
generativeModelName:
provider_name: mistral
type: generator/text
credential_name: Mistral API
credentialId: 32bf5e3b-a8fc-4697-b95a-b1af3dcf7498
model_name: mistral/mistral-large-2402
needs:
- triggerNode_1
```
## Output schema
The node returns your custom fields plus a `_meta` object with token usage and model info.
- **`_meta`** — Metadata for the request: `prompt_tokens`, `completion_tokens`, `total_tokens`, `model_name`, `model_provider`, and optional `prompt_tokens_details` / `completion_tokens_details`.
### Example output
```json
{
"name": "Adelaide",
"_meta": {
"prompt_tokens": 56,
"completion_tokens": 7,
"total_tokens": 63,
"model_name": "gpt-4-turbo",
"model_provider": "openai"
}
}
```
For full token-detail fields, see the [GraphQL response](/docs/interface/graphql) docs.
## Debugging
- Check **Flow logs** in Studio for the run and the failing node.
- Verify the **API key** (or model credential) used by the node is valid and has access to the chosen model.
---
# Multi Modal Agent
Source: https://lamatic.ai/docs/agents/multi-modal-agent.md
# Multi Modal Agent
The **Multi Modal Agent** is an AI-powered multi modal content generator that creates text and images programmatically based on user-defined prompts and parameters.
It integrates seamlessly into flow and supports generative AI models like OpenAI’s `GPT-4-Turbo`. This agent is useful for applications requiring automated visual content creation, such as marketing, e-commerce, and personalized graphics.

## Why Use the Multi Modal Agent?
- **AI-Generated Visuals:** Automatically generate images using state-of-the-art models.
- **AI Text Generation:** Generate text outputs based on custom prompts.
- **Customizable Prompts:** Define prompts to create images tailored to specific needs.
- **Workflow Integration:** Seamlessly connect content generation to automated processes.
- **Flexible Model Selection:** Choose from multiple AI models for diverse visual outputs.
## Key Features
**Core Functionalities**
1. **AI-Powered Image Generation** – Generate images based on custom prompts.
2. **Customizable Prompt Templates** – Define input instructions to control image style and content.
3. **Generative Model Selection** – Select the AI model and configure API credentials.
4. **Scalability** – Automate multi modal content creation within flow for efficiency.
**Advantages**
1. **Flexibility** – Supports multiple AI models, enabling a wide range of visual styles.
2. **User-Friendly Design** – Intuitive interface for prompt customization and model selection.
3. **Time-Saving Automation** – Generate images on demand without manual intervention.
4. **Enhanced Creativity** – Explore unique visual outputs for various applications.
## What Can I Build?
- **Automated Social Media Content Creation** – Generate visuals for social media, marketing, and branding.
- **Personalized Image Recommendations** – Create custom images based on user preferences.
- **Dynamic Visual Content Generation** – Produce images for e-commerce, advertising, and design.
- **Interactive Applications** – Develop tools for image-based user interactions and feedback.
## How to Use the Multi Modal Agent?
### Creating an Multi Modal Agent via Flow Editor
1. **Add an Multi Modal Agent Node** – Select the **Multi Modal Agent** from the node list.
2. **Configure Prompts** – Define text prompts for generating specific visuals.
3. **Select an AI Model** – Choose a generative model such as gpt-4-turbo
4. **Customize Output Settings** – Adjust resolution, style, and other parameters.
5. **Connect & Deploy** – Integrate the Multi Modal Agent into your workflow and execute.
### Creating an Multi Modal Agent via Agent Dashboard
1. **Go to the Agents Page** – Click **New Agent**.
2. **Choose Multi Modal Agent** – Select from available agent types.
3. **Configure Model & Prompts** – Set up AI credentials and parameters.
4. **Deploy & Integrate** – Save and start using the agent in your application.
## Configuration Options
| **Parameter** | **Description** | **Example Value** |
|---------------------------|----------------------------------------------------------------------------------------------------------------|-------------------------------|
| **Prompts** | Define the prompts for system, user and assistant to be used for the LLM | `System Prompt, User Prompt` |
| **Models** | Selects the AI model for text generation. | `GPT-4 Turbo` |
| **Tools** | Tools which can be added to the agent for additional processing of the generated text. | `Instagram API` |
| **Attachments** | Additional files or data to be used by the agent for generating the output. | `image.jpg` |
| **Messages** | System messages to guide the agent's behavior. | `[{'user' : 'create a post on the topic : roaming NYC streets'}]` |
| **Memory** | Retains context across iterations. | `[{'sessionID' : '1234','context' : 'roaming NYC streets'}]` |
## Save Agent Configuration

You can save the configuration of any agent by clicking on the `Load Save Config` button and selecting `Save as New`.
This will save the configuration of the agent and you can use it later by clicking on the `Load Configuration` button in other agents.
## Low-Code Example
```yaml
nodes:
- nodeId: MultiModalAgent_135
nodeType: MultiModalAgent
nodeName: AI Insta Post Generator
values:
promptTemplate: "Create an image and caption for the topic : ${{triggerNode_1.output.topic}}"
imageGenModelName:
provider_name: openai
type: generator/image
credential_name: OpenAI_Key
credentialId: b552a29b-69b6-4951-84c3-a6555bb132d1
model_name: gpt-4-turbo
needs:
- triggerNode_1
- nodeId: plus-node-addNode_401321
nodeType: addNode
nodeName: ""
values: {}
needs:
- MultiModalAgent_135
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ------------------------------------------------------------ |
| **Invalid API Key** | Ensure the API key is correct and has not expired. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# Supervisor Agent
Source: https://lamatic.ai/docs/agents/supervisor-agent.md
# Supervisor Agent
The **Supervisor Agent** is a specialized AI agent in Lamatic.ai designed to manage and coordinate multi-agent flow. It serves as the central hub, collecting input, maintaining structured memory, and orchestrating the execution of sub-agents based on predefined logic. This ensures an efficient, iterative process for dynamic AI-powered applications such as structured decision-making systems and task automation.

## Why Use the Supervisor Agent?
- **Orchestrate Complex AI Flow:** Manage multiple agents dynamically, ensuring structured execution.
- **Maintain Context and Memory:** Retain past interactions to improve continuity in multi-step tasks.
- **Enable Adaptive Execution:** Define agent paths, loop conditions, and AI-generated decision trees.
## Key Features
**Core Functionalities**
1. **Multi-Agent Coordination** - Dynamically routes tasks across multiple agents.
2. **Memory Retention** - Remembers previous interactions, reducing redundant queries.
3. **Agent Path Definition** - Supports branching logic for flexible flow.
4. **Loop Control** - Enables iterative execution with stopping conditions.
**Advantages**
1. **Scalability** - Supports multiple sub-agents, allowing complex flow to scale.
2. **Efficient Context Handling** - Reduces repetitive data collection by recalling previous user inputs.
3. **Adaptive Decision-Making** - Executes different branches based on AI responses.
4. **Visual Workflow Representation** - Provides a structured layout of multi-agent execution paths.
## How to Use the Supervisor Agent?
### Creating a Supervisor Agent via Flow Editor
1. **Add an Agent Node** - Select **Supervisor Agent** from the node list.
2. **Define Agent Paths** - Set up branches for different sub-agents.
3. **Configure Prompt Templates** - Customize how the agent interacts with users and sub-agents.
4. **Select an LLM Model** - Choose the AI model for text generation.
5. **Set Loop & Stop Conditions** - Define execution limits to prevent infinite loops.
6. **Deploy & Connect** - Integrate the agent into the flow and execute the workflow.
### Creating a Supervisor Agent via Agent Dashboard
1. **Navigate to the Agents Page** - Click "New Agent."
2. **Select Supervisor Agent** - Choose it from the available agent types.
3. **Configure Agent Settings** - Adjust memory, iteration limits, and agent paths.
4. **Deploy the Agent** - Save and activate it in your workflow.
## Configuration Options
| **Parameter** | **Description** | **Example Value** |
|----------------------|-------------------------------------------------------------|-------------------|
| **Prompts** | Set system, user, and assistant prompts. | `System Prompt, User Prompt` |
| **Models** | Selects the AI model for text generation. | `GPT-4 Turbo` |
| **Tools** | Tools which can be added to the agent for additional processing of the generated text. | `Sentiment Analysis` |
| **Agent Paths** | Define execution paths for multiple sub-agents. | `Research Agent, Writer Agent` |
| **Messages** | System messages to guide the agent's behavior. | `[{'user' : 'give me a write up for the topic : Claude vs GPT 4'}]` |
| **Stop Words** | Specifies trigger words to halt execution. | `"end"` |
| **Max Iterations** | Sets the maximum loops before termination. | `5` |
## Agent Path Configuration
The Supervisor Agent allows you to define different execution paths for specialized sub-agents. Each agent path represents a distinct functionality or responsibility within your workflow.
### Configuring Agent Paths
For each agent path, you'll need to define three key components:
1. **Agent Name**: A descriptive identifier for the sub-agent's role (e.g., "Researcher", "Writer", "Editor")
2. **Agent Description**: A clear explanation of the sub-agent's purpose and responsibilities
3. **Agent Schema**: A structured JSON schema defining the expected output format from the agent
### Defining Agent Schema
The agent schema uses a JSON structure to specify the format and requirements for the agent's output. In the example shown:
```json
{
"research": {
"type": "string",
"required": true,
"description": "This implies the final research fetched by the research team, which is supposed to be passed to the writing team"
}
}
```
This schema defines:
- A field named `research` that will store the agent's output
- The data type is specified as `string`
- The field is marked as `required` (true)
- A description that explains the purpose and usage of this data
### Visual Schema Builder
Lamatic.ai provides a visual schema builder to easily define your agent path configurations:
1. **Field Name**: Enter the output field name (e.g., "research")
2. **Data Type**: Select the appropriate type (string, number, boolean, etc.)
3. **Required**: Toggle whether the field is mandatory
4. **Description**: Add explanatory text to clarify the field's purpose
By properly configuring your agent paths, you enable the Supervisor Agent to effectively route tasks, maintain context, and orchestrate complex flow across multiple specialized agents.
## Save Agent Configuration

You can save the configuration of any agent by clicking on the `Load Save Config` button and selecting `Save as New`.
This will save the configuration of the agent and you can use it later by clicking on the `Load Configuration` button in other agents.
## Low-Code Example
```yaml
nodes:
- nodeId: agentNode_960
nodeType: agentNode
nodeName: Supervisor
values:
tools: []
agents:
- name: Research
schema: {}
description: Agent 1 description
- name: Writer
schema: {}
description: Agent 2 description
prompts:
- id: 9ed337ec-a4c0-4885-9066-f2853347d20b
role: system
content: >-
Research on the topic {{triggerNode_1.output.topic}} and pass on
your search to the writer to generate the ideal text.
messages: '[]'
stopWord: 'end'
connectedTo: agentLoopEndNode_242
maxIterations: 5
generativeModelName:
type: generator/text
model_name: gpt-4o-mini-2024-07-18
credentialId: f6930a0d-9947-472c-b64b-2244a131cad0
provider_name: openai
credential_name: OPEN_AI_KEY
needs:
- triggerNode_1
- agentLoopEndNode_242
connections:
- condition: Research
value: webSearchNode_852
type: conditionEdge
invisible: false
- condition: Writer
value: LLMNode_238
type: conditionEdge
invisible: false
- condition: Agent Loop End
value: agentLoopEndNode_242
type: agentLoopEdge
invisible: true
```
## Output
### output
- A nested object containing the output generated by the Supervisor Node. This depends and modifies based on the
paths and agents defined in the configuration.
### Example Output
```json
{
“output”: {
"Research": {
"output": "Research on the topic Bali and pass on your search to the writer to generate the ideal text."
},
"Writer": {
"output": "The text generated by the writer based on the research is..."
}
}
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ----------------------------------------------------------------- |
| **Invalid API Key** | Ensure the API key is correct and has not expired. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# Text Agent
Source: https://lamatic.ai/docs/agents/text-agent.md
# Text Agent
The **Text Agent** is a generative AI agent that enables users to programmatically create text-based outputs using prompts and selected LLMs. It is ideal for applications requiring dynamic content generation, such as chatbots, content creation, automated reporting, and structured AI responses.

## Why Use the Text Agent?
- **AI-Powered Content Generation:** Automate text creation for various use cases.
- **Customizable AI Responses:** Define system and user prompts for precise output.
- **Flexible Model Selection:** Choose from different LLM providers based on your needs.
- **Seamless Integration:** Connect with flow for automated processing.
## Key Features
**Core Functionalities**
1. **Generative Model Selection** – Choose from multiple LLM providers and configure API credentials.
2. **Customizable Prompts** – Define user and system prompts for tailored AI responses.
3. **System Prompt Definition** – Guide AI behavior with context-aware instructions.
4. **Advanced Properties Management** – Fine-tune outputs with additional configuration options.
**Advantages**
1. **Flexibility** – Supports multiple LLMs, enabling diverse AI-powered applications.
2. **User-Friendly Interface** – Easily configure prompt settings for quick deployment.
3. **Enhanced Control** – Customize AI behavior through structured prompt templates.
4. **Scalability** – Reuse and adapt prompt templates for various flow.
## What Can I Build?
- **Automated Content Generation** – AI-powered writing for blogs, social media, and marketing.
- **Chatbots & Virtual Assistants** – Dynamic, context-aware conversational agents.
- **Automated Reports & Summaries** – AI-driven data analysis and business intelligence reporting.
- **Email & Message Drafting** – Smart communication tools for efficiency and personalization.
## How to Use the Text Agent?
### Creating a Text Agent via Flow Editor
1. **Add a Text Agent Node** – Select the **Text Agent** from the node list.
2. **Configure Prompts** – Define system-level and user prompts.
3. **Select an LLM Model** – Choose an AI model for text generation.
4. **Customize Output Settings** – Adjust properties for response formatting.
5. **Connect & Deploy** – Integrate the Text Agent into your workflow and execute.
### Creating a Text Agent via Agent Dashboard
1. **Go to the Agents Page** – Click **New Agent**.
2. **Choose Text Agent** – Select from available agent types.
3. **Configure Model & Prompts** – Set up LLM credentials and prompt templates.
4. **Deploy & Integrate** – Save and start using the agent in your application.
## Configuration Options
| **Parameter** | **Description** | **Example Value** |
|---------------------------|----------------------------------------------------------------------------------------------------------------|-------------------------------|
| **Prompts** | Define the prompts for system, user and assistant to be used for the LLM | `System Prompt, User Prompt` |
| **Models** | Selects the AI model for text generation. | `GPT-4 Turbo` |
| **Tools** | Tools which can be added to the agent for additional processing of the generated text. | `Sentiment Analysis` |
| **Messages** | System messages to guide the agent's behavior. | `[{'user' : 'give me a write up for the topic : Claude vs GPT 4'}]` |
| **Memory** | Retains context across iterations. | `[{'sessionID' : '1234','context' : 'Claude vs GPT 4'}]` |
## Save Agent Configuration

You can save the configuration of any agent by clicking on the `Load Save Config` button and selecting `Save as New`.
This will save the configuration of the agent and you can use it later by clicking on the `Load Configuration` button in other agents.
## Output
### `_meta`
- A nested object containing metadata about the processing of the text generation request.
- **`prompt_tokens`**: Number of tokens in the input prompt.
- **`completion_tokens`**: Number of tokens in the generated output.
- **`total_tokens`**: Sum of `prompt_tokens` and `completion_tokens`.
- **`prompt_tokens_details`**: Breakdown of token usage in the prompt.
- **`cached_tokens`**: Tokens reused from cache.
- **`audio_tokens`**: Tokens from audio input (if applicable).
- **`completion_tokens_details`**: Breakdown of token usage in the generated output.
- **`reasoning_tokens`**: Tokens used for reasoning.
- **`audio_tokens`**: Tokens from audio output (if applicable).
- **`accepted_prediction_tokens`**: Tokens from accepted predictions.
- **`rejected_prediction_tokens`**: Tokens from rejected predictions.
- **`model_name`**: Name of the AI model used for text generation.
- **`model_provider`**: The provider or organization supplying the model.
### `generatedResponse`
- A string containing the text output generated by the model based on the input prompt.
### Example Output
```json
{
"_meta": {
"prompt_tokens": 19,
"completion_tokens": 212,
"total_tokens": 231,
"prompt_tokens_details": {
"cached_tokens": 0,
"audio_tokens": 0
},
"completion_tokens_details": {
"reasoning_tokens": 0,
"audio_tokens": 0,
"accepted_prediction_tokens": 0,
"rejected_prediction_tokens": 0
},
"model_name": "gpt-4-turbo",
"model_provider": "openai"
},
"generatedResponse": "Response"
}
```
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------------ | ----------------------------------------------------------------- |
| **Invalid API Key** | Ensure the API key is correct and has not expired. |
| **Dynamic Content Not Loaded** | Increase the `Wait for Page Load` time in the configuration. |
### Debugging
1. Check Lamatic Flow logs for error details.
1. Verify API Key.
---
# Benchmarks
Source: https://lamatic.ai/docs/models/benchmark.md
# Benchmarks
At the core of any powerful gen AI application is a large language model that can understand and generate human-like text. On Lamatic.ai, you have the flexibility to integrate and leverage LLMs from a variety of leading providers.
But with so many options available, how do you choose the right model for your use case? Lamatic.ai provides a robust benchmarking capability to objectively evaluate and compare model performance.
## Recommended Benchmarks
### [Artificial Analaysis](https://artificialanalysis.ai/#summary)
## Choosing Wisely
With objective benchmarking data, rich model insights, and built-in experimentation capabilities, Lamatic.ai empowers you to make highly informed decisions when selecting LLM models.
Thoroughly vetting model performance allows you to optimize for the criteria that matter most - quality, capability fit, cost efficiency, safety, and more. The right model choice is critical for delivering intelligent and delightful user experiences.
---
# Custom Model Integration
Source: https://lamatic.ai/docs/models/custom-model-integration.md
# Custom Model Integration
With Lamatic, you can define custom models per provider — this doc walks through how to add, override, and control model behavior across different AI backends.
---
Custom models offer control and flexibility, enabling better experimentation and enterprise-level customization.
We introduced this feature to:
- Support **internal/fine-tuned models** hosted privately
- Allow per-provider **override of default logic**
- Improve **model testing and validation** with custom credentials
- Support **multi-tenant use cases** with separate model handling
---
## Add Custom Models

To add a model:
1. Select a **provider** (e.g. `OpenAI`, `Orai`, `Lamatic`)
2. Click **Add Custom Model**
3. Enter:
- **Model Name** (e.g., `gpt-4.1A-private`)
- **Model Type** (Chat, Completion, Embeddings, or Image Generation)
4. Save
If added, this model will be used for:
- Credential validation
- Inference calls
- Testing
---
## Update Custom Models

You can modify:
- **Model Name**
- **API Key**
> 🛑 Note: The **Provider** field cannot be edited once set.
---
## Delete Custom Models
You can remove a model by clicking **Delete**.
If no custom model exists, the platform uses **provider defaults**.
---
## Use Cases
| Use Case | Description |
|-----------------------|---------------------------------------------|
| Enterprise override | Use internal model deployments securely |
| Staging test | Try new models without changing production |
| Multi-provider fallback | Combine OpenAI + Orai with routing logic |
| Fine-tuned models | Specialized logic for narrow domains |
You can use custom models across any supported provider without altering your primary config.
---
# Model Config
Source: https://lamatic.ai/docs/models/model-config.md
# Model Config

Model Config play a crucial role in fine-tuning the behavior of Large Language Models (LLMs). They help control aspects such as creativity, coherence, repetition, and response length, ensuring that the model generates outputs tailored to specific use cases. Properly configuring these parameters can significantly impact the quality and relevance of the generated text.
## 1. Temperature
- Controls the randomness of responses.
- **Higher values (e.g., 1.0-1.5)** → More creative and diverse responses.
- **Lower values (e.g., 0.2-0.5)** → More focused and deterministic outputs.
## 2. Seed
- Sets a fixed starting point for randomization, ensuring repeatability.
- If a specific seed is used, the model will generate the same output for the same prompt.
## 3. Frequency Penalty
- Discourages frequent word repetition.
- **Higher values (e.g., 1.0-2.0)** → Less repetition.
- **Lower values (e.g., 0-0.5)** → More repetition.
## 4. Presence Penalty
- Encourages or discourages introducing new words.
- **Higher values** → More variety in topics covered.
- **Lower values** → Tends to stick to common words.
## 5. Top P (Nucleus Sampling)
- Limits token selection to a subset of the most likely words.
- **Lower values (e.g., 0.1-0.5)** → More focused and deterministic.
- **Higher values (e.g., 0.8-1.0)** → More diverse and creative.
## 6. Logit Bias
- Adjusts the likelihood of specific words appearing.
- Can be used to make the model prefer or avoid specific words.
## 7. Stop Sequences
- Defines words/phrases where the response should stop.
- Useful for structured outputs like chatbots.
## 8. Max Tokens
- The maximum length of the generated response.
- Affects the response length.
## Additional Parameters
- Custom key-value pairs can be added for model-specific tuning.
---
# Model Logic
Source: https://lamatic.ai/docs/models/model-logic.md
# Model Logic

Model Logic provides powerful ways to wrap and extend your model node's behavior, enabling advanced control mechanisms for error handling, branching, experimentation, and performance optimization. These logic options help you build more robust, reliable, and flexible AI workflows.
> **Tip**: Model Logic is useful for error handling, branching, and experimentation. Add logic to your model nodes to enhance reliability and control flow execution.
## Overview
When configuring a model node, you can add logic to control how the model executes and handles different scenarios. The available logic options include:
- **Fallback** - Automatically switch to a backup model configuration on timeout or failure
- **Retry** - Automatically retry model execution with configurable attempts and delays
- **Parallel** - Execute multiple model configurations simultaneously
- **A/B Test** - Split traffic between two model configurations with configurable percentages
---
## 1. Fallback
Fallback logic enables automatic failover to a backup model configuration when the primary model times out or fails. This ensures your workflow continues executing even if the primary model encounters issues.
### When to Use Fallback
- When you need high availability and reliability
- When working with models that may have variable response times
- When you want to ensure your workflow doesn't fail due to model unavailability
### Configuration
When you select **Fallback**, you can configure:
- **Config A (Primary Model)** - The primary model configuration that will be attempted first
- **Config B (Fallback Model)** - The backup model configuration used if Config A fails or times out
- **Timeout** - The maximum time to wait for Config A before switching to Config B
### How It Works
1. The system attempts to execute **Config A** (your primary model configuration)
2. If Config A times out (based on your timeout setting) or fails, the system automatically switches to **Config B**
3. The result from the successful configuration (either A or B) is used to continue the workflow
> **Note**: Make sure Config B uses a different model or configuration that's more reliable or faster, even if potentially less optimal.
---
## 2. Retry
Retry logic automatically retries model execution when it fails, helping you handle transient errors and network issues gracefully.
### When to Use Retry
- When dealing with intermittent network issues or API rate limits
- When you want to automatically recover from temporary failures
- When working with models that may occasionally timeout
### Configuration
When you select **Retry**, you can configure:
- **Max Retry Attempts** - The maximum number of times to retry the model execution (e.g., 3, 5, 10)
- **Delay** - The time to wait between retry attempts (e.g., 1 second, 5 seconds)
### How It Works
1. The system attempts to execute the model
2. If the execution fails, it waits for the specified **Delay** period
3. The system retries the execution
4. This process repeats until either:
- The execution succeeds, or
- The maximum number of retry attempts is reached
> **Best Practice**: Set appropriate delay values to avoid overwhelming the model API and to respect rate limits.
---
## 3. Parallel Execution
Parallel logic executes two model configurations simultaneously, allowing you to compare results or combine outputs from different models.
### When to Use Parallel
- When you want to compare outputs from different models
- When you need to combine results from multiple model configurations
- When you want to improve performance by running models concurrently
### Configuration
When you select **Parallel**, you can configure:
- **Config A** - The first model configuration to execute
- **Config B** - The second model configuration to execute
- Both configurations execute simultaneously
### How It Works
1. Both **Config A** and **Config B** start executing at the same time
2. The system waits for both configurations to complete
3. You can access results from both configurations in subsequent nodes
4. Results are typically available as separate outputs or can be combined based on your workflow logic
> **Tip**: Parallel execution can significantly reduce total execution time when you need results from multiple models, as they run concurrently rather than sequentially.
---
## 4. A/B Testing
A/B Testing logic allows you to split traffic between two model configurations with configurable percentages, enabling you to test and compare different model setups.
### When to Use A/B Testing
- When you want to compare the performance of different model configurations
- When testing new models or prompts against existing ones
- When you need to gradually roll out new model configurations
### Configuration
When you select **A/B Test**, you can configure:
- **Config A** - The first model configuration
- **Config B** - The second model configuration
- **Traffic Split** - The percentage distribution between Config A and Config B
- **Config A Percentage** - e.g., 40% of requests go to Config A
- **Config B Percentage** - e.g., 60% of requests go to Config B
- Percentages must total 100%
### How It Works
1. For each execution, the system randomly selects Config A or Config B based on the configured percentages
2. If Config A is set to 40% and Config B to 60%:
- Approximately 40% of executions use Config A
- Approximately 60% of executions use Config B
3. Results from both configurations can be tracked and compared
4. The system maintains the traffic split distribution over time
> **Analytics**: Use the Logs and Reports tabs to analyze the performance and results of each configuration in your A/B test.
---
## Adding Model Logic to a Node
To add logic to a model node:
1. Select the model node in your flow
2. Open the **Config** tab in the right sidebar
3. Navigate to the **MODEL** section
4. Click on the **Logic** sub-tab
5. Click **+ Add Logic** button
6. Select the logic type you want to add:
- **Fallback** (clock icon)
- **Retry** (refresh icon)
- **Parallel** (parallel lines icon)
- **A/B Test** (A/B icon)
7. Configure the selected logic type with the appropriate settings
8. Save your configuration
> **Note**: You can combine multiple logic types on a single node for more complex behavior, such as using Retry with Fallback for maximum reliability.
---
## Best Practices
- **Fallback**: Always configure a reliable backup model that's faster or more stable than your primary
- **Retry**: Set reasonable retry limits and delays to avoid excessive API calls and costs
- **Go Back**: Implement safeguards to prevent infinite loops (e.g., iteration counters)
- **Parallel**: Use when you genuinely need both results, as it increases resource usage
- **A/B Testing**: Run tests for sufficient duration to gather statistically significant data
---
## Related Resources
- [Model Config](./model-config.mdx) - Learn about configuring model parameters
- [Custom Model Integration](./custom-model-integration.mdx) - Add and manage custom models
- [Node Configuration](/docs/flows/node-config) - General node configuration guide
---
# Memory Store
Source: https://lamatic.ai/docs/context/memory-store.md
# Memory Store
Lamatic's Memory Store is designed to store and manage contextual information efficiently, enabling persistent memory collections tied to unique users and sessions. This feature enhances large language models (LLMs) by providing long-term memory capabilities, allowing for more personalized and context-aware interactions.

## Key Features
1. Persistent Memory Collections: Store contextual data linked to users and sessions to improve continuity.
1. Scalability: Efficiently manage memory across multiple interactions without performance degradation.
1. Efficient Querying: Retrieve relevant contextual data quickly using optimized indexing.
## Use Cases
1. Conversational AI: Maintain session continuity for chatbots and virtual assistants.
1. Personalized Recommendations: Store user preferences to improve AI-driven suggestions.
1. Enterprise Knowledge Management: Retain historical context for collaborative applications.
1. Developer Customization: Enable developers to define custom schemas for specific use cases.
## Implementation
1. **Initialize the Memory Store:** Go to Context and select Create New Memory Store.
1. **Define a Unique Identifier:** Use a User ID, Session ID, or another unique key to link stored information.
1. **Store Contextual Data:** Utilize the [Memory Add Node](/docs/nodes/memory-add-node) to save relevant data.
1. **Retrieve Data Efficiently:** Use the [Memory Retrieve Node](/docs/nodes/memory-retrieve-node) to access stored information when needed.
1. **Access the Memory Store:** Navigate to Context and select Memory Store.

---
# Vector Store
Source: https://lamatic.ai/docs/context/vectordb.md
# Lamatic.ai built in Vector Store

At the core of many generative AI applications is the ability to store, search, and retrieve semantic vector representations of data. Lamatic.ai provides seamless integration with **Weaviate**, an open-source vector database, allowing you to easily build and scale vector storage for your use cases.
---
## Vector Store powered by Weaviate
[Weaviate](https://weaviate.io/developers/weaviate) is a cloud-native, vectorized data storage solution. It allows you to store objects (documents, images, videos, etc.) and their properties in a data schema you define.
The real power comes from Weaviate's ability to store high-dimensional vector embeddings generated from embedding models. These embeddings capture semantic representations, enabling complex filtering, searching, and nearest neighbor queries based on conceptual similarity.
> **Key Insight**: Weaviate's ability to store vector embeddings makes it perfect for AI use cases involving search and retrieval based on meaning, not just keywords.
---
## Setting Up Vector Store
On Lamatic.ai, you can provision a fully managed Weaviate instance with just a few clicks from the **"Vector Stores"** dashboard. Simply provide a name, select your desired configuration, and Lamatic.ai will handle the provisioning and scaling for you.
1. Navigate to Context
2. Click on Add New Store button
3. Select Vector Store and Provide name of the Store
4. Click on the Create Button to create new Vector Store
> **Pro Tip**: Quickly deploy a Weaviate instance and start storing vectors in minutes, without worrying about infrastructure management.
---
## Data Vectorization
A key capability is the ability to automatically vectorize your data as it gets loaded into Weaviate. Lamatic.ai supports connecting to and orchestrating different embedding models to generate high-quality vector representations.
- **Pre-trained embeddings**: For common data types like text, images, and audio.
- **Custom embeddings**: Connect your own custom embedding model for specialized needs.
> **Quick Tip**: Easily vectorize your data using either pre-trained or custom embeddings, tailored to your specific use case.
---
## Queries and Retrieval

With your data vectorized, you can use Weaviate's **GraphQL** interface to run powerful queries combining filters, where clauses, semantic searching, and more. Results are returned ranked by relevance using nearest neighbor search over the vector embeddings.
### Example Use Cases:
- Semantic text search over documents or knowledge bases
- Similarity matching for recommendation engines
- Clustering and classification of multimedia data
- Query understanding and intent matching for conversational AI
> **Did You Know?**: Lamatic.ai provides a visual query builder and templates, so you can build these queries without dealing with raw GraphQL syntax.
---
## Vector Explorer

[Lamatic.ai](http://Lamatic.ai) offers an intuitive and comprehensive Vector Explorer feature, designed to provide users with a clear view of their vector records. This powerful tool allows you to delve deep into your vector database, offering insights and analysis capabilities that can significantly enhance your understanding of your data.
To access the Vector Explorer, navigate through the following path: Context > Vector Store > [Vector Store]. Here, you'll find a user-friendly interface that displays all the vector objects you've created. This centralized view makes it easy to manage and analyze your vector data efficiently.
One of the key features of the Vector Explorer is its ability to run sample search queries. This functionality allows you to test and refine your search parameters, ensuring that your vector database is performing optimally. As you run these queries, you can examine various similarity scores, which provide valuable insights into how closely different vector objects relate to each other.
The similarity scores are particularly useful for understanding the semantic relationships between your vector objects. By analyzing these scores, you can fine-tune your vector representations, improve your search algorithms, and ultimately enhance the overall performance of your AI applications that rely on this vector data.score.
### Delete record
You can also remove the records by clicking the delete button.

## Scaling Vector Storage
Weaviate is a distributed, cloud-native database that can scale horizontally by adding more nodes. Lamatic.ai automatically handles this scaling based on your usage and performance needs.
- **Modular storage backend**: Start with localized storage and seamlessly migrate to remote object stores as your data grows to petabyte scales.
> **Scale Effortlessly**: As your data grows, Lamatic.ai automatically scales your vector storage infrastructure to meet demand.
---
---
# Mapping and Ingesting Data
Source: https://lamatic.ai/docs/context/vectordb/adding-data.md
# **Mapping and Ingesting Data into Weaviate**
To build powerful generative AI applications on [Lamatic.ai](http://lamatic.ai/), you need a way to load your data into the Weaviate vector store in a structured, vectorized format. [Lamatic.ai](http://lamatic.ai/) provides flexible data mapping tools to make this process seamless.
---
## Defining a Data Schema
Your first step is to define a schema that maps your data objects and their properties into Weaviate's data model. This schema acts as the structure for how objects will be stored and queried in the vector database.
Your Vector Store schema can be defined automatically when you index the first object inside a Vector Store. You can construct a schema by adding various keys (e.g. Article, Product, etc.), properties/fields, and mapping values to automatically define data types.
> **Tip**: Weaviate supports rich data types like text, numeric, geolocations, dates, and even pre-calculated crossRef vectors from embedding models. This flexibility allows you to map almost any structured or unstructured data source.
---
### Primary Keys
To avoid duplication of Vector Objects, you can set up primary keys. In the index node, add all the fields you would like to act as unique identifiers as an array and choose between **skip** or **overwrite**. This will automatically maintain consistent, unique vector objects.
---
## Mapping and Vectorization
With your data source connected, you can visually map the fields from the source to your defined Weaviate schema. This mapping configuration determines how data gets extracted and transformed before loading.
A key part of the mapping step is generating vector embeddings to capture semantic representations of text, images, or other data modalities. [Lamatic.ai](http://lamatic.ai/) lets you connect different embedding models from providers like Hugging Face, Anthropic, Cohere, and more.
These embeddings power the vector search and similarity capabilities in Weaviate. You can run embeddings at ingest time or pre-compute them for your data.
---
## Incremental Updates
After your initial data load, you'll likely have changes or additions to your data over time. [Lamatic.ai](http://lamatic.ai/) supports incremental updates and merges with Weaviate using change data capture, data distribution, or event sourcing patterns.
You can set up continuous data pipelines that automatically detect new data, apply your mapping logic, and load it into the vector database—keeping it up-to-date with a canonical, unified view across all your data sources.
---
## Optimized Vectorization at Scale
Under the hood, [Lamatic.ai](http://lamatic.ai/) automatically optimizes and parallelizes the vectorization and data mapping workloads. This serves to accelerate the data preparation and loading process at scale.
With [Lamatic.ai](http://lamatic.ai/)'s visual data mapping tools integrated with the fully-managed Weaviate service, you can spend less time on data wrangling and more time building innovative vector search experiences.
> **Quick Start**: Let us handle the mapping complexities while you focus on creating transformative generative AI apps!
---
# Code IDE
Source: https://lamatic.ai/docs/ide/code-ide.md
# Code IDE

Unlock the power of customization with the **Code IDE** in Lamatic flows. This feature allows you to write concise scripts or execute JavaScript directly within your flow. Whether you need to transform input data, manipulate output data, or perform preprocessing tasks, the Code IDE gives you flexible control over your workflow logic.
Use the variable editor for plain, structured input. Heading formatting support has been removed from the variable editor component.
## Key capabilities:
- Identify and merge duplicate records with custom logic
- Iterate over array objects and apply custom mappings or transformations
- Fetch external API data (e.g., currency conversion rates)
- Implement complex business logic and calculations
- Integrate with external libraries and services to extend functionality
## Code Assistant
The **Code Assistant** is an AI-powered helper that guides you through writing efficient JavaScript code in the Code IDE. Instead of starting from scratch, you can leverage the assistant to generate, refine, and optimize your code with intelligent suggestions and real-time assistance.

### Using the Code Assistant
1. **Access the Assistant**: The Code Assistant is available directly in the code editor interface. Look for the "Ask AI..." input field in the editor panel.
2. **Ask for Help**: Type your request or question in the input field. For example:
- "Create a function to filter and transform an array of objects"
- "Help me write code to merge duplicate records"
- "Add error handling to this function"
- "Explain how this code snippet works"
3. **Use Suggested Options**: The assistant provides quick-action suggestions to help you get started:
- **Basic function calling**: Generates foundational function structures for common tasks
- **Add async/await pattern**: Helps you implement asynchronous operations correctly
- **Create event handler**: Assists with event-driven code patterns
- **Add input validation**: Suggests validation logic to ensure data integrity
4. **Iterate and Refine**: The assistant can help you refine your code iteratively. After receiving a suggestion, you can ask follow-up questions or request specific modifications.
## Benefits
- **Understands Your Code**: The assistant analyzes your code context and understands what you're trying to accomplish, providing relevant suggestions
- **Suggests Improvements and Fixes**: Receive intelligent recommendations for bug fixes, performance optimizations, and code quality improvements
- **Optimizes Logic and Structure**: Get help refactoring code for better readability, maintainability, and efficiency
- **Explains Snippets and Concepts**: Learn as you code with inline explanations of code snippets, JavaScript concepts, and best practices
The Code Assistant makes JavaScript development more accessible, helping both beginners and experienced developers write high-quality, efficient code in their flows.
> **Quick Start**: Start with a basic understanding of JavaScript. The Code IDE offers syntax highlighting, auto-completion, and error checking to assist you in writing efficient code.
## Other Resources:
- [MDN JavaScript Guide](https://developer.mozilla.org/en-US/docs/Web/JavaScript/Guide) - A high-level overview of fundamental JavaScript concepts.
- [Codecademy Introduction to JavaScript](https://www.codecademy.com/learn/introduction-to-javascript) - Free interactive JavaScript course.
- [Node.js Documentation](https://nodejs.org/en/docs/) - Official Node.js documentation for runtime features used in Lamatic's Code IDE.
---
---
# GraphQL Playgrounds IDE
Source: https://lamatic.ai/docs/ide/graphql-ide.md
# GraphQL IDE

The **GraphQL IDE**, powered by GraphiQL, is a powerful tool for interacting with GraphQL APIs within Lamatic. This interactive IDE allows you to explore, test, and optimize your GraphQL queries, mutations, and subscriptions.
## Key features:
- Interactive query builder with auto-completion and syntax highlighting
- Real-time documentation explorer for your GraphQL schema
- Query result viewer with collapsible fields for easy navigation
- History of recent queries for quick reference and reuse
> **Pro Tip**: Start by exploring your schema in the documentation panel and use auto-completion for faster query writing. The IDE validates your syntax as you type.
## Other Resources:
- [GraphQL Official Documentation](https://graphql.org/learn/) - A comprehensive guide to GraphQL concepts and best practices.
- [How to GraphQL](https://www.howtographql.com/) - Free open-source tutorial for learning GraphQL.
---
---
# Prompt IDE
Source: https://lamatic.ai/docs/ide/prompt-ide.md
# Prompt IDE

Use the **Prompt IDE** to design, test, and refine prompts for your LLM nodes in one place. You can configure the model, define role-based prompt blocks (such as **System** and **User**), and run quick tests to validate output before deploying your flow.
## Writing Prompts in Text editor
The Prompt IDE supports **Text formatting** and structured prompt authoring. You can:
- Insert dynamic variables with **Insert Variable**
- Use the built-in **AI Assistant** to generate and improve prompt content
- Test prompt behavior instantly from the test panel
## Prompt Assistant
The **Prompt Assistant** is an AI-powered helper that guides you through writing effective prompts for your AI nodes. Instead of starting from scratch, you can leverage the assistant to generate, refine, and optimize your prompts with intelligent suggestions.

## Using the Prompt Assistant
1. **Access the Assistant**: The Prompt Assistant is available directly in the prompt editor interface. Look for the "Ask AI..." input field in the editor panel.
2. **Ask for Help**: Type your request or question in the input field. For example:
- "Create a system prompt for a customer support chatbot"
- "Help me write a prompt that extracts key information from user messages"
- "Improve this prompt to be more specific"
3. **Use Suggested Options**: The assistant provides quick-action suggestions to help you get started:
- **Create system prompt**: Generates a foundational system prompt based on your use case
- **Add examples**: Helps you include example interactions to guide the AI's behavior
- **Add context**: Suggests ways to incorporate relevant context into your prompts
- **Improve structure**: Refines your existing prompt for better clarity and effectiveness
4. **Iterate and Refine**: The assistant can help you refine your prompts iteratively. After receiving a suggestion, you can ask follow-up questions or request specific modifications.
## Benefits
- **Faster Prompt Creation**: Get started quickly with AI-generated prompt templates
- **Best Practices**: The assistant incorporates prompt engineering best practices automatically
- **Context-Aware Suggestions**: Receive relevant recommendations based on your specific use case
- **Learning Tool**: Understand effective prompt structures by seeing the assistant's suggestions
The Prompt Assistant makes prompt engineering more accessible, helping both beginners and experienced users create high-quality prompts for their AI nodes.
## Adding and Using Variables
To make your prompts more dynamic and context-aware, you can **insert variables** directly into your prompts. Variables allow you to personalize responses or integrate real-time data into the prompt text.

1. Click **Insert Variable** to add dynamic placeholders.
2. Choose the data source:
- **Project**: Use data specific to your project context.
- **Organization**: Pull information from your organization-level settings.
- **Secrets**: Use stored sensitive data securely.
3. Once inserted, the variable will be dynamically replaced during execution, enabling a personalized and adaptable prompt structure.

## Creating Prompts for Different User Roles
When crafting prompts, you can specify the **role** for the interaction:
- **System**: Defines the overarching instructions for the conversation.
- **User**: Represents the user’s input or request.
- **Assistant**: Controls how the AI responds based on the provided context.
To set a role:
1. Use the **Role** dropdown in the editor.
2. Select **System**, **User**, or **Assistant**.
3. Customize the prompt content accordingly to guide the AI effectively.
This feature ensures a structured and contextually relevant prompt design, improving interactions and responses.
## Key Features
- Create dynamic prompts that adapt to user input and context.
- Design conditional logic to route users through different flows.
- Implement variable placeholders for personalized content.
- Test and iterate on prompts within the IDE for optimal results.
> **Tip**: To start building custom prompts, explore our example prompts and templates. The IDE provides syntax highlighting and real-time preview to help you craft effective prompts.
## Reusing Saved Prompts in LLM Nodes

Once you’ve created and saved prompts in the Prompt IDE, you can reuse them in your **flows** when adding an **LLM Node**. This allows you to maintain a centralized library of prompts, ensuring consistency and efficiency in your AI interactions.
## How to Use Saved Prompts in LLM Nodes
1. **Add an LLM Node** to your flow.
2. Click on **Load Saved Config** to access previously created prompts.
3. Select the relevant prompt to apply it instantly.
4. The prompt will be prefilled, including all structured variables and formatting.
This feature enables seamless integration of reusable prompts, reducing redundancy and improving workflow efficiency.
## Other Resources:
- [Prompt Engineering Guide](https://platform.openai.com/docs/guides/prompt-engineering) - Learn strategies for better results from large language models.
- [Prompting Guide](https://www.promptingguide.ai/) - A comprehensive resource for learning prompt engineering techniques.
---
# Tools
Source: https://lamatic.ai/docs/mcp-tools/tools.md
# Tools
A tool is a powerful feature in the Lamatic for modern AI systems that enables seamless interaction with external functions and APIs in a structured manner. It acts as a bridge between natural language processing and programmatic actions, allowing AI models to interpret user requests and execute specific functions accordingly. This capability enhances automation, improves efficiency, and extends the AI’s ability to perform complex tasks beyond simple text-based interactions.

Tools can be added in [**Generate Text Node**](/docs/nodes/ai/generate-text-node) and [**Multimodal Node**](/docs/nodes/ai/multimodal-node)
**Tools are a mechanism that enables AI models to:**
1. Comprehend natural language input
1. Determine when a specific function should be invoked
1. Extract relevant parameters from user requests
1. Execute the appropriate function with the correct parameters
1. Present the results in a clear and meaningful manner
## What you can build
1. **AI-Powered Systems** – Enable seamless interaction with external functions and APIs in a structured manner.
1. **Natural Language Processing (NLP) Integration** – Bridge the gap between NLP and programmatic actions.
1. **Automated Task Execution** – Allow AI models to interpret user requests and execute specific functions.
1. **Enhanced Workflow Automation** – Improve efficiency by automating repetitive processes.
1. **Dynamic API Interaction** – Enable AI to call APIs, extract data, and return meaningful results.
## How to Create Tools

1. Go to Lamatic Studio
1. Navigate to Models > Tools Sections
1. Click on + Add Tool Button
1. Configure Tool by adding Name, Description, Parameters and Code
## Tool Config
### Name
The name of the tool and the name of the function associated with it. This will be used to identify the tool in the flow. The naming constraints are the same as for function names in JavaScript.
Example: `convertINRtoUSD`
### Description
A short description of the tool
Example: Convert amount from Indian Rupees (INR) to US Dollars (USD)
### Parameters

This is a JSON Schema object that describes the parameters that the tool accepts and are the ones that will be passed to the model.
Example:
```JSON
{
"amount": {
"type": "number",
"required": true,
"description": "Amount in INR to convert"
}
}
```
### Code
This is the code that will be executed when the tool is called.

**Important Notes**
1. **Reserved Variables**:
- `input` and `output` are reserved variables. Avoid overwriting them.
2. **Using Schema Variables**:
- To access variables defined in the schema, use `input.variableName`.
- Example: If the schema includes `query`, reference it as `input.query` in the function.
3. **Returning Output**:
- Assign the return value to `output` to pass data from the function.
Example
```js
const response = await fetch('https://api.exchangerate-api.com/v4/latest/INR');
const data = await response.json();
const usdRate = data.rates.USD;
const result = input.amount * usdRate;
output = result
```
## How to use Tools in the Flows

Tools can be added in [**Generate Text Node**](/docs/nodes/ai/generate-text-node) and [**Multimodal Node**](/docs/nodes/ai/multimodal-node)
To integrate tools into your flow, follow these steps:
1. Select the **Flow** where you want to use the tool.
2. Choose either **Generate Text Node** or **Multimodal Node**, then navigate to node config.
3. Select the desired tools. You can add multiple tools as needed.
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ---------------- | -------------------------------------------- |
| **Parameter** | Ensure the parameter is defined correctly. |
| **Code** | Ensure the parameter is accessed correctly in the code. |
### Debugging
1. Check the Lamatic Flow logs for error details.
2. Verify the input parameters to ensure proper configuration.
---
# Code Testing
Source: https://lamatic.ai/docs/tests/code-testing.md
# Testing Custom Code
You can test custom logic written in Code Nodes before running the entire flow.

## How to Test
- Open the Code Node in your flow
- Write or paste your logic
- Provide test inputs if required
- Click **Test** to execute the code and view results
The system will automatically:
- Show output of the code block
- Highlight errors or missing dependencies
- Optionally prompt to run prior nodes for input values
Use this to:
- Validate complex logic
- Debug syntax or runtime errors
- Iterate quickly without triggering full flow execution
---
# Flow Debugging
Source: https://lamatic.ai/docs/tests/flow-debugging.md
# Flow Debugging

Lamatic Studio provides powerful tools to help developers debug and test their flows efficiently. Use the debug mode to simulate inputs, capture outputs, and iterate quickly.
With Flow Debugging you can:
- **Save test cases** to reuse and iterate faster.
- **Inspect input, output, logs, and token usage** for each node in your flow.
- **View estimated token cost** per test run to manage expenses better.
- **Identify and fix issues precisely** — no more guessing what went wrong.
## Running Debug Mode
1. Go to your **Flow Editor**.
2. Click the **Debug** Button in the bottom right.
3. Enter your test input data (as JSON or plain text).
4. Hit **Run Test** to simulate execution.
Each test run executes the full flow using your provided input, showing node-by-node progress and output.
Each test execution visualizes:
- Node-by-node status (✅/❌)
- Real-time inputs & outputs
- Token usage breakdown
## Saving Test Cases
Click the plus (+) icon to add and save new test cases.
### To Save a Test Case:

1. Enter your input data.
2. Click the plus (+) icon
3. Give it a name (e.g., `User sign-up flow test`).
### To Reuse a Test Case:

- Select the saved test case from the **Saved Tests** dropdown and click **Run Test**.
## Debugging Output
After running a test:
- Each node will show a status: ✅ Success, ❌ Error.
- Click on any node to inspect:
- **Input received**
- **Output generated**
- **Execution time**
- **Error messages** (if any)
---
# Flow Testing
Source: https://lamatic.ai/docs/tests/flow-testing.md
# Flow Testing

Lamatic.ai allows you to validate your entire flow from start to finish before deploying it to production. It ensures all nodes execute in the intended order, inputs and outputs are correctly passed between them, and the final result matches expectations.
## Run a full flow test for end-to-end execution:
- **Execution:** Click the "Test" button and Provide Payload to execute all nodes in sequence.
- **Progress Tracking:** Observe nzode-level progress during execution.
- **Output Review:** View the final output generated at the end of the flow.
Each test run executes the full flow using your provided input, showing node-by-node progress and output.
## Trigger-Specific Testing Approaches
Different triggers require unique testing methods:
| **Trigger Type** | **Input Method** | **Testing Procedure** |
|------------------|--------------------------------|-------------------------------------------------------------------------------------|
| **API** | Sample API request payload | 1. Enter or choose the payload 2. Run the test |
| **Widget** | Sample payload or interaction | 1. Interact with the widget or enter/choose payload 2. Run the test |
| **Webhook** | Sample or actual webhook data | 1. Send data to the specified webhook or enter/choose payload 2. Run the test |
| **App** | Sample payload | 1. Perform the desired trigger event or enter/choose payload 2. Run the test |
---
# Prompt Testing
Source: https://lamatic.ai/docs/tests/prompt-testing.md
# Prompt Testing
You can test and fine-tune your prompts directly inside the AI nodes in the flow builder.

## How to Test
- **Open the Prompt Node**: Navigate to the node containing your prompt.
- **Enter Test Input**: Provide sample inputs or rely on outputs from previous nodes.
- **Click Test**: Run the prompt and evaluate its output instantly.
- **Iterate**: Update and refine your prompt for better responses.
Prompt testing is essential for:
- Validating instructions for AI behavior
- Adjusting context formatting
- Reducing hallucinations or errors before production
---
# Caching
Source: https://lamatic.ai/docs/deployments/cache.md
# Caching
At Lamatic.ai, we understand the importance of delivering high-performance and efficient GenAI applications. To achieve this, we've implemented a robust caching mechanism that leverages the power of distributed caching to optimize response times and reduce computational overhead.
## Caching GraphQL Requests and Triggers
Our caching strategy focuses on GraphQL requests and flow triggers, which are essential components of our GenAI platform. By caching these requests and triggers, we can significantly reduce the latency associated with processing and executing GenAI flow, ensuring a seamless and responsive user experience.
## User-Controlled Caching
At Lamatic.ai, we believe in empowering our users with control over their caching preferences. That's why we've introduced the ability to enable or disable caching on a per-request basis. By default, caching is enabled for all requests, but users have the flexibility to bypass caching when needed.
### Bypassing Cache
To bypass caching for a specific request, you can include the `X-Bypass-Cache` header with a value of `True` in your GraphQL request. This will instruct our platform to skip the cache and process the request directly, ensuring the most up-to-date response.
```
X-Bypass-Cache: True
```
### Disabling Cache
If you prefer to disable caching globally for your application, you can set the default caching behavior to `False`. This can be achieved by modifying the appropriate configuration settings in your Lamatic.ai account.
```
X-Bypass-Cache: False
```
## Cache Time-to-Live (TTL)
To ensure optimal performance and data freshness, Lamatic.ai employs a cache time-to-live (TTL) of 24 hours. This means that cached responses will be automatically invalidated and refreshed after 24 hours, ensuring that your GenAI applications always have access to the most up-to-date data and computations.
## Benefits of Caching
Implementing caching in Lamatic.ai offers several benefits for our users:
1. **Improved Performance**: By caching frequently accessed data and computations, we can significantly reduce response times, leading to faster and more responsive GenAI applications.
2. **Reduced Computational Overhead**: Caching helps minimize the computational resources required to process and execute GenAI flow, allowing our platform to scale more efficiently and handle higher loads.
3. **Cost Optimization**: By reducing the computational overhead, caching can help optimize the overall cost of running GenAI applications, making our platform more cost-effective for users.
4. **User Control**: Our user-controlled caching approach ensures that you have the flexibility to tailor caching behavior to your specific application requirements, balancing performance and data freshness as needed.
---
# GraphQL API
Source: https://lamatic.ai/docs/interface/graphql.md
# Executing Flows with GraphQL API
New to the API? The [Integration Guide](/docs/sdk/integration-guide) walks through your first call step by step. Come back here for the full GraphQL reference, async flows, and response shapes.
## What is GraphQL?
GraphQL is an open-source data query and manipulation language developed by Facebook. It provides a more efficient, powerful, and flexible alternative to traditional REST APIs. GraphQL allows clients to define the structure of the data they need, enabling them to retrieve precisely the information they require with a single request.
### GraphQL over REST

While REST APIs have been the industry standard for many years, they often suffer from over-fetching or under-fetching data, leading to inefficient data transfers and increased latency. GraphQL addresses these limitations by empowering clients to request only the data they need, reducing network overhead and improving performance.
## Setting up
### API Playground

Use the API Playground to test your flow and view the response in real-time.
The easies way to setup GraphQL Connection is to click the Connect bar and get the automated code for your project.
Lamatic.ai also generate automatic API documentation for your project. You can access it by visiting the API Docs section.
### Authentication with API Keys
To ensure secure access to our platform, Lamatic.ai employs API keys for authentication. When triggering flows via GraphQL, you'll need to include your API key in the request headers. This key serves as a unique identifier, granting you authorized access to our services while maintaining the integrity and confidentiality of your data.
Here's an example of how you can include the API key in your GraphQL request headers:
```
Authorization: Bearer your_api_key
```
By including the API key in the `Authorization` header, our platform can verify your identity and grant you access to trigger the desired flow.
> Click Here to know how to get your own [API Key](/docs/studio/studio-keys)
### Triggering Flows with GraphQL

Lamatic.ai's GraphQL integration allows you to trigger your GenAI flows seamlessly using GraphQL queries. This approach provides a standardized and efficient way to interact with our platform, enabling you to execute your GenAI flows on-demand or as part of larger application flows. You need to provide `YOUR_PROJECT_ID` and `LAMATIC_API_KEY`.
Here's an example GraphQL query that demonstrates how you can trigger a flow:
#### Realtime Response Type
```js
const axios = require('axios');
// Export your Lamatic API key as an environment variable
const lamatic_api_key = process.env.LAMATIC_API_KEY;
const query = `
query ExecuteWorkflow(
$workflowId: String!
$topic: String
) {
executeWorkflow(
workflowId: $workflowId
payload: {
topic: $topic
}
) {
status
result
}
}`;
const variables = {
"workflowId": "YOUR_WORKFLOW_ID",
"topic": "topic"
};
const options = {
method: 'POST',
url: 'YOUR_PROJECT_ENDPOINT',
headers: {
Authorization: `Bearer ${lamatic_api_key}`,
'Content-Type': 'application/json',
'x-project-id': 'YOUR_PROJECT_ID',
},
data: { query, variables }
};
axios(options)
.then(response => console.log(response.data))
.catch(error => console.error(error));
```
```python
import os
import requests
gqlQuery = """
query ExecuteWorkflow(
$workflowId: String!
$topic: String
) {
executeWorkflow(
workflowId: $workflowId
payload: {
topic: $topic
}
) {
status
result
}
}"""
variables = {"workflowId":"YOUR_WORKFLOW_ID","topic":"topic"}
data = {"query": gqlQuery, "variables": variables}
# Export your Lamatic API key as an environment variable
lamatic_api_key = os.getenv('LAMATIC_API_KEY')
headers = {
"Authorization": f"Bearer {lamatic_api_key}",
"Content-Type": "application/json",
"x-project-id": "YOUR_PROJECT_ID"
}
url = "YOUR_PROJECT_ENDPOINT"
response = requests.post(url, headers=headers, json=data)
if response.status_code == 200:
print(response.json())
else:
print(f"Error: {response.status_code}")
print(response.text)
```
```bash
curl -X POST \
https://testingnewflow-lamatic.stellate.sh \
-H "Authorization: Bearer ${LAMATIC_API_KEY}" \
-H 'Content-Type: application/json' \
-H 'x-project-id: YOUR_PROJECT_ID' \
-d '{ "query": " query ExecuteWorkflow( $workflowId: String! $prompt: String ) { executeWorkflow( workflowId: $workflowId payload: { prompt: $prompt } ) { status result } }", "variables": {"workflowId": "YOUR_WORKFLOW_ID", "prompt": "The excited car draws." } }'
```
#### Async Response Type
For long-running flows, set the trigger's response type to **async**. Instead of waiting for the flow to finish, the API returns immediately with a `requestId` and a status of `in-progress`, while the flow keeps running in the background. You check back later for the result.
**The request lifecycle**
```
Trigger flow (async)
↓
Immediate response: { requestId, status: "in-progress" }
↓
Flow keeps running in the background
↓
Poll checkStatus(requestId) periodically
↓
Terminal status: "success" | "error" | "failed"
```
There is currently **no way to register a webhook or callback URL** that Lamatic calls automatically when an async flow finishes. Polling `checkStatus` is the only way to retrieve the result. If you want your own server notified instead of polling, see [Pushing results to your own server](#pushing-results-to-your-own-server-instead-of-polling) below.
If you're using the [JavaScript/TypeScript SDK](/docs/sdk), its `checkStatus(requestId, pollInterval, pollTimeout)` method handles this polling loop for you, defaulting to a 15 second interval and a 15 minute timeout. See [Checking Request Status](/docs/sdk#checking-request-status).
If you're polling manually instead of using the SDK, keep requests to **no more than one every 3 seconds per IP**, polling faster risks Cloudflare rate-limiting or blocking your IP. Also bound your polling loop to the flow's maximum run time (~20 minutes on the standard async path, up to 1 hour with container mode, see [Limits & Quotas](/docs/limits)), a request won't still be `in-progress` past that.
### Pushing results to your own server instead of polling
**This is a suggested pattern, not an official Lamatic feature.** It hasn't been verified by the Lamatic team as the recommended approach, it's a reasonable use of the existing [API Node](/docs/nodes/data/api-node), which is documented and does make outbound HTTP calls, but nobody has confirmed this specific setup end-to-end. Test it yourself before relying on it in production.
Since there's no built-in callback, you can build the equivalent yourself: add an **API Node** as the last step of your async flow, and have it `POST` the result to your own server. From your server's point of view, this behaves like a webhook, your endpoint receives the result the moment the flow finishes, instead of you polling for it.
1. **Add an API Node** to your flow, after the node that produces your final result (e.g. after your LLM or response-shaping node), instead of ending on a plain Response node.
2. **Set Method to `POST`.**
3. **Set Endpoint URL** to the endpoint on your own server that should receive the result.
4. **Set Body** to map in whatever you want your server to receive, typically the request ID and the result from the upstream node, for example:
```json
{
"requestId": "{{triggerNode_1.output.requestId}}",
"result": "{{LLMNode_1.output.generatedResponse}}"
}
```
5. **(Recommended) Set Number of Retries and Delay between retry** so a transient failure to reach your server doesn't silently drop the result. See the [API Node reference](/docs/nodes/data/api-node) for the full field list.
Your server now receives a POST request with the flow's result as soon as it's ready, no polling loop required on your end.
Here's an example GraphQL query to check the status of an async request:
```js
const axios = require('axios');
// Export your Lamatic API key as an environment variable
const lamatic_api_key = process.env.LAMATIC_API_KEY;
const query = `query CheckStatus {
checkStatus(requestId: your_request_id)
}`;
const variables = {};
const options = {
method: 'POST',
url: 'YOUR_PROJECT_ENDPOINT',
headers: {
Authorization: `Bearer ${lamatic_api_key}`,
'Content-Type': 'application/json',
'x-project-id': 'YOUR_PROJECT_ID',
},
};
const response = await axios(options);
console.log(response.data);
```
```python
import os
import requests
url = "YOUR_PROJECT_ENDPOINT"
gqlQuery = """query CheckStatus {
checkStatus(requestId: your_request_id)
}"""
variables = {}
# Export your Lamatic API key as an environment variable
lamatic_api_key = os.getenv('LAMATIC_API_KEY')
headers = {
"Authorization": f"Bearer {lamatic_api_key}",
"Content-Type": "application/json",
"x-project-id": "YOUR_PROJECT_ID"
}
data = {"query": gqlQuery, "variables": variables}
response = requests.post(url, headers=headers, json=data)
if response.status_code == 200:
print(response.json())
else:
print(f"Error: {response.status_code}")
print(response.text)
```
```bash
curl -X POST \
https://testingnewflow-lamatic.stellate.sh \
-H "Authorization: Bearer ${LAMATIC_API_KEY}" \
-H 'Content-Type: application/json' \
-H 'x-project-id: YOUR_PROJECT_ID' \
-d '{ "query": " query CheckStatus( $requestId: String! ) { checkStatus( requestId: $requestId ) { status result } }", "variables": {
"requestId": "your_request_id"
} }'
```
#### Output
The Structure output can be configured in the Schema of the Graphql Response node. The expected output will be as follows:
##### Success Status
If the request is successful, the response will follow this structure:
```json
{
"data": {
"checkStatus": {
"status": "success",
"input": {
"question": "just say hi"
},
"output": {
"response": "Hi!",
"_meta": {
"prompt_tokens": 24,
"completion_tokens": 3,
"total_tokens": 27,
"prompt_tokens_details": {
"cached_tokens": 0,
"audio_tokens": 0
},
"completion_tokens_details": {
"reasoning_tokens": 0,
"audio_tokens": 0,
"accepted_prediction_tokens": 0,
"rejected_prediction_tokens": 0
},
"model_name": "gpt-4o-mini",
"model_provider": "openai"
}
},
"nodes": [
{
"input": {
"nodeName": "API Request",
"responeType": "async",
"advance_schema": "{\n \"question\": \"string\"\n}"
},
"output": {
"question": "just say hi"
},
"timeTakenInSeconds": 0,
"status": "success",
"nodeId": "triggerNode_1",
"nodeType": "graphqlNode",
"nodeName": "API Request",
"statusCode": 200
},
{
"input": {
"tools": [],
"prompts": [
{
"id": "719ebf1b-17f1-41c9-8228-4de1837583f2",
"role": "system",
"content": "You are an AI Assistant"
},
{
"id": "10005fb6-3566-41f2-bf7a-d865773e6c3a",
"role": "user",
"content": "Answer the given question: {{triggerNode_1.output.question}}"
}
],
"messages": "[]",
"nodeName": "Text Generate",
"generativeModelName": {
"type": "generator/text",
"model_name": "gpt-4o-mini",
"credentialId": "a9ecd7b5-0a47-41e0-9754-550fe9fd685b",
"provider_name": "openai",
"credential_name": "OpenAI"
}
},
"output": {
"_meta": {
"prompt_tokens": 24,
"completion_tokens": 3,
"total_tokens": 27,
"prompt_tokens_details": {
"cached_tokens": 0,
"audio_tokens": 0
},
"completion_tokens_details": {
"reasoning_tokens": 0,
"audio_tokens": 0,
"accepted_prediction_tokens": 0,
"rejected_prediction_tokens": 0
},
"model_name": "gpt-4o-mini",
"model_provider": "openai"
},
"generatedResponse": "Hi!"
},
"timeTakenInSeconds": 2.427,
"status": "success",
"nodeId": "LLMNode_746",
"nodeType": "LLMNode",
"nodeName": "Text Generate",
"statusCode": 200
},
{
"input": {
"nodeName": "API Response",
"outputMapping": "{\n \"response\": \"{{LLMNode_746.output.generatedResponse}}\",\n \"_meta\": \"{{LLMNode_746.output._meta}}\"\n}"
},
"output": {
"response": "Hi!",
"_meta": {
"prompt_tokens": 24,
"completion_tokens": 3,
"total_tokens": 27,
"prompt_tokens_details": {
"cached_tokens": 0,
"audio_tokens": 0
},
"completion_tokens_details": {
"reasoning_tokens": 0,
"audio_tokens": 0,
"accepted_prediction_tokens": 0,
"rejected_prediction_tokens": 0
},
"model_name": "gpt-4o-mini",
"model_provider": "openai"
}
},
"timeTakenInSeconds": 0,
"status": "success",
"nodeId": "responseNode_triggerNode_1",
"nodeType": "graphqlResponseNode",
"nodeName": "API Response",
"statusCode": 200
}
],
"statusCode": 200,
"timeTakenInSeconds": 2.7
}
}
}
```
##### In-Progress Status
If the request is still being processed, the response will be:
```json
{
"data": {
"checkStatus": {
"status": "in-progress",
}
}
}
```
##### Failed / Error Status
If the flow itself failed, or the request could not be processed, `status` comes back as `failed` or `error` instead of `success`:
```json
{
"data": {
"checkStatus": {
"status": "failed",
"message": "A description of what went wrong"
}
}
}
```
These are the only three terminal states, `success`, `failed`, and `error`, polling should stop as soon as you see any one of them.
In this example, the `ExecuteWorkflow` query is used to initiate a workflow execution. You'll need to provide the `workflowId` of the desired workflow and any required `payload`(Input Data) as part of the query variables.
---
# Mailhook
Source: https://lamatic.ai/docs/interface/mailhook.md
# Mailhook
Mailhook is a **trigger node** that lets you start a flow when an email is received. Any email sent to the mailhook address triggers the flow, with its metadata and content included in the payload for processing.
Use mailhooks in [Lamatic.ai](https://lamatic.ai) to build email-driven automations e.g. support ticket routing, inbox parsing, or notifications without polling or manual steps.
## Mailhook overview
- **Trigger node**: The mailhook acts as the entry point of your flow; when an email arrives, the flow runs.
- **Unique email address**: Each mailhook has a dedicated inbound email address. Messages to this address start the flow.
- **Rich payload**: Every triggered run receives the full email in the payload: metadata (from, to, subject, date, etc.) and body content, so downstream nodes can process it.
## Setting up a Mailhook
1. **Create or open a flow**
In your Lamatic dashboard, create a new flow or open an existing one.
2. **Add the Mailhook node**
In the nodes panel, search for **Mailhook** (or "mail hook") and add it as the trigger node for your flow.
3. **Get your mailhook address**
After adding the node, copy the unique email address shown for this mailhook. This is the address that will trigger the flow.
4. **Build your flow**
Add nodes after the mailhook to process the payload—e.g. parse subject/body, call an LLM, send replies, or update external systems.
5. **Deploy the flow**
Deploy the flow so the mailhook is active. Incoming emails to the mailhook address will then trigger runs.
## Payload schema
When an email triggers the flow, the mailhook node passes a payload with the following structure. Use it in later nodes or your trigger node’s output reference) to drive logic, extract data, or generate responses.
| Field | Type | Description |
| ------------ | ------ | ------------------------------------------------ |
| `webhookId` | string | Unique identifier for the mailhook. |
| `to` | string | Recipient address (the mailhook inbox). |
| `from` | string | Sender email address. |
| `subject` | string | Email subject line. |
| `text` | string | Plain-text body of the email. |
| `html` | string | HTML body of the email (if present). |
| `attachments`| array | List of attachments (e.g. files) on the email. |
Example payload:
```json
{
"webhookId": "string",
"to": "string",
"from": "string",
"subject": "string",
"text": "string",
"html": "string",
"attachments": []
}
```
## Using your Mailhook
- **Share the address**: Send the mailhook email address to users, systems, or forms that should trigger the flow (e.g. `@lamatic.dev`).
- **Monitor runs**: Check the flow **Logs** in the dashboard to see triggered runs, inspect payloads, and debug.
- **Iterate**: Adjust parsing, prompts, or integrations in the flow and redeploy; the same mailhook address keeps working.
Mailhooks give you a simple, event-driven way to turn incoming email into automated workflows on Lamatic.
---
# Webhooks
Source: https://lamatic.ai/docs/interface/webhooks.md
# Webhook Integration Guide
Webhooks are user-defined HTTP callbacks that trigger events in external systems. They allow you to automate flow by sending real-time notifications when specific events occur.

Webhooks enable asynchronous automation in [Lamatic.ai](http://Lamatic.ai), providing high-performance triggers to integrate with your applications or third-party services easily.
## Webhooks Overview
Webhooks facilitate seamless communication between systems in Lamatic. Here’s a quick breakdown of how they function:
- **Unique Identifier**: Each webhook-triggered flow has a distinct webhook ID.
- **Request Handling**: Incoming requests to this ID initiate the configured flow.
- **Flow Execution**: The flow runs predefined actions based on your setup.
If your webhook receiver is protected by a firewall or IP-based access policy,
see [IP Allowlisting](/docs/ips) before enabling production traffic.
## Setting Up Webhooks
Follow these steps to configure a webhook in Lamatic:
1. **Create a New Flow**
Begin by creating a new flow within your Lamatic dashboard.
2. **Add Webhook Node**
In the "Nodes" section, search for "webhook" and add it to your flow.
3. **Configure Endpoint**
Copy the generated webhook endpoint and select "Fetch" to activate it.
4. **Test the Webhook**
Send a sample payload or event to the endpoint to verify functionality. A webhook accepts any JSON body, whatever you send becomes the trigger node's output, available to downstream nodes as `{{triggerNode_1.output.}}`.
```bash
curl -X POST "" \
-H "Content-Type: application/json" \
-d '{
"topic": "hello world",
"source": "my-app"
}'
```
With the payload above, `{{triggerNode_1.output.topic}}` resolves to `"hello world"` anywhere later in the flow.
5. **Build Your Flow Logic**
Once the test payload is received, continue developing your flow logic based on your automation needs.
## Accessing Automatic Documentation
Lamatic automatically provides webhook documentation to streamline integration:
- **Locate Documentation**
Go to the "Install Steps" or "Setup" section in your Lamatic dashboard.
- **Review Instructions**
Use the provided documentation for step-by-step integration guidance.
## Deploying and Utilizing Webhooks
After configuring your flow, activate and start using your webhook:
1. **Deploy the Flow**
This step finalizes your webhook setup within the project.
2. **Send Requests**
Begin sending requests to your webhook endpoint to trigger the flow.
3. **Monitor Activity**
Check the "Logs" section to review incoming requests and troubleshoot as needed.
Lamatic’s webhook capabilities allow you to build robust, event-driven flow that seamlessly integrate with your systems, creating efficient automation possibilities.
---
# Ask Widget
Source: https://lamatic.ai/docs/interface/widgets/ask-widget.md
# Ask Widget
Integrate the Ask Widget into your website using the Ask Trigger node. This widget provides an AI-powered Q&A experience where users can type questions, pick from suggested prompts, and get answers with the option to follow up. You can embed this conversational interface directly on your site.

## Steps to Integrate the Ask Widget
Follow these steps to integrate the Ask Widget into your site using the provided CDN script:
### 1. Whitelist Your Domains
To use the Ask Widget, you need to whitelist the domains where you will deploy the widget. This ensures that the widget is only used on approved domains.
- **Update your `askTrigger` settings** to include the domains you plan to use (e.g. in the trigger node’s `domains` field).
- This configuration is typically done through your flow’s Ask Trigger node or admin panel.
### 2. Configure the Ask Widget
Click the Configure button in the Ask Trigger node to customize the widget: suggested questions, placeholders, policy URL, appearance, and helper text.

## General Configuration
### General configuration fields
| Field | Description | Example |
| ---------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------- |
| `suggestions` | List of suggested questions shown when the widget opens. Users can click one to send it as their first message. Press Enter to add; maximum 8 suggestions. | "How do I get started with Lamatic.ai?", "How do I create my first AI flow?" |
| `initialPlaceholder` | Placeholder text in the input field before the user types or selects a suggestion. | `Ask your message` |
| `followUpPlaceholder` | Placeholder text in the input field after a message has been sent, for follow-up questions. | `Follow up on your message` |
| `errorMessage` | Message shown when the request fails or an error occurs. | `Oops! Something went wrong. Please try again.` |
| `policyUrl` | URL to your privacy policy, linked from the widget (e.g. in the footer). Required. | `https://lamatic.ai/docs/legal/privacy-policy` |
| `showNavHelperText` | Shows "↑↓ to navigate" for keyboard navigation. | Toggle on/off |
| `showEscapeHelperText` | Shows "esc to close". | Toggle on/off |
| `hideBranding` | When `false`, shows the "Powered by Lamatic.ai" badge; when `true`, hides it. | Toggle on/off |
---
#### Appearance Configuration

#### 1. Primary Color
- **Field:** `primaryColor`
- **Purpose:** Main accent color for highlights, icons, and interactive elements (e.g. the query indicator and branding).
- **Example Value:** `#ef4444` (Red)
#### Preview
The widget shows an initial view with the input and suggestions, and after a question is sent, a conversation view with the query, response area, and follow-up input.
---
### Saving Your Settings
- After configuring your widget, click **Save** (e.g. top-right in the flow editor) to apply changes.
### 3. Include the CDN Script and Configure the Widget
Add the CDN script to your HTML and point it to your project and flow.
```html
```
### Props
| Parameter | Type | Description |
| ----------------------- | -------- | --------------------------------------------------------------------------------- |
| `PROJECT_ID` (required) | `string` | The project ID where the Ask Widget is deployed. Required for the widget to work. |
| `FLOW_ID` (required) | `string` | The workflow ID that contains your Ask Trigger configuration. Required. |
| `API_URL` (required) | `string` | The base URL of your project endpoint. Required for the widget to work. |
### Trigger node schema (Ask Trigger)
The Ask Trigger node is configured in your flow. Example structure:
```yaml
triggerNode:
nodeId: triggerNode_1
nodeType: askTriggerNode
nodeName: Ask Trigger
values:
domains:
- "*" # or list specific domains
askConfig:
suggestions:
- How do I get started with Lamatic.ai?
- How do I create my first AI flow?
- How do I use the Studio interface?
- How do I use the VectorDB feature?
- How do I add custom context to my agents?
- How do I integrate with external APIs?
primaryColor: "#ef4444"
errorMessage: Oops! Something went wrong. Please try again.
policyUrl: https://lamatic.ai/docs/legal/privacy-policy
initialPlaceholder: Ask your message
followUpPlaceholder: Follow up on your message
hideBranding: false
showNavHelperText: true
showEscapeHelperText: true
```
### Schema
The Ask Widget sends the user’s message (and any follow-ups) to your flow. Input parameters typically include:
```json
{
"message": "string",
"conversationId": "string (optional)"
}
```
The flow’s response is then rendered in the widget (e.g. as the AI reply and optional follow-up context).
---
# Chat Widget
Source: https://lamatic.ai/docs/interface/widgets/chat.md
# Chat Widget
Integrate our powerful chat widget into your website using the chat nodes. This widget leverages AI-driven conversation technology to provide interactive and context-aware responses to user queries. Now, you can offer this advanced chat functionality directly on your site.

## Steps to Integrate the Chat Widget
Follow these steps to integrate the chat widget into your site using the provided CDN script:
### 1. Whitelist Your Domains

To use the Chat Widget, you need to whitelist the domains where you will deploy the widget. This ensures that the widget is only used on approved domains.
- **Update your `chatTrigger` settings** to include the domains you plan to use.
### 2. Configure the Chat Widget
Click the Configure button in the chat widget to customize settings such as the bot name, position, image, policy URL, appearance, and messages.
#### 1. General Settings
| Field | Description |
|---------------------|-------------|
| **Bot Name** | Sets the name displayed on the chat header. _Example: `Google Drive Bot`_ |
| **Position** | Determines which side of the screen the widget appears. _Options: `Left`, `Right`_ |
| **Bot Image** | Upload a custom avatar for your bot. |
| **Policy URL** | Link to your privacy policy, shown in the footer. _Example: `https://lamatic.ai/docs/legal/privacy-policy`_ |
| **Show Powered by Lamatic** | Toggle to display or hide the "Powered by Lamatic" branding. |
---
#### 2. Appearance Settings

Customize the color scheme of your chat widget:
| Element | Example Value | Description |
|--------------------------|---------------|-------------|
| **Primary Color** | `#251d1d` | Primary UI accents and theme color. |
| **Header Background** | `#14aadB` | Background color of the chat header. |
| **Header Text** | `#FFFFFF` | Text color for the bot name in the header. |
| **User Message Background** | `#1f0ea0` | Background for messages sent by the user. |
| **User Message Text** | `#FFFFFF` | Text color inside user messages. |
| **Agent Message Background** | `#f1f5f9` | Background color of bot responses. |
| **Agent Message Text** | `#2c343f` | Text color of bot messages. |
| **Suggestion Background** | `#f1f5f9` | Background color of quick reply suggestions. |
| **Suggestion Text** | `#334155` | Text color for suggestion buttons. |
---
#### 3. Messages Configuration
Configure default messages and placeholder texts:
| Field | Description |
|---------------------|-------------|
| **Greeting Message** | Message shown when the bot first appears. _Example: `Hi, I am Lamatic Bot. Ask me anything about Lamatic`_ |
| **Error Message** | Displayed when something goes wrong. _Example: `Oops! Something went wrong. Please try again.`_ |
| **Input Placeholder**| Placeholder in the input text box. _Example: `Compose your message`_ |
| **Suggested Questions** | Add up to 3 quick-start suggestions. _Examples: `What is lamatic?`, `How do I add data to my chatbot?`_ |
---
#### 4. Preview Panel
A live preview panel is available on the right side to visualize real-time changes across all tabs.
---
#### Final Step
After customizing, don't forget to click **Save** to apply your changes.
### 3. Include the CDN Script and Configure the Widget
Add the CDN script to your HTML file and configure the widget using the provided options.
Here's how to include the CDN script and configure the widget:
```html
```
### Props
Below is the detailed documentation for the props used in the chat widget configuration:
| Parameter | Type | Description |
|------------------------|----------|--------------------------------------------------------------------------------------------------------------------------------------------------------------------|
| `PROJECT_ID` (required) | `string` | The project ID where the chat widget is deployed. This is mandatory for the widget to function correctly. |
| `FLOW_ID` (required)| `string` | The workflow ID where you have set up your chat configuration. This is also mandatory. |
| `API_URL` (required) | `string` | The base URL of your project endpoint. This is mandatory for the widget to function correctly. |
### 4. Testing
If you're using a payload, it would take the following input parameters :
```json
{
"userId": string,
"sessionId": string,
"chatMessage": string,
"chatHistory": [
{
"content": string,
"role": string,
"timestamp": string,
"sessionId": string,
}
]
}
```
The output will be given as follows :
```json
{
"output": {
"content": string,
"attachments": [],
"timestamp": string,
"type": string
}
}
```
Otherwise, click on the chat widget located at the bottom right corner of your screen to start a conversation. The widget will open, allowing you to interact with it.
### 5. Chat Widget CSS IDs Documentation
**PRO Feature**
The following CSS IDs are available only in the Pro version of the chat widget. If you are using the free version, these IDs will not be present, and you will not be able to apply custom styles using them.
| ID | Description |
| ---------------------------------- | ----------------------------------------------------------- |
| `lam-chat-header` | Main header container with logo, title, and close button |
| `lam-chat-header-logo` | Bot avatar/logo image in the header |
| `lam-chat-header-title` | Bot name/title text in the header |
| `lam-chat-header-close-button` | Close button (X) in the header |
| `lam-chat-body` | Main chat messages container with scrollable area |
| `lam-chat-message-*` | Individual message container (user or bot) |
| `lam-chat-message-avatar-*` | Bot avatar image for each bot message |
| `lam-chat-message-container-*` | Message content wrapper including bubble and timestamp |
| `lam-chat-message-bubble-*` | Message bubble container with background and styling |
| `lam-chat-user-message-content-*` | User message text content area |
| `lam-chat-bot-message-content-*` | Bot message content area with markdown rendering |
| `lam-chat-message-file-*` | File attachment container within a message |
| `lam-chat-message-timestamp-*` | Timestamp text below each message |
| `lam-chat-typing-indicator` | Container for the typing animation indicator |
| `lam-chat-typing-avatar` | Bot avatar in the typing indicator |
| `lam-chat-typing-bubble` | Typing animation bubble with dots |
| `lam-chat-image-attachment` | Image attachment container with click-to-zoom functionality |
| `lam-chat-image-skeleton` | Loading skeleton placeholder for images |
| `lam-chat-image-content` | Actual image content that replaces the skeleton |
| `lam-chat-file-attachment` | Non-image file attachment container |
| `lam-chat-file-download-link` | Download link for file attachments |
| `lam-chat-references-container` | Container for source references/sources section |
| `lam-chat-references-label` | "Sources:" label text |
| `lam-chat-references-list` | List container for all reference items |
| `lam-chat-reference-*` | Individual reference item container |
| `lam-chat-reference-title-*` | Reference title text |
| `lam-chat-reference-description-*` | Reference description text |
| `lam-chat-reference-icon-*` | External link icon for references |
| `lam-chat-citation-*` | Citation link in markdown content |
| `lam-chat-citation-badge-*` | Citation number badge styling |
| `lam-chat-markdown-link` | Regular markdown links in bot messages |
| `lam-chat-table-container` | Table wrapper with horizontal scroll |
| `lam-chat-table` | Markdown table element |
| `lam-chat-table-header` | Table header cells |
| `lam-chat-table-cell` | Table data cells |
| `lam-chat-footer` | Main footer container with input and suggestions |
| `lam-chat-suggestions-container` | Container for quick suggestion buttons |
| `lam-chat-suggestion-*` | Individual suggestion button |
| `lam-chat-input-container` | Input area container with border |
| `lam-chat-message-input` | Text input field for typing messages |
| `lam-chat-input-actions` | Container for emoji and send buttons |
| `lam-chat-emoji-section` | Emoji picker button container |
| `lam-chat-emoji-button` | Emoji picker toggle button |
| `lam-chat-send-section` | Send button container |
| `lam-chat-send-button` | Send message button |
> **Note:** The asterisk (\*) in the IDs represents a dynamic index that gets assigned to each element. For example, `lam-chat-message-0`, `lam-chat-message-1`, etc.
### Usage Examples
Here are examples of how to use these CSS IDs as selectors:
**Plain selector (targeting all elements of that type):**
```css
#lam-chat-message-bubble-* {
border-radius: 12px;
padding: 12px 16px;
}
```
**Specific index selector (targeting a specific element):**
```css
#lam-chat-message-bubble-0 {
background-color: #e3f2fd;
border-left: 4px solid #2196f3;
}
```
### 6. Troubleshooting
- Ensure the `apiUrl` is correctly set to your pod URL.
- Verify that the `workflowId` matches your workflow ID.
- Check the console for any errors related to script loading or widget initialization.
## Common Issues
### Chat Input Not Focusing When Using Material UI Drawer
If you're using Material UI's Drawer component alongside the chat widget, you might encounter an issue where the chat input cannot be focused when the Drawer is open. This happens because the Drawer's Modal behavior enforces focus within itself.
**Solution:**
Add the `disableEnforceFocus` prop to the Drawer's ModalProps:
```jsx
// Option 1: Apply to a specific Drawer instance
{/* Drawer content */}
// Option 2: Apply globally using a custom theme
const theme = createTheme({
components: {
MuiDrawer: {
defaultProps: {
ModalProps: {
disableEnforceFocus: true,
},
},
},
},
});
```
This allows the chat widget input to properly receive focus even when the Drawer is open, without affecting the overall functionality of your drawer.
This documentation provides a comprehensive guide to integrating the chat widget, including all necessary configurations and troubleshooting tips.
---
# Search Widget
Source: https://lamatic.ai/docs/interface/widgets/search.md
# Search Widget
Integrate our powerful search widget into your website using the search nodes. This widget leverages AI driven search technology to provide more accurate and relevant search results by understanding the context and meaning of the queries rather than just matching keywords. Now, you can offer this advanced search functionality directly on your site.

## Steps to Integrate the Search Widget
Follow these steps to integrate the search widget into your site using the provided CDN script:

### 1. Whitelist Your Domains
To use the Search Widget, you need to whitelist the domains where you will deploy the widget. This ensures that the widget is only used on approved domains.
- **Update your `searchTrigger` settings** to include the domains you plan to use.
- This configuration is typically done through your admin panel or server settings.
### 2. Configure the Search Widget

Click the Configure button in the search widget to customize settings such as the bot name, position, image, policy URL, appearance, and messages.
## General Configuration
### 1. Search Placeholder
- **Field:** `Search Placeholder`
- **Description:** The placeholder text that appears in the search bar before a user types.
- **Example:** `Search our knowledge base…`
### 2. Search Debounce (ms)
- **Field:** `Search Debounce (ms)`
- **Description:** Controls the delay (in milliseconds) before triggering a search after typing stops.
- **Recommended Value:** `200`
### 3. Link Target
- **Field:** `Link Target`
- **Options:**
- `Same Tab`
- `New Tab` (Recommended)
- **Effect:** Determines how links from the search results open.
### 4. Toggle Options
- `Show Navigation Helper Text` — Enables arrow key navigation tips.
- `Show Escape Helper Text` — Displays `esc to close` text.
- `Show Lamatic Banner` — Shows the "Powered by Lamatic.ai" badge.
---
### Appearance Configuration
#### 1. Primary Color
- **Field:** `Primary Color`
- **Purpose:** Sets the highlight color used for active items, selected results, and other primary UI elements.
- **Example Value:** `#007bff` (Blue)
#### 2. Secondary Color
- **Field:** `Secondary Color`
- **Purpose:** Sets the text and icon color for secondary UI elements.
- **Example Value:** `#666` (Dark Gray)
#### Preview Panel
- Displays a live preview of the search widget with applied settings.
- Tabs include: `All`, `Documentation`, `API`, `Pricing`.
---
### 3. Select an Ask flow to run
- **Field:** Ask flow (dropdown in search widget node config)
- **Description:** Select an Ask flow to run alongside the search widget. When configured, the Ask widget is available from the search widget’s dropdown menu, so users can use both search and Ask in the same interface.
- **Effect:** Enables the Ask widget to run alongside the search widget from the search widget node config dropdown.
### Saving Your Settings
- After configuring your widget, click **Save** (top-right) to apply changes.
### 2. Include the CDN Script and Configure the Widget
Add the CDN script to your HTML file and configure the widget using the provided options.
Here’s how to include the CDN script and configure the widget:
```html
```
### Props
Below is the documentation for the props used in the search widget configuration:
| Parameter | Type | Description |
|-------------------------|----------|--------------------------------------------------------------------------------------------------------------------------------------------------------------------|
| `PROJECT_ID` (required) | `string` | The project ID where the chat widget is deployed. This is mandatory for the widget to function correctly. |
| `FLOW_ID` (required)| `string` | The workflow ID where you have set up your chat configuration. This is also mandatory. |
| `API_URL` (required) | `string` | The base URL of your project endpoint. This is mandatory for the widget to function correctly. |
### Schema
The search widget/flows would take the input parameters as below:
```json
{
"searchQuery": string,
}
```
The output schema of the search widget would be as below:
```json
{
"output": [
{
"content": string,
}
],
"input": {
"link": string,
"title": string,,
"content": string,
"nodeName": string,
"breadcrumpsField": string
},
"logs": null,
"status": string
}
```
---
# Langfuse Integration
Source: https://lamatic.ai/docs/reports/langfuse-integration.md
# Langfuse Integration
At Lamatic.ai, we understand the critical role that Large Language Models (LLMs) play in powering our cutting-edge GenAI applications. To ensure optimal performance, transparency, and cost-effectiveness, we've integrated [Langfuse](https://langfuse.com/), a powerful tracing and optimization tool specifically designed for LLM interactions.

## What is Langfuse?
Langfuse is a state-of-the-art solution that provides deep insights into your LLM interactions, enabling you to monitor, analyze, and optimize the performance and cost of your GenAI applications. With Langfuse, you can unlock a new level of visibility and control over your LLM usage, empowering you to make informed decisions and continuously improve your flows.
## Integrating Langfuse
Click on the "Settings" section of your Lamatic.ai account and enable the Langfuse integration by clicking on "Connect" and enter the required credentials. You can always look up your Langfuse API keys or create new ones by navigating to Project --> Settings within Langfuse. Once enabled, Langfuse will automatically start tracing all LLM interactions within your account, providing you with real-time data and analytics to enhance your GenAI applications.
## Tracing LLM Calls with Langfuse
At Lamatic.ai, we leverage Langfuse to trace every single LLM call made within our platform. This comprehensive tracing approach ensures that you have a complete and accurate record of all LLM interactions, including input prompts, output responses, processing times, and associated costs.
By capturing this valuable data, Langfuse enables you to:
1. **Monitor Performance**: Gain insights into the performance of your LLM interactions, identifying bottlenecks, and optimizing response times.
2. **Analyze Costs**: Understand the cost implications of your LLM usage, enabling you to optimize resource allocation and control expenses.
3. **Inspect Outputs**: Review and inspect the outputs generated by LLMs, ensuring quality control and compliance with your business requirements.
4. **Identify Inefficiencies**: Pinpoint inefficient or redundant LLM calls, allowing you to streamline your flows and reduce unnecessary computational overhead.
---
# API Keys
Source: https://lamatic.ai/docs/api-integration/api-key.md
# API Keys
Lamatic uses API keys to authenticate access to its services. There are two types of API keys, each scoped to a different part of the platform.
## Project API Key
To ensure secure access to our platform, Lamatic.ai employs API keys for authentication. When triggering flows via GraphQL, you'll need to include your API key in the request headers. This key serves as a unique identifier, granting you authorized access to our services while maintaining the integrity and confidentiality of your data.

### How to Get the Project API Key
Follow these steps to create and retrieve your API key:
1. **Navigate to Studio**: Open your Lamatic.ai Studio
2. **Go to Settings**: Click on **Settings** in the navigation menu
3. **Access API Keys**: Select **API Keys** from the settings options
4. **Create New Key**: Click the **Create a New API Key** button
5. **Copy Your Key**: Once created, copy your API key immediately (you won't be able to see it again)
**Important**: Store your API key securely. If you lose it, you'll need to create a new one. After creating a new API key, make sure to redeploy your project for the changes to take effect.
### Using the Project API Key
Include your API key in the `Authorization` header of all GraphQL requests using the Bearer token format:
```js
Authorization: Bearer your_api_key
```
By including the API key in the `Authorization` header, our platform can verify your identity and grant you access to trigger the desired flow.
## Network and firewall configuration
If your application environment, API gateway, or webhook receiver uses IP-based access controls, review [IP Allowlisting](/docs/ips) to allow Lamatic traffic before moving to production.
### Next Steps
Now that you have your API key, you're ready to integrate Lamatic.ai into your application. Check out our [Integration Guide](/docs/sdk/integration-guide) for step-by-step instructions and code examples in JavaScript, Python, and cURL.
## Enterprise API Key
The Enterprise (org-level) API key (`lt-org-...`) is used for managing your Lamatic organization via the Enterprise API. It gives access to:
- Managing projects (create, delete, deploy)
- Managing flows (create, update, delete)
- Managing credentials (model keys, integrations)
- Managing contexts and deployments
- Listing resources across your org, and much more
## When to use which
| | Project API Key | Enterprise API Key |
| ---------------- | ---------------------------------------- | ------------------------------------------------- |
| **Scope** | Single project | Entire organization |
| **Prefix** | `lt-...` | `lt-org-...` |
| **Use case** | Trigger deployed flows from your app | Manage org-level resources programmatically |
| **Where to get** | Studio → Project Settings → API Keys | In Enterprise plan |
---
# API Overview
Source: https://lamatic.ai/docs/api-integration.md
# API Overview
Lamatic exposes a **GraphQL API** as the primary way to run Flows from your app, CLI, or backend. This page explains why we use GraphQL, how to authenticate, and where to find the full reference.
## Why GraphQL?
Most developer tools use REST (`POST /api/v1/flows/{id}/execute`). Lamatic uses **GraphQL** because:
- **Dynamic schemas**: The shape of inputs and outputs depends on how your Flow is configured. GraphQL lets you request exactly the fields you need and matches the response to your Flow's schema.
- **Single endpoint**: One URL per project; the operation and variables are in the request body.
- **Strong typing**: Queries and responses align with your Flow's input/output definitions.
If you're used to REST, you can think of "execute a Flow" as a single mutation: `executeWorkflow(workflowId, payload)`.
## Quick orientation
| You want to… | Go to |
|--------------------------|--------|
| Get an API key | [API Keys](/docs/api-integration/api-key) |
| Call a Flow from code | [Integration Guide](/docs/sdk/integration-guide) |
| See GraphQL operations | [GraphQL](/docs/interface/graphql) |
| Use the SDK (JS/React/Go) | [SDK](/docs/sdk) |
| Webhooks / Widgets | [Webhooks](/docs/interface/webhooks), [Widgets](/docs/interface/widgets/chat) |
## Authentication
All API requests use **Bearer token** authentication with an API key:
- **Header:** `Authorization: Bearer `
- **Project scope:** `x-project-id: `
Create and copy your API key from **Studio → Settings → API Keys**. Never commit the key; use environment variables or a secrets manager.
## Minimal example
**Prerequisites:** ``, ``, ``, and `` from Studio (project settings and the Flow's Connect/API panel).
```bash
curl -X POST "" \
-H "Authorization: Bearer " \
-H "Content-Type: application/json" \
-H "x-project-id: " \
-d '{
"query": "query ExecuteWorkflow($workflowId: String!, $payload: JSON) { executeWorkflow(workflowId: $workflowId, payload: $payload) { status result } }",
"variables": {
"workflowId": "",
"payload": { "question": "Hello" }
}
}'
```
The response includes `status` (e.g. `success`) and `result` (your Flow's output as configured in the GraphQL Response node).
## Next steps
- [Integration Guide](/docs/sdk/integration-guide): Step-by-step setup and examples in JavaScript, Python, and cURL.
- [GraphQL](/docs/interface/graphql): Full request/response shapes, async flows, and schema.
- [Error Codes](/docs/error-reference): Diagnose failed requests.
- [Limits & Quotas](/docs/limits): Rate limits and payload size.
---
# Lamatic Docs MCP
Source: https://lamatic.ai/docs/mcp/docs-mcp.md
# Lamatic Docs MCP
> Query Lamatic.ai documentation instantly from any AI assistant. No searching, no tab switching, just answers.
---
## What is the Docs MCP?
The **Lamatic Docs MCP** is a [Model Context Protocol](https://modelcontextprotocol.io) server that gives AI assistants like Claude, Cursor, and Windsurf direct access to Lamatic.ai documentation, and to the Lamatic AgentKit repository of kits, bundles, and templates.
It is powered by a RAG pipeline built entirely on Lamatic:
- **Firecrawl** scrapes the docs
- **Chunking + Vectorize** indexes them into a VectorDB
- **RAG Node** answers questions semantically
- **Next.js + Vercel** exposes the MCP endpoint publicly
The MCP is free to use. No API key or account required.
---
## Install
Pick your client and you're connected in a few seconds.
### Claude Code
```bash
claude mcp add --transport http lamatic-docs https://docmcp.lamatic.ai/api/mcp
```
### Claude Desktop, Windsurf, Cline, and other clients
Add this to your MCP client config:
```json
{
"mcpServers": {
"lamatic-docs": {
"url": "https://docmcp.lamatic.ai/api/mcp"
}
}
}
```
For Claude Desktop specifically, the config file lives at:
**macOS:** `~/Library/Application Support/Claude/claude_desktop_config.json`
**Windows:** `%APPDATA%\Claude\claude_desktop_config.json`
Restart the client after saving. You should see a 🔌 tools icon in the chat input.
---
## Available Tools
### `query_docs`
Ask any question about Lamatic.ai documentation. Uses RAG to search across all indexed docs and return a precise answer with references.
**Input:**
| Parameter | Type | Required | Description |
|-----------|------|----------|-------------|
| `text` | string | ✅ | The question to ask |
**Example:**
```json
{
"name": "query_docs",
"arguments": {
"text": "How do I set up a RAG node in Lamatic?"
}
}
```
### AgentKit tools
These call the [Lamatic AgentKit](https://github.com/Lamatic/AgentKit) repository directly through the GitHub API, so answers reflect whatever is on the repo right now rather than the indexed vector store. No authentication is required for any of these.
| Tool | What it does |
|------|---------------|
| `kit_list` | Lists every kit, bundle, and template available in AgentKit |
| `kit_get` | Returns the full details for one kit: its `lamatic.config.ts`, README, and list of flows |
| `kit_search` | Searches kits by type (kit, bundle, or template) and/or a free-text keyword |
| `kit_get_flow` | Returns the raw `.ts` source for a specific flow inside a kit |
| `kit_check_pr_status` | Checks the structural and Studio runtime validation status of an open AgentKit pull request |
A few more tools exist for people actively contributing kits — `kit_validate_structure`, `kit_auth_login`, and `kit_revalidate_pr`. These either touch your local filesystem or post GitHub comments, so they only run when you're running the server locally over stdio, never on the public hosted endpoint.
---
## How It Works
```
Your Question
↓
MCP Client (Claude / Cursor)
↓
docmcp.lamatic.ai/mcp/api
↓
Lamatic RAG Flow
↓
VectorDB (indexed Lamatic docs)
↓
Answer
```
The entire pipeline is built on Lamatic:
1. **Indexing Flow**: scrapes `lamatic.ai/docs` using Firecrawl, chunks content, vectorizes and stores in VectorDB
2. **Query Flow**: takes your question, runs semantic search, generates answer
3. **MCP Server**: Next.js API route deployed on Vercel, calls the query flow via GraphQL
---
## Supported Clients
| Client | Supported |
|--------|-----------|
| Claude Desktop | ✅ |
| Claude Code | ✅ |
| Cursor | ✅ |
| VS Code (Copilot) | ✅ |
| Windsurf | ✅ |
| Cline | ✅ |
| Any HTTP MCP client | ✅ |
---
## Source Code
The MCP is open source. You can view, fork, and contribute on GitHub:
[github.com/Lamatic/Lamatic-MCP-Docs](https://github.com/Lamatic/Lamatic-MCP-Docs)
Want to build your own Docs MCP for your company? See the [Build Your Own Docs MCP guide](/guides/tutorials/build-your-own-docs-mcp). Fork the repo, connect your own Lamatic flow, and deploy to Vercel in minutes.
---
## Other Lamatic MCP Servers
- [Graph MCP](/docs/mcp/graph-mcp): Execute your deployed Lamatic flows via AI agents
---
## Feedback
Found an issue or want to suggest an improvement?
- [Open an issue on GitHub](https://github.com/Lamatic/Lamatic-MCP-Docs/issues)
- [Join Lamatic Slack](https://lamatic.ai/slack)
- [Feature board](https://product.lamatic.ai/)
---
# Graph MCP
Source: https://lamatic.ai/docs/mcp/graph-mcp.md
# Graph MCP (Beta)
> Execute your deployed Lamatic flows via AI agents using natural language.
---
## What is it?
**Lamatic Graph MCP** is an [Model Context Protocol](https://modelcontextprotocol.io) server that turns your deployed Lamatic flows into AI-callable tools. Connect Claude, GitHub Copilot, or Cursor, and your flows become tools your AI can call directly using natural language.
---
## Install
Pick your client and you're connected in a few seconds.
After connecting, ask your AI assistant to run `graph_auth_login` with your org API key, project API key, and org ID. Nothing else works until you authenticate.
## Installation
```bash
# Run directly via npx (recommended)
npx @lamatic/graph-mcp
# Or install globally
npm install -g @lamatic/graph-mcp
# Or install as a dependency
npm install @lamatic/graph-mcp
```
---
## Setup
### Claude Code
```bash
claude mcp add lamatic-graph -- npx -y @lamatic/graph-mcp
```
### VS Code
Add to `.vscode/mcp.json`:
```json
{
"servers": {
"lamatic-graph": {
"command": "npx",
"args": ["-y", "@lamatic/graph-mcp"],
"type": "stdio"
}
}
}
```
### Claude Desktop / Cursor
Add to your MCP config file:
```json
{
"mcpServers": {
"lamatic-graph": {
"command": "npx",
"args": ["-y", "@lamatic/graph-mcp"]
}
}
}
```
---
## Authentication
Graph MCP requires two API keys: an **org-level key** and a **project-level key**.
Run the `graph_auth_login` tool:
```
authenticate with orgApiKey lt-org-xxx, projectApiKey lt-mmup-xxx and orgId your-org-id
```
Your credentials are stored locally at `~/.lamatic/config.json`.
---
## Tools
| Tool | Description |
|------|-------------|
| `graph_auth_login` | Authenticate with Lamatic |
| `graph_load_project_flows` | Load all active flows with input schemas |
| `graph_execute_flow` | Execute a deployed flow with a payload |
| `graph_refresh_flows` | Refresh the list of active flows |
---
## Supported Flow Triggers
Graph MCP can execute flows with the following trigger types:
| Trigger | Supported |
|---------|-----------|
| API Request | ✅ |
| Chat Widget | ✅ |
| Search Widget | ✅ |
| Webhook | ✅ |
---
## How It Works
1. Connect your MCP client with **org API key + project API key + org ID**
2. Run `graph_load_project_flows` to see all active flows and their input fields
3. Run `graph_execute_flow` with the flow ID and matching payload
4. The AI maps your natural language to the right flow and payload automatically
---
## Example Usage
```
show me all flows for project fcd1aa1d-...
```
```
run the Changelog flow with sampleInput "hello world"
```
```
execute the RAG flow and ask it "what is Lamatic?"
```
```
refresh my flows
```
---
## Links
- [GitHub repository](https://github.com/Lamatic/GraphMCP-Lamatic)
- [npm package](https://www.npmjs.com/package/@lamatic/graph-mcp)
- [Docs MCP](/docs/mcp/docs-mcp): Query Lamatic.ai documentation via AI
- [Dev MCP](/docs/dev-mcp): Manage Lamatic projects via AI
---
# MCP Overview
Source: https://lamatic.ai/docs/mcp.md
# MCP in Lamatic
[Model Context Protocol (MCP)](https://modelcontextprotocol.io) is an open standard for connecting AI assistants to external systems, data sources, APIs, tools, and services through one uniform interface.
Lamatic ships three MCP products, each covering a different direction of the protocol:
- **[MCP Node](/docs/mcp/mcp-node)** lets your flow consume tools from any external MCP server.
- **[Graph MCP](/docs/mcp/graph-mcp)** exposes your deployed flows as MCP tools that external AI assistants can call.
- **[Docs MCP](/docs/mcp/docs-mcp)** is a hosted MCP server that answers questions about Lamatic itself.
---
## The three MCPs
### MCP Node: consume external MCP servers
The [MCP Node](/docs/mcp/mcp-node) connects your Lamatic flow to an existing MCP server. Configure the server's URL, headers, and protocol once, and any AI node downstream can call the tools that server exposes.
**Use it when** you want your flow to call a third-party MCP server, such as a weather API, a database, or an internal tool catalog.
### Graph MCP: expose your flows as MCP tools
[Graph MCP](/docs/mcp/graph-mcp) runs in the opposite direction: it turns your deployed Lamatic flows into MCP-callable tools. Any MCP client (Claude Desktop, Cursor, VS Code, custom agents) can then invoke those flows with natural language.
**Use it when** you want an external AI assistant to drive your flows. For example, a developer in Cursor triggering a flow that generates a weekly report.
### Docs MCP: query Lamatic docs from any AI assistant
[Docs MCP](/docs/mcp/docs-mcp) is a hosted MCP server that Lamatic maintains. It indexes [lamatic.ai/docs](https://lamatic.ai/docs) into a RAG pipeline and exposes a `query_docs` tool. Any MCP client can ask natural-language questions about Lamatic and get answers with references. No setup, no API key.
**Use it when** you want your AI assistant to answer questions about Lamatic itself its nodes, agents, integrations and error messages, instead of you searching the docs manually.
---
## When to use which
| | MCP Node | Graph MCP | Docs MCP |
| -------------------- | ----------------------------------------------- | ----------------------------------------------- | ------------------------------------------------------------- |
| **Direction** | Lamatic flow → external MCP server | External MCP client → Lamatic flow | External MCP client → Lamatic-hosted docs server |
| **Role** | Client (consumer) | Server (provider) | Server (hosted by Lamatic) |
| **What you provide** | The URL of an external MCP server | A deployed flow with an API trigger | Nothing — it's hosted |
| **What you get** | External tools available inside the flow | Your flow callable from any MCP client | A `query_docs` tool that answers questions about Lamatic |
| **Typical caller** | AI nodes inside your flow | Claude Desktop, Cursor, VS Code, custom agents | Claude Desktop, Cursor, anyone reading the docs |
| **Auth model** | Headers and API keys you set on the node | Org API key + Project API key | None (free to use) |
| **Setup location** | Studio → MCP/Tools → MCP | `npx @lamatic/graph-mcp` in the client's config | Add `https://docmcp.lamatic.ai/api/mcp` to your client config |
---
## Quick chooser
- "I want my flow to use tools from an external service via MCP." → [MCP Node](/docs/mcp/mcp-node)
- "I want Claude or Cursor to call my Lamatic flow." → [Graph MCP](/docs/mcp/graph-mcp)
- "I want my AI assistant to answer questions about Lamatic itself." → [Docs MCP](/docs/mcp/docs-mcp)
- All of the above. → A flow that consumes external MCP tools (MCP Node) can itself be exposed via Graph MCP, while you use Docs MCP to ask your assistant about Lamatic as you build.
---
# MCP Node
Source: https://lamatic.ai/docs/mcp/mcp-node.md
# MCP Node
Model Context Protocol (MCP) is a standardized protocol that enables AI models to securely access external data sources and tools through a structured interface. It provides a secure, efficient, and standardized way for AI applications to interact with external resources, databases, APIs, and tools without compromising security or performance.

MCP can be integrated with [**Generate Text Node**](/docs/nodes/ai/generate-text-node)
for enhanced AI capabilities
**MCP enables AI models to:**
1. **Secure Data Access** – Safely connect to external data sources and APIs
2. **Tool Integration** – Access and utilize external tools and functions
3. **Contextual Information** – Retrieve relevant information from various sources
4. **Real-time Updates** – Access live data and dynamic content
5. **Standardized Communication** – Use a consistent protocol for all external interactions
## What you can build with MCP
1. **Data-Driven AI Applications** – Connect AI models to databases, APIs, and external data sources
2. **Real-time Information Systems** – Access live data feeds, weather updates, stock prices, and more
3. **Document Processing** – Retrieve and analyze documents from various sources
4. **API Integration** – Seamlessly integrate with third-party services and APIs
5. **Custom Tool Ecosystems** – Build and deploy custom tools that AI models can access
6. **Multi-Source Intelligence** – Combine information from multiple sources for comprehensive insights
## How to Setup MCP

1. Go to Lamatic Studio
2. Navigate to MCP/Tools > MCP
3. Click on + Add MCP
4. Configure the MCP server with the following details:
- **Credential Name**: Enter a descriptive name for your MCP server
- **Host**: Provide the MCP server URL (required field)
- **Type**: Select the protocol type (http or sse)
- **Headers**: Configure authentication and custom headers
5. Click "Test & Save" to validate the connection and save your configuration
## MCP Configuration
### Credential Name
A descriptive name for your MCP server connection. This will be used to identify the server in your flows.
Example: `MCP Server`
### Host
The endpoint URL where your MCP server is hosted. This is a required field that specifies the server address.
Example: `https://api.weatherapi.com/v1`
### Type
The protocol type for your MCP server connection. Choose between:
- **http**: Standard HTTP protocol for most API connections
- **sse**: Server-Sent Events for real-time data streaming
### Headers
Custom HTTP headers for authentication and configuration. You can add headers like:
- **Authorization**: For API key or bearer token authentication
- **Content-Type**: Specify the content type for requests
- **Custom Headers**: Any additional headers required by your MCP server
Click the "Edit" button to configure headers in JSON format:
```json
{
"Authorization": "Bearer your-api-key",
"Content-Type": "application/json"
}
```
## How to Use MCP in Flows
MCP can be integrated with [**Generate Text Node**](/docs/nodes/ai/generate-text-node)
To integrate MCP into your flow, follow these steps:
1. **Select Your Flow** – Choose the flow where you want to use MCP
2. **Add MCP Node** – Add an MCP node to your flow
3. **Configure MCP Server** – Select the MCP server you want to connect to
4. **Choose Resources/Tools** – Select the specific resources or tools you need
5. **Handle Responses** – Configure how MCP responses are processed in your flow
### MCP Node Configuration
The MCP node allows you to:
- **Select MCP Server**: Choose from your configured MCP servers
- **Access Tools**: Use tools and resources provided by the MCP server
- **Process Data**: Handle responses and integrate with other nodes in your flow
## MCP Best Practices
### Security
- Always use secure connections (HTTPS) for MCP servers
- Implement proper authentication and authorization
- Regularly rotate API keys and tokens
- Monitor and log all MCP interactions
### Performance
- Implement caching for frequently accessed data
- Use connection pooling for better performance
- Set appropriate timeouts and retry policies
- Monitor response times and optimize slow queries
### Error Handling
- Implement robust error handling for network failures
- Provide fallback mechanisms for critical data
- Log errors for debugging and monitoring
- Gracefully handle rate limiting and quota exceeded scenarios
## Troubleshooting
### Common Issues
| **Problem** | **Solution** |
| ------------------------- | -------------------------------------------------------- |
| **Connection Timeout** | Check network connectivity and increase timeout settings |
| **Authentication Errors** | Verify API keys and authentication credentials |
| **Rate Limiting** | Implement proper rate limiting and retry logic |
| **Data Format Issues** | Ensure MCP server returns data in expected format |
### Debugging
1. **Check MCP Server Logs** – Review server-side logs for connection issues
2. **Verify Configuration** – Ensure all connection parameters are correct
3. **Test Connectivity** – Use simple test calls to verify server accessibility
4. **Monitor Performance** – Track response times and identify bottlenecks
---
# Go
Source: https://lamatic.ai/docs/sdk/go.md
# Using Lamatic SDK with Go
This guide demonstrates how to integrate the Lamatic Go SDK with your Go applications to execute flows and agents.
This is a **community-built** Go SDK for the Lamatic AI platform. The SDK is maintained under the [Lamatic organization](https://github.com/Lamatic/lamatic-sdk-go) on GitHub.
## Installation
Install the Lamatic Go SDK using Go modules:
```bash
go get github.com/Lamatic/lamatic-sdk-go
```
Or if you're using the community version:
```bash
go get github.com/AasheeshLikePanner/lamatic-sdk-go
```
## Getting Started
To use the Lamatic Go SDK, you'll need:
- An API key or access token
- Your project ID
- The Lamatic API endpoint
## Basic Setup
Import the SDK in your Go code:
```go
import (
"context"
lamatic "github.com/Lamatic/lamatic-sdk-go/pkg/lamatic"
)
```
## Authentication
The SDK supports two authentication methods:
```go
package main
import (
"context"
lamatic "github.com/Lamatic/lamatic-sdk-go/pkg/lamatic"
)
func main() {
apiKey := "your-api-key"
client, err := lamatic.NewClient(lamatic.Config{
Endpoint: "your-endpoint",
ProjectID: "your-project-id",
APIKey: &apiKey,
})
if err != nil {
panic(err)
}
// Use client...
}
```
```go
package main
import (
"context"
lamatic "github.com/Lamatic/lamatic-sdk-go/pkg/lamatic"
)
func main() {
accessToken := "your-access-token"
client, err := lamatic.NewClient(lamatic.Config{
Endpoint: "your-endpoint",
ProjectID: "your-project-id",
AccessToken: &accessToken,
})
if err != nil {
panic(err)
}
// Use client...
}
```
## Executing Flows
Execute a workflow using the `ExecuteFlow` method:
```go
package main
import (
"context"
"fmt"
"log"
lamatic "github.com/Lamatic/lamatic-sdk-go/pkg/lamatic"
)
func main() {
ctx := context.Background()
apiKey := "your-api-key"
client, err := lamatic.NewClient(lamatic.Config{
Endpoint: "your-endpoint",
ProjectID: "your-project-id",
APIKey: &apiKey,
})
if err != nil {
log.Fatalf("Failed to create client: %v", err)
}
flowId := "your-flow-id"
payload := map[string]interface{}{
"prompt": "Hello, AI!",
}
resp, err := client.ExecuteFlow(ctx, flowId, payload)
if err != nil {
log.Fatalf("Error executing flow: %v", err)
}
if resp.Status == lamatic.StatusSuccess {
fmt.Printf("Result: %v\n", resp.Result)
} else {
fmt.Printf("Failed: %s\n", resp.Message)
}
}
```
## Checking Request Status
For long-running workflows or agents, you can check the status using `CheckStatus`:
```go
package main
import (
"context"
"fmt"
"log"
"time"
lamatic "github.com/Lamatic/lamatic-sdk-go/pkg/lamatic"
)
func main() {
ctx := context.Background()
apiKey := "your-api-key"
client, err := lamatic.NewClient(lamatic.Config{
Endpoint: "your-endpoint",
ProjectID: "your-project-id",
APIKey: &apiKey,
})
if err != nil {
log.Fatalf("Failed to create client: %v", err)
}
requestId := "your-request-id"
// Check status with polling interval of 2 seconds and timeout of 30 seconds
status, err := client.CheckStatus(ctx, requestId, 2*time.Second, 30*time.Second)
if err != nil {
log.Fatalf("Error checking status: %v", err)
}
if status.Status == lamatic.StatusSuccess {
fmt.Printf("Request completed: %+v\n", status.Result)
} else {
fmt.Printf("Request failed: %s\n", status.Message)
}
}
```
## Updating Access Token
If you're using access token authentication and need to update the token:
```go
// Update the access token
newToken := "new-access-token"
err := client.UpdateAccessToken(newToken)
if err != nil {
log.Fatalf("Failed to update access token: %v", err)
}
```
## Response Structure
The `ExecuteFlow` and `ExecuteAgent` methods return a response with the following structure:
```go
type Response struct {
Status string // "success", "error", or "failed"
Result interface{} // The result data from the workflow/agent (if successful)
Message string // Error message (if status is "error" or "failed")
}
```
## Error Handling
Always handle errors properly:
```go
resp, err := client.ExecuteFlow(ctx, flowId, payload)
if err != nil {
// Handle network errors, configuration errors, etc.
log.Fatalf("Error: %v", err)
}
// Check response status
if resp.Status == lamatic.StatusSuccess {
// Handle success
fmt.Printf("Success: %v\n", resp.Result)
} else if resp.Status == lamatic.StatusError || resp.Status == lamatic.StatusFailed {
// Handle execution errors
fmt.Printf("Execution failed: %s\n", resp.Message)
}
```
## Environment Variables
For better security, use environment variables:
```go
package main
import (
"context"
"log"
"os"
lamatic "github.com/Lamatic/lamatic-sdk-go/pkg/lamatic"
)
func main() {
apiKey := os.Getenv("LAMATIC_API_KEY")
projectID := os.Getenv("LAMATIC_PROJECT_ID")
endpoint := os.Getenv("LAMATIC_ENDPOINT")
client, err := lamatic.NewClient(lamatic.Config{
Endpoint: endpoint,
ProjectID: projectID,
APIKey: &apiKey,
})
if err != nil {
log.Fatalf("Failed to create client: %v", err)
}
// Use client...
}
```
## Complete Example
Here's a complete example that demonstrates executing a flow with proper error handling:
```go
package main
import (
"context"
"fmt"
"log"
"os"
lamatic "github.com/Lamatic/lamatic-sdk-go/pkg/lamatic"
)
func main() {
ctx := context.Background()
// Get credentials from environment variables
apiKey := os.Getenv("LAMATIC_API_KEY")
if apiKey == "" {
log.Fatal("LAMATIC_API_KEY environment variable is not set")
}
projectID := os.Getenv("LAMATIC_PROJECT_ID")
if projectID == "" {
log.Fatal("LAMATIC_PROJECT_ID environment variable is not set")
}
endpoint := os.Getenv("LAMATIC_ENDPOINT")
if endpoint == "" {
log.Fatal("LAMATIC_ENDPOINT environment variable is not set")
}
// Create client
client, err := lamatic.NewClient(lamatic.Config{
Endpoint: endpoint,
ProjectID: projectID,
APIKey: &apiKey,
})
if err != nil {
log.Fatalf("Failed to create client: %v", err)
}
// Execute flow
flowId := os.Getenv("LAMATIC_FLOW_ID")
payload := map[string]interface{}{
"prompt": "Generate a creative story about AI",
}
resp, err := client.ExecuteFlow(ctx, flowId, payload)
if err != nil {
log.Fatalf("Error executing flow: %v", err)
}
// Handle response
if resp.Status == lamatic.StatusSuccess {
fmt.Printf("Flow executed successfully!\n")
fmt.Printf("Result: %+v\n", resp.Result)
} else {
fmt.Printf("Flow execution failed: %s\n", resp.Message)
}
}
```
## Project Structure
The Go SDK follows standard Go project structure:
```
lamatic-sdk-go/
├── go.mod
├── README.md
├── LICENSE
├── internal/
│ └── client/
│ └── client.go # Internal HTTP client
├── pkg/
│ └── lamatic/
│ ├── lamatic.go # Public SDK API
│ └── lamatic_test.go # Unit tests
└── examples/
├── api_key/
│ └── main.go # Example: API Key auth
├── access_token/
│ └── main.go # Example: Access Token auth
├── access_token_expiry/
│ └── main.go # Example: Handling token expiry
└── token_generation/
└── main.go # Example: Server-side JWT generation
```
## Features
The Go SDK provides the following features:
- ✅ Execute Workflows (Flows)
- ✅ Execute Agents
- ✅ Job Polling with `CheckStatus`
- ✅ Support for API Key and Access Token (JWT) authentication
- ✅ Proper internal/pkg separation for Go best practices
- ✅ Context support for cancellation and timeouts
## Resources
- **GitHub Repository**: [github.com/Lamatic/lamatic-sdk-go](https://github.com/Lamatic/lamatic-sdk-go)
- **Documentation**: Check the repository README for the latest updates
- **Examples**: See the `examples/` directory in the repository for more usage examples
## Support
For help and support with the Go SDK:
- Open an issue on [GitHub](https://github.com/Lamatic/lamatic-sdk-go/issues)
- Contact [support@lamatic.ai](mailto:support@lamatic.ai)
---
# SDK & Integration Guide
Source: https://lamatic.ai/docs/sdk.md
# Lamatic SDK
Once your Flows are built and deployed, the SDK is the easiest way to call them from TypeScript, Node.js, or browser-based apps.
The [Lamatic SDK](https://github.com/Lamatic/lamatic-sdk) provides a simple way to interact with the Lamatic AI platform, allowing you to execute Flows and integrate AI capabilities into your applications.
## Installation
Install the Lamatic SDK using npm:
```bash
npm install lamatic
```
## Getting Started
To use the Lamatic SDK, you'll need:
- An API key or access token
- Your project ID
- The Lamatic API endpoint
Initialize the SDK like this:
```typescript
const lamatic = new Lamatic({
endpoint: "your-endpoint", // Required: The Lamatic API endpoint
projectId: "your-project-id", // Required: Your project ID
apiKey: "your-api-key", // Required if not using accessToken
// OR
accessToken: "your-access-token" // Required if not using apiKey
});
```
The constructor will throw an error if:
- Configuration object is not provided
- `endpoint` is missing
- `projectId` is missing
- Neither `apiKey` nor `accessToken` is provided
## Authentication
The SDK supports two authentication methods:
```typescript
const lamatic = new Lamatic({
apiKey: "your-api-key",
projectId: "your-project-id",
endpoint: "your-endpoint",
});
```
```typescript
const lamatic = new Lamatic({
accessToken: "your-access-token",
projectId: "your-project-id",
endpoint: "your-endpoint",
});
```
You must provide either an API key or an access token, but not both.
### How to obtain your API Key/Secret
1. Navigate to Project Settings in your Lamatic dashboard
2. Locate and copy your API Key/Secret from the credentials section
## API Methods
The Lamatic SDK provides the following methods:
- `executeFlow(flowId: string, payload: Object): Promise` - Execute a workflow
- `executeAgent(agentId: string, payload: Object): Promise` - Execute an agent
- `checkStatus(requestId: string, pollInterval?: number, pollTimeout?: number): Promise` - Check the status of a request with polling
- `updateAccessToken(accessToken: string): void` - Update the access token for the SDK instance
## Executing Flows
One of the main functions of the SDK is to execute Flows that you've created on the Lamatic platform.
```typescript
const lamatic = new Lamatic({
apiKey: "your-api-key",
projectId: "your-project-id",
endpoint: "your-endpoint",
});
async function main() {
const flowId = "your-flow-id";
// sample payload
const payload = {
prompt: "hey, how are you?"
}
try {
const response = await lamatic.executeFlow(flowId, payload);
console.log(response);
} catch (error) {
console.error(error);
}
}
main();
```
```typescript
const lamatic = new Lamatic({
accessToken: "your-access-token",
projectId: "your-project-id",
endpoint: "your-endpoint",
});
async function main() {
const flowId = "your-flow-id";
// sample payload
const payload = {
prompt: "hey, how are you?",
};
const response = await lamatic.executeFlow(flowId, payload);
console.log(response);
}
main();
```
### Handling Expired Access Tokens
This example shows how to handle an expired access token by fetching a new one
and updating the SDK.
```typescript
const lamatic = new Lamatic({
accessToken: "your-access-token",
projectId: "your-project-id",
endpoint: "your-endpoint",
});
async function getAccessToken() {
const response = await fetch("your-server-endpoint/get-access-token", {
method: "GET",
});
const data = await response.json();
return data.accessToken;
}
async function main() {
const flowId = "your-flow-id";
// sample payload
const payload = {
prompt: "hey, how are you?",
};
const response = await lamatic.executeFlow(flowId, payload);
console.log(response);
if (response.statusCode === 403) {
// Get the new access token
const accessToken = await getAccessToken();
// Update the access token for the Lamatic SDK
lamatic.updateAccessToken(accessToken);
// Execute the flow again
const response = await lamatic.executeFlow(flowId, payload);
console.log(response);
}
}
main();
```
Here, you are supposed to have a server endpoint that returns a new access token when called. This works for both flow and agent executions.
The server should handle the authentication and return the new access token from the same secret generated from Lamatic Studio.
### Generating an Access Token Using JWT Sign
Here's a method to create an access token using jsonwebtoken (JWT) with and without an expiration time:
```javascript
const secretKey = 'KEY'; // Secret key generated from Lamatic Studio
// Generate token without expiry
const accessToken = jwt.sign({ project_id: 'PROJECT_ID' }, secretKey, {
algorithm: 'HS256',
});
console.log('Access Token (without expiry):', accessToken);
// Generate token with expiry (e.g., 1 hour)
const accessTokenWithExpiry = jwt.sign({ project_id: 'PROJECT_ID' }, secretKey, {
algorithm: 'HS256',
expiresIn: '1h', // Change this to '1s' for testing or adjust as needed
});
console.log('Access Token (with expiry):', accessTokenWithExpiry);
```
## Response Structure
The `executeFlow` and `executeAgent` methods return a promise that resolves to a `LamaticResponse` object with the following structure:
```typescript
{
status: "success" | "error" | "failed", // Status of the workflow/agent execution
result: object | null, // The result data from the workflow/agent (if successful)
message?: string, // Error message (if status is "error" or "failed")
statusCode: number // HTTP status code
}
```
### Example with Error Handling
Here's an example of how you might handle the response from a workflow execution:
```typescript
async function runWorkflow() {
const flowId = "your-flow-id";
const payload = {
input: "Generate a creative story about robots",
parameters: {
temperature: 0.7,
maxTokens: 500,
},
};
try {
const response = await lamatic.executeFlow(flowId, payload);
if (response.status === "success") {
console.log("Workflow executed successfully!");
console.log("Result:", response.result);
return response.result;
} else if (response.status === "error" || response.status === "failed") {
console.error("Workflow execution failed:", response.message);
return null;
}
} catch (error) {
console.error("Exception occurred:", error);
return null;
}
}
```
Here we have an example of handling with agent execution:
```typescript
async function runAgent() {
const agentId = "your-agent-id";
const payload = {
input: "Generate a linkedin post about AI",
parameters: {
temperature: 0.7,
maxTokens: 500,
},
};
try {
const response = await lamatic.executeAgent(agentId, payload);
if (response.status === "success") {
console.log("Agent executed successfully!");
console.log("Result:", response.result);
return response.result;
} else if (response.status === "error" || response.status === "failed") {
console.error("Agent execution failed:", response.message);
return null;
}
} catch (error) {
console.error("Exception occurred:", error);
return null;
}
}
```
## Checking Request Status
The SDK provides a `checkStatus` method to check the status of a request with polling capability. This is useful for long-running workflows or agents that execute asynchronously.
Unlike `executeFlow` and `executeAgent`, the `checkStatus` method returns error responses instead of throwing exceptions. This allows you to handle errors without try-catch blocks, though you should still check the response status.
### Basic Usage
```typescript
const requestId = "your-request-id";
const response = await lamatic.checkStatus(requestId);
if (response.status === "success") {
console.log("Request completed:", response.result);
} else if (response.status === "error" || response.status === "failed") {
console.error("Request failed:", response.message);
}
```
### With Custom Polling Configuration
The `checkStatus` method supports custom polling intervals and timeouts:
```typescript
// Check status with custom polling interval (15 seconds) and timeout (900 seconds = 15 minutes)
const response = await lamatic.checkStatus(
requestId,
15, // pollInterval in seconds (default: 15)
900 // pollTimeout in seconds (default: 900)
);
```
### Complete Example
```typescript
const lamatic = new Lamatic({
apiKey: "your-api-key",
projectId: "your-project-id",
endpoint: "your-endpoint",
});
async function executeAndCheckStatus() {
const flowId = "your-flow-id";
const payload = {
prompt: "Generate a long report",
};
try {
// Execute the flow
const executeResponse = await lamatic.executeFlow(flowId, payload);
// If the response includes a requestId, you can check its status
if (executeResponse.result?.requestId) {
const requestId = executeResponse.result.requestId;
// Poll for status with custom configuration
// Note: checkStatus returns error responses instead of throwing
const statusResponse = await lamatic.checkStatus(
requestId,
10, // Check every 10 seconds
600 // Timeout after 10 minutes
);
if (statusResponse.status === "success") {
console.log("Request completed:", statusResponse.result);
} else if (statusResponse.status === "error" || statusResponse.status === "failed") {
console.error("Request failed:", statusResponse.message);
console.error("Status code:", statusResponse.statusCode);
}
} else {
// Request completed immediately
console.log("Immediate result:", executeResponse.result);
}
} catch (error) {
// This catch block handles errors from executeFlow, not checkStatus
console.error("Error executing flow:", error);
}
}
executeAndCheckStatus();
```
### Status Response
The `checkStatus` method returns a `LamaticResponse` object:
```typescript
{
status: "success" | "error" | "failed", // Current status (never returns "in_progress" as it polls until completion)
result: object | null, // Result data (if completed)
message?: string, // Error message (if failed or timeout)
statusCode: number // HTTP status code (408 for timeout)
}
```
The method will automatically poll until:
- The status becomes `"success"`, `"error"`, or `"failed"` (returns immediately)
- The timeout is reached (returns with `status: "error"`, `statusCode: 408`, and a timeout message)
If a timeout occurs, your request may still be executing in the background. You can check the status again after a few minutes using the same `requestId`. The timeout message will indicate this.
## Updating Access Token
If you're using access token authentication, you can update the token during runtime, if the need be:
```typescript
// Initialize with an access token
const lamatic = new Lamatic({
accessToken: "initial-access-token",
projectId: "your-project-id",
endpoint: "your-endpoint",
});
// Later, update the access token
lamatic.updateAccessToken("new-access-token");
```
## Advanced Usage
### Customizing Payloads
The payload structure depends on the specific workflow/agent you're executing. Make
sure to check the documentation for your workflow/agent to understand what
parameters it expects.
```typescript
// Example for a text generation workflow
const textGenPayload = {
prompt: "Write a poem about artificial intelligence",
options: {
temperature: 0.8,
topP: 0.95,
maxLength: 200
}
};
```
```typescript
// Example for a tweet generation agent
const tweetPayload = {
prompt: "Write a tweet about the future of technology",
options: {
maxLength: 280
}
};
```
```typescript
// Example for a classification workflow
const classifyPayload = {
text: "This is a sample text to classify",
categories: ["technology", "science", "art"]
};
```
```typescript
// Example for an image analysis agent
const imageAnalysisPayload = {
imageUrl: "https://example.com/image.jpg",
analysisTypes: ["objects", "faces", "text"]
};
```
### Handling Responses
Different flow/agents may return different result structures. Here's how you might handle responses from different types of flow/agents:
```typescript
// Text generation workflow response
const textResponse = await lamatic.executeFlow(
"text-gen-flow-id",
textGenPayload
);
if (textResponse.status === "success" && textResponse.result) {
const generatedText = textResponse.result.text;
console.log("Generated text:", generatedText);
}
// Tweet Generation agent response
const tweetResponse = await lamatic.executeAgent("tweet-gen-agent-id", tweetPayload);
if (tweetResponse.status === "success" && tweetResponse.result) {
const tweet = tweetResponse.result.tweet;
console.log("Generated tweet:", tweet);
}
// Classification workflow response
const classificationResponse = await lamatic.executeFlow(
"classify-flow-id",
classifyPayload
);
if (
classificationResponse.status === "success" &&
classificationResponse.result
) {
const category = classificationResponse.result.category;
const confidence = classificationResponse.result.confidence;
console.log(`Classification: ${category} (confidence: ${confidence})`);
}
// Image analysis agent response
const imageAnalysisResponse = await lamatic.executeAgent("image-analysis-agent-id", imageAnalysisPayload);
if (imageAnalysisResponse.status === "success" && imageAnalysisResponse.result) {
const objects = imageAnalysisResponse.result.objects;
const faces = imageAnalysisResponse.result.faces;
const text = imageAnalysisResponse.result.text;
console.log("Analysis results:", { objects, faces, text });
}
```
## TypeScript Support
The SDK is written in TypeScript and provides type definitions for all its functionality:
### Workflow Execution Example
```typescript
// Custom payload type
interface TextGenerationPayload {
prompt: string;
maxTokens?: number;
temperature?: number;
}
// Custom response type
interface TextGenerationResult {
text: string;
usedTokens: number;
}
async function generateText(
prompt: string
): Promise {
const payload: TextGenerationPayload = {
prompt,
maxTokens: 1000,
temperature: 0.7,
};
const response = await lamatic.executeFlow(
"text-gen-flow",
payload
);
if (response.status === "success" && response.result) {
return response.result as TextGenerationResult;
}
return null;
}
```
### Agent Execution Example
```typescript
// Custom payload type
interface ImageAnalysisPayload {
imageUrl: string;
analysisTypes: string[];
}
// Custom response type
interface ImageAnalysisResult {
objects: string[];
faces: string[];
text: string;
}
async function analyzeImage(imageUrl: string): Promise {
const payload: ImageAnalysisPayload = {
imageUrl,
analysisTypes: ["objects", "faces", "text"]
};
const response = await lamatic.executeAgent("image-analysis-agent", payload);
if (response.status === "success" && response.result) {
return response.result as ImageAnalysisResult;
}
return null;
}
```
## Error Handling
The SDK has different error handling behaviors:
- **`executeFlow` and `executeAgent`**: These methods throw exceptions for network errors, configuration issues, or parsing errors. They also return error responses in the `LamaticResponse` object for GraphQL errors. Always wrap these calls in try-catch blocks.
- **`checkStatus`**: This method returns error responses instead of throwing exceptions (except in rare cases). Check the response status rather than relying on try-catch.
### Workflow Execution Example
```typescript
try {
const response = await lamatic.executeFlow(flowId, payload);
// Check response status
if (response.status === "success") {
console.log("Success:", response.result);
} else if (response.status === "error" || response.status === "failed") {
console.error("Execution failed:", response.message);
console.error("Status code:", response.statusCode);
}
} catch (error) {
if (error instanceof Error) {
// Log the error
console.error("SDK Error:", error.message);
// Handle specific error scenarios
if (error.message.includes("timeout")) {
// Handle timeout
} else if (error.message.includes("network")) {
// Handle network error
} else if (error.message.includes("required")) {
// Handle configuration errors
}
}
}
```
### Agent Execution Example
```typescript
try {
const response = await lamatic.executeAgent(agentId, payload);
// Check response status
if (response.status === "success") {
console.log("Success:", response.result);
} else if (response.status === "error" || response.status === "failed") {
console.error("Execution failed:", response.message);
console.error("Status code:", response.statusCode);
}
} catch (error) {
if (error instanceof Error) {
// Log the error
console.error("SDK Error:", error.message);
// Handle specific error scenarios
if (error.message.includes("timeout")) {
// Handle timeout
} else if (error.message.includes("network")) {
// Handle network error
} else if (error.message.includes("required")) {
// Handle configuration errors
}
}
}
```
### Status Check Example
```typescript
// checkStatus returns error responses instead of throwing
const response = await lamatic.checkStatus(requestId, 15, 900);
if (response.status === "success") {
console.log("Request completed:", response.result);
} else if (response.status === "error" || response.status === "failed") {
console.error("Request failed:", response.message);
console.error("Status code:", response.statusCode);
// Handle timeout specifically
if (response.statusCode === 408) {
console.log("Request timed out. It may still be processing in the background.");
}
}
```
## Environment Variables
For better security, consider using environment variables for sensitive information:
```typescript
// Using environment variables
const lamatic = new Lamatic({
apiKey: process.env.LAMATIC_API_KEY,
projectId: process.env.LAMATIC_PROJECT_ID,
endpoint: process.env.LAMATIC_ENDPOINT,
});
```
## Python SDK
Lamatic also provides a Python SDK (`pip install lamatic`) for executing flows from Python applications, with both sync and async methods and status checking with polling.
For detailed information, installation instructions, and code examples, see the [Python SDK documentation](/docs/sdk/python).
## Go SDK
Lamatic also provides a Go SDK for integrating with Go applications. The Go SDK offers the same core functionality as the JavaScript/TypeScript SDK, with a Go-native API design that includes support for executing workflows and agents, status checking with polling, and both API key and access token authentication.
For detailed information, installation instructions, code examples, and API reference, see the [Go SDK documentation](/docs/sdk/go).
## Support
For help and support, visit our [documentation](https://docs.lamatic.ai) or contact [support@lamatic.ai](mailto:support@lamatic.ai).
---
# Integration Guide
Source: https://lamatic.ai/docs/sdk/integration-guide.md
# Integration Guide
This guide provides step-by-step instructions for integrating Lamatic.ai into your application. You can trigger workflows programmatically from any application that can make HTTP requests, including web applications, mobile apps, backend services, and serverless functions.
## Integration Overview
Lamatic.ai integrates with your application through GraphQL API endpoints. This approach provides a standardized and efficient way to interact with our platform, enabling you to execute your GenAI flows on-demand or as part of larger application flows.
## Required Information
Before integrating, gather the following information from your Lamatic Studio:
1. **API Key**: Your authentication key (from Studio > Settings > API Keys) - [Learn how to get your API key](/docs/api-integration/api-key)
2. **Project ID**: Unique identifier for your project (found in project settings)
3. **Project URL**: Your GraphQL endpoint URL (provided in your project dashboard)
4. **Workflow ID**: The ID of the specific workflow you want to trigger (visible in the workflow editor)

## Integration Steps
### Step 1: Set Up Environment Variables
Store your API key securely as an environment variable. Never hardcode credentials in your source code.
**For local development:**
- Create a `.env` file (add it to `.gitignore`)
- Add: `LAMATIC_API_KEY=your_api_key_here`
**For production:**
- Use your platform's secret management system (AWS Secrets Manager, Azure Key Vault, etc.)
- Or set environment variables in your deployment configuration
### Step 2: Install Required Dependencies
Depending on your technology stack:
- **JavaScript/Node.js**: `npm install axios` or `npm install node-fetch`
- **Python**: `pip install requests`
- **Other languages**: Use your language's standard HTTP client library
### Step 3: Configure Request Headers
Every request must include these headers:
```js
{
"Authorization": "Bearer YOUR_API_KEY",
"Content-Type": "application/json",
"x-project-id": "YOUR_PROJECT_ID"
}
```
### Step 4: Structure Your GraphQL Query
Use the `executeWorkflow` mutation with your workflow ID and payload:
```graphql
query ExecuteWorkflow($workflowId: String!, $payload: JSON) {
executeWorkflow(workflowId: $workflowId, payload: $payload) {
status
result
}
}
```
### Step 5: Map Your Data to Workflow Inputs
Ensure your payload matches the input schema defined in your workflow. Check your workflow's input variables in the Studio to ensure correct field names and types.
### Step 6: Handle Responses and Errors
Always implement proper error handling:
- Check HTTP status codes
- Parse GraphQL errors from the response
- Handle network failures gracefully
- Implement retry logic for transient failures
## Code Examples
Here's how to trigger a workflow using GraphQL in different programming languages:
**Note**: In these examples, we're using `url` as a payload variable. You should adjust the payload variables based on your workflow's input requirements.
```javascript
const axios = require('axios');
// Step 1: Get your API key from environment variable
const lamatic_api_key = process.env.LAMATIC_API_KEY;
// Step 2: Define your GraphQL query
const query = `
query ExecuteWorkflow(
$workflowId: String!
$url: String
) {
executeWorkflow(
workflowId: $workflowId
payload: {
url: $url
}
) {
status
result
}
}
`;
// Step 3: Define your query variables
const variables = {
workflowId: "YOUR_WORKFLOW_ID",
url: "url"
};
// Step 4: Configure the request
const options = {
method: 'POST',
url: 'YOUR_PROJECT_URL',
headers: {
'Authorization': `Bearer ${lamatic_api_key}`,
'Content-Type': 'application/json',
'x-project-id': 'YOUR_PROJECT_ID',
},
data: {
query,
variables
}
};
// Step 5: Make the request
axios(options)
.then(response => {
console.log('Success:', response.data);
})
.catch(error => {
console.error('Error:', error.response?.data || error.message);
});
```
```python
import os
import requests
# Step 1: Get your API key from environment variable
lamatic_api_key = os.getenv('LAMATIC_API_KEY')
if not lamatic_api_key:
raise ValueError("LAMATIC_API_KEY environment variable is not set")
# Step 2: Define your GraphQL query
gql_query = """
query ExecuteWorkflow(
$workflowId: String!
$url: String
) {
executeWorkflow(
workflowId: $workflowId
payload: {
url: $url
}
) {
status
result
}
}
"""
# Step 3: Define your query variables
variables = {
"workflowId": "YOUR_WORKFLOW_ID",
"url": "url"
}
# Step 4: Prepare the request payload
data = {
"query": gql_query,
"variables": variables
}
# Step 5: Set up request headers
headers = {
"Authorization": f"Bearer {lamatic_api_key}",
"Content-Type": "application/json",
"x-project-id": "YOUR_PROJECT_ID"
}
# Step 6: Set your project URL
url = "YOUR_PROJECT_URL"
# Step 7: Make the request
try:
response = requests.post(url, headers=headers, json=data)
response.raise_for_status() # Raises an error for bad status codes
# Step 8: Handle the response
result = response.json()
print("Success:", result)
except requests.exceptions.RequestException as e:
print(f"Error: {e}")
if hasattr(e, 'response') and e.response is not None:
print(f"Status Code: {e.response.status_code}")
print(f"Response: {e.response.text}")
```
```bash
# Step 1: Set your API key (if not already set)
export LAMATIC_API_KEY=your_api_key_here
# Step 2: Set your project details
PROJECT_URL="YOUR_PROJECT_URL"
PROJECT_ID="YOUR_PROJECT_ID"
WORKFLOW_ID="YOUR_WORKFLOW_ID"
# Step 3: Make the GraphQL request
curl -X POST "$PROJECT_URL" \
-H "Authorization: Bearer ${LAMATIC_API_KEY}" \
-H "Content-Type: application/json" \
-H "x-project-id: ${PROJECT_ID}" \
-d '{
"query": "query ExecuteWorkflow($workflowId: String!, $url: String) { executeWorkflow(workflowId: $workflowId, payload: { url: $url }) { status result } }",
"variables": {
"workflowId": "'"$WORKFLOW_ID"'",
"url": "url"
}
}'
```
## Understanding the Response
The response structure can be configured in the **Schema** of the GraphQL Response node in your workflow. The response will follow this structure:
```json
{
"data": {
"executeWorkflow": {
"status": "success",
"result": {
// Your custom output as configured in the Schema
}
}
}
}
```
## Common Integration Patterns
**Synchronous Integration**: Make a request and wait for the response before proceeding. Best for workflows that complete quickly.
**Asynchronous Integration**: Trigger the workflow and handle the response in a callback or promise. Best for longer-running workflows.
**Webhook Integration**: Configure your workflow to send results to a webhook endpoint in your application. Best for workflows that may take time to complete.
**Batch Processing**: Trigger multiple workflows in parallel or sequence. Ensure you respect rate limits.
## Troubleshooting
### Authentication Errors (401)
- Verify your API key is correct and not expired
- Check that the API key is properly set in environment variables
- Ensure the `Bearer` prefix is included in the Authorization header
### Project Not Found (404)
- Verify your Project ID is correct
- Check that the Project URL is correct
- Ensure your project is deployed
### Rate Limit Exceeded (429)
- Ensure you’re not exceeding the allowed number of requests for your plan
- Check if multiple requests are being sent in parallel or in rapid succession
- Implement request throttling or retries with exponential backoff
### Workflow Execution Errors
- Verify the Workflow ID is correct
- Check that payload structure matches workflow inputs
- Review workflow logs in the Studio
### Network Errors
- Check your internet connection
- Verify the Project URL is accessible
- Check firewall settings
- Implement retry logic with exponential backoff
## Important Notes
- **Workflow ID**: You can find your workflow ID in the Studio when viewing your workflow
- **Payload Variables**: The `payload` object should match the input variables defined in your workflow. In this example, we're using `url`, but you should adjust this based on your workflow's requirements
- **Error Handling**: Always check the response status and handle errors appropriately in your application
- **API Key Security**: Never commit your API key to version control. Always use environment variables or secure secret management
---
# Next.js
Source: https://lamatic.ai/docs/sdk/next.md
# Using Lamatic SDK with Next.js
This guide demonstrates how to integrate the Lamatic SDK with Next.js applications to execute flows.
## Setup
First, install the Lamatic SDK in your Next.js project:
```bash
npm install lamatic
```
## Environment Configuration
Create a `.env.local` file in your project root with your Lamatic credentials:
```
LAMATIC_PROJECT_ENDPOINT=your-project-endpoint
LAMATIC_FLOW_ID=your-flow-id
LAMATIC_PROJECT_ID=your-project-id
LAMATIC_PROJECT_API_KEY=your-project-api-key
```
## Basic Integration
### Create a Lamatic Client
Create a utility file to initialize the Lamatic client:
```tsx
// utils.ts
export const lamaticClient = new Lamatic({
projectId: process.env.LAMATIC_PROJECT_ID,
apiKey: process.env.LAMATIC_PROJECT_API_KEY,
endpoint: process.env.LAMATIC_PROJECT_ENDPOINT,
})
```
### Using the Client in a Next.js Component
Now, you can use the Lamatic client in your Next.js components to execute flows or agents.
```tsx
// app.tsx
export default async function Page() {
const executeFlow = async () => {
const response = await lamaticClient.executeFlow(process.env.LAMATIC_FLOW_ID, {
prompt: 'hello',
})
console.log(response)
}
return (
)
}
```
When the button is clicked, the component will execute the flow and log the response to the console.
---
# Python
Source: https://lamatic.ai/docs/sdk/python.md
# Using Lamatic SDK with Python
This guide demonstrates how to integrate the Lamatic Python SDK into your Python applications to execute flows.
This SDK is in **early/alpha release** (v0.1.0). It currently supports executing **flows** only, agent execution (`executeAgent`) isn't available in the Python SDK yet, use the [JavaScript SDK](/docs/sdk) or [Go SDK](/docs/sdk/go) if you need that today.
## Installation
Requires **Python 3.10+**. Install with pip:
```bash
pip install lamatic
```
## Getting Started
To use the Lamatic Python SDK, you'll need:
- An API key or access token
- Your project ID
- The Lamatic API endpoint
## Basic Setup
```python
from lamatic import Lamatic
lamatic = Lamatic(
endpoint="https://yourproject.lamatic.dev/graphql",
project_id="your-project-id",
api_key="your-api-key",
)
```
## Authentication
The SDK supports two authentication methods:
```python
from lamatic import Lamatic
lamatic = Lamatic(
endpoint="https://yourproject.lamatic.dev/graphql",
project_id="your-project-id",
api_key="your-api-key",
)
```
```python
from lamatic import Lamatic
lamatic = Lamatic(
endpoint="https://yourproject.lamatic.dev/graphql",
project_id="your-project-id",
access_token="your-access-token",
)
```
You must provide either `api_key` or `access_token`, but not both, the constructor raises `ValueError` if neither is set.
## Executing Flows
Execute a workflow synchronously with `execute_flow`:
```python
response = lamatic.execute_flow(
flow_id="your-flow-id",
payload={"prompt": "Hello, Lamatic!"},
)
print(response.status) # "success"
print(response.result)
print(response.message)
```
## Async Usage
For async applications, use `async_execute_flow` instead:
```python
import asyncio
from lamatic import Lamatic
lamatic = Lamatic(
endpoint="https://yourproject.lamatic.dev/graphql",
project_id="your-project-id",
api_key="your-api-key",
)
async def main():
response = await lamatic.async_execute_flow(
flow_id="your-flow-id",
payload={"prompt": "Hello from async!"},
)
print(response.status)
print(response.result)
asyncio.run(main())
```
## Checking Request Status
For long-running flows, poll for the result with `check_status` (sync) or `async_check_status` (async). Both accept a polling interval and a timeout, in seconds, and return as soon as the request reaches a terminal state (`success`, `error`, or `failed`):
```python
response = lamatic.check_status(
request_id="your-request-id",
poll_interval=5, # seconds between polls, default 15
poll_timeout=120, # max wait time in seconds, default 900
)
print(response.status)
print(response.result)
```
```python
async def poll():
response = await lamatic.async_check_status(
request_id="your-request-id",
poll_interval=5,
poll_timeout=120,
)
print(response.status)
print(response.result)
```
If `poll_timeout` is reached before the flow finishes, `check_status` returns `status="error"`, `status_code=408`, and a message noting the request may still be executing in the background. The flow itself isn't cancelled, only the polling loop gives up.
## Updating Access Token
If you're using access token authentication, update it at runtime with `update_access_token`:
```python
lamatic.update_access_token("new-access-token")
```
## Response Structure
`execute_flow`, `async_execute_flow`, `check_status`, and `async_check_status` all return a `LamaticResponse`:
```python
@dataclass
class LamaticResponse:
status: str # "success" | "error" | "failed" | in-progress while running
result: dict | None
message: str | None = None
status_code: int | None = None
```
### Example
```python
response = lamatic.execute_flow("your-flow-id", {"prompt": "hey, how are you?"})
if response.status == "success":
print("Result:", response.result)
else:
print("Failed:", response.message)
```
## Error Handling
`execute_flow` and `async_execute_flow` raise an exception on network failures (they don't catch and swallow errors), so wrap calls in a `try`/`except` block:
```python
try:
response = lamatic.execute_flow(flow_id, payload)
if response.status == "success":
print("Success:", response.result)
else:
print("Execution failed:", response.message)
except Exception as e:
print("SDK error:", e)
```
`check_status` and `async_check_status` behave differently: they catch errors internally and return a `LamaticResponse` with `status="error"` instead of raising, so you can check `response.status` without a `try`/`except`.
## Environment Variables
For better security, keep credentials out of source code:
```python
import os
from lamatic import Lamatic
lamatic = Lamatic(
endpoint=os.environ["LAMATIC_PROJECT_ENDPOINT"],
project_id=os.environ["LAMATIC_PROJECT_ID"],
api_key=os.environ["LAMATIC_PROJECT_API_KEY"],
)
```
## Resources
- **PyPI package**: [pypi.org/project/lamatic](https://pypi.org/project/lamatic/)
- **GitHub repository**: [github.com/Lamatic/Lamatic-Python-SDK](https://github.com/Lamatic/Lamatic-Python-SDK)
- **Examples**: see `examples/basic_usage.py` in the repository
## Support
For help and support with the Python SDK:
- Open an issue on [GitHub](https://github.com/Lamatic/Lamatic-Python-SDK/issues)
- Contact [support@lamatic.ai](mailto:support@lamatic.ai)
---
# React SDK
Source: https://lamatic.ai/docs/sdk/react.md
# Using Lamatic SDK with React
This guide demonstrates how to integrate the Lamatic SDK with React applications to execute flows.
## Setup
First, install the Lamatic SDK in your React project:
```bash
npm install lamatic
```
## Environment Configuration
Create a `.env.local` file in your project root with your Lamatic credentials:
```
LAMATIC_PROJECT_ENDPOINT=your-project-endpoint
LAMATIC_FLOW_ID=your-flow-id
LAMATIC_PROJECT_ID=your-project-id
LAMATIC_PROJECT_API_KEY=your-project-api-key
```
## Basic Integration
### Create a Lamatic Client
Create a utility file to initialize the Lamatic client:
```tsx
// utils.ts
export const lamaticClient = new Lamatic({
projectId: process.env.LAMATIC_PROJECT_ID,
apiKey: process.env.LAMATIC_PROJECT_API_KEY,
endpoint: process.env.LAMATIC_PROJECT_ENDPOINT,
})
```
### Using the Client in a React Component
Now, you can use the Lamatic client in your React components to execute flows or agents.
```tsx
// App.tsx
function Page() {
const executeFlow = async () => {
const response = await lamaticClient.executeFlow(process.env.LAMATIC_FLOW_ID, {
prompt: 'hello',
})
console.log(response)
}
return (
)
}
export default Page
```
When the button is clicked, the component will execute the flow and log the response to the console.
---
# Anonymous Reporting
Source: https://lamatic.ai/docs/security/anonymous-reporting.md
# Anonymous Reporting
Speak up safely and securely about potential violations or concerns
This Whistleblower Form is intended to encourage and enable employees and others to communicate potential legal and ethical concerns to appropriate leadership and oversight teams to allow Lamatic to address and correct inappropriate conduct and actions. It is the responsibility of all board members, officers, employees, and contractors to report concerns about violations of code of ethics or suspected violations of law or regulations that govern Lamatic's operations.
All information gathered will remain anonymous and only provided to appropriate teams
to facilitate escalation and remediation. It is prohibited by Lamatic for anyone to
retaliate against any individual who in good faith reports an ethics violation or
a suspected violation of law, such as a complaint of discrimination, suspected fraud,
or potential violation of any regulation related to Lamatic's operations. Any employee
who retaliates against an individual who has reported a violation in good faith is
subject to disciplinary measures, up to and including termination of employment.
Reports of violations or suspected violations will be kept confidential to the extent
possible, consistent with the need to conduct an adequate investigation.{" "}
## What Happens Next?
1. Your report is securely transmitted to our compliance team.
1. A preliminary review will be conducted.
1. If additional information is needed, it will be requested through this system.
1. Appropriate action will be taken based on the investigation findings.
---
# Security Architecture
Source: https://lamatic.ai/docs/security/architecture.md
# Security Architecture
## Why traditional security falls short
For decades, most security programs have followed the same rhythm: conduct an annual penetration test, run periodic audits, patch vulnerabilities after they are reported, and add controls around a network perimeter.
That approach is no longer enough for modern AI infrastructure. Applications change daily. Dependencies change constantly. APIs, models, tools, and agent workflows introduce new paths through which data can be accessed or actions can be performed.
At the same time, attackers can use AI agents to scan systems faster, automate reconnaissance, test many attack paths at once, and adapt their techniques as environments change. A security program that only evaluates risk periodically cannot keep pace with an attack surface that evolves continuously.
The future of security is not simply more automation. It is agentic: continuous, contextual, adaptive, and built into every layer of the platform.
At Lamatic.ai, we build agentic infrastructure that is secure in two directions:
**Secure from agents**: our platform is designed to resist malicious autonomous behavior, unauthorized tool use, data exposure, prompt injection, and automated exploitation.
**Secure for agents**: legitimate agents operate with clear identity, narrowly scoped access, isolated execution environments, observable actions, and enforceable policy boundaries.

---
## Secure development lifecycle
Security should not be something added before release. It needs to be part of how software is planned, written, reviewed, tested, deployed, and monitored.
### Agent-assisted code review
Every code change can introduce security consequences. A new endpoint may expose information, an authorization check may be missed, a dependency may introduce a known vulnerability, or a small configuration change may accidentally broaden access.
Lamatic uses automated and agent-assisted review to examine code changes continuously. These agents look beyond simple keyword matching: they evaluate patterns, data flows, permissions, and the security implications of a change in context.
AI review does not replace engineering judgment. Instead, it acts as an always-on additional reviewer that can flag risky patterns early, before code reaches production. Engineers remain accountable for reviewing findings, validating their relevance, and making the final design decisions.
Agent-assisted review focuses on:
- Authentication and authorization changes
- Input validation and unsafe data handling
- Secret exposure and insecure configuration
- Dependency changes and known vulnerabilities
- Data-flow paths that could expose customer information
- Business-logic gaps that conventional scanners may miss

### Security gates in CI/CD
A secure development process needs enforceable checkpoints. Security gates prevent code from being promoted when it fails critical security requirements.
At Lamatic, automated checks run throughout the CI/CD pipeline. A developer receives feedback while the change is still small and easy to fix, rather than discovering a problem after it has been deployed to production.
Our security gates include:
- **Static application security testing (SAST)**: reviews source code for common insecure patterns such as injection risks, unsafe deserialization, weak cryptography, and missing validation
- **Software composition analysis (SCA)**: checks open-source dependencies for known vulnerabilities, license issues, and outdated packages
- **Secrets detection**: blocks commits that include credentials, private keys, tokens, or connection strings
- **Infrastructure-as-code scanning**: reviews Terraform, Kubernetes manifests, Dockerfiles, and cloud configuration for insecure defaults or over-permissive access
- **Container image scanning**: identifies vulnerable libraries, operating-system packages, and misconfigurations before an image is deployed
- **Dynamic and API security testing**: tests running staging environments for weaknesses that only appear when services interact
- **Release-risk review**: applies deeper analysis and agentic pentesting to material changes or major releases
Production is not the first place where security checks happen. It is the last place a validated change is allowed to go.

### Continuous agentic pentesting
A traditional penetration test is a snapshot. It is valuable, but it cannot represent the security state of a fast-moving platform for an entire year or quarter.
Agentic pentesting makes offensive testing continuous. Autonomous agents can map authorized attack surfaces, replay relevant tests after a deployment, look for new exposure caused by configuration changes, and test newly disclosed vulnerabilities against the current environment.
Every automated finding still needs prioritization. We combine continuous machine-scale testing with human validation to ensure security teams focus on vulnerabilities that are practical, impactful, and relevant to customers.
| Area | Traditional pentest | Continuous agentic pentesting |
| --- | --- | --- |
| Timing | Scheduled periodically | Runs continuously and after meaningful changes |
| Scope | Defined before the engagement | Evolves with the approved attack surface |
| Detection speed | Often weeks after a release | Can identify issues shortly after change |
| Validation | Primarily manual | Autonomous testing plus human validation |
| Retesting | Usually a separate engagement | Automated after remediation or deployment |
Continuous testing helps us:
- Detect exposures introduced by new releases or configuration changes
- Validate whether newly published vulnerabilities affect our environment
- Test APIs, web applications, cloud services, and integration boundaries together
- Verify fixes by retesting the original attack path
- Give engineering teams actionable evidence instead of abstract alerts

### Static analysis plus agentic reasoning
Static analysis is fast and reliable for detecting known insecure patterns. It is an essential part of secure software delivery, but it does not always understand why a feature exists or whether a sequence of valid actions creates a business-logic vulnerability.
Agentic analysis adds contextual reasoning. It can evaluate how data moves through an application, how identity and permission checks are used across services, and whether a user could perform an action that their role should not permit.
| Security layer | What it does best |
| --- | --- |
| Static analysis | Finds known patterns such as injection, weak cryptography, exposed secrets, and unsafe functions |
| Dependency analysis | Finds vulnerable or outdated third-party packages |
| Agentic reasoning | Investigates data flow, authorization paths, business logic, and multi-step attack scenarios |
| Human review | Validates product intent, threat model assumptions, and risk trade-offs |
{/* image: static analysis, agentic reasoning, and human review compared */}
---
## Data security and zero trust
Customer data is the most sensitive part of an AI infrastructure platform. Our approach assumes that no request, service, identity, or environment should receive more access than it needs.
This is the foundation of zero trust: verify explicitly, use least privilege, and limit the duration and scope of access.
### Separate environments
We separate development, staging, and production environments so that experimentation and testing do not expose production systems or customer data.
- **Development**: used for engineering work with isolated services and non-production data
- **Staging**: mirrors production architecture as closely as possible while using synthetic, masked, or otherwise non-sensitive data
- **Production**: hosts customer workloads and is isolated from lower environments through separate identities, resources, networks, and access controls
Environment separation limits blast radius. A mistake in development should not provide a path to production data or infrastructure.

### Authentication and access control
Identity is the starting point for security. Before a person, service, or agent can access a resource, Lamatic verifies who or what is making the request and whether that identity has a legitimate reason to perform the action.
Our access-control model includes:
- **2FA/MFA**: multi-factor authentication is required for user and administrative access, reducing the risk that a stolen password alone can compromise an account
- **OAuth 2.0 and OIDC**: federated identity standards enable scoped, revocable, and short-lived authorization rather than persistent shared credentials
- **RBAC (Role-Based Access Control)**: permissions are granted according to defined roles, so users and services receive only the capabilities required for their responsibilities
- **RLS (Row-Level Security)**: database policies restrict which records a requester can access, creating another enforcement layer even if application logic fails
- **Service identities**: services and agents use distinct identities with narrowly scoped permissions rather than sharing broad administrator credentials
### Encryption in depth
Encryption protects data while it is moving, while it is stored, and while it is accessed. We use multiple layers because no single control should be responsible for protecting sensitive information.
| Layer | How it protects data |
| --- | --- |
| Encryption in transit | TLS protects data moving between users, services, APIs, and infrastructure endpoints from interception or tampering |
| Encryption at rest | AES-256 protects stored databases, backups, files, and persistent infrastructure resources |
| Per-project keys | Each project or tenant receives unique encryption key material, limiting the impact of any individual key exposure |
| Key separation | Encryption keys and salts are stored separately from the encrypted data they protect |
| Just-in-time decryption | Data is decrypted only for the authorized operation, for the minimum necessary time, and then re-encrypted |
| Key rotation | Key material is rotated according to policy and operational requirements to reduce long-term exposure |
Just-in-time decryption is especially important for agentic systems. An agent should not receive a permanent decrypted dataset simply because it has a valid task. It should receive only the data and access required for the specific approved action.

### Data lifecycle management
Security includes what happens to data after it has been created. We define how information is stored, retained, recovered, accessed, and deleted.
- **Point-in-Time Recovery (PITR)**: continuous backup capabilities allow data to be restored to a precise moment, reducing the impact of accidental deletion, corruption, or operational failure
- **Data retention policies**: data is retained only for an approved business, legal, operational, or customer-defined purpose; when the retention period ends, deletion is automated and documented
- **Immutable audit logs**: security-relevant actions are recorded in tamper-evident storage, supporting investigations, compliance evidence, and accountability
- **Controlled backups**: backups are encrypted, access-controlled, and subject to retention and deletion requirements
### Tenant and resource isolation
Multi-tenant platforms must be designed so that one customer cannot access, affect, or infer information about another customer. Lamatic applies isolation at multiple layers, including database policies, storage boundaries, compute resources, network segmentation, identity controls, and encryption keys. Where a workload requires stronger separation, dedicated tenant infrastructure can provide an additional boundary.
See [Tenant Security & Isolation](/docs/security/tenant-isolation) for the full architecture, network diagram, and subprocessor inventory.
{/* image: multi-tenant isolation diagram with separate databases, storage, compute, keys, and network boundaries */}
---
## Infrastructure and runtime security
Secure AI infrastructure requires more than secure code. The platform must also protect the way services run, communicate, store data, and respond to malicious traffic.
### Serverless microservices architecture
Lamatic uses serverless microservices, including Cloudflare Workers and Digital Ocean Cloud Functions, to separate responsibilities into smaller services with explicit interfaces and limited permissions.
This architecture can reduce operational risk when implemented carefully. Services can scale automatically, execution is often short-lived, and each component can be assigned a dedicated identity with only the permissions it needs. A compromise in one service should not automatically become unrestricted access across the environment.
Core principles:
- Least-privilege IAM for every workload
- Separate service identities rather than shared credentials
- Explicit APIs and network paths between services
- Short-lived, ephemeral execution where appropriate
- Controlled deployment through validated CI/CD pipelines

### Dedicated tenant-isolated infrastructure
For sensitive workloads, infrastructure isolation may need to go beyond logical access controls. Dedicated tenant-isolated infrastructure can provide separate compute, storage, network, database, and encryption boundaries for a customer or workload. This option helps reduce shared-resource exposure, simplify customer security reviews, and support strict data-separation requirements, particularly for organizations operating in regulated environments or handling highly sensitive data.
### Full OpenTelemetry tracing
Security cannot be effective if critical actions are invisible. Lamatic instruments services with OpenTelemetry (OTEL) to provide end-to-end traces across distributed systems.
Observability helps us understand how a request moved through services, where an authorization decision occurred, which tool an agent invoked, and what data-access operation was attempted. These signals support reliability engineering, security monitoring, incident response, and auditability.
Security-relevant telemetry includes:
- Authentication events and failed login attempts
- Authorization decisions, including denied requests
- Privileged administrative actions
- Agent tool calls and runtime behavior
- Data-access events and sensitive configuration changes
- API errors, abuse patterns, and anomalous traffic

### Edge protection: WAF, rate limiting, bots, and DDoS
Public-facing applications need protection at the edge, before malicious traffic reaches internal services. We use layered controls because attacks range from simple credential-stuffing attempts to sophisticated application-layer DDoS campaigns.
- **Web Application Firewall (WAF)**: filters common malicious request patterns, enforces custom rules, and helps protect against common web vulnerabilities
- **Rate limiting**: limits how frequently a client can call a sensitive endpoint, reducing brute force, scraping, abuse, and resource exhaustion
- **Bot detection and mitigation**: identifies suspicious automated traffic while minimizing impact on legitimate users and integrations
- **DDoS mitigation**: absorbs or blocks volumetric and application-layer attacks so legitimate customers can continue to use the platform

### Audit logs and intrusion detection
Audit logs establish accountability. They record who performed an action, what action occurred, where it originated, and when it happened. These records support investigations, customer assurance, and detection of unusual patterns.
Intrusion detection adds another layer by analyzing network, host, application, and identity signals for behavior that may indicate compromise. Alerts are routed through defined severity and escalation paths so the right people can investigate quickly.
### Zero Data Retention options
Some customers need stronger control over how long data remains available. For eligible workloads, Lamatic can provide Zero Data Retention (ZDR) options that minimize or eliminate persistence beyond the active session or approved processing window. Depending on the configuration, ZDR can include ephemeral processing, reduced logging, no storage of prompts or outputs, and destruction of session-specific encryption material after use. Exact behavior is defined by the product configuration and customer agreement.
### Agent container sandboxing
AI agents can take actions, use tools, process inputs, and interact with external systems. That makes the agent runtime a critical security boundary.
Lamatic runs agents in isolated container sandboxes with explicit constraints. A sandbox limits what an agent can access and what it can do even if its instructions, tool inputs, or dependencies behave unexpectedly.
Sandbox controls include:
- CPU, memory, execution-time, and process limits
- Read-only or ephemeral filesystems where possible
- Restricted system calls through security profiles
- Explicit ingress and egress network policies
- Scoped secrets and short-lived credentials
- Per-agent identity and logging of tool actions
- Isolation between customer workloads and agent sessions
The goal is to ensure that an agent can perform its intended task without receiving unrestricted access to the host, network, data plane, or other tenants.
{/* image: agent sandbox diagram with resource limits, read-only filesystem, restricted egress, scoped tools, and audit logging */}
---
## What makes security agentic
Traditional security is often reactive and periodic. Agentic security is designed for a world where software, infrastructure, agents, and threats all change continuously.
| Characteristic | Traditional security | Agentic security at Lamatic |
| --- | --- | --- |
| Monitoring | Periodic reviews and alerting | Continuous signals across code, identity, runtime, and infrastructure |
| Testing | Scheduled scans and annual assessments | Continuous validation triggered by changes and emerging threats |
| Analysis | Rules and manual investigation | Rules, AI-assisted context analysis, and human judgment |
| Response | Often ticket-driven and delayed | Prioritized workflows, rapid triage, and repeatable remediation |
| Agent controls | Generic application permissions | Scoped identity, sandboxing, policy enforcement, and observable tool use |
| Data protection | Broad encryption and access policies | Per-tenant isolation, key separation, just-in-time decryption, and least privilege |
Agentic security does not mean handing security decisions entirely to AI. It means using agents responsibly to make security continuous, scalable, and context-aware, while keeping humans accountable for high-impact decisions.
**Secure from agents. Secure for agents. Built for what comes next.**
## Related
---
# Security & Compliance
Source: https://lamatic.ai/docs/security.md
# Security & Compliance
This section is written for security reviewers, IT/procurement teams, and enterprise buyers evaluating Lamatic.
Lamatic builds agentic infrastructure that is secure in two directions: **secure from agents**, resistant to malicious autonomous behavior, unauthorized tool use, and automated exploitation, and **secure for agents**, where legitimate agents run with clear identity, scoped access, isolated execution, and enforceable policy boundaries.
---
## Get in touch
- Explore our [Trust Center](https://trust.lamatic.ai) for security and compliance information
- Read the [Security Architecture](/docs/security/architecture) docs for implementation details
- [Get a demo](/request-demo) or reach out on [Slack](/docs/slack) for security questionnaires and customer reviews
## Related
---
# Security Programs
Source: https://lamatic.ai/docs/security/programs.md
# Security Programs
Technology alone does not create a secure organization. Security also depends on how people make decisions, how quickly teams respond, and whether responsibilities are clear.
## Annual security training
Every employee completes annual security awareness training. The goal is practical behavior, not checkbox compliance.
Training covers phishing and social engineering, secure handling of customer information, password and device hygiene, incident reporting, secure development expectations, and privacy obligations. We reinforce that security concerns should be reported early, even when the impact is uncertain.
## Quarterly disaster recovery and incident response exercises
A plan that has never been tested is only a document. Lamatic runs quarterly disaster recovery and incident response exercises to validate people, tooling, escalation paths, communications, and recovery procedures.
Exercises may simulate data-exfiltration attempts, ransomware, a cloud-provider outage, compromised credentials, DDoS events, or service failures. Each exercise produces lessons, follow-up actions, and owners so that our response capabilities improve over time.

## Vulnerability Disclosure Program
Security researchers play an important role in improving the security of the broader ecosystem. Our Vulnerability Disclosure Program provides a responsible path for researchers to report potential issues. We aim to acknowledge reports quickly, triage them transparently, and provide clear remediation expectations based on severity.
## Managed device security
Corporate devices are part of the security perimeter. A compromised laptop can bypass otherwise strong cloud controls through stolen sessions, source code access, or credential theft.
All corporate endpoints are enrolled in Mobile Device Management (MDM). This supports consistent requirements for full-disk encryption, supported operating-system versions, screen-lock policies, remote wipe, approved software, and jailbreak or root detection.
## Automated and human review
Automation gives us speed and consistency. Human review adds context, accountability, and judgment.
Automated controls continuously monitor identity, code, dependencies, infrastructure, runtime signals, and compliance posture. Human reviews assess architecture, high-severity findings, exceptions, vendor risk, incident learnings, and changes with meaningful business impact.
The combination is intentional: agents detect and analyze at machine speed, while people decide, prioritize, and remain accountable for outcomes.
{/* image: security operations dashboard with automated alerts, investigation queue, and human review workflow */}
## Compliance programs
- SOC 2 Type II
- ISO 27001
- GDPR
## Related
---
# Security Service-Level Objectives
Source: https://lamatic.ai/docs/security/sla.md
# Security Service-Level Objectives
Not every vulnerability carries the same risk. We use severity-based service-level objectives to ensure the highest-risk issues receive the fastest attention.
| Severity | Initial response target | Remediation target | Typical examples |
| --- | --- | --- | --- |
| Critical | Within 24 hours | Within 5 business days | Confirmed data exposure, remote code execution, authentication bypass |
| High | Within 72 hours | Within 10 business days | Significant privilege escalation or exploitable service weakness |
| Medium | Within 1 week | Within 30 business days | Limited-impact configuration or application weakness |
| Low | Within 2 weeks | Within 60 business days | Hardening opportunities with low exploitability or impact |
These targets guide prioritization, but active exploitation, customer impact, and business context can always accelerate response.
## Related
---
# Tenant Security & Isolation
Source: https://lamatic.ai/docs/security/tenant-isolation.md
# Tenant Security & Isolation
This page is written for security reviewers, IT/procurement teams, and enterprise buyers evaluating Lamatic for multi-tenant or regulated deployments.
Lamatic enforces tenant boundaries across runtime, data, access, and operations. Every request and background job carries an explicit tenant context, and every service enforces it before reading or writing data, or performing administrative operations.
### What this enables
- Strong separation between tenants
- Tenant-scoped authentication context and authorization
- Tenant-scoped logs and administrative actions
### How it works, in brief
- Tenant-aware routing for requests and jobs
- Enforced tenant context at every service boundary
- Layered isolation across access, application, data, operations, and observability
---
## Architecture overview

At a high level, the platform is split into three planes:
- **Runtime plane**: tenant-facing application traffic, authentication, storage access, worker execution, and artifacts (stateless)
- **Control plane**: shared control services, provisioning workflows, secrets management, ingestion, and supporting infrastructure
- **Data plane**: tenant data storage with logical separation from other customer data
**Key principle: explicit tenant context everywhere.** Every request and background job carries an explicit tenant context, and every service enforces it before reading/writing data or performing administrative operations.
### Tenant provisioning & lifecycle
Each tenant is onboarded through an automated provisioning flow that configures tenant resources and service integrations. This includes isolated tenant setup for Supabase and Studio, along with tenant-scoped configuration for ClickHouse, the secret store, vector database infrastructure, and Airbyte.
### Tenant-aware execution
Runtime requests are resolved with tenant-aware routing so application requests, worker jobs, storage operations, and artifacts stay within the tenant boundary. Platform services enforce tenant context throughout execution to prevent cross-tenant reads, writes, and operational access.
---
## Network layers & isolation controls
The architecture uses layered isolation to reduce the risk of customer data exposure:
- **Access layer isolation**: tenant-scoped identities, authentication, and authorization
- **Application layer isolation**: tenant-aware runtime requests and worker execution paths
- **Data layer isolation**: tenant separation across relational storage, analytics systems, vector infrastructure, secrets, and synchronization services
- **Operational layer isolation**: controlled internal interfaces for administrative access, provisioning actions, and support workflows
- **Logging & observability isolation**: tenant-safe monitoring, audit trails, redaction controls, and optional restrictions such as disabling request body logging
**Regulated environments.** Where required, the architecture can support stricter deployment and network boundary controls to reduce or prevent customer PII from leaving approved environments (e.g., bank-network or regulator-driven requirements).
---
## Security guarantees
### Guaranteed by design
- Tenant-scoped access: tenant-aware authN/authZ tied to tenant-scoped identities and roles
- Tenant-safe data access: reads/writes constrained to tenant-specific namespaces and partitions
- Tenant-safe operations: provisioning and admin actions gated via controlled internal interfaces with tenant context
- No training on customer data: controls prevent customer data from being used for model training, fine-tuning, or cross-customer prompt sharing
### Configurable per customer
- Log retention and "no request-body logging" modes
- Data retention and deletion policies (where applicable)
- Optional opt-outs for certain shared systems (where supported)
We continuously extend audit, redaction, and dedicated-deployment capabilities for regulated customers. [Reach out](/docs/slack) to discuss your specific compliance requirements.
---
## Customer controls & admin operations
External stakeholders often ask how isolation interacts with day-to-day operations:
- **Tenant onboarding**: automated provisioning creates tenant-scoped configuration and service boundaries
- **Access management**: role-based access control for tenant and operator actions
- **Support & break-glass**: tightly controlled internal access paths; access is tenant-scoped and auditable
- **Offboarding**: tenant lifecycle processes support retention controls, deletion requests, and data export as required by contract
---
## Data systems (subprocessor inventory)
| System | Vendor | Use | Configuration | Compliance |
| --- | --- | --- | --- | --- |
| Studio | Vercel | Control plane | No retention | [Trust Centre](https://security.vercel.com) · [SOC 2](https://vercel.com/kb/guide/is-vercel-soc-2-compliant) · [ISO 27001](https://vercel.com/kb/guide/is-vercel-iso-27001-certified) |
| Studio DB | Supabase | Project configuration, flows & prompts, admin & user accounts | Shared, encrypted sensitive information | [Trust Centre](https://trust.supabase.io) · [SOC 2](https://supabase.com/security) · [ISO 27001](https://supabase.com/blog/supabase-is-now-iso-27001-certified) |
| Runtime worker, proxy | Cloudflare Worker + Containers | Agent execution runtime | Stateless | [Trust Centre](https://www.cloudflare.com/trust-hub/) · [SOC 2](https://www.cloudflare.com/trust-hub/compliance-resources/soc-2/) · [ISO 27001](https://www.cloudflare.com/trust-hub/compliance-resources/iso-certifications/) |
| Secrets | Cloudflare KV | Secrets, webhooks | Isolated, kill switch | [Trust Centre](https://www.cloudflare.com/trust-hub/) · [SOC 2](https://www.cloudflare.com/trust-hub/compliance-resources/soc-2/) · [ISO 27001](https://www.cloudflare.com/trust-hub/compliance-resources/iso-certifications/) |
| Tables | Cloudflare D1 | Durable data storage | Isolated, kill switch | [Trust Centre](https://www.cloudflare.com/trust-hub/) · [SOC 2](https://www.cloudflare.com/trust-hub/compliance-resources/soc-2/) · [ISO 27001](https://www.cloudflare.com/trust-hub/compliance-resources/iso-certifications/) |
| Files | Cloudflare Storage | Durable file storage | Isolated, kill switch | [Trust Centre](https://www.cloudflare.com/trust-hub/) · [SOC 2](https://www.cloudflare.com/trust-hub/compliance-resources/soc-2/) · [ISO 27001](https://www.cloudflare.com/trust-hub/compliance-resources/iso-certifications/) |
| VectorDB | Qdrant | Vectors, memories | Isolated, kill switch | [Trust Centre](https://qdrant.tech/documentation/cloud-security/) · [SOC 2 Type II](https://qdrant.tech/blog/qdrant-soc2-type2-audit/) · ISO 27001 in progress |
| ETL | Digital Ocean Postgres | Data ETL | Isolated, kill switch | [Trust Centre](https://www.digitalocean.com/trust) · [SOC 2 & ISO 27001 reports](https://www.digitalocean.com/trust/certification-reports) |
| ETL | Digital Ocean Droplet | Data ETL | Isolated | [Trust Centre](https://www.digitalocean.com/trust) · [SOC 2 & ISO 27001 reports](https://www.digitalocean.com/trust/certification-reports) |
| ETL, webhooks | Digital Ocean Kafka | Data ETL, webhooks | Shared, stateless | [Trust Centre](https://www.digitalocean.com/trust) · [SOC 2 & ISO 27001 reports](https://www.digitalocean.com/trust/certification-reports) |
| Integrations | Composio | Integrations, MCP | Shared, opt-out | [Trust Centre](https://trust.composio.dev) · [SOC 2 & ISO 27001](https://composio.dev/enterprise) |
| Logs, reports | ClickHouse | Logs | Isolated, opt-out (global or per flow), clear-all | [Trust Centre](https://trust.clickhouse.com) · [SOC 2 & ISO 27001](https://clickhouse.com/docs/cloud/security/compliance-overview) |
| Internal | Grafana | System observability | Shared, opt-out | [Trust Centre](https://trust.grafana.com) · [SOC 2 & ISO 27001](https://grafana.com/legal/security-compliance/) |
---
## Compliance & assurance
The architecture is designed to support compliance and security requirements commonly requested by enterprise and regulated customers:
- TLS 1.2 minimum, with a preference for TLS 1.3, for data in transit
- Encryption at rest for systems storing tenant or customer data
- Role-based access control for tenant and operator actions
- Isolation controls preventing customer-level analytics exposure or filterable bank-level visibility
- Zero data retention controls where required
- Controls preventing customer data from being used for model training, fine-tuning, or cross-customer prompt sharing
**Common evidence requests.** SOC 2 Type 2, recent penetration testing, vulnerability management documentation, information security policies, business continuity / disaster recovery plans, incident response plans, cyber insurance evidence, third-party risk management documentation, and data retention policies.
---
## Additional topics
### Threat model (high level)
- Prevent cross-tenant data access (primary objective)
- Reduce blast radius of credential compromise via tenant-scoped permissions
- Limit sensitive data exposure through logging controls and redaction, where applicable
### Data residency & customer requirements
Requirements can vary by customer and regulator. For deployments with strict residency needs, controls may include environment restrictions, region constraints, and customer-specific retention/logging policies.
### Incident response & customer communications
Enterprise readiness includes incident response procedures, defined escalation paths, and customer notification commitments aligned to contractual obligations.
### Third-party risk & subprocessors
See the [data systems inventory](#data-systems-subprocessor-inventory) above for vendor and subprocessor review and security questionnaires.
---
## Related
---
# Vulnerability Disclosure Program
Source: https://lamatic.ai/docs/security/vulnerability-disclosure.md
# Vulnerability Disclosure Program
At Lamatic, we believe in collaborating with the global security researcher community to enhance the security of our products. By welcoming researchers to identify vulnerabilities in our systems, we aim to make our products more secure while fostering a cooperative security ecosystem. To this end, we reward researchers for their valuable contributions.
## Scope of the Program
### In Scope
The following areas and vulnerabilities are included in the Vulnerability Disclosure Program:
1. **Products**
- [Lamatic.ai Studio](https://studio.lamatic.ai/): only the web application hosted at **studio.lamatic.ai** is in scope.
2. **Vulnerability Categories**
- Cross-Site Scripting (XSS)
- SQL Injection
- Authentication flaws
- Data leakage
- Privilege escalation
### Out of Scope
The following are **not covered** by the program:
1. Any asset or subdomain other than **studio.lamatic.ai**
2. Social engineering attacks (e.g., phishing)
3. Physical security vulnerabilities
4. Denial of Service (DoS) or Distributed Denial of Service (DDoS) attacks
5. Brute-force attacks against authentication or rate-limited endpoints
6. Use of non-application attack vectors such as machine takeover, cookie takeover, local privilege escalation, or network sniffing
7. Findings based on use of intrusive tools such as **Burp Suite**, **Wireshark**, or similar packet interception/analyzer tools
8. Third-party integrations, dependencies, or services not owned or controlled by Lamatic
## Submission Guidelines
Security researchers are required to provide detailed information about identified vulnerabilities. Submissions should include:
1. A clear description of the vulnerability
2. Step-by-step instructions to reproduce the issue
3. An impact analysis outlining the potential risk
4. Supporting evidence such as screenshots, videos, or scripts
5. Recommendations for remediation
## Response Times
We strive to provide timely responses to all submissions:
1. Initial response: **24 hours**
2. Severity assessment: **20 business days**
3. Status updates: **Every 30 business days**
4. Payment processing: **Within 60 days of validation**
## Review Process
| **Step** | **Description** |
| ---------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **1. Acknowledgment** | Confirm receipt of the report within **24–48 hours**. Assign a unique **Reference ID** to track the submission. |
| **2. Initial Assessment** | - Validate the authenticity of the issue. - Perform a **Duplicate Check** to ensure the bug hasn’t been previously reported. - Note that **multiple reports within the same exploit chain are considered one vulnerability**. - Share an NDA if necessary. |
| **3. Severity Analysis** | Assess the severity using a standard rating system such as **CVSS**: - **Critical**: Immediate, widespread impact (e.g., RCE, data breaches). - **High**: Significant functionality or security risks. - **Medium**: Moderate impact. - **Low**: Minor risks. |
| **4. Assignment & Prioritization** | Assign the validated issue to the appropriate team and prioritize based on severity. |
| **5. Development & Fixing** | Address the issue based on priority and ensure timely resolution. |
| **6. Researcher Verification** | Notify the researcher upon resolving the issue. Provide testing environments or evidence (e.g., logs, screenshots) for verification. |
| **7. Reward & Closure** | Issue the reward based on the severity, impact, and uniqueness of the vulnerability. |
| **8. Post-Resolution Analysis** | Conduct a root cause analysis to identify gaps in code review, testing, or system architecture. |
## Rules of Engagement
To ensure ethical conduct, researchers are required to adhere to the following guidelines:
| **Do’s** | **Don’ts** |
|----------------------------------------------|------------------------------------------------------------------------------------------------------|
| Test **only** within the defined scope (**studio.lamatic.ai**). | Do not test on any other Lamatic domains or services. |
| Avoid impacting production systems. | Do not use automated tools (e.g., Burp Suite, Wireshark) or network-level scanners. |
| Report vulnerabilities immediately. | Do not exploit vulnerabilities beyond proof-of-concept or attempt denial of service. |
| Operate responsibly and respect user privacy. | Do not attempt brute-force, credential stuffing, or machine-level exploitation. |
| Submit logically distinct vulnerabilities as separate reports. | Do not submit **multiple reports from the same exploit chain**, as these will be **grouped as one vulnerability**. |
## Legal Protections
### Safe Harbor Clause
Lamatic provides safe harbor for researchers acting in good faith, ensuring protection from legal consequences as long as they:
1. Operate within the defined scope and guidelines
2. Avoid compromising user data
3. Do not disrupt services
4. Responsibly report vulnerabilities through the program
## Disclosure Restrictions
By submitting a vulnerability report, you agree to abide by Lamatic’s [Terms & Conditions](https://lamatic.ai/docs/legal/terms-of-service) and the conditions outlined in this program.
- All submitted reports are **confidential** and must **not** be shared publicly, including on social media, blogs, forums, or other channels, regardless of their resolution status.
- Even if a vulnerability report is marked as **invalid**, it is **strictly prohibited** to disclose any details of the finding without explicit written consent from Lamatic.
- Breaching these terms may disqualify you from receiving a reward and could result in legal action under applicable laws.
## Rewards
We greatly appreciate responsible disclosures and will reward eligible contributors with exclusive goodies and swag as a token of thanks.
**Note:** Our Vulnerability Disclosure Program (VDP) does not include any form of monetary compensation.
Thank you for contributing to the security of Lamatic's products!